# ContextQA Documentation
ContextQA documentation — complete reference for AI-powered test automation, the MCP server, integrations, and platform administration.
## Quick answer
ContextQA documentation — complete reference for AI-powered test automation, the MCP server, integrations, and platform administration. Use this page to choose the relevant workflow guide, understand the available capabilities, and navigate to the supporting instructions.
## What this page covers
ContextQA is an AI-powered test automation platform that creates, executes, and maintains browser, mobile, API, and Salesforce tests without requiring test code. The AI agent interprets natural language test steps, locates UI elements using visual AI and DOM analysis, and self-heals broken tests when an application changes.
> **ContextQA:** An AI-powered test automation platform that executes test cases written in natural language against web, mobile, API, and Salesforce applications, producing full evidence packages (screenshots, video, HAR logs, Playwright traces) for every run.
{% hint style="info" %}
**70% less human effort · 10× faster execution · Zero selector maintenance** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA with your application in 30 minutes.
{% endhint %}
***
## What ContextQA Does
ContextQA executes every test through an AI pipeline that handles navigation, element interaction, evidence capture, and self-healing automatically. Tests run on real browsers — Chromium, Firefox, and WebKit.
**Key capabilities:**
* **AI test generation** — create test cases from a URL, Jira ticket, Figma design, OpenAPI spec, video recording, or plain-text requirements
* **Natural language execution** — steps written in plain English execute as full browser interactions
* **Self-healing** — when a UI element moves or changes, the AI finds the new location automatically
* **MCP server** — 67 tools for AI agents (Claude, Cursor, VS Code Copilot) to create, execute, and analyze tests programmatically
* **17 plugin integrations + 5 CI/CD guides** — plugins such as Jira, Slack, Microsoft Teams, Azure DevOps, Linear, and Trello, plus CI/CD guides for GitHub Actions, Jenkins, and GitLab CI
***
## Start by Role
{% tabs %}
{% tab title="🧪 Tester" %}
Write tests in plain English, run on real browsers, get video evidence. No code required.
[**→ ContextQA for Testers**](/documentation-by-role/by-role/for-testers)
{% endtab %}
{% tab title="⚙️ SDET" %}
67 MCP tools, Playwright export, CI/CD API, full evidence access. Your automation superpowers.
[**→ ContextQA for SDETs**](/documentation-by-role/by-role/for-sdets)
{% endtab %}
{% tab title="📋 QA Manager" %}
Test plans, analytics dashboard, flaky detection, shareable reports. Release confidence, quantified.
[**→ ContextQA for QA Managers**](/documentation-by-role/by-role/for-qa-managers)
{% endtab %}
{% tab title="💻 Developer" %}
Generate tests from Jira tickets, PR quality gates, AI root cause in your terminal.
[**→ ContextQA for Developers**](/documentation-by-role/by-role/for-developers)
{% endtab %}
{% tab title="🗺️ PM" %}
Turn your acceptance criteria into automated tests. Track feature coverage. Know before you ship.
[**→ ContextQA for Product Managers**](/documentation-by-role/by-role/for-product-managers)
{% endtab %}
{% tab title="🏗️ Eng Manager" %}
Parallel CI gates, SSO, team metrics, and AI that eliminates test maintenance toil.
[**→ ContextQA for Engineering Managers**](/documentation-by-role/by-role/for-engineering-managers)
{% endtab %}
{% tab title="🚀 VP/CTO" %}
The ROI, build-vs-buy analysis, and enterprise architecture for AI test automation at scale.
[**→ ContextQA for VPs & CTOs**](/documentation-by-role/by-role/for-vp-engineering)
{% endtab %}
{% endtabs %}
***
## Documentation Sections
### [Business Use Cases](/business-use-cases/business-use-cases)
Start with the business risk: requirements-to-test traceability, complex authenticated web flows, risk-based regression, document and KYC application validation, Salesforce lifecycles, or connected delivery workflows. Each guide maps capabilities to an implementation pattern, evidence, guardrails, and success measures.
### [Getting Started](/getting-started/introduction)
New to ContextQA? Start here. Covers platform overview, a 5-minute quickstart, core concepts, and the AI pipeline architecture.
* [Introduction to ContextQA](/getting-started/introduction)
* [Quickstart Guide](/getting-started/quickstart)
* [Core Concepts](/getting-started/core-concepts)
* [Platform Architecture](/getting-started/architecture-overview)
### [Web Testing](/web-testing/web-testing)
Create and run automated tests for web applications. Covers test case authoring, the step editor, test suites, data management, and self-healing.
### [Mobile Testing](/mobile-testing/mobile-testing)
Automate iOS and Android app testing. Covers device setup, app uploads, gesture authoring, and multi-device test plans.
### [API Testing](/api-testing/api-testing)
Test REST APIs with assertions and request chaining. Covers request configuration, response validation, and multi-step API flows.
### [Salesforce Testing](/salesforce-testing/salesforce-testing)
Automate Salesforce Lightning UI testing. Covers AI-assisted test generation, metadata-aware execution, and parallel test plans.
### [Execution](/execution/running-tests)
Run tests manually, on a schedule, or from CI/CD. Covers parallel execution, environments, scheduling, and evidence capture.
### [Reporting](/reporting/reporting)
Analyze test results and diagnose failures. Covers execution reports, the analytics dashboard, AI root cause analysis, and flaky test detection.
### [AI Features](/ai-features/ai-test-generation)
The AI capabilities that power ContextQA. Covers test generation sources, the autonomous agent pipeline, knowledge bases, and custom agents.
### [Integrations](/integrations/integrations)
Connect ContextQA to your existing toolchain. Covers Jira, Slack, GitHub Actions, Jenkins, GitLab CI, CircleCI, Azure DevOps, and webhooks. ContextQA offers 17 portal integrations (configured from **Integrations & Plugins**) across bug tracking, project management, notifications, and infrastructure, plus 5 CI/CD integration guides that trigger test plans from your pipeline.
### [MCP Server](/mcp-server/overview)
Use ContextQA from AI agents via the Model Context Protocol. Covers installation, authentication, 67 tool references, and agent workflow patterns.
### [Administration](/administration/administration)
Manage users, roles, SSO, and workspace settings.
### [Reference](/reference/glossary)
Glossary, changelog, and keyboard shortcuts.
***
## Quick Links
| I want to… | Go to |
| --------------------------------------------------- | ---------------------------------------------------------------------------------- |
| Match ContextQA features to a business problem | [Business Use Cases](/business-use-cases/business-use-cases) |
| Create my first test | [Quickstart Guide](/getting-started/quickstart) |
| Generate a test from a Jira ticket | [AI Test Generation](/ai-features/ai-test-generation) |
| Upload an Android APK or iOS IPA build | [Uploading Apps](/mobile-testing/uploading-apps) |
| Chain API calls and reuse response data | [API Chaining](/api-testing/api-chaining) |
| Find execution video, screenshots, logs, and traces | [Video & Screenshots](/execution/video-and-screenshots) |
| Investigate repeated or intermittent failures | [Flaky Test Detection](/reporting/flaky-test-detection) |
| Run tests in a CI/CD pipeline | [GitHub Actions](/integrations/github-actions) or [Jenkins](/integrations/jenkins) |
| Use ContextQA from Claude or Cursor | [MCP Server Overview](/mcp-server/overview) |
| Give an AI agent the ContextQA documentation | [Use the Docs with Search and AI](/reference/using-contextqa-docs-with-ai) |
| Understand why a test failed | [Failure Analysis](/reporting/failure-analysis) |
| Create roles and assign least-privilege access | [Roles & Permissions](/administration/roles-and-permissions) |
| Set up the platform for my team | [Administration](/administration/administration) |
| Look up a tool in the MCP API | [Tool Reference](/mcp-server/tool-reference) |
| Understand what "self-healing" means | [AI Self-Healing](/web-testing/self-healing) |
***
## Platform Requirements
| Requirement | Detail |
| ------------------------- | ------------------------------------ |
| Supported browsers | Chromium, Firefox, WebKit (Safari) |
| Mobile platforms | iOS 14+, Android (API level 21+) |
| MCP server Python version | 3.9+ |
| MCP server default port | 8080 |
| Deployment options | Local (uv), Docker, Google Cloud Run |
***
## Common questions about ContextQA
What is ContextQA?
ContextQA is an AI-powered test automation platform for creating, executing, and maintaining web, mobile, API, and Salesforce tests. Teams can describe workflows in natural language, import requirements, or record an interaction, then review the generated test and its execution evidence.
Do I need to write code to use ContextQA?
No code is required for the standard test-creation and execution workflow. Testers can use natural-language instructions, recording, or supported imports. Developers and SDETs can still add custom JavaScript, API steps, CI/CD automation, or MCP-based agent workflows when they need more control.
What applications can ContextQA test?
ContextQA supports browser applications, Android and iOS apps, REST APIs, Salesforce, and documented enterprise workflows. Start with the [web](/web-testing/web-testing), [mobile](/mobile-testing/mobile-testing), [API](/api-testing/api-testing), or [Salesforce](/salesforce-testing/salesforce-testing) guide for target-specific prerequisites.
How does ContextQA reduce test maintenance?
Natural-language steps describe user intent instead of exposing brittle selector code. During web execution, self-healing can identify an equivalent element after routine UI drift and persist the repaired element reference when the match is sufficiently reliable. Genuine product failures still remain failures for investigation.
Can ContextQA run tests from CI/CD or an AI coding agent?
Yes. Teams can prepare test-plan quality gates for supported CI/CD systems, and authenticated MCP-compatible agents can use ContextQA tools to create tests, trigger executions, poll status, and retrieve results. See [Integrations](/integrations/integrations) and the [MCP Server](/mcp-server/overview).
Can search engines and AI tools read this documentation?
Yes. The public documentation provides crawlable HTML, a sitemap, an AI-oriented `llms.txt` index, and Markdown versions of individual pages. See [Use the Docs with Search and AI](/reference/using-contextqa-docs-with-ai) for the public endpoints and retrieval examples.
***
## Need Help?
* Search these docs using the search bar above
* Check the [Glossary](/reference/glossary) for term definitions
* Not sure where to start? [Browse by Role](/documentation-by-role/by-role)
* If a page is unclear or out of date, use the page-rating control at the bottom and include the heading or step that needs attention
***
{% hint style="info" %}
**Want a guided tour?** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — Our team will walk through ContextQA with your actual application and testing goals. Most teams are running their first tests within 24 hours of the demo.
{% endhint %}
# Browse by Role
Find the ContextQA documentation that's most relevant to your role — whether you're a tester, developer, QA manager, or technology leader.
## Quick answer
Find the ContextQA documentation that's most relevant to your role — whether you're a tester, developer, QA manager, or technology leader. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
Different people use ContextQA for different reasons. This section takes you directly to the workflows, tools, and concepts that matter most for your job.
***
## Choose Your Role
{% tabs %}
{% tab title="🧪 Tester" %}
**You want to:** Write automated tests without coding. Create, run, and review tests using natural language.
**Your quick wins:**
* Create a test in 5 minutes using plain English
* Run it on a real browser with full video evidence
* Let AI repair your tests when the UI changes
[**→ Documentation for Testers**](/documentation-by-role/by-role/for-testers)
{% endtab %}
{% tab title="⚙️ SDET" %}
**You want to:** Integrate ContextQA into your automation framework, use the MCP API, export to Playwright, and plug into CI/CD pipelines.
**Your quick wins:**
* Connect ContextQA to Claude/Cursor via MCP in 10 minutes
* Export any test as Playwright TypeScript
* Trigger test plans via REST from any CI system
[**→ Documentation for SDETs**](/documentation-by-role/by-role/for-sdets)
{% endtab %}
{% tab title="📋 QA Manager" %}
**You want to:** Manage test plans, track coverage metrics, analyze flaky tests, and communicate quality to leadership.
**Your quick wins:**
* Run a full regression suite and get a shareable report
* Identify flaky tests vs true regressions
* Set up nightly runs with Slack alerts
[**→ Documentation for QA Managers**](/documentation-by-role/by-role/for-qa-managers)
{% endtab %}
{% tab title="💻 Developer" %}
**You want to:** Generate tests from your tickets, add a quality gate to your PRs, and get root cause analysis without leaving your terminal.
**Your quick wins:**
* Generate tests from a Jira ticket before writing code
* Add a GitHub Actions quality gate in 15 minutes
* Get AI root cause in your terminal when tests fail
[**→ Documentation for Developers**](/documentation-by-role/by-role/for-developers)
{% endtab %}
{% tab title="🗺️ Product Manager" %}
**You want to:** Turn acceptance criteria into tests, track feature coverage, and get release readiness reports.
**Your quick wins:**
* Paste a Jira ticket URL → get automated test cases from your AC
* View release readiness as a pass/fail test plan summary
* Share authenticated execution URLs and controlled evidence artifacts with stakeholders
[**→ Documentation for Product Managers**](/documentation-by-role/by-role/for-product-managers)
{% endtab %}
{% tab title="🏗️ Eng Manager" %}
**You want to:** Configure CI/CD quality gates, manage team access, measure engineering productivity, and reduce testing toil.
**Your quick wins:**
* Add parallel test execution to your CI pipeline
* Configure SSO and role-based access for your team
* Measure self-healing rate (= manual work avoided)
[**→ Documentation for Engineering Managers**](/documentation-by-role/by-role/for-engineering-managers)
{% endtab %}
{% tab title="🚀 VP/CTO" %}
**You want to:** Understand the business case, architecture, security posture, and ROI for AI test automation at scale.
**Your quick wins:**
* Read the executive summary of business outcomes
* Review the build-vs-buy analysis
* See the enterprise implementation timeline
[**→ Documentation for VPs & CTOs**](/documentation-by-role/by-role/for-vp-engineering)
{% endtab %}
{% endtabs %}
***
## Role Matrix: Features by Persona
| Feature | Tester | SDET | QA Mgr | Developer | PM | Eng Mgr | VP/CTO |
| ------------------------------ | ------ | ---- | ------ | --------- | -- | ------- | ------ |
| Natural language test creation | ✅ | ✅ | | | | | |
| MCP Server (67 tools) | | ✅ | | ✅ | | | |
| Playwright code export | | ✅ | | ✅ | | | |
| Test Plans & scheduling | | ✅ | ✅ | | | ✅ | |
| Analytics dashboard | | | ✅ | | ✅ | ✅ | ✅ |
| AI test generation | ✅ | ✅ | | ✅ | ✅ | | |
| Jira integration | | ✅ | | ✅ | ✅ | | |
| CI/CD integration | | ✅ | | ✅ | | ✅ | |
| Roles & SSO | | | | | | ✅ | ✅ |
| ROI & coverage metrics | | | ✅ | | | ✅ | ✅ |
| Mobile testing | ✅ | ✅ | ✅ | | | | |
| Self-healing | ✅ | ✅ | ✅ | | | | |
***
## Not Sure Where to Start?
→ [Quickstart Guide](/getting-started/quickstart) — Create your first test in 5 minutes, regardless of role.
{% hint style="info" %}
**Talk to a human.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — Tell us your role and current testing challenges. We'll show you the exact features that matter most for your situation.
{% endhint %}
# For Testers
Stop writing brittle selectors. Write plain-English test steps, let AI handle execution, and spend your time on exploratory testing instead of script maintenance.
## Quick answer
Stop writing brittle selectors. Write plain-English test steps, let AI handle execution, and spend your time on exploratory testing instead of script maintenance. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** Manual testers, QA analysts, and automation beginners who want to write effective automated tests without learning to code.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
You already know how to test software. The problem is translating that knowledge into automation — learning XPath, fighting flaky selectors, and babysitting scripts that break every sprint. ContextQA eliminates that translation layer. You write what to test in plain English and the AI handles the rest.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## What You Can Do Without Writing Code
| Task | How |
| --------------------------- | ------------------------------------------------------------------------------------------- |
| Create a login test | Type: *"Go to /login, enter , click Login, verify dashboard appears"* |
| Test a checkout flow | Describe each step as you'd explain it to a colleague |
| Verify an error message | *"Submit the form with an invalid email, verify the error message says 'Invalid email'"* |
| Parameterize with test data | Upload a CSV with username/password pairs — ContextQA runs each row as a separate execution |
| Generate tests from Jira | Paste a Jira ticket URL and get complete test cases generated automatically |
| Record a test | Click through the UI once — ContextQA records your actions as reusable steps |
***
## Your Day-to-Day Workflow
### 1. Create Test Cases
Go to **Test Cases → New Test Case**. Enter a starting URL and describe each test step in natural language:
```
1. Navigate to https://your-staging-app.com/login
2. Enter "testuser@example.com" in the Email field
3. Enter "SecurePass123" in the Password field
4. Click the "Sign In" button
5. Verify the text "Welcome back" appears on the page
```
No selectors. No code. ContextQA's AI identifies the correct elements.
→ [Creating Test Cases in detail](/web-testing/creating-test-cases)
### 2. Run Your Tests
Click **Run** on an individual test case for focused feedback. To run a suite, add it to a test plan, then click **Run** on the plan. Watch execution happen in real time — a browser opens, your steps execute, and screenshots appear for each step.
→ [Running Tests](/execution/running-tests)
### 3. Review Evidence
Every execution captures:
* **Screenshot per step** — see exactly what the browser showed
* **Video recording** — full playback of the test run
* **Network log (HAR)** — every API call made during the test
* **Console log** — browser errors and warnings
* **AI root cause analysis** — when a test fails, AI explains why in plain English
→ [Video & Screenshots](/execution/video-and-screenshots)
### 4. Let AI Fix Broken Tests
When a developer changes a button label or moves a form field, your tests automatically heal. The AI detects the change, finds the correct element, and repairs the step. You get notified if the confidence is below 90% and a manual review is needed.
→ [AI Self-Healing](/web-testing/self-healing)
***
## Common Tester Scenarios
{% tabs %}
{% tab title="Login Testing" %}
**Testing login flows:**
1. Create a test case with your login page URL
2. Write steps: *Navigate → Enter credentials → Click Submit → Verify redirect*
3. Add a Test Data Profile with valid/invalid credential rows
4. Run — ContextQA tests every combination
For invalid credential testing, add a step: *"Verify the error message 'Invalid password' is displayed"*
{% endtab %}
{% tab title="Form Validation" %}
**Testing form validation:**
1. Describe each invalid input scenario as a separate step group
2. Use `Verify` steps to assert error messages: *"Verify the text 'This field is required' appears below the Email input"*
3. Group happy-path and error-path scenarios into separate test cases
Tip: Use the **Step Group** feature to create a reusable `SG_FillContactForm` group and insert it into multiple test cases.
{% endtab %}
{% tab title="Regression Testing" %}
**Running regression suites before a release:**
1. Organize your test cases into a **Test Suite** (e.g., "Smoke Tests", "Full Regression")
2. Create a **Test Plan** targeting the regression suite on Chrome + Firefox
3. Enable **parallel execution** — all tests run simultaneously
4. Review the summary: passed count, failed count, flaky tests detected
→ [Managing Test Suites](/web-testing/managing-test-suites)
{% endtab %}
{% tab title="Test Data" %}
**Data-driven testing:**
1. Create a Test Data Profile with columns matching your test's variables
2. Add rows for each scenario (valid login, expired account, locked user, etc.)
3. Reference variables in steps: *"Enter `{{username}}` in the Email field"*
4. ContextQA runs one execution per data row automatically
→ [Test Data Management](/web-testing/test-data-management)
{% endtab %}
{% endtabs %}
***
## Frequently Asked Questions
**Do I need to know how to code?** No. Test steps are plain English. The AI generates selectors, handles waits, and adapts when elements move.
**What if the AI picks the wrong element?** Use the **Test Steps Editor** to inspect what element was selected and adjust the description if needed. You can also add explicit identifiers like *"the button labeled 'Submit'"*.
**How do I test on different browsers?** Test Plans let you target Chrome, Firefox, and Safari in one run. Results are shown per-browser.
**Can I test behind a login that needs MFA?** Yes. Add MFA handling instructions to your **Knowledge Base** — the AI will follow them every time it encounters the MFA prompt.
***
## Start Here
{% hint style="success" %}
**Recommended path for new testers:**
1. [Quickstart Guide](/getting-started/quickstart) — create your first test in 5 minutes
2. [Creating Test Cases](/web-testing/creating-test-cases) — full step-by-step guide
3. [Test Data Management](/web-testing/test-data-management) — run multiple scenarios from a CSV
4. [AI Self-Healing](/web-testing/self-healing) — understand how your tests stay healthy
5. [Mobile Testing](/mobile-testing/mobile-testing) — automate iOS and Android app testing
{% endhint %}
{% hint style="info" %}
**Hands-on tutorials.** When you're ready to go beyond the basics, follow these guided, step-by-step walkthroughs:
* [Tutorial: Your first data-driven test](/web-testing/data-driven-testing-tutorial) — run a single test against multiple rows of input data.
* [Tutorial: Creating and reusing step groups](/web-testing/step-groups-tutorial) — bundle common steps into reusable building blocks.
{% endhint %}
***
{% hint style="info" %}
**Ready to see ContextQA in action?** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — Get a 30-minute walkthrough tailored to your application and testing goals.
*Join teams that reduced manual test maintenance by 70% with AI-powered self-healing.*
{% endhint %}
# For SDETs
Extend your automation framework with 67 MCP tools, export tests as Playwright code, manage test infrastructure via API, and let AI handle the maintenance burden so you focus on architecture.
## Quick answer
Extend your automation framework with 67 MCP tools, export tests as Playwright code, manage test infrastructure via API, and let AI handle the maintenance burden so you focus on architecture. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** Software Development Engineers in Test (SDETs), senior automation engineers, and QA engineers who write and maintain test frameworks.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
You've written the frameworks, built the CI/CD integrations, and maintained the test suites. You know the real cost: every sprint brings selector rot, environment drift, and another afternoon debugging why a locator stopped working. ContextQA augments your existing expertise with AI infrastructure that handles the brittle parts — so you focus on test architecture, coverage strategy, and toolchain integration.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## What ContextQA Adds to Your Stack
| Capability | Your Gain |
| -------------------------- | ------------------------------------------------------------------------- |
| 67 MCP tools | Full platform control from Claude, Cursor, or any MCP-compatible AI agent |
| `export_to_playwright` | Export any ContextQA test as runnable Playwright TypeScript code |
| `export_test_case_as_code` | Get the raw step definitions for custom framework integration |
| AI self-healing | Zero selector maintenance — AI fixes broken locators above 90% confidence |
| Evidence API | Programmatic access to screenshots, HAR, console logs, Playwright traces |
| Parallel execution | Run full regression in minutes across browsers and devices |
| CI/CD ready | Plan-based quality-gate pattern works across common pipeline tools |
***
## MCP Server Integration
ContextQA exposes a Model Context Protocol server at your configured endpoint. Every platform capability is available as a tool call from any MCP-compatible AI client.
**Key SDET tools:**
```python
# Create a test case from a URL + natural language description
create_test_case(
url="https://staging.yourapp.com/checkout",
task_description="Complete a purchase with a valid credit card and verify the order confirmation"
)
# Execute a test case and get the execution ID
execute_test_case(test_case_id=18750)
# Poll for completion
get_execution_status(test_case_id=18750, number_of_executions=1)
# Get results with step-level detail
get_test_case_results(result_id=26242)
get_test_step_results(result_id=26242)
# AI root cause analysis for failures
get_root_cause(execution_id=26242)
```
→ [MCP Server Overview](/mcp-server/overview) | [Tool Reference](/mcp-server/tool-reference)
***
## Exporting Tests as Playwright Code
Any test case created in ContextQA can be exported as Playwright TypeScript for use in your existing framework:
```python
# Via MCP tool
export_to_playwright(output_dir="./tests", test_case_ids=[18750])
```
The exported code includes:
* Page object model structure
* Resilient locator strategies (role-based + text-based + attribute fallbacks)
* Explicit wait patterns matching ContextQA's execution behavior
* Assertion calls using Playwright's `expect()` API
→ [Exporting Reports](/reporting/exporting-reports)
***
## CI/CD Integration Patterns
Use the same plan-based quality-gate design across GitHub Actions, Jenkins, GitLab CI, CircleCI, Azure DevOps, and other supported pipeline systems:
1. Manually validate the plan and environment before making it a required gate.
2. Store a dedicated API token in the CI provider's secret store.
3. Start the plan using the current public contract supplied for the workspace.
4. Keep the returned run ID and check status with a bounded timeout.
5. Map every documented non-success result to a failing job outcome.
6. Include the run ID in job output for traceability.
{% hint style="warning" %}
The verified production **CI / CD** tab describes start and status operations but does not display public endpoint paths. Do not infer a contract from portal network traffic or reuse legacy `/testplans/{id}/execute` examples.
{% endhint %}
→ [GitHub Actions](/integrations/github-actions) | [Jenkins](/integrations/jenkins) | [GitLab CI](/integrations/gitlab-ci)
***
## Test Architecture Best Practices
### Step Groups as Reusable Libraries
Build a `SG_Auth` step group containing your login flow. Reference it in every test case that requires authentication. When the login form changes, update `SG_Auth` once — all test cases inherit the fix automatically.
### Environments for Multi-Stage Testing
Define `staging`, `qa`, and `production` environments with their respective base URLs and API keys. Test Plans reference an environment by name — the same plan runs against any stage without modification.
→ [Environments](/execution/environments)
### Knowledge Base for Application Context
Add known UI quirks to the Knowledge Base:
* *"Always dismiss the cookie consent banner before interacting with the page"*
* *"The loading spinner takes up to 8 seconds on the checkout page"*
* *"Use credentials / TestPass123 for MFA bypass in staging"*
The AI reads these instructions before every execution — reducing false failures from environment-specific behavior.
→ [Knowledge Base](/ai-features/knowledge-base)
### Custom Agents for Domain Logic
Create a Custom Agent with a tailored system prompt for complex scenarios:
* A Salesforce-aware agent that understands Lightning UI navigation patterns
* An accessibility agent that verifies ARIA labels on every step
* A performance agent that flags any network request exceeding 2 seconds
→ [Custom Agents](/ai-features/custom-agents)
***
## Evidence & Debugging API
Every execution produces a queryable evidence package:
| Tool | Returns |
| ----------------------- | -------------------------------------------------------- |
| `get_test_step_results` | Per-step pass/fail, screenshot URL, assertion detail |
| `get_console_logs` | Browser console entries (errors, warnings, info) |
| `get_network_logs` | Full HAR network log for the execution |
| `get_trace_url` | Playwright trace viewer URL (`.zip` downloadable) |
| `get_root_cause` | AI classification + suggested fix + affected step number |
| `get_ai_reasoning` | Full AI reasoning chain for the execution |
| `get_ai_insights` | Pattern-based insights across multiple executions |
→ [Execution & Results tools](/mcp-server/tool-reference/execution-and-results)
***
## Flaky Test Management
ContextQA automatically classifies failures across four categories:
* **Test bug** — the test assertion is incorrect
* **Application bug** — the application has a regression
* **Flaky failure** — the test passes on retry, likely a timing issue
* **Environment issue** — infrastructure or network problem
Use `get_root_cause` to retrieve this classification programmatically and route failures to the correct team automatically.
→ [Flaky Test Detection](/reporting/flaky-test-detection)
***
{% hint style="success" %}
**Recommended next steps for SDETs:**
1. [MCP Server Installation](/mcp-server/installation-and-setup) — connect your AI agent in 10 minutes
2. [Tool Reference](/mcp-server/tool-reference) — full 67-tool catalog with parameters
3. [Agent Integration Guide](/mcp-server/agent-integration-guide) — Claude/Cursor integration patterns
4. [CI/CD integrations](/integrations/github-actions) — drop-in pipeline configs
{% endhint %}
***
{% hint style="info" %}
**See the platform from an SDET's perspective.** [**Book a Technical Demo →**](https://contextqa.com/book-a-demo/) — A 45-minute deep-dive into MCP tooling, API patterns, and CI/CD integration with your actual test infrastructure.
*SDETs using ContextQA report 70% less time spent on test maintenance.*
{% endhint %}
# For QA Managers
Get full visibility into test coverage, release readiness, and team productivity. Manage test plans across products, track flaky test trends, and demonstrate QA's impact with concrete metrics.
## Quick answer
Get full visibility into test coverage, release readiness, and team productivity. Manage test plans across products, track flaky test trends, and demonstrate QA's impact with concrete metrics. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA Managers, Test Leads, and QA Directors responsible for test strategy, team productivity, and release quality across one or more products.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
Your job is to answer two questions before every release: *Is this ready to ship?* and *How confident are we?* ContextQA gives you the dashboards, analytics, and reporting to answer both — without spending three hours aggregating spreadsheets before a go/no-go meeting.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## Management Overview
| What You Need | Where to Find It |
| ----------------------------- | ------------------------------------------------------------------------------------ |
| Release readiness at a glance | Test Plan execution summary: pass rate, failed count, duration |
| Coverage gaps | Analytics Dashboard → untested flows by feature area |
| Flaky test trends | Flaky Test Detection report — recurring failures vs true regressions |
| Team velocity | Test cases created per sprint, executions per week |
| Failure root causes | AI failure classification: application bug / test bug / environment issue |
| Controlled reporting | Share authenticated run URLs, Execution History CSV, or available evidence artifacts |
| CI/CD quality gates | Automated pass/fail status integrated into your deployment pipeline |
***
## Test Plans: Your Release Gates
A Test Plan is a named execution configuration that runs specific test suites against specific environments and browsers. Think of it as your release checklist, automated.
**Typical setup:**
* **Smoke Plan** — 15 critical path tests, runs on every commit (< 3 minutes)
* **Regression Plan** — Full suite, runs nightly or before every release (30–60 minutes parallel)
* **Release Gate Plan** — Smoke + Regression + API tests on Production-equivalent environment
Each plan returns a single **pass/fail/partial** result you can wire into your deployment pipeline.
→ [Running Tests](/execution/running-tests) | [Parallel Execution](/execution/parallel-execution)
***
## Analytics Dashboard
The Analytics Dashboard gives you a time-series view of your test suite health:
{% tabs %}
{% tab title="Pass Rate Trends" %}
Track pass rate over time per suite, per environment, and per browser. Spot when a release introduced new failures. Drill into any data point to see the individual test results.
{% endtab %}
{% tab title="Failure Analysis" %}
View failures grouped by:
* **Root cause type** — application bug, test bug, flaky, environment
* **Feature area** — based on suite organization
* **Browser/device** — identify browser-specific regressions
AI-generated summaries explain the most impactful failures in plain English.
{% endtab %}
{% tab title="Coverage Gaps" %}
Use the `analyze_coverage_gaps` MCP tool or the Coverage view in the portal to identify:
* User flows with no test coverage
* High-risk code paths with low test density
* New features added this sprint with no associated tests
{% endtab %}
{% tab title="Flaky Tests" %}
ContextQA tracks test stability over time. The Flaky Test report shows:
* Tests that failed then passed on immediate re-run (likely flaky)
* Tests failing consistently (likely application regression)
* Failure frequency and affected environments
{% endtab %}
{% endtabs %}
→ [Analytics Dashboard](/reporting/analytics-dashboard) | [Flaky Test Detection](/reporting/flaky-test-detection)
***
## Reporting for Stakeholders
### Shareable Report Links
Every test plan execution has a stable result URL. Recipients must sign in to the target ContextQA organization and have permission to view the run.
### Failure Analysis Reports
After a failed release candidate, generate a failure analysis that includes:
* Total failures with severity breakdown
* AI classification (is this a test problem or an application problem?)
* Screenshot evidence for each failure
* Suggested remediation steps
→ [Failure Analysis](/reporting/failure-analysis) | [How to Debug a Failing Test](/reporting/debugging-failing-tests)
### Export Options
* **Authenticated result URL** — for the complete portal view
* **Playwright code export** — for engineering teams who want to reproduce failures locally
* **Execution-history CSV** — for the active plan-history matrix or summary view
* **Downloaded evidence artifacts** — for technical review and controlled archival
→ [Exporting Reports](/reporting/exporting-reports)
***
## Team & Access Management
### Roles and Permissions
Control what each team member can do:
| Role | Capabilities |
| ----------- | --------------------------------------------------------------- |
| **Admin** | Full access including workspace settings, integrations, billing |
| **Manager** | Create/manage test plans, view all results, manage team members |
| **Tester** | Create and run test cases, view results |
| **Viewer** | Read-only access to results and reports |
→ [Roles & Permissions](/administration/roles-and-permissions)
### Team Organization
Organize testers by product area, feature team, or testing type (web, mobile, API). Each team member works in the same shared workspace with full visibility into each other's work.
→ [Team Management](/administration/team-management)
***
## Scheduling and Continuous Testing
Set test plans to run automatically:
* **On commit** — trigger via GitHub Actions, Jenkins, or GitLab CI webhook
* **On schedule** — nightly regression, Monday morning smoke test
* **On demand** — one-click execution from the portal
Slack notifications alert the right people when a plan fails — with a direct link to the failure report.
→ [Scheduling](/execution/scheduling) | [Slack Integration](/integrations/slack)
***
## Communicating QA Value to Leadership
Use these metrics in your sprint reviews and executive reports:
| Metric | How to Measure in ContextQA |
| --------------------------------- | ----------------------------------------------------------- |
| **Test coverage %** | Analytics Dashboard → Coverage view |
| **Defects caught pre-production** | Failure Analysis → classified as "Application Bug" |
| **Mean time to detect (MTTD)** | Time from commit to first test failure notification |
| **Test maintenance effort** | Track self-healing events — each heal = manual work avoided |
| **Release confidence score** | Test Plan pass rate on release candidate build |
***
{% hint style="success" %}
**Recommended path for QA Managers:**
1. [Analytics Dashboard](/reporting/analytics-dashboard) — understand what's available
2. [Test Results](/reporting/test-results) — navigate the results interface
3. [Failure Analysis](/reporting/failure-analysis) — diagnose why a release candidate failed, with AI root-cause classification
4. [How to Debug a Failing Test](/reporting/debugging-failing-tests) — step through a failure to its root cause
5. [Flaky Test Detection](/reporting/flaky-test-detection) — clean up your test suite
6. [AI Self-Healing](/web-testing/self-healing) — understand how tests maintain themselves
7. [Jira Integration](/integrations/jira) — connect Jira for defect tracking
8. [Roles & Permissions](/administration/roles-and-permissions) — set up your team
9. [Scheduling](/execution/scheduling) — automate your regression runs
{% endhint %}
***
{% hint style="info" %}
**Want to see your team's test coverage gaps?** [**Book a QA Strategy Demo →**](https://contextqa.com/book-a-demo/) — We'll analyze your current test suite and show you exactly where ContextQA closes the gaps.
*QA managers using ContextQA report 3× more releases per quarter with the same team size.*
{% endhint %}
# For Developers
Generate tests from your Jira tickets, trigger test runs from your IDE via MCP, get AI root cause analysis in your terminal, and never break production again.
## Quick answer
Generate tests from your Jira tickets, trigger test runs from your IDE via MCP, get AI root cause analysis in your terminal, and never break production again. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** Frontend developers, full-stack engineers, and backend developers who want fast feedback on their changes without becoming QA experts.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
You're not a tester — but you're responsible for not breaking things. ContextQA integrates directly into your development workflow: generate tests from your tickets before you write the first line of code, run them from your IDE via MCP, and get AI-generated root cause reports in your terminal when something fails.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## Developer Workflow Integration
### Generate Tests from Your Jira Ticket
Before writing code, generate test cases from the acceptance criteria in your Jira ticket:
```python
# In Claude / Cursor with ContextQA MCP connected
generate_tests_from_jira_ticket(
ticket_id="PROJ-456"
)
# → Creates 3 test cases covering the acceptance criteria
# → Test Case IDs: 18850, 18851, 18852
```
This gives you a test suite to run against your branch before opening a PR — no QA involvement required for the initial coverage.
→ [AI Test Generation](/ai-features/ai-test-generation)
### Run Tests from Your Terminal
With the ContextQA MCP server connected to your AI coding assistant:
```
# Ask Claude/Cursor directly:
"Run test case 18850 and tell me if it passes"
# Or use the MCP tool directly:
execute_test_case(test_case_id=18850)
```
You get back a pass/fail result with screenshot and video evidence — no context switching to a browser.
### Get Root Cause in Seconds
When a test fails, don't stare at a cryptic error. Ask for root cause:
```python
get_root_cause(execution_id=26300)
# Returns:
# {
# "rootCause": "The 'Add to Cart' button was not found on the product page.",
# "affectedStep": 4,
# "errorType": "APPLICATION_BUG",
# "remediation": "Check that the ProductCard component renders the button when stock > 0.",
# "evidenceLinks": ["screenshot_step_4", "console_log", "har"]
# }
```
The `errorType` field tells you immediately: is this your bug or a test problem?
→ [Failure Analysis](/reporting/failure-analysis)
***
## CI/CD Quality Gate
Use a ContextQA test plan as a pull-request or deployment check. The pipeline starts a validated plan, keeps the returned run ID, checks its status with a bounded timeout, and fails for every documented non-success result.
Create a dedicated [API token](/administration/api-tokens) instead of storing a user's ContextQA password in the repository. Keep the token in the CI provider's secret store and the plan ID in a pipeline variable.
{% hint style="warning" %}
The current production **CI / CD** tab lists GitHub, GitLab, Bitbucket, Azure DevOps, CircleCI, Codeship, Bamboo, Jenkins, AWS, TravisCI, and a generic shell option, but it does not display public endpoint paths. Use the public contract supplied for your workspace; do not reuse legacy `/auth/login` or `/testplans/{id}/execute` examples.
{% endhint %}
→ [GitHub Actions Integration](/integrations/github-actions)
***
## Generating Tests from Your Codebase
If you have code changes that need test coverage, generate tests based on the diff:
```python
generate_tests_from_code_change(
diff_text="Added a discount code field to the checkout form. Valid codes apply 10-20% off.",
app_url="https://staging.yourapp.com"
)
```
For API changes, generate tests directly from your OpenAPI/Swagger spec:
```python
generate_tests_from_swagger(
file_path_or_url="https://staging.yourapp.com/api/docs/swagger.json"
)
```
→ [Creating API Tests](/api-testing/creating-api-tests)
***
## API Testing for Backend Developers
ContextQA supports REST API testing natively — no browser required:
{% tabs %}
{% tab title="Create API Test" %}
```
Step 1: POST https://api.yourapp.com/users
Body: {"email": "test@example.com", "password": "SecurePass123"}
Assert: Status 201
Assert: Response body contains "userId"
```
{% endtab %}
{% tab title="Chain API Calls" %}
API Chaining lets you use response values in subsequent requests:
```
Step 1: POST /auth/login → extract token from response
Step 2: GET /users/profile → use token in Authorization header
Step 3: Assert profile.email equals "test@example.com"
```
{% endtab %}
{% tab title="Validate Responses" %}
Assert on:
* HTTP status codes
* Response body fields (exact match, contains, regex)
* Response headers
* Response time (SLA validation)
* Schema compliance (JSON Schema validation)
{% endtab %}
{% endtabs %}
→ [API Testing Overview](/api-testing/api-testing)
***
## Connecting Your AI Coding Assistant
Connect Claude, Cursor, ChatGPT, Codex, or another MCP-compatible client to the hosted ContextQA MCP server:
```json
{
"mcpServers": {
"contextqa": {
"url": "https://mcp.contextqa.com/mcp"
}
}
}
```
The hosted server uses OAuth 2.0. The first tool call opens a browser so you can sign in; no local MCP checkout or password in the configuration is required.
Once connected, you can ask your AI assistant to:
* *"Run the smoke test suite on the staging environment"*
* *"Generate tests for the new payment flow I just built"*
* *"Why did test case 18850 fail in the last run?"*
* *"Create a test plan that covers all checkout tests"*
→ [MCP Installation & Setup](/mcp-server/installation-and-setup) | [Agent Integration Guide](/mcp-server/agent-integration-guide)
***
## Reproducing Bugs from Tickets
When a bug is reported in Jira, reproduce it automatically:
```python
reproduce_from_ticket(
ticket_text="BUG-789: Add to Cart button not visible on product page when stock > 0",
url="https://yourcompany.app.com/products"
)
# Analyzes the bug description and steps to reproduce
# Generates and executes a reproduction test case
# Returns: pass/fail + evidence if reproduced
```
→ [Bug, Defect & Advanced Testing tools](/mcp-server/tool-reference/bug-defect-and-advanced)
***
{% hint style="success" %}
**Recommended path for developers:**
1. [MCP Installation](/mcp-server/installation-and-setup) — connect to your IDE in 10 minutes
2. [AI Test Generation](/ai-features/ai-test-generation) — generate tests from Jira tickets
3. [Jira Integration](/integrations/jira) — connect Jira for automatic defect filing
4. [GitHub Actions](/integrations/github-actions) — add a CI quality gate
5. [API Testing](/api-testing/api-testing) — test your endpoints directly
{% endhint %}
***
{% hint style="info" %}
**Ship faster without breaking things.** [**Book a Developer Demo →**](https://contextqa.com/book-a-demo/) — See how to integrate ContextQA into your PR workflow in under 15 minutes.
*Development teams using ContextQA catch 80% more regressions before they reach production.*
{% endhint %}
# For Product Managers
Turn your Jira tickets into automated test cases, get release readiness reports you can trust, and ensure every feature ships with test coverage before it reaches users.
## Quick answer
Turn your Jira tickets into automated test cases, get release readiness reports you can trust, and ensure every feature ships with test coverage before it reaches users. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** Product Managers and Product Owners who define features, write acceptance criteria, and need confidence that what ships matches what was specified.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
You write the requirements. You define done. But by the time a feature reaches QA, your acceptance criteria has often been interpreted, compressed, or partially tested. ContextQA closes that loop: your Jira ticket becomes automated test cases automatically, so every feature is tested against your original specification — not an engineer's interpretation of it.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## From Ticket to Test in One Step
Paste your Jira ticket URL into ContextQA (or ask your AI assistant with ContextQA MCP connected) and get automated test cases generated from your acceptance criteria:
**Your Jira ticket:**
```
PROJ-456: Add discount code field to checkout
Acceptance Criteria:
- Valid discount codes reduce the order total by the configured percentage
- Invalid codes show an error message "Invalid discount code"
- Expired codes show "This discount code has expired"
- The discount amount is visible in the order summary
```
**ContextQA generates:**
* Test Case 1: Apply valid 10% discount code → verify order total reduced
* Test Case 2: Enter invalid code → verify error message displayed
* Test Case 3: Enter expired code → verify expiry message displayed
* Test Case 4: Verify discount line item appears in order summary
Your acceptance criteria, automated. No manual interpretation.
→ [AI Test Generation from Jira](/ai-features/ai-test-generation)
***
## Release Readiness at a Glance
Before every release, you need one number: *what percentage of the acceptance criteria is passing?* The Test Plan summary gives you exactly that:
| Metric | What It Tells You |
| --------------------- | ----------------------------------------- |
| **Pass rate** | % of tests passing right now |
| **Failed count** | Number of failing acceptance criteria |
| **Test coverage** | Features with tests vs features without |
| **Blocking failures** | Critical path tests that are failing |
| **AI root cause** | Plain-English explanation of each failure |
You can share this directly with engineering, stakeholders, or in your release review meeting — no technical interpretation required.
→ [Test Results](/reporting/test-results) | [Analytics Dashboard](/reporting/analytics-dashboard)
***
## Feature Coverage Tracking
Track which features have test coverage and which don't:
{% tabs %}
{% tab title="Coverage by Feature" %}
Organize test suites to mirror your feature areas:
* `checkout-flow/` suite → tests for all checkout AC
* `user-account/` suite → profile, settings, preferences
* `notifications/` suite → email, in-app, push
The Analytics Dashboard shows pass rate and coverage percentage per suite — giving you a feature-level view of quality.
{% endtab %}
{% tab title="Sprint Coverage" %}
After each sprint, check: do all stories from the sprint have test coverage?
Use the `analyze_coverage_gaps` tool (via your team's AI assistant) to identify stories from the last sprint that have no associated test cases — and flag them before they ship.
{% endtab %}
{% tab title="Release Signoff" %}
Create a **Release Gate Test Plan** that runs every test covering the features in the current release. Before shipping:
1. Run the Release Gate plan
2. Review the summary
3. Sign off on green or escalate failures
This creates an auditable quality record tied to each release.
{% endtab %}
{% endtabs %}
***
## Communicating Quality to Stakeholders
### Release Quality Reports
ContextQA generates shareable reports that non-technical stakeholders can understand:
* **Pass rate trend** — is quality improving or declining?
* **Feature risk map** — which features have low test coverage?
* **Failure breakdown** — how many failures are application bugs vs test configuration?
* **Regression detection** — how many regressions were caught before reaching production?
Share the authenticated execution URL with stakeholders who have organization access. For a spreadsheet summary, export the active Execution History view to CSV; ContextQA does not currently provide a general PDF export of the complete run.
→ [Exporting Reports](/reporting/exporting-reports)
### Bug Prevention Metrics
Use these figures to quantify QA's value to leadership:
| Metric | Source |
| --------------------------------- | -------------------------------------------------------- |
| Regressions caught pre-production | Failures classified as "Application Bug" in ContextQA |
| Test coverage % | Analytics Dashboard coverage view |
| Release speed | Compare release cadence before/after ContextQA adoption |
| Manual testing time saved | Self-healing events = manual investigation hours avoided |
***
## Working with Your Engineering Team
### Connecting Jira for Defect Tracking
When ContextQA finds a failure, it can automatically create a Jira issue:
1. The test fails
2. AI generates root cause analysis
3. A Jira ticket is created with: failure summary, affected step, screenshot evidence, and suggested fix
4. The ticket is assigned to the relevant engineer
No manual bug filing. No screenshot copy-paste. The defect goes directly into your workflow.
→ [Jira Integration](/integrations/jira)
### Slack Notifications
Get notified in the right Slack channel when:
* A nightly regression run fails
* A critical path test fails after a deployment
* A new test plan completes with a summary
→ [Slack Integration](/integrations/slack)
***
## Generating Tests from Figma Designs
If your team uses Figma for design specs, ContextQA can generate tests directly from design files — before the feature is even built:
```
generate_tests_from_figma(
figma_url="https://figma.com/file/ABC123/Checkout-Redesign",
workspace_version_id=YOUR_WV_ID
)
```
Tests are created based on the UI elements and interaction patterns defined in the design. When engineering ships the feature, the tests are already waiting.
→ [AI Test Generation](/ai-features/ai-test-generation)
***
{% hint style="success" %}
**Recommended path for Product Managers:**
1. [AI Test Generation](/ai-features/ai-test-generation) — understand how tickets become tests
2. [Analytics Dashboard](/reporting/analytics-dashboard) — your release readiness view
3. [Jira Integration](/integrations/jira) — connect defect tracking
4. [Test Results](/reporting/test-results) — read and share execution reports
{% endhint %}
***
{% hint style="info" %}
**Ship features that actually match your acceptance criteria.** [**Book a Product Demo →**](https://contextqa.com/book-a-demo/) — See how your Jira tickets become automated test cases in minutes.
*Teams using ContextQA catch acceptance criteria failures before sprint review — not after production release.*
{% endhint %}
# For Engineering Managers
Ship faster with quality gates that don't slow you down. Get team-level test coverage metrics, reduce MTTD, and give your engineers AI testing infrastructure that scales with your product.
## Quick answer
Ship faster with quality gates that don't slow you down. Get team-level test coverage metrics, reduce MTTD, and give your engineers AI testing infrastructure that scales with your product. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** Engineering Managers, Dev Leads, and Technical Leads responsible for engineering productivity, CI/CD pipelines, and the balance between velocity and quality.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
Your team ships fast. The question is whether quality keeps up. Every escaped regression costs more to fix than it would have taken to catch — and every slow CI pipeline taxes developer productivity. ContextQA gives you AI-powered quality gates that run in parallel, heal themselves, and integrate with the toolchain your engineers already use.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## The Engineering Manager Dashboard
Key metrics available in ContextQA:
| Metric | Why It Matters |
| ------------------------------ | ----------------------------------------------------- |
| **Test execution time** | Is your CI pipeline fast enough to run on every PR? |
| **Pass rate by feature team** | Which team is shipping the most regressions? |
| **Self-healing rate** | How much manual maintenance would AI have required? |
| **MTTD (Mean Time to Detect)** | How quickly are failures caught after a commit? |
| **Flaky test count** | Flakiness = false CI failures = developer frustration |
| **Coverage gaps** | Untested code paths that are risk vectors |
***
## CI/CD Integration
Use a ContextQA test plan as a quality gate between a validated environment and the next release stage. The pipeline starts the plan, keeps the returned run ID, checks its status with a bounded timeout, and stops the release for every documented non-success result.
Before requiring the gate, the team should validate the pass, failure, timeout, and expired-token paths. Use a small plan for pull-request feedback and reserve broader regression plans for release or scheduled workflows.
{% hint style="warning" %}
The current production **CI / CD** tab lists supported pipeline systems and describes start and status operations, but it does not display public endpoint paths. Implementation owners should use the current public contract supplied for the workspace, not legacy examples or portal network calls.
{% endhint %}
CI/CD integrations available:
| Platform | Guide |
| -------------- | ------------------------------------------------- |
| GitHub Actions | [Integration Guide](/integrations/github-actions) |
| Jenkins | [Integration Guide](/integrations/jenkins) |
| GitLab CI | [Integration Guide](/integrations/gitlab-ci) |
| CircleCI | [Integration Guide](/integrations/circleci) |
| Azure DevOps | [Integration Guide](/integrations/azure-devops) |
***
## Team Scalability
### Multi-Team Workspace Organization
Organize test suites by team or feature area:
* `team-payments/` — owned by the payments team
* `team-auth/` — owned by the auth team
* `team-mobile/` — owned by the mobile team
Each team maintains their own suite. The Release Gate Test Plan aggregates them for release qualification.
### Role-Based Access
| Role | Typical Assignment |
| ------- | ----------------------------------------- |
| Admin | EM, QA Lead |
| Manager | Senior QA, Tech Lead |
| Tester | QA Engineers, developers with test duties |
| Viewer | Product, stakeholders |
→ [Roles & Permissions](/administration/roles-and-permissions)
### SSO Integration
Connect to your company's identity provider for centralized access management:
* **SAML 2.0** — Okta, Azure AD, Google Workspace, OneLogin
* **OAuth 2.0** — GitHub, Google
Engineer onboarding and offboarding handled through your existing IdP — no separate ContextQA account management.
→ [SSO & Authentication](/administration/sso-and-authentication)
***
## Reducing Engineering Toil
### AI Self-Healing: Quantified
Every time a UI element changes and the AI heals a test automatically:
* **Without ContextQA**: An engineer spends 20–60 minutes investigating the failure, updating the selector, re-running the test
* **With ContextQA**: Zero engineer time for heals with confidence ≥ 90%
At scale across a large test suite, self-healing represents hundreds of engineer-hours saved per quarter.
→ [AI Self-Healing](/web-testing/self-healing)
### MCP Server: Testing Infrastructure as Code
Give your engineers an AI-native testing interface. Any AI coding assistant (Claude, Cursor, GPT-4 with MCP plugin) can:
* Generate test cases from requirements or Jira tickets
* Execute test plans and retrieve results
* Get AI root cause analysis for failures
* Create defect tickets in Jira
This means testing becomes a native part of the AI-assisted development workflow — not a separate tool context switch.
→ [MCP Server Overview](/mcp-server/overview)
***
## Quality Gates: Recommended Configuration
### For Every Commit (PR Check)
* **Suite**: Smoke Tests (10–20 critical path tests)
* **Parallel**: `parallelNode: 5`
* **Target time**: < 3 minutes
* **Gate**: Block merge if any smoke test fails
### For Every Merge to Main (Pre-Deploy)
* **Suite**: Feature regression (tests for everything changed this sprint)
* **Parallel**: `parallelNode: 10`
* **Target time**: 8–12 minutes
* **Gate**: Block deploy if > 2 failures
### Nightly Regression
* **Suite**: Full regression
* **Environments**: staging + production-replica
* **Notification**: Slack channel `#qa-alerts`
* **Review**: QA Manager reviews failures before standup
***
## Incident Response and Debugging
When a production incident occurs, use ContextQA to:
1. **Run a targeted test plan** against the affected feature area immediately
2. **Review evidence** — screenshots, HAR logs, console errors per test step
3. **Get AI root cause** — classify the failure: application regression, infrastructure issue, or environment problem
4. **Compare with last green run** — did this test pass before the latest deploy?
The full evidence package (video, HAR, trace) accelerates post-incident analysis and reduces MTTR.
→ [Failure Analysis](/reporting/failure-analysis)
***
## Onboarding Engineers to ContextQA
Estimated onboarding time by role:
| Engineer Type | Onboarding Path | Time |
| ---------------------- | --------------------------------------------------------------------------------------------------- | ------ |
| New to automation | [Quickstart](/getting-started/quickstart) + [Creating Test Cases](/web-testing/creating-test-cases) | 1 hour |
| Experienced tester | [Test Plans](/execution/running-tests) + [Environments](/execution/environments) | 30 min |
| SDET / API integration | [MCP Server](/mcp-server/installation-and-setup) + [Tool Reference](/mcp-server/tool-reference) | 1 hour |
| CI/CD owner | [GitHub Actions](/integrations/github-actions) or [Jenkins](/integrations/jenkins) | 30 min |
***
{% hint style="success" %}
**Recommended path for Engineering Managers:**
1. [Parallel Execution](/execution/parallel-execution) — configure CI speed
2. [Environments](/execution/environments) — set up staging/production configurations
3. [Roles & Permissions](/administration/roles-and-permissions) — configure team access
4. [SSO & Authentication](/administration/sso-and-authentication) — connect your IdP
5. [Analytics Dashboard](/reporting/analytics-dashboard) — measure quality metrics
{% endhint %}
***
{% hint style="info" %}
**See how ContextQA fits into your engineering stack.** [**Book an Engineering Demo →**](https://contextqa.com/book-a-demo/) — A technical walkthrough covering CI/CD integration, parallelism configuration, and MCP tooling for your team.
*Engineering teams using ContextQA ship 3× more releases per quarter without increasing QA headcount.*
{% endhint %}
# For VPs & CTOs
The business case for AI-powered test automation. Reduce engineering toil, accelerate release cadence, and build a quality-at-speed culture without growing your QA headcount.
## Quick answer
The business case for AI-powered test automation. Reduce engineering toil, accelerate release cadence, and build a quality-at-speed culture without growing your QA headcount. Use this page to identify the ContextQA workflows, controls, and evidence that matter most for this role.
## What this page covers
{% hint style="info" %}
**Who is this for?** VPs of Engineering, CTOs, and technology leaders making infrastructure and tooling decisions for engineering organizations.
{% endhint %}
{% hint style="info" %}
**New to ContextQA?** Start with [Core Concepts](/getting-started/core-concepts) for the key terminology used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
Quality at speed is not a tradeoff — it's an architecture decision. The traditional testing model scales linearly with headcount: more features require more testers. ContextQA breaks that model. AI handles the execution, maintenance, and analysis, while your engineers focus on building. The result: higher release velocity with no increase in defect escape rate.
{% hint style="info" %}
**New to ContextQA?** Read [Core Concepts](/getting-started/core-concepts) first to get familiar with the key terms used throughout these docs — Workspace, Test Case, Test Suite, Test Plan, and Environment.
{% endhint %}
***
## Executive Summary
| Business Outcome | How ContextQA Delivers |
| -------------------------------------------- | ----------------------------------------------------------------------------------------- |
| **70% reduction in test maintenance effort** | AI self-healing repairs broken tests automatically above 90% confidence |
| **10× faster test execution** | AI-powered parallel execution pipeline; configurable parallelism scales to any suite size |
| **3× more releases per quarter** | Faster CI loops + automated quality gates eliminate manual sign-off bottlenecks |
| **Zero-headcount scaling** | AI generates, executes, and analyzes tests; team size doesn't limit test coverage |
| **Reduced MTTR** | AI root cause analysis classifies failures in seconds vs hours of manual debugging |
| **Universal coverage** | Web, mobile (iOS/Android), REST API, Salesforce, SAP from a single platform |
***
## The Business Case
### Testing at Scale is a People Problem
A typical enterprise engineering org spends 30–40% of QA engineering time on test maintenance — updating selectors, investigating false failures, chasing flaky tests. As the codebase grows, this percentage grows with it. The traditional solution is to hire more QA engineers.
**ContextQA eliminates the root cause:**
* **Selector rot** → AI self-healing: heals automatically, no engineer intervention
* **Flaky tests** → AI classification: identifies flakiness vs regressions, stops false alerts
* **Manual test creation** → AI generation: Jira tickets, Figma designs, Swagger specs → test cases in seconds
* **Root cause investigation** → AI analysis: failure classification + suggested fix + evidence in 30 seconds
### Compliance and Audit Readiness
Every test execution produces an immutable evidence package:
* Screenshots per step
* Full video recording
* Network log (HAR)
* Browser console log
* AI reasoning trace
* Playwright execution trace
This evidence package supports SOC 2, ISO 27001, and HIPAA compliance requirements for software quality validation. All evidence is stored with timestamps and linked to specific build artifacts.
### The MCP Multiplier
ContextQA exposes its full platform as a Model Context Protocol (MCP) server — 67 tools that any AI coding assistant can call. This means your engineers' AI tools (Claude, Cursor, GitHub Copilot with MCP) can create tests, run them, and interpret failures without leaving their development environment.
**The compounding effect:** As your engineers adopt AI coding assistants (which most already have), they automatically gain testing superpowers through ContextQA MCP — no additional training, no new workflows, no context switching.
***
## Platform Architecture Overview
ContextQA is a multi-tenant SaaS platform:
| Component | Detail |
| ---------------------------- | ------------------------------------------------------------------ |
| **Execution infrastructure** | Managed browser farm (Chrome, Firefox, Safari, mobile devices) |
| **AI pipeline** | AI execution pipeline running on real browsers |
| **MCP server** | Containerized; runs in your environment or ContextQA-hosted |
| **Data residency** | Evidence stored in regional object storage; configurable retention |
| **Authentication** | SAML 2.0 + OAuth 2.0; SSO with Okta, Azure AD, Google Workspace |
| **Uptime SLA** | 99.9% execution infrastructure availability |
| **API access** | Full REST API; MCP server for AI agent access |
***
## Build vs Buy Analysis
| Factor | Build in-house | ContextQA |
| ---------------------------- | -------------------------- | --------- |
| Time to production | 6–18 months | Days |
| AI self-healing | Requires ML team | Included |
| Browser farm maintenance | DevOps overhead | Managed |
| Mobile device management | Significant infrastructure | Managed |
| MCP server for AI agents | Requires SDK expertise | Included |
| Evidence storage & retrieval | Custom development | Included |
| CI/CD integrations | Per-platform engineering | Pre-built |
| Ongoing maintenance | Dedicated team | Included |
The build-vs-buy math is clear for test automation infrastructure. Your engineers' time is better spent building your product.
***
## Enterprise Deployment Options
### Cloud (SaaS)
* Zero infrastructure management
* Instant provisioning
* Automatic updates
* SOC 2 Type II certified infrastructure
### Self-Hosted MCP Server
* MCP server runs in your VPC
* Test execution remains in ContextQA cloud
* API tokens never leave your network boundary
* Suitable for regulated industries
### Enterprise SSO
* SAML 2.0 with all major IdPs
* Centralized user provisioning/deprovisioning
* Role-based access aligned to your org structure
→ [SSO & Authentication](/administration/sso-and-authentication) | [Administration Overview](/administration/administration)
***
## ROI Framework
Use this framework for internal business case development:
**Input variables:**
* Number of test cases in your suite: `N`
* Average time to manually investigate + fix a broken test: `H` hours
* Engineer hourly cost: `C`
* Monthly test breaks without AI healing: `B`
**Monthly savings calculation:**
```
Self-healing savings = N × (failure rate %) × H × C
≈ Typically $15,000–$80,000/month for 500+ test suites
```
**Additional value:**
* Regressions caught pre-production (each escaped bug = $10k–$100k remediation cost)
* Release velocity improvement (each week faster = competitive advantage × market opportunity)
* QA headcount avoided as product scales
***
## Implementation Timeline
Typical enterprise onboarding:
| Week | Milestone |
| ------- | --------------------------------------------------------------------- |
| 1 | SSO configuration, first workspace created, pilot team onboarded |
| 2 | First test suite migrated or generated; CI/CD integration complete |
| 3 | First Test Plan running in nightly CI; Slack alerts configured |
| 4 | Full regression suite running in CI; analytics baseline established |
| Month 2 | Mobile testing added; MCP server integrated with engineering AI tools |
| Month 3 | Full ROI measurement; rollout to remaining product teams |
***
{% hint style="success" %}
**Decision-maker reading path:**
1. [Platform Architecture](/getting-started/architecture-overview) — technical architecture overview
2. [MCP Server Overview](/mcp-server/overview) — AI agent integration
3. [Administration Overview](/administration/administration) — enterprise controls
4. [Integrations Overview](/integrations/integrations) — your existing toolchain
{% endhint %}
***
{% hint style="info" %}
**Ready to evaluate ContextQA for your organization?** [**Book an Executive Briefing →**](https://contextqa.com/book-a-demo/) — A 30-minute overview covering ROI, architecture, security, and implementation timeline tailored to your engineering org size and stack.
*"ContextQA reduced our QA maintenance overhead by 70% in the first quarter and let us ship 3× faster without adding headcount." — VP Engineering, Series B SaaS company*
{% endhint %}
# Business Use Cases Overview
Map ContextQA capabilities to business outcomes, implementation patterns, evidence, and measurable QA success criteria.
## Quick answer
Map ContextQA capabilities to business outcomes, implementation patterns, evidence, and measurable QA success criteria. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA leaders, product owners, engineering managers, solution architects, and evaluators who want to connect ContextQA features to a concrete testing problem and business outcome.
{% endhint %}
ContextQA supports web, mobile, API, database, and Salesforce testing in one workflow. The most useful way to evaluate the platform is not feature by feature, but against a release risk: slow regression, incomplete requirements coverage, brittle authentication, missing execution evidence, or a business process that spans several systems.

## Choose the use case that matches your goal
| Business goal | Recommended pattern | ContextQA capabilities | Outcome to measure |
| --------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------- |
| Turn product requirements into executable coverage | [Requirements to release](/business-use-cases/requirements-to-release) | Document, image, video, Jira, Figma, spreadsheet, and natural-language inputs; clarification; approval; traceability | Time from approved requirement to reviewed automated tests; acceptance criteria covered |
| Automate a workflow that crosses login, MFA, a browser extension, files, or third-party pages | [Complex web and authentication](/business-use-cases/complex-web-and-authentication) | Reusable prerequisites, variables, email or TOTP handling, file operations, UI/API/database steps, self-healing | Manual steps removed; authenticated flow stability; maintenance effort per release |
| Decide what to run before a release and explain every failure | [Regression risk and evidence](/business-use-cases/regression-risk-and-evidence) | Suites, plans, scheduling, parallel and cross-browser execution, RBT, impacted tests, screenshots, video, trace, console, and network evidence | Critical-flow coverage; feedback time; time to triage a failed run |
| Add non-functional release gates | [Specialized quality gates](/business-use-cases/specialized-quality-gates) | Performance/load, accessibility guidance, visual evidence, DAST, compatibility matrices, and code export | Service objectives met; findings owned; browser/device risks covered |
| Validate an application that performs document extraction or identity checks | [Document, OCR, and KYC validation](/business-use-cases/document-mobile-and-ocr) | Web/mobile automation, file and camera inputs, API assertions, data-driven negative cases, visual evidence | Accuracy by document class; rejection behavior; device and input coverage |
| Protect Salesforce revenue and service processes | [Salesforce and enterprise workflows](/business-use-cases/salesforce-and-enterprise-workflows) | Lightning UI automation, reusable sessions, AI verification, API tests, test data, suites, self-healing | Coverage of lead-to-revenue and service flows; release confidence across sandboxes |
| Connect QA to engineering and product delivery | [Connected delivery workflows](/business-use-cases/connected-delivery-workflows) | Jira and ALM links, CI/CD execution, Slack notifications, MCP tools, defect creation, report sharing | Requirements-to-test traceability; build-gate adoption; time from failure to owner |
## A practical evaluation model
Use the same five questions for any proof of concept:
1. **Risk:** Which customer or employee journey would cause material harm if it failed?
2. **Context:** What requirements, code, designs, data, and prior tests help describe that journey?
3. **Execution:** Which browsers, devices, environments, identities, and connected systems are required?
4. **Evidence:** What must be captured so another person can reproduce and triage a failure?
5. **Measure:** What baseline will you compare before and after automation?
Good success measures include authoring lead time, percentage of acceptance criteria linked to tests, regression feedback time, failure-triage time, flaky-run rate, and maintenance touches after UI changes. Establish the baseline with your own applications and release process rather than relying on a generic ROI assumption.
## Capability guardrails
* ContextQA automates and validates an application's OCR, KYC, payment, messaging, or voice workflow; it does not replace those business services.
* Email OTP, authenticator codes, browser extensions, private grids, database access, and third-party systems require environment-specific configuration. Validate these dependencies during a proof of concept.
* Keep credentials and tokens in workspace variables or an approved secrets provider. Do not put production secrets in test names, descriptions, steps, screenshots, or shared reports.
* Use approval gates for AI-generated tests when requirements are regulated, safety-sensitive, or still being refined.
{% hint style="success" %}
Start with one high-value end-to-end journey, one meaningful negative case, and one release gate. Once the team trusts the evidence, expand the same pattern into a reusable regression suite.
{% endhint %}
## Evaluate your highest-risk journey
Bring one release-critical workflow and the systems it crosses. A personalized demo can map that journey to the relevant ContextQA authoring, execution, evidence, and integration capabilities without relying on a generic feature tour.
[**Book a Demo →**](https://contextqa.com/book-a-demo/)
# Requirements to Release
Turn requirements, tickets, spreadsheets, designs, videos, and natural-language workflows into reviewed, traceable ContextQA tests.
## Quick answer
Turn requirements, tickets, spreadsheets, designs, videos, and natural-language workflows into reviewed, traceable ContextQA tests. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** Product intent lives in tickets, documents, spreadsheets, designs, and demo recordings. QA must translate it into test coverage quickly without losing traceability or skipping negative scenarios.
{% endhint %}
ContextQA can use several forms of source material to create a test baseline. The workflow is most effective when the source remains linked to the generated cases, the AI can ask clarifying questions, and a human approves the result before it becomes a release gate.

## Interactive demo: requirements to generated tests
Use this three-screen tour to see the review path from a source requirement to AI-assisted test generation. It highlights the requirements library, connected Jira context, and generation choices without requiring access to a live workspace.
{% embed url="" %}
### What to notice
* Source material remains visible as the reason the coverage exists.
* Jira configuration connects delivery context to the requirement workflow.
* Generation options let the reviewer shape coverage before accepting tests into a suite.
## Supported starting points
| Source | Typical business use | Review focus |
| --------------------------------------------- | --------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| Plain-English description | A known user journey or a newly discovered regression | URLs, setup state, user role, and explicit expected results |
| PRD, BRD, FRD, PDF, DOCX, TXT, or spreadsheet | Formal requirements and legacy manual test libraries | Requirement boundaries, field rules, omitted error states, and duplicated cases |
| Jira or another connected work item | Sprint stories, acceptance criteria, and bug reproduction | Ticket scope, linked work, priority, and traceability |
| Image, wireframe, or Figma design | UI behavior that is designed before implementation | Intended navigation, state changes, accessibility, and responsive behavior |
| Video walkthrough | A complex workflow best demonstrated by a subject-matter expert | Hidden prerequisites, pauses, data dependencies, and implied assertions |
| OpenAPI or API definition | Contract and integration coverage | Authentication, status codes, schema, boundary values, and chaining |
## Recommended workflow
### 1. Define the release question
Write the business outcome before uploading the source. For example: “A returning customer can renew a subscription using a saved payment method, and a declined payment leaves the original subscription unchanged.” This gives the generated tests a clear end state and includes a meaningful failure case.
### 2. Add context
Upload the primary requirement and any useful visual context. Select the target platform—web, mobile, or API—and choose the test types you need: positive, negative, edge, field validation, boundary, functional, or end-to-end.
For large legacy libraries, import a representative spreadsheet first. Verify the column mapping, parameterization, tags, and expected results before processing the rest of the library.
### 3. Resolve ambiguity
Answer AI clarification questions with concrete rules. Confirm user roles, environment, starting state, acceptable values, integrations, cleanup behavior, and what should happen when a dependency fails. If the answer is not yet known, record the gap with the product owner rather than allowing the test to invent policy.
### 4. Generate and review
Use **Required Approval** when a QA owner must review generated coverage. Check that each test has:
* one clear business purpose;
* the correct prerequisite and starting URL;
* explicit assertions, not only navigation steps;
* safe parameters instead of embedded credentials or personal data;
* tags or links that preserve feature, ticket, and release traceability;
* negative and edge cases that reflect the real cost of failure.
### 5. Organize and execute
Place approved cases in a feature suite and a test plan. Run a focused smoke set first, then the broader regression plan. Use the first execution to identify missing data, unstable environments, or requirements that cannot yet be verified.
### 6. Keep the source and coverage current
When requirements or code change, review linked tests and impacted areas. AI Insights can crawl an authorized application on a schedule to maintain application context and reveal new pages or flows that may need coverage.
See [AI Insights](/ai-features/ai-insights) for the current setup screen, scheduling fields, and journey-report workflow.
## Example: subscription renewal
**Inputs:** a Jira story, checkout wireframes, payment API specification, and a short product walkthrough.
**Generated coverage to expect:**
* successful renewal with a saved payment method;
* declined card and expired card behavior;
* displayed price, taxes, term, and confirmation details;
* API response and persisted subscription state;
* duplicate-submit protection;
* email confirmation, when the test environment exposes a safe way to verify it.
**Business value:** Product, QA, and engineering share the same release contract. Reviewers can see which acceptance criteria are automated, which gaps remain, and which evidence supports the release decision.
## Success measures
* Lead time from requirement approval to reviewed automated cases
* Acceptance criteria with at least one linked test
* Generated cases accepted, edited, or rejected during review
* Escaped defects caused by a missing requirement or missing negative case
* Reuse of imported test data, prerequisites, and steps across later features
## Related documentation
* [Creating test cases](/web-testing/creating-test-cases)
* [AI test generation](/ai-features/ai-test-generation)
* [Requirements management](/web-testing/requirements-management)
* [Generate tests from requirements tutorial](/ai-features/generate-tests-from-requirements-tutorial)
# Complex Web and Authentication
Automate multi-system web journeys involving MFA, email, browser extensions, file handling, APIs, and databases.
## Quick answer
Automate multi-system web journeys involving MFA, email, browser extensions, file handling, APIs, and databases. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** A critical user journey rarely stays on one page. It may cross a web application, identity provider, inbox, browser extension, file exchange, API, and database before the business outcome is complete.
{% endhint %}
Model the journey as one business transaction, but keep setup concerns reusable. ContextQA test cases can combine natural-language UI steps with prerequisites, variables, API calls, database checks, and evidence from the same run.

## Pattern: separate reusable setup from business verification
1. Create a prerequisite for the common authenticated session.
2. Store usernames, passwords, tokens, mailbox identifiers, and environment URLs as parameters or secrets.
3. Capture runtime values—record IDs, confirmation numbers, or links—as variables.
4. Keep the main test focused on the customer or employee outcome.
5. End with assertions that prove both the visible UI result and, where required, the downstream system state.
This pattern prevents every scenario from duplicating login logic and makes authentication changes easier to maintain.
## MFA and one-time-code flows
Use an environment-approved mechanism for retrieving a test-only code:
* **TOTP/authenticator:** generate a current code from a protected test secret.
* **Email OTP or magic link:** retrieve the message through an approved mailbox or mail-testing API, parse the code or link, and continue the browser flow.
* **Identity provider redirect:** allow the prerequisite to complete the redirect and hand the authenticated session to the main case.
Never log the seed, password, access token, or full message body. Mask sensitive values in reports, and use non-production identities with controlled access and reset procedures.
## Testing a customer browser extension
Testing an application-under-test extension is different from using the ContextQA recorder extension. For a customer extension:
1. Provide the approved extension build and manifest for the test environment.
2. Configure a compatible managed browser session with the extension installed.
3. Launch the web application and extension in the same session.
4. Exercise the cross-surface workflow—for example, capture data on a website, open the extension panel, submit it, and verify the result in the web application.
5. Record console and network evidence from the relevant surfaces.
Extension installation, browser policies, incognito behavior, permissions, and update strategy vary by deployment. Validate them during the proof of concept before promising broad browser coverage.
## File and document flows
ContextQA web tests can cover file selection, drag-and-drop upload, download initiation, and visible processing results. Combine UI steps with assertions such as:
* correct file name, type, size, and processing status;
* expected validation message for an unsupported or damaged file;
* downloaded file exists and has the expected metadata or content;
* API or database record references the uploaded artifact;
* no sensitive file content appears in logs or shared screenshots.
Use synthetic files that exercise size, encoding, language, corruption, and boundary conditions without exposing customer data.
## UI, API, and database in one business flow
A mixed-channel test is useful when the outcome cannot be proved from the UI alone. A payment example can:
1. Create a cart through an API.
2. Complete checkout through the web UI.
3. Capture the order identifier.
4. Query an approved read-only database connection or verification API.
5. Verify the order state and displayed confirmation agree.
Keep database access read-only whenever possible, isolate test data, and put cleanup in a controlled prerequisite or teardown process.
## Interactive demo: connect API and UI automation
Follow a focused example of API setup and browser validation in one ContextQA test. The workflow demonstrates how backend speed and frontend evidence can support the same user outcome instead of becoming disconnected suites.
{% embed url="" %}
### What to notice
* An API step establishes or retrieves test state before the browser interaction begins.
* Extracted values can cross the API and UI boundary without manual copying.
* One execution result preserves the sequence, validations, and evidence across both channels.
## Self-healing and visual checks
Self-healing helps a test locate an intended control after non-breaking DOM or layout changes. It does not change the business assertion. Review healed steps after significant releases so the team can confirm the test still interacts with the intended element.
Add visual, accessibility, responsive-layout, or content assertions when the experience itself is part of the requirement. Treat a visual difference as evidence to review, not automatically as a product defect.
## Success measures
* Critical journeys automated end to end, including authentication and connected systems
* Authentication setup reused across cases
* Secrets exposed in steps or reports (target: none)
* Failures with enough evidence to assign an owner without rerunning
* Maintenance edits caused by login, DOM, or dependency changes
## Related documentation
* [Step groups and reusable prerequisites](/web-testing/step-groups-tutorial)
* [Environment data management](/web-testing/environment-data-management)
* [Database steps](/web-testing/database-steps)
* [API chaining](/api-testing/api-chaining)
* [Execution evidence](/execution/video-and-screenshots)
# Regression Risk and Evidence
Build a risk-based regression program with targeted execution, self-healing, root cause analysis, and auditable run evidence.
## Quick answer
Build a risk-based regression program with targeted execution, self-healing, root cause analysis, and auditable run evidence. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** Full regression is slow, while a small smoke suite can miss high-impact failures. Release owners need a defensible way to choose tests and rapidly explain failures.
{% endhint %}
ContextQA combines business priority, usage context, suites, test plans, impacted-test analysis, and execution history. The goal is not to run fewer tests by default; it is to run the right scope for each decision and retain evidence for the result.
## Build a regression portfolio
Organize cases by purpose rather than maintaining one undifferentiated list:
| Portfolio | When to run | Example content |
| ------------------- | ------------------------------------------------------ | ------------------------------------------------------------------------------- |
| Smoke | Every deployment or environment check | Login, primary navigation, one critical transaction |
| Changed-area | Pull request, feature branch, or targeted verification | Tests linked to changed requirements, services, pages, or dependencies |
| Critical regression | Release candidate | High-priority and high-usage business journeys, including negative cases |
| Full regression | Scheduled or milestone run | Supported browsers, devices, integrations, and longer-tail workflows |
| Revisit/quarantine | After triage | Flaky, data-blocked, or environment-blocked cases with an owner and review date |
Use test suites to express feature ownership and test plans to define execution: environment, browser, device, schedule, parallelism, notifications, and release-gate behavior.
## Prioritize by risk
The RBT view plots usage frequency against business priority. Start with high-frequency, high-priority areas, then add recent code and requirement impact, defect history, and integration criticality.
Do not interpret the heatmap as a substitute for judgment. A rarely used workflow may still be legally, financially, or operationally critical. Document overrides and keep the priority metadata current.
## Run at the right point in delivery
* Trigger changed-area or smoke plans from CI/CD.
* Run broader plans on a schedule or before a release decision.
* Use parallel execution where the environment and test data can safely support concurrency.
* Add browsers, viewports, and devices according to supported-user data, not an arbitrary matrix.
* Send a concise result summary to the delivery channel and link to the detailed run.
## Triage with evidence, not guesswork

Review a failed run in this order:
1. **Failed step and assertion:** What was expected, and what actually occurred?
2. **Screenshot and video:** Was the application in the expected state? Did a modal, redirect, or loading condition intervene?
3. **Console and network:** Did a client error, failed request, timeout, or service response explain the visible failure?
4. **Trace:** Can the interaction and timing be replayed in detail?
5. **History:** Is the failure new, recurring, environment-specific, or flaky?
6. **Self-heal record:** Did the test use a recovered element, and was it the intended control?
Classify the result as a product defect, test defect, data issue, environment issue, dependency failure, or known flake. Root-cause summaries accelerate triage, but the attached evidence remains the audit trail.
## Release decision example
A team shipping a revised checkout can run:
* tests linked to the checkout requirements and code changes;
* high-priority, high-usage purchase and refund flows;
* payment API and persisted-order checks;
* supported browser and responsive viewport combinations;
* one declined-payment and one dependency-failure scenario.
The release owner receives the plan status, failing cases, root-cause context, and evidence links. Any excluded case should have an explicit reason and owner.
## Success measures
* Regression feedback time by plan type
* Critical business flows passing before release
* Failures triaged without rerun
* Product defects versus test, data, and environment failures
* Flaky tests and recurring failure clusters
* Self-healed steps reviewed and accepted
* Release incidents that had no corresponding pre-release test
## Related documentation
* [Build and schedule a regression suite](/execution/regression-suite-tutorial)
* [Analytics Dashboard](/reporting/analytics-dashboard)
* [Failure analysis](/reporting/failure-analysis)
* [Parallel execution](/execution/parallel-execution)
* [Video and screenshots](/execution/video-and-screenshots)
# Specialized Quality Gates
Add performance, accessibility, visual, security, compatibility, and export checks to a functional ContextQA release workflow.
## Quick answer
Add performance, accessibility, visual, security, compatibility, and export checks to a functional ContextQA release workflow. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** A functionally correct release can still be too slow, inaccessible, visually broken, insecure, or incompatible with the environments customers use.
{% endhint %}
Start with a stable functional journey, then add the quality gate that represents a real service objective or customer risk. Availability and execution infrastructure can vary by plan, deployment, and integration; confirm the required capability in the target workspace before making it release-blocking.
## Performance and load
Use a representative test flow or API target as the scenario for a controlled performance run. The MCP `execute_performance_test` capability accepts a virtual-user count, duration, and ramp-up and returns a live result reference with response-time percentiles, error rate, and throughput.
Define the pass criteria before running:
* target environment and approved load window;
* representative data and authentication behavior;
* concurrency and ramp profile;
* response-time percentile objectives;
* maximum error rate;
* backend or third-party rate limits;
* abort criteria and an owner monitoring the environment.
Do not aim production-scale traffic at an environment without authorization. A load result is meaningful only when environment capacity, data, caches, and dependent services resemble the decision being made.
## Accessibility
Combine explicit keyboard, focus, label, role, contrast, error-message, and screen-reader expectations with an accessibility-oriented custom agent where appropriate. Automated observations help find repeatable issues, but they do not replace assistive-technology testing or expert review for high-impact journeys.
Use the applicable organizational standard—such as a specified WCAG conformance target—and preserve the violated expectation, page state, element context, and evidence with each finding.
## Visual and responsive behavior
Capture consistent screenshots at named checkpoints across the supported browser and viewport matrix. Compare the current result with an approved baseline when a comparison workflow is enabled, and review differences caused by content, fonts, animation, test data, or rendering before filing a defect.
Useful visual gates include:
* clipped or overlapping content;
* missing controls, icons, or images;
* responsive navigation and breakpoint behavior;
* Salesforce or other dynamic-layout regressions;
* generated document previews;
* critical brand, legal, or localization content.
Keep data, locale, viewport, browser version, and animation state stable so the comparison measures the product rather than test noise.
## Security scanning
The MCP `execute_security_dast_scan` capability can launch a configured dynamic scan against flows exercised by a test case. Use a standard profile in an approved CI or test environment and reserve more aggressive scans for a dedicated window.
Treat scanner results as findings to validate. Record the affected flow, evidence, severity, owner, and remediation status. Do not scan an application or third-party system without explicit authorization.
## Browser, device, and environment compatibility
Build the matrix from supported-user and risk data. Run the same suite across required browsers, responsive viewports, mobile devices, and environment profiles, while isolating data that cannot safely execute in parallel.
For every difference, determine whether it is a product issue, browser or device limitation, provider dependency, environment configuration, or unstable test data.
## Export and portability
Where teams need code ownership or a transition path, export supported cases to an approved automation framework and store the generated output with its dependencies and execution instructions. Validate the exported test in the target runner; platform evidence, self-healing, variables, and integrations may not map one-for-one to standalone code.
## Success measures
* Releases evaluated against explicit functional and non-functional objectives
* Performance results tied to an authorized, representative environment
* Accessibility defects found before release and verified after remediation
* Visual differences reviewed with stable baselines and low noise
* Security findings validated and owned
* Supported browser, device, and viewport coverage based on customer usage
* Exported tests that run successfully in the intended target framework
## Related documentation
* [Advanced MCP testing tools](/mcp-server/tool-reference/bug-defect-and-advanced)
* [Custom agents](/ai-features/custom-agents)
* [Cross-browser execution](/execution/cross-browser-testing)
* [Execution environments](/execution/environments)
* [Exporting reports and code](/reporting/exporting-reports)
# Document, OCR, and KYC Validation
Validate document extraction and identity-verification applications with web, mobile, API, and data-driven ContextQA tests.
## Quick answer
Validate document extraction and identity-verification applications with web, mobile, API, and data-driven ContextQA tests. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="warning" %}
ContextQA automates the system being tested. It does not perform OCR, identity verification, liveness detection, or regulatory approval itself. The available checks depend on the application, test environment, devices, and provider APIs you connect.
{% endhint %}
Document and identity workflows combine difficult inputs: camera capture, file upload, image quality, extraction, personal data, third-party decisions, and manual review. A complete test strategy validates both the accepted path and the reasoned rejection of unsafe or unusable inputs.
## Reference workflow
1. Start a web or mobile identity-verification session with synthetic test data.
2. Upload or capture the permitted document and, where required, a selfie.
3. Verify the user receives clear progress and consent information.
4. Wait for the application or connected service to finish processing.
5. Verify extracted fields, confidence or review state, and the final decision through the UI or an approved API.
6. Confirm downstream records contain the expected synthetic identifiers and status.
7. Retain only the evidence allowed by the data-handling policy, then clean up the test record.
## Positive coverage
Create representative synthetic samples for every supported document family, issuing region, language, layout, and capture channel. Verify:
* document type is recognized correctly;
* name, date, identifier, and address fields match expected synthetic values;
* normalization rules for dates, punctuation, case, and whitespace;
* front/back association where two images are required;
* successful selfie or liveness response when a test provider supports it;
* UI, API, and persisted status agree;
* the user sees the correct next step after approval or manual review.
## Negative and edge coverage
Use approved synthetic fixtures for:
* blurred, dark, overexposed, cropped, rotated, or low-resolution images;
* glare, occlusion, missing corners, or unreadable fields;
* unsupported type, file extension, file size, or page count;
* expired or incomplete documents;
* mismatched front and back, or mismatched document and selfie;
* duplicate submission and replay behavior;
* corrupted files, provider timeouts, and delayed callbacks;
* altered or suspicious samples supplied by the provider's test program.
The assertion should check more than “failed.” Verify the reason category, safe user message, retry path, manual-review behavior, and absence of sensitive technical details.
## Data-driven test design
Keep the workflow stable and move sample variation into a test data profile:
| Parameter | Example purpose |
| ------------------------------ | ------------------------------------------- |
| Fixture path or provider token | Select the synthetic document or image |
| Document family and region | Route the expected extraction rules |
| Expected fields | Compare normalized extracted values |
| Expected decision | Approved, rejected, retry, or manual review |
| Expected reason code | Verify precise negative behavior |
| Device, OS, and orientation | Exercise supported capture combinations |
Avoid real identity documents and biometrics in general-purpose test environments. Restrict access to fixtures, secrets, screenshots, downloads, and execution evidence according to the organization's privacy and retention requirements.
## Mobile-specific considerations
* Camera permission allowed, denied, and revoked
* Front/rear camera switching and orientation changes
* App backgrounding or network interruption during upload
* Device viewport, safe-area, and accessibility behavior
* Retry after an interrupted provider callback
* Consistent status when the user resumes on another channel
Use device coverage based on the product's supported-user population. A provider sandbox may not reproduce every production model or fraud signal, so document what is simulated and what still requires controlled manual validation.
## Business value and success measures
Automating these flows makes provider changes, mobile releases, and document-rule updates safer while reducing repetitive manual fixture checks. Measure:
* extraction accuracy by document class and field;
* false accept, false reject, retry, and manual-review outcomes in the approved test set;
* supported device and capture-mode coverage;
* failures with a specific, user-safe reason;
* time from provider or application change to regression feedback;
* privacy exceptions or unintended sensitive data in evidence (target: none).
## Related documentation
* [Mobile testing overview](/mobile-testing/mobile-testing)
* [Uploading mobile apps](/mobile-testing/uploading-apps)
* [Test data management](/web-testing/test-data-management)
* [Validating API responses](/api-testing/validating-responses)
* [Execution evidence](/execution/video-and-screenshots)
# Salesforce and Enterprise Workflows
Protect Salesforce lead, opportunity, CPQ, revenue, and service workflows with reusable sessions, UI/API validation, and evidence.
## Quick answer
Protect Salesforce lead, opportunity, CPQ, revenue, and service workflows with reusable sessions, UI/API validation, and evidence. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** Salesforce processes cross dynamic Lightning pages, custom objects, permissions, APIs, approvals, documents, and downstream systems. A UI-only happy path does not provide enough release confidence.
{% endhint %}
Build Salesforce coverage around business lifecycles rather than individual screens. ContextQA can reuse an authenticated Salesforce session, execute natural-language Lightning steps, combine UI and API verification, drive record variations from test data, and retain evidence for each run.

## High-value process maps
| Process | Representative coverage | Business risk addressed |
| ----------------------------- | ------------------------------------------------------------------------------------ | ------------------------------------------------------- |
| Lead to opportunity | Lead creation, qualification, conversion, owner assignment, stage and history checks | Lost pipeline, routing errors, inaccurate forecasting |
| Opportunity to quote | Products, price books, discounts, approvals, quote generation, synchronization | Incorrect pricing, margin leakage, approval bypass |
| Quote to contract or order | Acceptance, document generation, downstream handoff, status reconciliation | Revenue delay, mismatched commercial records |
| Service and case management | Case intake, priority, assignment, status, escalation, communication | SLA breach and inconsistent customer service |
| Account and contact lifecycle | Create, update, duplicate handling, permissions, relationship integrity | Bad customer data and access-control errors |
| Agent or guided workflow | Prompt/action sequence, tool or API result, audit history, fallback | Incorrect autonomous action or missing human escalation |
## Reuse the authenticated session
Create a Salesforce session-login test and select it as a prerequisite for dependent cases. Keep credentials and authenticator material in protected parameters. This shortens authoring, centralizes authentication maintenance, and allows the business case to begin from a known logged-in state.
## Verify outcomes, not clicks
For a stage-change test, assert the new stage, its history entry, relevant calculated fields, and any required downstream action. Use AI verification for dynamic page content where appropriate, but make the expected business state explicit.
Add API verification when Salesforce UI state alone is insufficient—for example, confirming an OAuth-backed update or downstream CPQ object. Use read-only queries or dedicated test records where possible.
## Interactive demo: connect Salesforce API and UI validation
Follow one Salesforce business case across two layers: use an API step to establish or retrieve state, then validate the user-visible outcome in the Salesforce interface.
{% embed url="" %}
### What to notice
* API setup shortens the path to the business state without removing the UI validation that users depend on.
* Extracted identifiers and response values can be reused by later Salesforce steps without manual copying.
* One result preserves the API request, Salesforce interaction, validations, and evidence as a continuous journey.
## Design stable enterprise tests
* Reference fields by labels, roles, and business context rather than generated DOM identifiers.
* Parameterize record types, users, regions, currencies, products, and approval thresholds.
* Use unique synthetic names or run identifiers to prevent collisions in parallel execution.
* Keep cleanup explicit so repeat runs do not accumulate records or alter shared baselines.
* Separate environment configuration for each sandbox.
* Review self-healed steps after Salesforce seasonal updates or page-layout changes.
## Example: discount approval
1. Reuse the authenticated sales-user prerequisite.
2. Create or open an opportunity with parameterized products.
3. Generate a quote and apply a discount at the approval boundary.
4. Verify the quote cannot bypass the required approval.
5. Complete the manager approval with a permitted test identity.
6. Verify quote status, totals, history, and the associated opportunity.
7. Confirm any downstream API or generated document reflects the approved amount.
Add cases immediately below and above the threshold, a rejected approval, an unauthorized user, a multi-currency variation, and a dependency failure.
## Success measures
* Revenue and service lifecycle steps covered across UI and API
* Reuse of session and record-setup prerequisites
* Sandbox-specific failures and test-data collisions
* Salesforce release changes absorbed without unintended test behavior
* Time to identify whether a failure belongs to configuration, permissions, data, integration, or product logic
* Critical record changes supported by execution evidence and history
## Related documentation
* [Salesforce testing overview](/salesforce-testing/salesforce-testing)
* [Salesforce test generation and execution](/salesforce-testing/test-generation-and-execution)
* [Test data management](/web-testing/test-data-management)
* [API testing overview](/api-testing/api-testing)
* [Self-healing](/web-testing/self-healing)
# Connected Delivery Workflows
Connect ContextQA requirements, tests, CI/CD execution, notifications, defects, reports, and AI agents across the delivery lifecycle.
## Quick answer
Connect ContextQA requirements, tests, CI/CD execution, notifications, defects, reports, and AI agents across the delivery lifecycle. Use this page to connect the business problem to a supported ContextQA workflow, its expected value, and its operating considerations.
## What this page covers
{% hint style="info" %}
**Business problem:** Test automation creates less value when requirements, build gates, failures, and owners remain disconnected across product and engineering tools.
{% endhint %}
ContextQA can connect authoring and execution to issue trackers, source workflows, CI/CD, notifications, and MCP-compatible agents. Choose integrations by the decision they support, then keep the detailed execution evidence in ContextQA as the source of truth.
## Reference flow
1. A product story or requirement becomes the traceable source for generated test cases.
2. QA reviews and approves the positive, negative, boundary, and end-to-end coverage.
3. The cases are organized into suites and a release plan.
4. CI/CD triggers the appropriate plan for a pull request, deployment, or release candidate.
5. ContextQA executes and returns status to the pipeline.
6. A concise result is sent to the team channel; the full report retains step, screenshot, video, console, network, and trace evidence.
7. A confirmed product defect becomes a linked work item with the relevant reproduction context.
8. Trend, flakiness, root-cause, and coverage views guide the next release decision.
## Integration patterns
| Need | Pattern | Design note |
| ------------------------- | ---------------------------------------------------------------------- | ------------------------------------------------------------------------ |
| Requirements traceability | Generate from Jira or another supported source and preserve links/tags | Keep one owner for ambiguous acceptance criteria |
| Pull-request feedback | Trigger a smoke or impacted-test plan from CI/CD | Set a timeout and an explicit policy for infrastructure failures |
| Release regression | Schedule or manually start a broader plan | Freeze environment and test-data assumptions for the run |
| Team awareness | Send a summary to Slack or another approved channel | Include status, scope, failure count, owner, and report link—not secrets |
| Defect handoff | Create a ticket after evidence review | Avoid filing duplicate tickets for test-data or environment failures |
| Agent-assisted QA | Use MCP tools to create, execute, and analyze tests | Restrict credentials and permissions to the minimum required scope |
## Build-gate policy
Define how the pipeline handles each result:
* **Passed:** continue when the required scope completed and all blocking assertions passed.
* **Product failure:** block or require an explicit release exception.
* **Test failure or flake:** quarantine only with an owner, evidence, and review date.
* **Environment or infrastructure failure:** do not label the product as defective; retry or escalate according to the service policy.
* **Timed out or incomplete:** treat as unknown, not passed.
Keep smoke gates fast and deterministic. Run deeper, longer, or integration-heavy coverage at the appropriate release stage.
## Cross-channel and agentic workflows
Applications may span chat, email, Slack, WhatsApp, voice, or third-party agents. Coverage is integration-dependent. Define a proof-of-concept contract for each channel: input, identity, expected action, observable outcome, timeout, fallback, and human-escalation behavior.
For an agent workflow, verify both the user-facing response and the action trail: tools invoked, API or record result, authorization boundary, refusal behavior, and audit history. Do not assume that a passing conversational response proves the downstream action occurred.
## Success measures
* Stories or acceptance criteria linked to approved automated tests
* Deployments evaluated by an appropriate automated plan
* Failed gates assigned to the correct owner from available evidence
* Time from confirmed failure to a reproducible defect ticket
* Duplicate or low-quality automated defects
* Test and result access granted with least privilege
* Agent actions with a verifiable downstream outcome and audit trail
## Related documentation
* [Integrations overview](/integrations/integrations)
* [GitHub Actions](/integrations/github-actions)
* [Jira integration](/integrations/jira)
* [Slack integration](/integrations/slack)
* [MCP Server overview](/mcp-server/overview)
* [Reporting overview](/reporting/reporting)
# Introduction to ContextQA
An overview of ContextQA, an AI-powered test automation platform that lets teams create, run, and maintain web, mobile, and API tests using natural language.
## Quick answer
An overview of ContextQA, an AI-powered test automation platform that lets teams create, run, and maintain web, mobile, and API tests using natural language. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Engineers, QA managers, and non-technical stakeholders who want to understand what ContextQA is, what problems it solves, and how it fits into a modern engineering team.
{% endhint %}
ContextQA is an AI-powered test automation platform designed to make software testing faster, more reliable, and accessible to every member of an engineering team. Instead of writing brittle Selenium scripts or complex Playwright code, you describe what to test in plain English and ContextQA's AI engine handles the rest — generating steps, executing them against real browsers, capturing evidence, and self-healing tests when the UI changes.
The platform is built around a multi-stage AI pipeline. Each agent handles a distinct concern: navigating the application, discovering interactive elements, executing steps, capturing screenshots, monitoring network calls, verifying assertions, and repairing broken locators. Together they produce a fully autonomous testing loop that requires minimal maintenance even as your application evolves.
## Why ContextQA
Modern software teams face two compounding pressures: applications change faster than tests can be updated, and test suites grow complex enough to require dedicated automation engineers. ContextQA addresses both:
* **Natural language test creation** — Write test instructions in plain English ("Login as admin, navigate to the reports page, verify a chart is visible"). No XPath, no CSS selectors, no code required.
* **Self-healing AI** — When a button is renamed or a class changes, the AI automatically locates the correct element and repairs the step instead of throwing a failure.
* **End-to-end evidence** — Every step captures a screenshot, the network HAR log, and browser console entries. A full video recording and Playwright trace are produced per execution.
* **Universal test targets** — Web, mobile (iOS and Android), REST APIs, Salesforce, and SAP are all supported from a single workspace.
* **AI agent integration via MCP** — ContextQA exposes 67 tools through a Model Context Protocol (MCP) server, letting AI coding assistants such as Claude, Cursor, and GPT create and run tests on your behalf.
* **Broad test generation sources** — Generate test cases from Jira tickets, Figma designs, Excel spreadsheets, Swagger/OpenAPI specs, screen recordings, and n8n workflow definitions.
* **Deep integrations** — Connect to Jira for defect tracking, Slack for notifications, and GitHub Actions, Jenkins, or Azure DevOps for CI/CD pipeline execution.
## Platform Highlights
| Capability | Details |
| ---------------------------- | ---------------------------------------------------------- |
| AI execution pipeline | Fully automated, end-to-end |
| Specialized AI agents | 13+ agents |
| Supported test targets | Web, Mobile (iOS/Android), REST API, Salesforce, SAP |
| MCP tools exposed | 67 tools |
| Evidence per step | Screenshot, network log, console log |
| Evidence per execution | Video recording, Playwright trace, root cause analysis |
| Self-healing | Automatic repair with high confidence |
| Test generation sources | Jira, Figma, Excel, Swagger, video, n8n, requirements text |
| CI/CD integrations | GitHub Actions, Jenkins, Azure DevOps, CircleCI |
| Notification integrations | Slack, email |
| Defect tracking integrations | Jira |
## Key Concepts Glossary
Understanding these terms will help you navigate the platform efficiently.
| Term | Definition |
| --------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Workspace** | An isolated project environment corresponding to one application under test. A workspace contains all test cases, suites, plans, environments, and settings for that application. You might have separate workspaces for your web app, your mobile app, and your internal API. |
| **Test Case** | The atomic unit of testing. A test case specifies a starting URL, a sequence of steps (authored in natural language or recorded), optional tags, and optional prerequisite test cases. |
| **Step** | A single instruction within a test case: "Click the Submit button", "Verify the confirmation email was displayed", "Call POST /api/login". Steps can be AI Agent steps, navigation steps, REST API calls, conditionals, loops, or verifications. |
| **Step Group** | A reusable collection of steps saved as a named library — similar to a function or subroutine. For example, `SG_Login` could contain the three steps needed to authenticate, and be inserted into dozens of test cases without duplication. |
| **Test Suite** | A logical grouping of test cases. Suites can be nested like folders. Typical examples: "Smoke Tests", "Regression Pack", "Checkout Flow". |
| **Test Plan** | An execution configuration that specifies which suites to run, which browsers or devices to target, which environment to use, whether to run in parallel or sequentially, and any recurring schedule. |
| **Environment** | A named configuration that stores a base URL and a set of key-value parameters (e.g., API keys, database hostnames). Switching environments lets the same test suite run against staging, QA, and production without modification. |
| **Test Data Profile** | A parameterized data set attached to a test case. Each row in the profile represents one complete test run with its own input values, enabling data-driven testing without duplicating test cases. |
| **Execution** | One run of a test case, suite, or plan. An execution produces a unique `result_id` and generates video, screenshots, logs, and a root cause analysis report. |
| **Self-Healing** | The AI capability that automatically detects when a UI element has changed and repairs the test step to reference the correct new element, provided the AI confidence score exceeds 90%. |
| **Knowledge Base** | A set of AI-readable instructions stored in the workspace that tell the test agent how to handle specific situations — closing cookie consent banners, bypassing CAPTCHA prompts in testing environments, handling multi-factor authentication flows. |
| **Custom Agent** | An AI persona with a custom system prompt. Custom agents allow domain-specific testing behavior, for example an agent calibrated for Salesforce object navigation or an agent that follows your company's specific accessibility standards. |
| **MCP Server** | The Model Context Protocol server that ContextQA runs, exposing platform capabilities as callable tools to external AI assistants. This allows Claude, Cursor, GPT, or any MCP-compatible client to create tests, run them, and retrieve results programmatically. |
## How the Platform Fits Together
A typical workflow on ContextQA follows this path:
1. **Create a Workspace** for your application.
2. **Configure an Environment** with the base URL and any credentials or API keys your tests need.
3. **Create Test Cases** — using AI assistance, recording, or importing from external sources.
4. **Organize into Test Suites** — group related tests so they can be run together.
5. **Build a Test Plan** — configure which suites, which browsers, and which environment.
6. **Execute** — manually for immediate feedback, or on a schedule for continuous monitoring.
7. **Review Results** — inspect screenshots, video, network logs, and AI-generated root cause analysis for any failure.
8. **Iterate** — the self-healing AI handles most minor UI changes automatically; you address genuine functional failures.
## Supported Platforms
**Web Browsers:** Chrome, Firefox, Safari, Microsoft Edge
**Mobile:** iOS (physical devices and simulators), Android (physical devices and emulators)
**API:** REST (GET, POST, PUT, PATCH, DELETE) with variable chaining between steps
**Enterprise Applications:** Salesforce (Lightning and Classic), SAP
## Frequently asked questions
Is ContextQA a no-code testing tool?
ContextQA supports a no-code workflow for creating and running tests with natural language, recording, and imports. It also provides advanced paths—API steps, custom JavaScript, CI/CD connections, Playwright export, and MCP tools—for technical teams that need extensibility.
How is ContextQA different from a traditional scripted test framework?
Traditional frameworks generally require engineers to author and maintain selector-based test code. ContextQA stores reviewable tests around user intent and lets an AI execution pipeline handle interaction, evidence capture, and routine element-location drift. Teams should still review generated coverage and investigate genuine functional failures.
What evidence does a ContextQA execution produce?
The documented result experience includes step status and screenshots, with execution-level video, browser/network artifacts, trace data, and failure-analysis information where available for the run type and deployment.
Who can create tests in ContextQA?
Testers and product stakeholders can use plain-language and import workflows, while developers and SDETs can use advanced steps, CI/CD, and MCP integrations. Actual actions depend on the user's assigned workspace permissions.
Where should a new user begin?
Use the [Quickstart](/getting-started/quickstart) for a first web test, choose a task from the [Video Walkthroughs](/getting-started/video-walkthroughs), or browse the documentation [by role](/documentation-by-role/by-role).
## Next Steps
* Follow the [Quick Start guide](/getting-started/quickstart) to run your first test in 5 minutes.
* Read [Core Concepts](/getting-started/core-concepts) for a deeper explanation of each platform building block.
* Explore [Platform Architecture](/getting-started/architecture-overview) to understand the AI pipeline in detail.
* Check the [Glossary](/reference/glossary) for definitions of key terms.
{% hint style="info" %}
**Create your first test in 5 minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see ContextQA with your application.
{% endhint %}
# Quickstart Guide
A step-by-step guide to signing in, creating a test case with AI assistance, running it, and reviewing the results in under five minutes.
## Quick answer
A step-by-step guide to signing in, creating a test case with AI assistance, running it, and reviewing the results in under five minutes. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Anyone new to ContextQA — developers, QA engineers, and product managers who want to run their first automated test without writing any code.
{% endhint %}
This guide takes you from a blank slate to a passing automated test in five minutes. You sign in to ContextQA, create a test case using the AI assistant, execute it against a live URL, and review the step-by-step results including screenshots and video. No code is required at any point.
[Watch the first-test generation walkthrough](https://drive.google.com/file/d/1QBow6jtlcI8JBbJ9mMZNLTywb_zTab1m/preview).
## Prerequisites
* A ContextQA account (sign up at [accounts.contextqa.com/onboard](https://accounts.contextqa.com/onboard))
* The URL of a web application you want to test
* A clear idea of one user flow to automate (e.g., login, search, form submission)
***
## Step 1: Sign In
Navigate to [accounts.contextqa.com/onboard](https://accounts.contextqa.com/onboard) in your browser.

Enter your **email address** and **password**, then click **Sign In**. If your organization uses single sign-on, click the SSO button and authenticate through your identity provider.
After signing in you land on the ContextQA dashboard. The left sidebar contains the main navigation icons for all platform areas.

***
## Step 2: Navigate to Test Cases
In the left sidebar, select **Test Cases**. This opens the test authoring area where all test cases, suites, and data profiles live.
If you have recently created your account you see an empty workspace. If your team has existing tests they are listed here.

***
## Step 3: Create a Test Case
Click the **+** button in the top-right area of the Test Cases panel. A menu appears with creation options.
Select **Start with AI Assistance**.
A dialog opens where you configure the AI-generated test.
***
## Step 4: Enter the URL and Task Description
Fill in two fields:
**Application URL** Enter the full URL of the page where the test should begin. For example:
```
https://yourapp.com/login
```
**Task Description** Write a plain-English description of the user flow you want to test. Be specific — name the fields, the expected outcomes, and any values to use. For example:
```
Login with username test@example.com and password secret123,
verify the dashboard loads and the welcome message is displayed
```
**Tips for writing effective task descriptions:**
* Include exact field labels or button names as they appear in the UI ("Click the Sign In button", not "Click login")
* Always include at least one verification step ("verify", "confirm", "check that")
* Mention exact test data values (email addresses, passwords, search terms)
* Keep each task focused on a single user flow — separate flows into separate test cases
Click **Generate**. The AI analyzes your description and creates a structured sequence of steps. Step generation typically takes 5–15 seconds.
***
## Step 5: Run the Test
Once the steps are generated, the test case editor opens showing the full step list. Review the steps to confirm they match your intent.
Click the **Run** (▶) button in the top toolbar to execute the test immediately.
ContextQA queues the execution and opens the live execution viewer. You see:
* **Left panel** — the list of steps with real-time pass/fail status indicators
* **Right panel** — a live screenshot of the current browser state as each step runs
* **Bottom panel** — network requests captured in real time
The test runs sequentially, step by step. A green checkmark appears as each step passes. If a step fails, a red indicator appears and the AI immediately begins root cause analysis.
Execution time depends on the number of steps and network speed of the application under test. A typical 5–10 step test completes in under 60 seconds.
***
## Step 6: View the Results
When execution completes, click **View Report** (or **View Detailed Report**) in the execution summary banner.
The results page shows:
* **Execution summary** — overall pass/fail status, duration, browser used, environment
* **Step-by-step breakdown** — each step with its pass/fail status and the screenshot captured at that exact moment
* **Video recording** — full playback of the browser session
* **Network log** — every HTTP request and response captured during the run
* **Console log** — browser console entries (errors, warnings, info messages)
* **Root cause analysis** — if any step failed, the AI explains what went wrong and suggests a fix
***
## What happens next
You have created and run your first automated test. From here you can:
* [**Create more test cases**](/web-testing/creating-test-cases) to build out your test suite
* [**Organize test cases into a Test Suite**](/web-testing/managing-test-suites) for grouped execution
* [**Create a Test Plan**](/execution/running-tests) to configure browser targets, environments, and schedules
* [**Enable self-healing**](/web-testing/self-healing) so minor UI changes don't break your tests
* [**Set up a CI/CD integration**](/integrations/integrations) to run tests automatically on every pull request
{% hint style="info" %}
**Ready to go deeper?** Try one of these hands-on tutorials:
* [Data-Driven Testing](/web-testing/data-driven-testing-tutorial) — run the same test with multiple input sets
* [Step Groups](/web-testing/step-groups-tutorial) — create reusable test building blocks
* [Your First API Test](/api-testing/api-testing-tutorial) — validate API endpoints alongside your UI tests
* [Your First Mobile Test](/mobile-testing/mobile-testing-tutorial) — test native apps on real devices
Or review [Core Concepts](/getting-started/core-concepts) to understand how all the platform pieces fit together.
{% endhint %}
## Tips and best practices
* **Start with a happy path** — automate the most critical user flow first (login, core feature, checkout). Expand to edge cases once the happy path is stable.
* **One flow per test case** — keep each test case focused on a single scenario. Short tests are easier to debug when they fail.
* **Always include verifications** — a test that only clicks through screens without asserting outcomes will pass even when the application is broken. Add at least one "verify" step per test case.
* **Use meaningful names** — name test cases after the user action and expected outcome, e.g., "Login with valid credentials — dashboard visible" rather than "Test 1".
* **Use the step editor to refine** — after AI generation, review each step. You can edit, reorder, or delete steps in the step editor before running.
## Troubleshooting
**The AI did not generate steps / generation timed out** Check that the URL is publicly accessible from ContextQA's execution servers. If your application is behind a VPN or firewall, you may need to allowlist ContextQA's IP ranges (see Administration → Network Configuration).
**The test failed on step 1 (navigation)** Confirm the URL is correct and the application is online. Try opening the URL in a private browser window to rule out authentication or cookie issues.
**Steps were generated but they don't match my application** Edit the task description to be more specific. Name the exact buttons, headings, and form fields as they appear in your application. Then click Regenerate.
**The execution is stuck in "Queued" status** Your workspace may have reached its concurrent execution limit. Wait for other running tests to finish, or contact support to increase your concurrency allocation.
## Related pages
* [Interactive Demo](/getting-started/interactive-demo) — see ContextQA in action with guided walkthroughs
* [Browse by Role](/documentation-by-role/by-role) — find the documentation path for your role
* [Core Concepts](/getting-started/core-concepts)
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Running Tests](/execution/running-tests)
* [Platform Architecture](/getting-started/architecture-overview)
***
## Execution evidence
The following recordings are from live ContextQA executions of the login and test creation flows:
{% hint style="info" %}
**Create your first test in 5 minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see ContextQA with your application.
{% endhint %}
# Video Walkthroughs
Task-focused ContextQA walkthroughs for web, mobile, API, requirements, test data, Jira, dashboards, suites, and plans.
## Quick answer
Task-focused ContextQA walkthroughs for web, mobile, API, requirements, test data, Jira, dashboards, suites, and plans. Use this page to preview the workflow and its visible results before following the linked written instructions.
## What this page covers
Use this library when you want to watch a complete workflow before following the written guide. Each recording opens in Google Drive's public preview player and is paired with the business outcome it supports and the detailed documentation to use as a reference.
The written summaries below are also the searchable companion to the recordings. Use them to choose a walkthrough, understand its outcome without playing the video, and continue into a complete step-by-step guide.
{% hint style="info" %}
The source folder contains older recordings of several workflows. To avoid conflicting instructions, this page links the corresponding recording from **Updated video** whenever one exists. Two older recordings are included because they uniquely cover the dashboard and Excel test-case import.
{% endhint %}
## Getting started and web testing
| Walkthrough | Business use case | Written guide |
| --------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------ |
| [Generate and execute your first web test](https://drive.google.com/file/d/1QBow6jtlcI8JBbJ9mMZNLTywb_zTab1m/preview) | Turn a plain-English user journey into a runnable browser test without writing automation code. | [Quickstart](/getting-started/quickstart) |
| [Reuse test-case prerequisites](https://drive.google.com/file/d/12Vvu28Pv9aUWGjXO3Lnd8J2Ma9iGTIRb/preview) | Reuse login or setup once instead of copying it into every dependent test. | [Creating test cases](/web-testing/creating-test-cases) |
| [Record and play a browser flow](https://drive.google.com/file/d/13Gab4J-oTb7XZVNxAZJNpDvXme-nE-iX/preview) | Convert an exploratory browser session into a repeatable regression test. | [Record your first test](/web-testing/recording-tutorial) |
| [Generate tests from requirements](https://drive.google.com/file/d/1JtdXOKBYGoQiGa4woSapLiVOge0vrlyS/preview) | Convert requirement files into reviewable positive, negative, boundary, validation, functional, and end-to-end coverage. | [Generate tests from requirements](/ai-features/generate-tests-from-requirements-tutorial) |
| [Generate runnable tests from Jira](https://drive.google.com/file/d/1v3KHLYP17reGp1BZDSOOxGF5MAsLuTF_/preview) | Keep ticket context and generated tests traceable to the same delivery source. | [Jira integration](/integrations/jira) |
| [Choose local or global variables](https://drive.google.com/file/d/1iX_UkzEWYG52QiNoIl7em5qnNrxV7oeW/preview) | Keep one-off values inside a test while managing shared values once for the workspace. | [Test data management](/web-testing/test-data-management) |
| [Configure environments and data profiles](https://drive.google.com/file/d/1UbcQCoDLHLrjbau3Jfb9HqGF3lnsGR-m/preview) | Run the same flow against different deployment targets and data rows without duplicating tests. | [Environment and data management](/web-testing/environment-data-management) |
| [Organize tests with suites and plans](https://drive.google.com/file/d/1sZGxrvhFYCIyAL5iKCOi6y7upmpluS-2/preview) | Group coverage by purpose, then control where, how, and when it runs. | [Test plans](/web-testing/test-plans) |
| [Import test cases from Excel](https://drive.google.com/file/d/1sP-9thppLX1NcEb5tI5471jaICkfMoqI/preview) | Migrate an existing manual test inventory and optionally organize it into a suite and plan. | [Creating test cases](/web-testing/creating-test-cases#import-test-cases-or-requirements) |
| [Understand dashboard analytics](https://drive.google.com/file/d/12ulnwgfotrp_vy0SSlmVs9DUVeX5McY_/preview) | Review execution, source, coverage, risk, and activity trends from a single operational view. | [Analytics dashboard](/reporting/analytics-dashboard) |
### What the web-testing walkthroughs cover
* **First web test:** describe a user journey, generate a runnable browser test, execute it, and review its result.
* **Prerequisites:** place shared setup or login behavior in a prerequisite so dependent tests do not repeat the same steps.
* **Record and Play:** capture a browser interaction and convert it into reusable test steps.
* **Requirements and Jira:** turn an existing delivery artifact into proposed test coverage, then review the generated cases before execution.
* **Variables, environments, suites, and plans:** separate reusable data and execution configuration from the test's business flow.
* **Excel import and analytics:** migrate existing cases and use reporting to understand execution and coverage trends.
## Mobile testing
| Walkthrough | Business use case | Written guide |
| ------------------------------------------------------------------------------------------------------------------------------ | ----------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------- |
| [Mobile testing overview](https://drive.google.com/file/d/1wAtefl0InGTTJ3Gq5qPckIBvkwCZo3uh/preview) | Understand how app builds, real devices, AI-assisted generation, and execution evidence fit together. | [Mobile testing overview](/mobile-testing/mobile-testing) |
| [Upload, configure, and run your first mobile test](https://drive.google.com/file/d/1jEH39OreAYE9eJYf3fpDFFek5wl4M-WO/preview) | Validate an Android APK or iOS IPA on a selected real device. | [Create and run mobile tests](/mobile-testing/creating-mobile-tests) |
| [Test tap, swipe, scroll, pinch, and zoom](https://drive.google.com/file/d/1-2B2YsEDjeadues_CsWehVUutsPKdpTk/preview) | Cover touch interactions that desktop-style click tests cannot represent. | [Gesture-based scenarios](/mobile-testing/creating-mobile-tests#gesture-based-mobile-scenarios) |
| [Run Android and iOS suites in a test plan](https://drive.google.com/file/d/1nS5FIKuOMw2oHlaWSan2n-J6WpYy-YYi/preview) | Execute platform-specific suites together and compare results in one plan report. | [Mobile test plans](/mobile-testing/mobile-test-plans) |
### What the mobile-testing walkthroughs cover
* **Mobile overview:** connect uploaded builds, device selection, AI-assisted test creation, and execution evidence.
* **First mobile test:** upload or select an app build, choose a compatible device, generate a test, and review its run.
* **Gestures:** represent touch-specific actions such as tap, swipe, scroll, pinch, and zoom.
* **Mobile plans:** group Android and iOS coverage into suites and run them through a repeatable plan.
## API testing
| Walkthrough | Business use case | Written guide |
| ------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------- | ----------------------------------------------------- |
| [API testing overview](https://drive.google.com/file/d/1KHQnWchIXiVLFka7a0ZGrtgYJw7Mt0hy/preview) | Validate backend behavior earlier and combine API checks with end-to-end UI coverage. | [API testing overview](/api-testing/api-testing) |
| [Create your first API test](https://drive.google.com/file/d/1OyuSh20YojL-qkQs9-5rG2yYR4YqjQ98/preview) | Configure a request, store its response, assert the status, and inspect the run history. | [Creating API tests](/api-testing/creating-api-tests) |
| [Chain API requests](https://drive.google.com/file/d/1zU67osZy0xyo7pTme0wy8720FsHx0QU1/preview) | Capture a live authentication token and pass it safely into a dependent request. | [API chaining](/api-testing/api-chaining) |
### What the API-testing walkthroughs cover
* **API overview:** understand where request steps, response variables, validations, and hybrid API-plus-UI flows fit.
* **First API test:** configure a request, store its response, add an assertion, and inspect the execution result.
* **API chaining:** extract a value from one response and reuse it in a later request without hardcoding a runtime token.
## Frequently asked questions
Which walkthrough should a new ContextQA user watch first?
Start with **Generate and execute your first web test** if you test a browser application, **Upload, configure, and run your first mobile test** for an Android or iOS app, or **Create your first API test** for a REST API. Continue with the written guide beside the selected video.
Can I understand a walkthrough without watching the video?
Yes. Each recording has a written business outcome and a related guide. The section summaries describe the workflow in text, while the written guide provides the detailed instructions.
Why does a video open in Google Drive?
The recordings are hosted in Google Drive and link directly to its public preview player. If a player is blocked by your browser or network, use the paired written guide or open the complete source folder.
Are the videos or written guides the authoritative instructions?
Use the written guide as the maintained reference for current user-facing behavior. The video demonstrates the workflow visually, while the written guide is easier to update when labels, navigation, or available options change.
If a player does not open, check whether your browser or network blocks Google Drive. You can also open the [complete source video folder](https://drive.google.com/drive/folders/1bRDzkQHTgqATstdfZBAZsnjr_ehEBADr) to access the original recordings.
## Want a walkthrough tailored to your workflow?
The recordings demonstrate standard workflows. For a guided walkthrough using your application, platform, and testing priorities, book a personalized session with the ContextQA team.
[**Book a Demo →**](https://contextqa.com/book-a-demo/)
# Tutorial: Prepare a CI/CD quality gate
Prepare a reliable ContextQA test plan, scoped automation credential, and pipeline gate without relying on unpublished REST endpoints.
## Quick answer
Prepare a reliable ContextQA test plan, scoped automation credential, and pipeline gate without relying on unpublished REST endpoints. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
This tutorial prepares the ContextQA and pipeline-side pieces of a quality gate. It intentionally does not provide a REST call copied from portal traffic: the verified production **CI / CD** tab describes the start and status operations but does not publish endpoint paths.
## Outcome
By the end, you will have:
* A small, stable suite for release-blocking coverage.
* A test plan that supplies the browser or device, environment, and execution settings.
* A narrowly scoped API token stored in your CI system's secret manager.
* A quality-gate design ready for the public API contract supplied to your workspace.
## Prerequisites
* Permission to create or edit test suites and test plans.
* Superadmin access for API token creation, or an administrator who can create the token for you.
* Permission to add protected secrets and variables to your pipeline project.
## Step 1: Build a focused CI suite
1. Open **Plans → Test Suites**.
2. Click **Create Test Suite**.
3. Choose the required platform and add only deterministic, release-blocking cases.
4. Give the suite a purpose-based name such as `Checkout PR gate`.
5. Run each case individually and fix unstable setup before continuing.
A small suite gives developers fast, actionable feedback. Keep broad regression coverage in a separate scheduled plan.
## Step 2: Create the executable test plan
1. Open **Plans → Test Plans** and click **New Test Plan**.
2. Add the CI suite.
3. Map it to the required browser or device.
4. Select the staging environment and configure timeouts, screenshots, and recovery behavior.
5. Start with one parallel node while validating the gate.
6. Create the plan, then run it manually once.
Do not connect CI until the plan passes against the same environment and data that the pipeline will use.
## Step 3: Review the production CI/CD surface
Open the plan and select **CI / CD**. The current page lists supported integration targets and two REST operation concepts:
* **Start Test Plan** — returns a run ID for polling.
* **Check Status** — returns status, result, and suite breakdown information.

{% hint style="warning" %}
The verified production tab does not publish endpoint paths. Older examples using `/auth/login`, `/testplans/{id}/execute`, or `/executions/{id}/status` are obsolete. Do not substitute internal portal request URLs.
{% endhint %}
## Step 4: Create a pipeline credential
1. Open **Settings → API Tokens**.
2. Click **Create token**.
3. Name it for the caller, such as `GitHub — checkout PR gate`.
4. Choose the shortest practical expiry.
5. Grant only the scopes required by the public contract supplied to your workspace.
6. Copy the value when it appears and save it immediately in the pipeline's secret manager.
Use a dedicated token per repository or pipeline so one integration can be rotated or revoked without disrupting the others.
## Step 5: Prepare pipeline variables
Use your CI system's protected secret store for the token and ordinary configuration variables for non-secret identifiers.
| Value | Storage | Example name |
| ---------------------------------- | ---------------- | ------------------------ |
| API token | Protected secret | `CONTEXTQA_API_TOKEN` |
| Test plan ID | Variable | `CONTEXTQA_TEST_PLAN_ID` |
| Public API base URL, when supplied | Variable | `CONTEXTQA_API_BASE_URL` |
Never store an account password, token value, or generated authorization header in the workflow file.
## Step 6: Design the gate
When the public contract is available, configure the pipeline job to:
1. Start the configured test plan.
2. Record the returned run ID without logging credentials.
3. Poll using the documented status operation at a bounded interval.
4. Stop at the documented terminal state.
5. Pass only for the documented successful result.
6. Surface the run ID and direct reviewers to ContextQA for the report.
Do not construct a report URL unless the public response explicitly returns one.
## Step 7: Validate before enforcing
1. Run the job on a disposable branch.
2. Confirm a passing plan produces a successful job.
3. Use an intentionally failing disposable test to confirm the job blocks as expected.
4. Confirm logs contain no token, password, request header, or sensitive test data.
5. Only then make the job required in branch or deployment protection.
## Troubleshooting
**The portal shows operation cards but no paths**
That is the verified production behavior. Obtain the current public contract from the official ContextQA reference available to your workspace. Do not derive it from browser developer tools.
**The token is rejected**
Check expiry, activation state, permission scopes, and the IP allowlist. The token authenticates calls only within its configured scope.
**The plan works manually but fails in CI**
Compare the environment, browser or device mapping, test data, and network access. The pipeline should trigger the same saved plan you validated manually.
## Related pages
* [Test Plans](/web-testing/test-plans)
* [API tokens](/administration/api-tokens)
* [GitHub Actions](/integrations/github-actions)
* [Integrations overview](/integrations/integrations)
* [ContextQA MCP server](/mcp-server/overview)
# Interactive Demo
Explore guided ContextQA product demos for test data, environments, AI-powered automation, and release confidence without creating an account.
## Quick answer
These click-through demos let you explore real ContextQA workflows without signing in or changing production data. Each walkthrough explains the user action, the product response, and the business value of the workflow. Use the short tours to evaluate a specific outcome, or open a detailed walkthrough when you want to inspect the complete workflow.
## Choose a demo
| Start with | Best for | Outcome |
| ----------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------ | -------------------------------------------------------------------------------- |
| [Platform capabilities](#explore-contextqa-platform-capabilities) | Evaluation teams comparing automation approaches | See how ContextQA connects test creation, execution, and release evidence |
| [API testing overview](/api-testing/api-testing#interactive-demo-api-testing-overview) | Developers and SDETs validating services | See how requests, validations, variables, and results fit together |
| [Create and execute an API test](/api-testing/creating-api-tests#interactive-demo-create-and-execute-an-api-test) | Teams starting API automation | Build, run, and inspect a reusable API test |
| [API chaining and tokens](/api-testing/api-chaining#interactive-demo-chain-api-calls-and-reuse-a-token) | Teams testing authenticated service journeys | Capture a response value and reuse it in later requests |
| [API and UI automation](/business-use-cases/complex-web-and-authentication#interactive-demo-connect-api-and-ui-automation) | Teams validating one journey across system layers | Use API setup and browser verification in one continuous flow |
| [Mobile testing overview](/mobile-testing/mobile-testing#interactive-demo-mobile-testing-overview) | Mobile QA teams evaluating Android and iOS coverage | Understand build, device, execution, and evidence workflows |
| [Gesture-based mobile testing](/mobile-testing/creating-mobile-tests#interactive-demo-configure-gesture-based-mobile-testing) | Mobile QA teams validating touch interactions | Configure tap, swipe, scroll, pinch, and zoom scenarios |
| [First mobile test](/mobile-testing/mobile-testing-tutorial#interactive-demo-run-your-first-mobile-test-on-a-real-device) | Teams evaluating the complete device workflow | Follow test creation through real-device execution and evidence |
| [Mobile suites and plans](/mobile-testing/mobile-test-plans#interactive-demo-organize-mobile-suites-and-plans) | Mobile release owners | Organize stable cases and preserve device-specific plan evidence |
| [Jira test generation](/integrations/jira#interactive-demo-generate-tests-from-jira) | Teams that manage requirements in Jira | Preserve requirement traceability while generating tests |
| [Jira defect reporting](/integrations/jira#interactive-demo-report-a-failure-to-jira) | Teams connecting test triage to delivery work | Carry failure evidence and root-cause context into Jira |
| [Test suites and plans](/web-testing/managing-test-suites#interactive-course-create-suites-and-start-a-test-plan) | Regression and release owners | Organize reusable coverage, configure execution, and run a plan |
| [Requirements to generated tests](/business-use-cases/requirements-to-release#interactive-demo-requirements-to-generated-tests) | QA teams turning source material into coverage | See the review path from requirement to generated tests in three screens |
| [Execution and evidence](/reporting/test-results#interactive-demo-execution-to-evidence) | SDETs and release owners investigating test runs | Follow a run from launch to durable evidence in four screens |
| [Root cause and impact analysis](/reporting/failure-analysis#interactive-course-analyze-root-cause-and-impact) | Teams triaging failed runs | Move from captured evidence to a reviewable AI-assisted assessment |
| [Access and system governance](/administration/administration#interactive-demo-access-and-system-governance) | Workspace administrators governing teams and settings | Review roles, members, audit activity, and organization settings in four screens |
| [Variables and environments](#use-variables-and-environments) | Testers and SDETs managing reusable data across deployment targets | Separate local, global, runtime, and environment-specific values |
| [Dynamic data generation](/web-testing/test-data-management#interactive-demo-generate-dynamic-test-data) | Teams preventing duplicate test-data collisions | Generate safe runtime values while keeping validations deterministic |
| [Self-healing and conditional validation](/web-testing/self-healing#interactive-demo-self-healing-and-conditional-validation) | Teams reducing routine locator maintenance | See how ContextQA repairs UI drift without hiding real failures |
| [Conditions and loops](/web-testing/test-steps-editor#interactive-demo-conditions-and-loops) | SDETs building data-dependent workflows | Model branches and repeated actions without duplicating tests |
| [Knowledge Base context](/ai-features/knowledge-base#interactive-demo-give-the-ai-agent-application-context) | Teams teaching the agent application conventions | Reuse governed guidance without copying it into every test |
| [Salesforce automation](/salesforce-testing/salesforce-testing#interactive-demo-salesforce-automation-overview) | Salesforce QA and release teams | See resilient Lightning automation, data, execution, and evidence |
| [First Salesforce test](/salesforce-testing/test-generation-and-execution#interactive-course-create-and-run-your-first-salesforce-test) | SDETs beginning Salesforce automation | Create and run a reusable Salesforce test in two segments |
| [Salesforce API and UI validation](/business-use-cases/salesforce-and-enterprise-workflows#interactive-demo-connect-salesforce-api-and-ui-validation) | Enterprise teams validating cross-layer outcomes | Combine fast API setup with user-visible Salesforce verification |
{% hint style="info" %}
No ContextQA account is required. The demos use guided, non-destructive screens and do not expose customer credentials or production test data.
{% endhint %}
## Explore ContextQA platform capabilities
Start here for an end-to-end orientation. The walkthrough connects the major stages of the ContextQA workflow so an evaluation team can decide which feature guide to explore next.
{% embed url="" %}
### What to notice
* ContextQA brings test design, execution, and result review into one governed workflow.
* Guided screens let stakeholders evaluate the user experience without accessing a live workspace.
* The final call to action opens a tracked request for a tailored evaluation.
## Use variables and environments
Use this demo when one test must combine case-specific values, shared workspace data, runtime outputs, and deployment-specific configuration. It shows how ContextQA keeps those scopes explicit so teams can reuse data without coupling unrelated tests or hard-coding target URLs.
{% embed url="" %}
### What to notice
* Local variables keep temporary or case-specific values close to the test that owns them.
* Global variables and data profiles provide controlled reuse across tests.
* Environment values keep URLs and target-specific configuration out of test steps.
* Test data profiles let one test cover multiple data combinations.
* Clear scope reduces duplicated setup, maintenance effort, and accidental data conflicts.
Read the complete guides to [test data](/web-testing/test-data-management) and [environment management](/web-testing/environment-data-management).
## How to use these demos
{% hint style="warning" %}
Any username, password, token, payment value, or one-time code visible in a captured demo is illustrative test data only. It is not a reusable ContextQA login and does not grant access to the captured workspace. Do not copy it into your application; use your own approved evaluation credentials.
{% endhint %}
1. Choose the workflow closest to the problem you are solving.
2. Follow the highlighted action in each step; use full-screen mode when available.
3. Open the linked guide for prerequisites, detailed instructions, and verification criteria.
4. Use the final call to action to evaluate the same workflow with your application and team.
## Frequently asked questions
### Is this a video or a live product trial?
It is an interactive product walkthrough. You control the pace and follow guided actions on captured ContextQA screens, so you can understand the workflow without provisioning a workspace.
### Do I need a ContextQA account?
No. These demos are publicly viewable and do not require credentials. A ContextQA workspace is needed only when you want to create, execute, and manage your own automated tests.
### Can I use credentials shown inside a demo?
No. Values visible in a Storylane screen are captured examples, not live credentials or a shared trial account. The interactive embed also does not sign you in to the ContextQA portal. [Book a demo](https://contextqa.com/book-a-demo/?utm_source=learning.contextqa.com\&utm_medium=interactive_demo\&utm_campaign=storylane_docs\&utm_content=demo_credentials_faq) when you need an evaluation workspace or access instructions.
### Can ContextQA use my application and test data?
Yes. During an evaluation, ContextQA can be configured for your application, environments, reusable data, browser or device coverage, and governance requirements. The public demos intentionally use safe example data.
### Where can I learn the full workflow?
Every demo links to its corresponding documentation page. The documentation explains prerequisites, field behavior, expected results, limitations, and related capabilities in a format that both people and AI assistants can retrieve and cite.
## Evaluate ContextQA with your application
See how the same reusable-data and environment patterns apply to your release process, then expand into AI-authored tests, cross-browser execution, evidence, and reporting.
{% hint style="success" %}
[Book a ContextQA demo →](https://contextqa.com/book-a-demo/?utm_source=learning.contextqa.com\&utm_medium=interactive_demo\&utm_campaign=storylane_docs\&utm_content=demo_hub_end)
{% endhint %}
# Core Concepts
A practical explanation of every major building block in ContextQA, from workspaces and test cases to environments, self-healing, and the MCP server.
## Quick answer
A practical explanation of every major building block in ContextQA, from workspaces and test cases to environments, self-healing, and the MCP server. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** New and existing ContextQA users across all roles who want a clear mental model of how workspaces, test cases, suites, plans, and environments fit together.
{% endhint %}
ContextQA is organized around a small set of composable building blocks. Understanding how they relate to each other makes it much easier to structure your test suite, manage test data, and get the most from the AI capabilities. This page explains each concept with concrete examples drawn from realistic testing scenarios.

## Prerequisites
* You have a ContextQA account and have signed in at least once.
* You have read the [Introduction](/getting-started/introduction) and understand the platform's high-level purpose.
***
## The Building Block Hierarchy
Before diving into each concept individually, here is how they nest together:
```
Workspace
└── Test Plan
├── Environment (Staging / Production / QA)
└── Test Suite: "Smoke Tests"
├── Test Case: "Login — happy path"
│ ├── Step 1: Navigate to /login
│ ├── Step 2: Type email in Email field
│ ├── Step 3: Type password in Password field
│ ├── Step 4: Click Sign In button
│ └── Step 5: Verify dashboard is visible
└── Test Case: "Login — invalid credentials"
├── Step Group: SG_Navigate_To_Login
├── Step 1: Type wrong@email.com in Email field
├── Step 2: Type wrongpass in Password field
├── Step 3: Click Sign In button
└── Step 4: Verify error message is displayed
```
A **Test Plan** pulls together one or more **Test Suites**, each containing **Test Cases**, each built from individual **Steps** (or reusable **Step Groups**). The plan specifies the **Environment** to run against and the browsers or devices to target.
***
## Workspace
A workspace is the top-level container for everything related to one application under test. It is isolated — the test cases, environments, variables, knowledge bases, and settings inside one workspace are completely separate from those in another.
**When to create a new workspace:**
| Application | Workspace |
| ----------------------- | -------------------- |
| Customer-facing web app | `MyApp - Web` |
| iOS mobile app | `MyApp - iOS` |
| Internal REST API | `MyApp - API` |
| Salesforce CRM instance | `MyApp - Salesforce` |
**Practical example:** Your company has a SaaS product with a React web frontend, a React Native mobile app, and a public REST API. You create three workspaces — one per target. Each workspace has its own environments (staging vs production), its own test cases, and its own execution history. Team members can be invited to specific workspaces with different permission levels.
***
## Test Case
A test case is the atomic unit of testing. It represents one complete user scenario — from opening a page to completing an action and asserting the expected outcome. Every test case has:
* **Name** — a human-readable label
* **Starting URL** — where the browser navigates when the test begins
* **Steps** — an ordered list of actions and verifications
* **Tags** — optional labels for filtering (e.g., `smoke`, `regression`, `login`)
* **Prerequisite test cases** — other test cases that must pass before this one runs
* **Test Data Profile** — optional parameterized data set for data-driven runs
**Practical example:** A test case named "Add item to cart — guest user" starts at `https://shop.example.com`, searches for "blue t-shirt", selects the first result, clicks "Add to Cart", and verifies the cart icon shows 1 item. This is one atomic scenario with a clear starting state, actions, and an assertion.
**Prerequisite linking:** If your "Checkout" test case requires a logged-in session that your "Login" test case establishes, you can link "Login" as a prerequisite of "Checkout". ContextQA runs prerequisites first and shares session state.
***
## Step Groups
A step group is a reusable library of steps that can be inserted into any test case like a function call. When you update a step group, every test case that uses it automatically inherits the change.
**Common step group patterns:**
| Step Group Name | Contents |
| ------------------------ | --------------------------------------------------------------------------- |
| `SG_Login_Admin` | Navigate to /login, type admin credentials, click Sign In, verify dashboard |
| `SG_Login_Guest` | Navigate to /login, type guest credentials, click Sign In |
| `SG_Close_Cookie_Banner` | Click the "Accept All" button if the cookie consent banner is visible |
| `SG_Checkout_Payment` | Fill card number, expiry, CVV, click Pay Now |
**Practical example:** You have 40 test cases that all start with logging in. Instead of repeating the login steps in each test case, you create `SG_Login` once. When the login page redesigns and the button label changes from "Sign In" to "Log In", you update `SG_Login` in one place and all 40 test cases are fixed instantly.
**Creating a step group:**
1. Navigate to Test Cases → Step Groups.
2. Click + Create Step Group.
3. Give it a name (prefix with `SG_` by convention).
4. Add steps exactly as you would in a test case.
Alternatively, use the three-dot menu on any test case → Clone → As Step Group to convert an existing test case into a reusable step group.
***
## Test Suite
A test suite is a named grouping of test cases. Suites serve two purposes: they organize related tests logically, and they define what executes together when the suite is included in a test plan.
**ContextQA supports nested suites** — a suite can contain sub-suites, creating a folder-like hierarchy for large test libraries.
**Practical example:**
```
Suite: "E-Commerce Regression"
├── Sub-suite: "Authentication"
│ ├── Login — valid credentials
│ ├── Login — invalid credentials
│ └── Password reset flow
├── Sub-suite: "Product Catalog"
│ ├── Search by keyword
│ ├── Filter by category
│ └── Product detail page
└── Sub-suite: "Checkout"
├── Add to cart — single item
├── Apply discount code
└── Complete purchase — credit card
```
**Naming convention:** Use a prefix that describes the suite's purpose and scope. Examples: `Smoke_Auth`, `Regression_Checkout`, `API_Products`, `Mobile_Onboarding`.
***
## Test Plan
A test plan is the run configuration. It brings together everything needed to execute a meaningful batch of tests:
* **Which suites** to include
* **Which browser(s)** to target (Chrome, Firefox, Safari, Edge) or which device for mobile
* **Which environment** to run against (Staging, Production, QA)
* **Parallel or sequential** execution
* **Schedule** (cron expression for recurring runs)
* **Notifications** (Slack channel, email recipients for results)
**Practical example:** Your CI/CD pipeline has two test plans:
1. `Smoke Plan` — runs the Smoke\_Auth and Smoke\_Checkout suites in Chrome against the Staging environment on every pull request. Runs in parallel, completes in under 5 minutes.
2. `Nightly Regression` — runs the full E-Commerce Regression suite against Chrome, Firefox, and Edge against the Production environment every night at midnight. Runs in parallel across browsers.
One test case can appear in multiple test plans, running against different environments or browser configurations without duplication.
***
## Environment
An environment is a named configuration that stores the base URL and a dictionary of key-value parameters for one deployment of your application.
**Anatomy of an environment:**
| Key | Value | Type |
| ------------- | --------------------------- | -------------------- |
| `BASE_URL` | `https://staging.myapp.com` | text |
| `API_KEY` | `sk-staging-abc123` | password (encrypted) |
| `DB_HOST` | `db-staging.internal` | text |
| `ADMIN_EMAIL` | `admin@staging.myapp.com` | text |
**Using environment variables in steps:** Reference them with the `${ENV.KEY}` syntax anywhere in a step description, URL field, or API call configuration:
* `Navigate to ${ENV.BASE_URL}/dashboard`
* `Set Authorization header to Bearer ${ENV.API_KEY}`
**Practical example:** You have two environments: `Staging` and `Production`. Both have the same keys but different values. By selecting the environment in your test plan, you can run the exact same test suite against either environment without editing a single test step.
**Password-type parameters** are stored encrypted and are never shown in plain text in the UI or in execution logs.
***
## Test Data Profile
A test data profile is a parameterized data set that enables data-driven testing — running the same test case multiple times with different input values.
**Structure:** A profile is a table where each column is a named variable and each row is one test run.
| `username` | `password` | `expected_result` |
| ------------------- | ----------- | --------------------- |
| `admin@test.com` | `Admin123!` | `Admin Dashboard` |
| `user@test.com` | `User456!` | `User Dashboard` |
| `readonly@test.com` | `Read789!` | `Read-Only Dashboard` |
When this profile is attached to the "Login" test case and executed, ContextQA runs the test three times — once per row — substituting `${username}`, `${password}`, and `${expected_result}` in the steps.
**Practical example:** Your login form needs to be tested with 10 different user roles. Instead of creating 10 separate test cases, you create one test case and one profile with 10 rows. The profile runs produce 10 individual execution records with independent pass/fail results.
**Creating a data profile:**
1. Navigate to Environment & Data → Data Profiles.
2. Click + Create Profile.
3. Define column names (these become the variable names).
4. Add rows of data.
5. In your test plan, attach the profile to the test case.
***
## Knowledge Base
A knowledge base is a set of plain-English instructions stored in your workspace that the AI test agent consults before and during execution. It is the mechanism for teaching the AI how to handle recurring situations specific to your application.
**Common knowledge base entries:**
* "If a cookie consent banner appears, click the 'Accept All Cookies' button before proceeding."
* "If a chat widget opens in the bottom-right corner, close it by clicking the X icon."
* "The application may show a 'Session expired' modal. If it appears, click 'Stay logged in'."
* "On the payment page, always use the test card number 4111 1111 1111 1111 with expiry 12/26 and CVV 123."
**Practical example:** Your application shows a GDPR cookie consent modal on first visit. Without a knowledge base entry, the AI might try to interact with the page before the modal is dismissed, causing failures. With the entry "Close the cookie banner before any other action", every test in the workspace automatically handles the modal correctly.
Knowledge bases are workspace-scoped — they apply to every test case in the workspace automatically.
***
## Custom Agents
A custom agent is an AI persona with a specialized system prompt. While the default ContextQA AI agent is calibrated for general web testing, custom agents can be configured for domain-specific testing scenarios.
**Use cases:**
* A Salesforce agent calibrated to understand Lightning component naming conventions
* An accessibility testing agent that looks for ARIA violations on every page
* A financial application agent that understands currency formatting and validation rules
* A localization agent that tests right-to-left layouts and non-ASCII character handling
Custom agents are created in Settings → Custom Agents and can be selected when creating or executing a test case.
***
## Execution
An execution is one complete run of a test case, test suite, or test plan. Each execution produces:
* A unique `execution_id` (also called `result_id`)
* Pass/fail status per step
* Screenshots captured at each step
* Full video recording of the browser session
* Network HAR log (all HTTP requests and responses)
* Browser console log (errors, warnings, info)
* Playwright trace file (for deep debugging)
* AI-generated root cause analysis (for failures)
Executions are stored indefinitely by default and can be accessed from the Execution History panel.
***
## Self-Healing
Self-healing is the AI capability that automatically repairs a broken test step when the UI element it references has changed.
**When healing occurs:**
1. A step tries to interact with an element (e.g., "Click the Sign In button").
2. The element cannot be found at its previously known location.
3. The AI scans the current page using visual analysis and DOM inspection.
4. If a semantically equivalent element is found with a confidence score above 90%, the step is automatically updated.
5. Execution continues without a failure being recorded.
**What triggers self-healing:**
* Button text changes ("Sign In" → "Log In")
* CSS class or ID attribute changes after a design system update
* Element moved to a different DOM position
* `data-testid` attribute renamed
**What does not trigger self-healing:**
* Elements completely removed from the page (this is treated as a genuine failure)
* Entire page flows replaced (the test needs to be rewritten)
* Confidence below 90% (flagged for manual review instead)
After execution, the report shows healed steps with their original locator, the healed locator, and the confidence score.
***
## MCP Server
The ContextQA MCP (Model Context Protocol) server exposes 67 platform tools to external AI assistants. Any MCP-compatible client — including Claude, Cursor, and GPT with the right plugins — can call these tools to create, run, and analyze tests programmatically.
**Examples of what an AI assistant can do via MCP:**
* "Create a test case for the login flow of my app" → calls `create_test_case`
* "Run the smoke suite and tell me the results" → calls `execute_test_suite`, then `get_execution_status`
* "Which tests are currently failing?" → calls `get_test_case_results`
* "Show me auto-healing suggestions for the last run" → calls `get_auto_healing_suggestions`
The MCP server is the foundation for the ContextQA integration with Claude Code, enabling test automation directly from your development environment.
***
## Tips & Best Practices
* **Keep test cases atomic** — one scenario per test case. This makes failures easier to diagnose and keeps execution time predictable.
* **Build step groups early** — identify repeated setup patterns (login, navigation to a module) and extract them as step groups before you have too many test cases to refactor.
* **Use environments from day one** — even if you only have one environment initially, setting up the environment configuration makes it easy to add staging/production variants later.
* **Write knowledge base entries proactively** — before creating test cases, add entries for any persistent UI elements that could interfere with automation (banners, modals, tours, chat widgets).
* **Tag every test case** — consistent tagging (smoke, regression, critical, login) allows you to build targeted test plans for different CI/CD stages.
## Troubleshooting
**My test cases do not appear in a suite after adding them** Refresh the page. The suite member list updates asynchronously and may take a moment to reflect changes.
**Environment variables are not being substituted in steps** Check that the variable name in the step exactly matches the key in the environment configuration, including case sensitivity. `${ENV.baseUrl}` and `${ENV.BaseUrl}` are different.
**A step group I updated is not reflecting in test cases** Step groups are resolved at execution time. Re-run the affected test cases to see the updated step group content. There is no need to re-open or re-save the test cases.
**The AI is not respecting my knowledge base instructions** Knowledge base entries must be written as clear, imperative instructions. Avoid ambiguous language. Instead of "handle cookie popups", write "If a cookie consent banner is visible, click the button labelled Accept All Cookies immediately before any other interaction."
## Related Pages
* [Introduction to ContextQA](/getting-started/introduction)
* [Platform Architecture](/getting-started/architecture-overview)
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Test Data Management](/web-testing/test-data-management)
* [AI Self-Healing](/web-testing/self-healing)
* [Configuring Environments](/execution/environments)
* [Glossary](/reference/glossary) — definitions of key terms
{% hint style="info" %}
**Create your first test in 5 minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see ContextQA with your application.
{% endhint %}
# Platform Architecture
A detailed explanation of ContextQA's 9-stage AI execution pipeline, its 13+ specialized agents, infrastructure components, and the MCP server that connects the platform to external AI assistants.
## Quick answer
A detailed explanation of ContextQA's 9-stage AI execution pipeline, its 13+ specialized agents, infrastructure components, and the MCP server that connects the platform to external AI assistants. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Engineers and technical leads who want to understand ContextQA's 9-stage AI pipeline, infrastructure components, and how evidence is captured during execution.
{% endhint %}
ContextQA executes tests through a 9-stage agentic pipeline in which 13 or more specialized AI agents collaborate to navigate, interact, verify, and repair tests against real browsers and devices. This page explains how each stage works, how the agents communicate, and how the supporting infrastructure stores and serves the evidence those agents produce.
Understanding the architecture helps you write better tests, interpret execution results accurately, and troubleshoot failures more effectively.

## Prerequisites
* You have read the [Introduction](/getting-started/introduction) and [Core Concepts](/getting-started/core-concepts).
* You understand the difference between a test case, a test suite, and a test plan.
***
## The 9-Stage AI Execution Pipeline
Every test execution — whether triggered manually, via CI/CD, or by a schedule — passes through all nine stages in order. Stages run sequentially per step but the platform can run multiple test cases in parallel across browser instances.
### Stage 1: Navigation
The pipeline begins by launching a browser instance and navigating to the starting URL defined in the test case. The navigation agent establishes the initial page context, waits for the page to reach a stable "load complete" state (using both the browser's `load` event and an AI-assessed visual stability check), and hands off control to the next stage.
If the navigation fails — for example, because the URL is unreachable or redirects to an error page — the execution terminates immediately with a root cause entry explaining the navigation failure.
### Stage 2: Element Discovery
Before executing any step, the element discovery agent performs a full scan of the current page. It combines two complementary signals:
* **DOM analysis** — the agent inspects the HTML structure, ARIA roles, `data-testid` attributes, input types, form labels, and button text to build an element inventory.
* **Visual analysis** — a screenshot is analyzed using computer vision to identify interactive regions, buttons, form fields, navigation menus, and modal dialogs that may not have clean DOM representations.
The element inventory is used by the step execution agent to match natural language step descriptions to real page elements. This dual-signal approach handles both well-structured SPAs and legacy applications with inconsistent DOM hygiene.
### Stage 3: Step Execution
The step execution agent interprets each natural language step and performs the corresponding browser action. The agent:
1. Reads the step description (e.g., "Type in the Email field").
2. Consults the element inventory from Stage 2 to locate the target element.
3. Executes the action via the browser automation layer (click, type, select, scroll, hover, drag-and-drop).
4. Waits for the browser to stabilize after the action (dynamic content settling, navigation completing, network requests resolving).
5. Updates the element inventory for the next step.
The step execution agent handles implicit waits automatically. You do not need to add sleep or wait steps for standard navigation and form interactions.
### Stage 4: Screenshot Capture
After every step execution (regardless of pass or fail), the screenshot capture agent saves a full-page screenshot to object storage. Screenshots are:
* Stored in S3 with a unique key per step per execution.
* Linked to the step result record in the database.
* Accessible in the execution report immediately after the step completes.
* Available for 90 days by default (configurable per workspace).
Screenshot capture can be configured per step: **Always** (default), **On Failure Only**, or **Never**.
### Stage 5: Network Monitoring
The network monitoring agent runs continuously throughout execution, intercepting all HTTP and HTTPS traffic produced by the browser. For every request it captures:
* Request method, URL, headers, and body
* Response status code, headers, and body
* Timing data (DNS resolution, connection, TLS handshake, time-to-first-byte, download duration)
The full HAR (HTTP Archive) log is attached to the execution record and viewable in the results report. This is particularly useful for diagnosing failures caused by API errors, authentication token expiry, or third-party service outages that are not visible in the UI screenshots.
### Stage 6: Console Monitoring
The console monitoring agent captures every message written to the browser console during execution: `console.log`, `console.warn`, `console.error`, and unhandled JavaScript exceptions. Console entries are timestamped and correlated with the step that was executing when they were emitted.
For applications that log structured diagnostic data to the console, this stage often reveals the root cause of a failure faster than the screenshots alone.
### Stage 7: AI Verification
When a step is an assertion ("verify the welcome message is displayed", "confirm the order total is correct"), the AI verification agent processes the step differently from an action step.
The verification agent:
1. Takes the current screenshot.
2. Reads the natural language verification condition.
3. Uses a vision-language model to evaluate whether the condition is satisfied in the screenshot.
4. Produces a boolean result (pass/fail) and a confidence score.
5. Adds a natural language explanation of what was observed to the step result.
This approach handles dynamic, unpredictable content that cannot be verified with hard-coded assertions. For example, "verify a unique order ID was generated and displayed" does not require knowing the exact order ID — the AI verifies that a plausible order ID is present in the expected location.
For deterministic assertions (exact string matching, specific numeric values), the agent performs the string comparison directly rather than relying solely on visual interpretation.
### Stage 8: Self-Healing
The self-healing agent activates when a step execution fails because an expected element was not found at its known location.
When a locator fails, the self-healing agent analyzes the current page state and finds the best matching element using AI.
Self-healing events are non-destructive: the healed locator is applied persistently to the test case going forward, so future runs do not need to heal the same step again.
### Stage 9: Evidence Collection
After all steps have executed, the evidence collection agent compiles the final execution record:
* **Video recording** — the full browser session stitched from the frame captures taken during execution, encoded as an MP4.
* **Playwright trace** — a structured trace file compatible with Playwright's trace viewer, containing DOM snapshots, action timeline, and network log for deep debugging.
* **Root cause analysis** — for any failed steps, the AI generates a structured root cause analysis that identifies the likely cause of the failure, distinguishes flakiness (transient network issues, race conditions) from genuine application bugs, and suggests corrective actions.
* **Execution summary** — overall pass/fail, duration, step count, browser/device used, environment.
All evidence assets are stored in S3 and linked to the execution record. The execution report page in the portal assembles all of this data into a readable, navigable view.
***
## Infrastructure Components
### Frontend
The ContextQA web portal is an **Angular TypeScript** single-page application. It communicates with the backend via REST APIs and WebSocket connections (for live execution streaming). The portal handles workspace management, test case authoring, execution triggering, report viewing, and administration.
### AI Engine
The AI engine is a **multi-agent pipeline** comprising 13 or more specialized agents. Agents are implemented as fine-tuned and prompted language models and vision-language models, orchestrated by a central pipeline coordinator. Agent specializations include:
| Agent | Responsibility |
| -------------------------- | ---------------------------------------------------- |
| Navigation Agent | URL navigation, page load stabilization |
| Element Discovery Agent | DOM and visual element inventory |
| Step Interpretation Agent | Natural language to browser action mapping |
| Verification Agent | AI-powered assertion evaluation |
| Self-Healing Agent | Broken locator detection and repair |
| Root Cause Analysis Agent | Failure diagnosis and explanation |
| Test Generation Agent | Creating test steps from natural language tasks |
| Code Generation Agent | Exporting tests as Playwright/Selenium code |
| Figma Analysis Agent | Extracting test scenarios from design files |
| Ticket Analysis Agent | Extracting test scenarios from Jira/Linear tickets |
| Video Analysis Agent | Extracting test scenarios from screen recordings |
| API Analysis Agent | Extracting test scenarios from Swagger/OpenAPI specs |
| Performance Analysis Agent | Load test result interpretation |
### MCP Server
The **ContextQA MCP Server** is a Python application built with the **FastMCP** framework. It exposes 67 platform capabilities as callable tools following the Model Context Protocol specification.
The server accepts connections from any MCP-compatible client (Claude Desktop, Cursor, custom integrations) and translates tool calls into authenticated requests to the ContextQA backend API.
Key tool categories exposed by the MCP server:
| Category | Example Tools |
| ----------------- | --------------------------------------------------------------------------------------------- |
| Test authoring | `create_test_case`, `update_test_case_step`, `create_complex_test_step` |
| Execution | `execute_test_case`, `execute_test_suite`, `execute_test_plan` |
| Results retrieval | `get_execution_status`, `get_test_step_results`, `get_test_case_results` |
| Evidence | `get_console_logs`, `get_network_logs`, `get_trace_url` |
| Self-healing | `get_auto_healing_suggestions`, `approve_auto_healing` |
| AI insights | `get_ai_insights`, `get_root_cause`, `investigate_failure` |
| Test generation | `generate_tests_from_jira_ticket`, `generate_tests_from_figma`, `generate_tests_from_swagger` |
The MCP server source code is open source and available in the ContextQA GitHub organization.
### Storage
* **Object Storage (S3)** — screenshots, video recordings, Playwright traces, HAR files. Assets are stored per execution with a structured key format: `{workspace_id}/{execution_id}/{step_index}/screenshot.png`.
* **Relational Database** — test case definitions, execution records, step results, workspace configuration, user accounts.
* **Secrets Storage** — environment parameter values of type `password` are stored encrypted at rest using AES-256 and are never returned in plain text through any API endpoint.
### Authentication
ContextQA uses **session-based authentication** for the web portal. Users authenticate with email and password (or SSO via SAML 2.0 for enterprise accounts). API access and MCP server connections use **API keys** scoped to a workspace, generated in Settings → API Keys.
***
## Execution Flow: End to End
The following trace shows what happens from the moment you click **Run** on a test case to the moment the report is available:
```
1. User clicks Run in portal
2. Portal sends POST /api/executions { test_case_id, environment_id, browser }
3. Backend creates execution record (status: QUEUED)
4. Execution coordinator picks up the job from the queue
5. Browser instance is launched (headless Chrome / visible Chrome)
6. Stage 1: Navigation agent navigates to starting URL
7. For each step:
a. Stage 2: Element discovery agent scans current page
b. Stage 3: Step execution agent performs action
c. Stage 4: Screenshot agent captures current state → upload to S3
d. Stage 5: Network agent appends request/response to HAR buffer
e. Stage 6: Console agent appends new console entries
f. If assertion step → Stage 7: AI verification agent evaluates condition
g. If element not found → Stage 8: Self-healing agent attempts repair
h. Step result (pass/fail, screenshot URL) written to database
i. Portal receives step result via WebSocket → live UI updates
8. Stage 9: Evidence collection
a. Video recording encoded and uploaded to S3
b. Playwright trace compiled and uploaded to S3
c. Root cause analysis generated for any failed steps
d. Execution record updated to PASSED or FAILED
9. Portal receives completion event via WebSocket
10. User sees final report with all evidence linked
```
***
## Tips & Best Practices
* **Understand Stage 7 for better assertions** — The AI verification agent is powerful but works best with clear, observable conditions. "Verify the page title says Welcome, John" is more reliable than "Verify the user logged in successfully" because the former specifies an observable UI element.
* **Use network logs for API failures** — If your test fails on a page action but the screenshot shows the UI looks correct, check the network log. A 401 or 500 response from an API call is often the real cause.
* **HAR logs contain sensitive data** — Network logs capture request and response bodies, which may include tokens, session cookies, or user data. Manage access to execution reports accordingly.
* **Self-healing is conservative by design** — The confidence threshold is intentional. A lower threshold would cause incorrect healings that mask real failures. If a step consistently fails the self-healing check, it is a signal that the application change is significant enough to warrant a manual test review.
## Troubleshooting
**Screenshots are not loading in the report** S3 asset retrieval uses pre-signed URLs that expire after 1 hour. If you are viewing a report after the URL expiry, refresh the page to generate new pre-signed URLs.
**The live execution view is not updating in real time** The live view uses a WebSocket connection. If you are behind a proxy or corporate firewall that terminates WebSockets, the view will fall back to polling, which updates every 5 seconds. Check with your network administrator if the fallback is noticeably delayed.
**Root cause analysis says "Analysis unavailable"** Root cause analysis requires at least one failed step with a screenshot. If the execution failed before any screenshot was captured (e.g., Stage 1 navigation failure due to a network timeout), the AI has insufficient evidence to generate analysis. The raw error message from the browser is still shown in the step result.
**The MCP server is not connecting** Verify that the API key in your MCP client configuration belongs to the correct workspace and has not been revoked. API keys can be managed in Settings → API Keys.
## Related Pages
* [Introduction to ContextQA](/getting-started/introduction)
* [Core Concepts](/getting-started/core-concepts)
* [AI Self-Healing](/web-testing/self-healing)
* [MCP Server](/mcp-server/overview)
* [Running Tests](/execution/running-tests)
{% hint style="info" %}
**Create your first test in 5 minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see ContextQA with your application.
{% endhint %}
# Web Testing Overview
Complete guide to creating, managing, and executing web application tests in ContextQA — from recording your first test to running full regression suites.
{% hint style="info" %}
**Who is this for?** Testers and SDETs who want to automate web application testing using natural language — no Selenium or Playwright expertise required.
{% endhint %}
ContextQA's web testing capabilities let you build automated tests for any web application in natural language — no code required. The AI agent navigates real browsers, interacts with your UI, and verifies results exactly as a human QA engineer would.
## Quick answer
ContextQA web testing converts a plain-English workflow, recorded browser session, or imported requirement into a reviewable automated test. The saved test runs in a real browser, collects step-level and execution-level evidence, and can be reused in suites, test plans, schedules, and CI/CD quality gates. Self-healing addresses routine element-location drift while genuine application failures remain visible for investigation.
***
## How Web Testing Works
1. **Describe the test** — Write what you want to test in plain English, including the steps to perform and what to verify.
2. **ContextQA creates the steps** — The AI parses your description into structured, executable steps.
3. **Execution runs in a real browser** — The AI agent navigates Chrome, Firefox, Safari, or Edge with actual browser rendering and JavaScript execution.
4. **Evidence is collected automatically** — Screenshots, video, network HAR, and console logs are captured for every run.
5. **AI self-healing keeps tests green** — If a UI element changes, the agent automatically finds the equivalent new element and continues.
***
## Supported Browsers
| Browser | Versions | Notes |
| ------- | ------------------- | ------------------------- |
| Chrome | Latest + 2 previous | Default; best performance |
| Firefox | Latest + 2 previous | |
| Safari | Latest | macOS/iOS only |
| Edge | Latest | Chromium-based |
Browser selection is configured in the **Test Plan** or per individual execution run.
***
## What You Can Test
* **Single-page applications** (React, Angular, Vue, Svelte) — full JavaScript execution and dynamic routing
* **Traditional server-rendered sites** — page loads, form submissions, redirects
* **Authentication flows** — login, logout, SSO/SAML redirect handling, MFA (with Knowledge Base entries)
* **Multi-step workflows** — checkout flows, onboarding wizards, multi-page forms
* **Data entry and validation** — form field inputs, error messages, required field enforcement
* **Navigation and routing** — breadcrumbs, back button behavior, deep link handling
* **API-backed UI** — the network monitor captures all XHR/fetch requests, so API failures surface in test results
* **PDF and file download** — verify that downloads trigger and files have expected content
* **File uploads** — test file input fields with actual files
* **Responsive layouts** — set the viewport size per run to test desktop, tablet, and mobile breakpoints
***
## In This Section
### Creating and editing tests
| Page | What you'll learn |
| --------------------------------------------------------- | -------------------------------------------------------------------------------------------------- |
| [Creating Test Cases](/web-testing/creating-test-cases) | How to write effective test descriptions; AI-powered test generation from tickets and requirements |
| [Test Steps Editor](/web-testing/test-steps-editor) | Manual step editing; conditional logic (If / Else If / Else), loops, API calls, and step groups |
| [Debugging Test Cases](/web-testing/debugging-test-cases) | Debug interactively with breakpoints, live variable inspection, and step-by-step execution |
### Requirements-driven testing
| Page | What you'll learn |
| --------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------ |
| [Requirements Management](/web-testing/requirements-management) | Upload requirement documents and let AI generate test cases, analyze coverage gaps, and track change history |
| [Requirements Library](/web-testing/requirements-library) | Review AI-generated test cases, analyze coverage gaps, and manage your requirements library |
| [Uploaded Test Files](/web-testing/uploaded-test-files) | View and manage imported requirement files, review AI analysis, and inspect file metadata |
| [Imported Files](/web-testing/imported-files) | View test cases generated from imported files, review AI results, and track import history |
### Advanced step types
| Page | What you'll learn |
| ------------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| [Database Steps](/web-testing/database-steps) | Run SQL queries during tests and verify backend data with assertions |
| [Custom Code Steps](/web-testing/custom-code-steps) | Execute custom JavaScript for complex logic, calculations, and DOM interactions |
| [Document Generation Steps](/web-testing/document-generation-steps) | Generate TXT and CSV files dynamically for file upload and import testing |
### Test data and variables
| Page | What you'll learn |
| ------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------ |
| [Test Data Management](/web-testing/test-data-management) | Data-driven testing with parameterized profiles; local and global variables |
| [Environment Data Management](/web-testing/environment-data-management) | Manage environments, variables, database connections, and data profiles from one workspace |
| [Importing and Exporting Data](/web-testing/importing-and-exporting-data) | Export and import environments, data profiles, and variables using JSON or Excel |
### Suites, plans, and versioning
| Page | What you'll learn |
| --------------------------------------------------------- | -------------------------------------------------------------------------------------------------- |
| [Managing Test Suites](/web-testing/managing-test-suites) | Grouping test cases; building regression and smoke suites |
| [Test Plans](/web-testing/test-plans) | Creating execution plans; scheduling, CI/CD integration, parallel execution, and recovery settings |
| [Version History](/web-testing/version-history) | Track, compare, and restore previous versions of your test cases |
### AI self-healing
| Page | What you'll learn |
| -------------------------------------------------------------------- | ------------------------------------------------------------------------ |
| [AI Self-Healing](/web-testing/self-healing) | How self-healing works; reviewing and approving healing suggestions |
| [AI Self-Healing (Interactive Demo)](/web-testing/self-healing-demo) | See self-healing detect a broken locator and repair a step automatically |
### Tutorials
| Page | What you'll learn |
| -------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------- |
| [Tutorial: Data-Driven Testing](/web-testing/data-driven-testing-tutorial) | Build a parameterized login test that runs with multiple user roles from one data profile |
| [Tutorial: Step Groups](/web-testing/step-groups-tutorial) | Build a reusable login step group, insert it into multiple test cases, and update it once |
***
## Quick Start: Your First Web Test
If you want to jump straight in:
1. Go to **Test Cases** in the left navigation.
2. Click **+ New Test Case**.
3. Choose **Start with AI Assistance**.
4. Enter your application URL and a plain-English description:
```
Navigate to https://demo.myapp.com/login
Enter admin@test.com in the email field
Enter the password Admin123!
Click the Login button
Verify the page heading reads "Welcome back"
```
5. Click **Generate Test Case**.
6. Watch the AI run, capture screenshots, and build the structured steps.
7. Click **Run** to execute the saved test case.
The test is now saved and can be added to a suite and scheduled.
***
## Tips for Effective Web Tests
* **Be specific about what to verify** — "verify the order confirmation number appears" is better than "verify the page loads".
* **Use your Knowledge Base** — if your app has cookie banners, chat widgets, or feature tours, add Knowledge Base entries to dismiss them automatically before they interfere with tests.
* **Keep tests atomic** — one test case per user scenario. This makes failures easier to diagnose.
* **Use step groups for shared setup** — if 20 test cases all start with "log in as admin", create a Login step group and reuse it.
* **Set realistic environments** — always use an Environment record instead of hardcoding URLs in steps, so the same tests can run against staging and production.
***
## Related Pages
* [Tutorial: Data-Driven Testing](/web-testing/data-driven-testing-tutorial)
* [Core Concepts](/getting-started/core-concepts)
* [Execution & Scheduling](/execution/running-tests)
* [AI Features Overview](/ai-features/ai-features)
* [MCP Server](/mcp-server/overview)
## Frequently asked questions
Can ContextQA automate a web application without Selenium or Playwright code?
Yes. The standard workflow uses natural-language steps, AI assistance, browser recording, or imported requirements. ContextQA handles browser interaction and evidence capture. Custom JavaScript and Playwright export remain available for teams that need code-level extensions.
What is the difference between a test case, test suite, and test plan?
A test case represents one user scenario. A test suite groups related cases, such as smoke or checkout coverage. A test plan determines which suites run, along with the browser or device, environment, parallelism, notifications, and schedule.
Does self-healing hide application bugs?
Self-healing is intended for routine element-location drift, such as an equivalent button moving in the DOM. It does not make a failed business assertion pass, replace a removed workflow, or correct a server-side error. See [AI Self-Healing](/web-testing/self-healing) for triggers and limits.
Can the same web test run against staging and production?
Yes. Store deployment-specific URLs and values in environments instead of hardcoding them in the test. Select the intended environment when you configure or execute the plan.
Can web tests run in CI/CD?
Yes. Put the cases in a suite and plan, validate the plan in the portal, and connect it to an approved CI/CD or MCP workflow. See [Integrations](/integrations/integrations) and [Prepare a CI/CD quality gate](/getting-started/ci-cd-tutorial).
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Creating Test Cases
Create ContextQA test cases with AI assistance, file import, browser recording, or manual authoring, then verify the saved test in the editor.
## Quick answer
Create ContextQA test cases with AI assistance, file import, browser recording, or manual authoring, then verify the saved test in the editor. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers, testers, and developers who want to create web test cases using any of the four creation methods available in ContextQA.
{% endhint %}
## Overview
ContextQA provides a unified three-step creation dialog with four methods: **AI Assistance**, **Import Files**, **Record & Play**, and **Create manually**. Use this page when you need to create a test case and verify it in the test case editor.
{% hint style="warning" %}
**Recorder versus extension testing:** **Record & Play** uses the ContextQA recorder capability to capture a web flow. Testing a browser extension that belongs to the application under test is a separate environment setup: the extension build must be installed in a compatible managed browser, and its permissions and cross-surface workflow must be validated. See [Complex web and authentication workflows](/business-use-cases/complex-web-and-authentication).
{% endhint %}
***
## Opening the creation panel
{% stepper %}
{% step %}
### Navigate to test development
Open and sign in to your workspace. Select **Test Cases** from the left sidebar to open the test cases list.
{% endstep %}
{% step %}
### Select New Test Case
Select **New Test Case** in the page header. The **Create Test Case** dialog opens at step 1.
{% endstep %}
{% step %}
### Select a creation method
The panel presents a method selection screen with up to four options (availability depends on your plan and feature flags):
| Method | Description | Button Label |
| ----------------- | ------------------------------------------------------------------------- | ---------------------------- |
| **AI Assistance** | Provide a description and let ContextQA generate test cases automatically | **Start with AI Assistance** |
| **Import Files** | Upload requirements or test files to generate test cases | **Import Files** |
| **Record & Play** | Record your actions in the browser while ContextQA captures each step | **Start Recording** |
| **Manual** | Define the case and its steps yourself | **Create manually** |
After selecting a method, the dialog shows step 2 with the available starting action. Select **Back** to return to the preceding step.
{% hint style="info" %}
The **Import Files** option requires the relevant upload feature to be enabled on your plan. The **Record & Play** option requires the recorder capability.
{% endhint %}
{% endstep %}
{% endstepper %}
***
## Creation methods in detail
{% tabs %}
{% tab title="AI Assistance" %}
### AI-assisted test generation
Describe your test scenario in plain English. ContextQA's AI generates all steps, locators, and assertions automatically.
**Fields:**
| Field | Required | Description |
| -------------------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| **Prerequisites** | No | Select existing test cases to run before this test. Available on paid plans. |
| **URL** | Yes | The starting URL for the test (must begin with `http://` or `https://`). Hidden when prerequisites are selected or when targeting mobile. |
| **Description** | Yes | A plain-English description of the test scenario. |
| **Select Target Platform** | Yes | Choose **Web Application** or **Mobile**. Mobile is available when mobile execution is enabled on your plan. |
**Example description:**
```
Log in with the fictional documentation account, navigate to the
Products page, search for "wireless headphones", and verify that
at least one product appears in the search results.
```
**Advanced settings (optional):**
Expand the **Advanced Settings** section to configure AI behavior:
| Setting | Options | Default |
| ----------------------- | --------------------------------------------------------- | -------------------- |
| **Enable AI Smartness** | Organization Default, Expert, Fast, Strict | Organization Default |
| **AI Action** | Organization Default, Create Steps, Dynamic Steps, Action | Organization Default |
| **Knowledge Base** | Select a knowledge base to provide application context | None |
| **Environments** | Select a target environment | None |
Click **Generate & Execute Test Case** to create and run the test case. If the **Generate From Crawl** feature is enabled on your plan, you can click **Generate From Crawl** to create test cases by crawling the target URL.
The AI agent parses your description into discrete steps, generates locators for each element, handles dynamic content and waits automatically, and captures screenshots and video during execution.
**Best for:** Complex multi-page flows, form submissions, checkout workflows
{% endtab %}
{% tab title="Import Files" %}
### Import test cases or requirements
Upload files to generate test cases automatically. Three modes are available:
**Mode selection:**
| Mode | Description |
| ----------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| **Import Test Cases** | Upload an Excel spreadsheet (`.xlsx`, `.xls`) containing test case definitions |
| **Import Requirements** | Upload requirements documents (XLSX, CSV, TXT, PDF) or video files (MP4, MOV, WEBM, MPEG, MKV) to generate test cases from specifications |
| **Import from Jira** | Browse and select Jira tickets to generate test cases from ticket descriptions and acceptance criteria |
{% hint style="info" %}
The **Import from Jira** mode is available when Jira is configured from **Integrations & Plugins → Bug Reporting → Jira → View Details → Config**. See [Jira Integration](/integrations/jira) for setup instructions.
{% endhint %}
**Select Target Platform:**
| Platform | Availability |
| ------------------- | ------------------------------------------ |
| **Web Application** | Always available |
| **Mobile** | Always available |
| **API** | Available in Import Requirements mode only |
**Publish mode:**
Select how imported test cases are published:
| Mode | Description |
| --------------------- | ---------------------------------------------------------------------------------------------------------- |
| **Auto Publish** | Generated test cases are saved and published immediately |
| **Required Approval** | Generated test cases are saved in a pending state and require manual review and approval before publishing |
**Test case types:**
Select which types of test cases the AI generates. Toggle individual types on or off, or click **All Types** to include every type:
| Type | Description |
| -------------------- | --------------------------------------------------- |
| **Positive** | Validates expected behavior with valid inputs |
| **Functional** | Verifies feature functionality against requirements |
| **Negative** | Tests error handling with invalid inputs |
| **Edge** | Covers boundary and unusual scenarios |
| **Field Validation** | Checks input field constraints and formatting |
| **End to End** | Validates complete user workflows |
| **Boundary Value** | Tests at the limits of acceptable input ranges |
**Optional configuration:**
| Option | Description |
| --------------------- | -------------------------------------------------------------------------------------------------------- |
| **Create Test Suite** | Automatically create a test suite containing the imported test cases. Enter a suite name. |
| **Create Test Plan** | Create a test plan for the imported cases. Enter a plan name. Automatically enables test suite creation. |
| **Execute Test Plan** | Run the test plan immediately after import. Available when Create Test Plan is enabled. |
**Context fields (optional):**
Before uploading files, you can provide additional context to improve AI test generation:
| Field | Description |
| -------------------------- | -------------------------------------------------------------------------------------------------- |
| **Name** | A descriptive name for the requirement (e.g., "Login flow requirements") |
| **Additional information** | Goals, notes, or context about the requirements that help the AI generate more accurate test cases |
**File upload — Import Test Cases mode:**
Upload `.xlsx` or `.xls` files. A **Download Sample Format** link is available to get the expected spreadsheet structure.
**File upload — Import Requirements mode:**
You can upload up to **10 files** per upload. Accepted file types depend on the target platform:
Accepted file types depend on the target platform:
* **Web / Mobile:** documents (`.xlsx`, `.xls`, `.docx`, `.csv`, `.txt`, `.pdf`), image files (`.png`, `.jpg`, `.jpeg`, `.webp`, `.gif`), or video files (`.mp4`, `.mov`, `.webm`, `.mpeg`, `.mkv`)
* **API:** `.json` files
{% hint style="info" %}
Attach UI mockups, screenshots, wireframes, or screen-flow documents along with your requirements. Visual context helps the AI generate more relevant and complete test cases.
{% endhint %}
When uploading requirements, the import follows a guided multi-step flow:
1. **Inputs** — Upload your files, add context, and configure platform, publish mode, and optional settings
2. **Analysis** — ContextQA analyzes the uploaded documents and extracts testable requirements
3. **Clarifications** — The AI may ask follow-up questions about ambiguous requirements. Answer them to improve test case accuracy.
4. **Generate** — Test cases are generated from the analyzed requirements
5. **Review** — Review the generated test cases before saving
{% hint style="info" %}
The Import Test Cases mode uses a shorter flow: **Inputs** → **Generate** → **Review**.
{% endhint %}
**Import from Jira mode:**
When you select **Import from Jira**, the flow adds a Jira ticket picker step:
1. **Inputs** — Configure platform, publish mode, context fields, and optional settings, then click **Continue to Jira Tickets**
2. **Pick Jira Tickets** — Search for tickets by key (e.g., `PROJ-123`) or text, browse results with infinite scroll, and select one or more tickets. Enable **Include linked tickets** to automatically pull in sub-tasks and epic children (up to 50 linked tickets). Click **Continue to Review** when your selection is complete.
3. **Analysis** — ContextQA reads the selected ticket descriptions, acceptance criteria, and linked content to extract testable requirements
4. **Clarifications** — Answer any AI follow-up questions
5. **Generate** — Test cases are generated from the Jira ticket content
6. **Review** — Review the generated test cases before saving
**Figma integration:**
When the Figma feature is enabled, select **Figma** as the source instead of file upload. Enter a Figma file URL (matching the pattern `https://www.figma.com/file/...`, `https://www.figma.com/proto/...`, or `https://www.figma.com/design/...`).
Click **Create Test Cases** to start the generation process.
{% hint style="info" %}
When importing requirements, the AI may ask clarification questions before generating test cases. After generation, you can review AI analysis, coverage gaps, and metadata from the **Requirements Details** page. See [Requirements Management](/web-testing/requirements-management) for the full workflow.
{% endhint %}
**Best for:** Migrating existing test libraries, generating tests from requirements documents, importing from Jira tickets, creating tests from design files
[Watch the Excel test-case import walkthrough](https://drive.google.com/file/d/1sP-9thppLX1NcEb5tI5471jaICkfMoqI/preview) or the [requirements-to-tests walkthrough](https://drive.google.com/file/d/1JtdXOKBYGoQiGa4woSapLiVOge0vrlyS/preview).
{% endtab %}
{% tab title="Record & Play" %}
### Browser recording
Record your actions in the browser while ContextQA captures each interaction as a test step.
{% hint style="warning" %}
This method requires the **ContextQA Recorder** Chrome extension. If the extension is not detected, the panel displays installation instructions with a link to the Chrome Web Store.
{% endhint %}
**When the extension is installed:**
| Field | Required | Description |
| ----------------- | -------- | ---------------------------------------------------------------------------- |
| **Prerequisites** | No | Select existing test cases to run before this test |
| **URL** | Yes | The starting URL for recording. Shows your open browser tabs as suggestions. |
Click **Create Test Case** to start recording. ContextQA opens the target URL with the recorder active. Navigate and interact with your application normally — the recorder captures each click, text entry, and navigation as a step. Click **Stop Recording** to finalize.
**When the extension is not installed:**
1. Click the link to install the **ContextQA Recorder** from the Chrome Web Store
2. Enable the extension in incognito mode
3. Close and reopen the creation panel
**Best for:** UI exploration, click-heavy workflows, onboarding flows
[Watch the Record & Play walkthrough](https://drive.google.com/file/d/13Gab4J-oTb7XZVNxAZJNpDvXme-nE-iX/preview).
{% endtab %}
{% tab title="Manual Creation" %}
### Manual test case creation
Create a case directly in the dialog, then define its steps in the full builder.
1. Select **Create manually** at step 1.
2. Select **Open step builder** at step 2.
3. At step 3, enter the required **Name**.
4. Optionally set **Priority**, **Type**, **Status**, **Prerequisites**, **Labels**, advanced options, and **Description**.
5. Select **Create Test Case**.
6. Confirm the editor opens and the **Test Case created successfully** notification appears.
**Form fields:**
| Field | Required | Description |
| -------------------- | -------- | ---------------------------------------------------------------------- |
| **Name** | Yes | Descriptive test case name |
| **Priority** | No | Select from available priority levels |
| **Type** | No | Select the test case type |
| **Status** | No | Draft, Ready, In Review, Approved, Obsolete, or Rework. Default: Ready |
| **Prerequisites** | No | Select existing test cases to run before this test |
| **Labels** | No | Add labels for organization and filtering |
| **Testcase Timeout** | No | Maximum execution time in minutes (1–40). Default: 20 |
| **Description** | No | Rich text description of the test case |
**Test data options:**
| Field | Description |
| ----------------------- | -------------------------------------------------------------------------- |
| **Test Data Profile** | Select a data profile for parameterized testing |
| **Data Driven** | Enable to run the test across multiple data sets from the selected profile |
| **Data Set** | When not data-driven, select a specific data set from the profile |
| **Iteration From / To** | When data-driven, define the range of data set iterations |
**Additional toggles:**
| Toggle | Description |
| ----------------------------- | --------------------------------------------------- |
| **Mobile Testing** | Switch the test case type from web to mobile |
| **Extension Used** | Mark whether the ContextQA Chrome extension is used |
| **Avoid auto wait for steps** | Disable automatic wait insertion between steps |
Select **Show Advanced Options** to review additional execution settings when needed. Select **Create Test Case** to save the case and open its details page.
**Best for:** Precise control over test metadata, data-driven testing configuration, complex assertions
{% endtab %}
{% endtabs %}
## Verify a manually created test case
After creation, confirm that the details page shows the new name and the **Test Steps**, **Relationships**, and **Version History** tabs. The side panel should show **Test Case**, **Variables**, **Used in Test**, and **Run History**. Return to **Test Cases** and search by the new title or assigned `TC-` identifier to verify list placement.
### Verify the test from the list
1. Return to **Test Cases**.
2. Enter the test's `TC-` identifier or a distinctive part of its title in **Search by ID or Title**.
3. Confirm that the row shows the expected **Type**, **Priority**, **Result**, **Status**, and **Labels**.
4. Switch between **List** and **Modular** view when you need a different way to browse the collection.
5. Use **Filter** to narrow a large test library instead of relying on naming alone.
{% hint style="success" %}
A successful creation is not complete verification. Run the saved test once and review its steps, console, network activity, screenshot, video, and trace before promoting it into a shared suite.
{% endhint %}
### Run a documentation-safe verification
When the test exists only to produce product documentation evidence, keep it separate from valuable regression tests:
1. Prefix the title with `DOC-` and include the feature and expected outcome—for example, `DOC — Test Cases — Open list and verify controls`.
2. Use fictional data and a non-production environment.
3. Reuse a stable login prerequisite instead of copying credentials into steps.
4. Add a viewport-safe verification that names only controls visible together on the page.
5. Run the test and wait for a final passed or failed status.
6. Open **View Run Results** and review all evidence before using it in documentation.
7. Record the test ID and run ID in the documentation task.
8. Delete the disposable test from the active list after the evidence is approved. Do not edit or delete the source regression test when you created the documentation test by duplication.
For every capability on the live execution and completed result screens, see [Execution and test results](/reporting/test-results).
***
## Mobile platform selection
When you select **Mobile** as the target platform (from the AI Assistance or Import Files tabs), a mobile device setup screen appears before starting execution.
**Concurrency indicators** appear in the header showing parallel execution slots and queue status.
| Field | Required | Description |
| ------------------------ | -------- | ------------------------------------------------------------------------------------------------------ |
| **Select Platform** | Yes | Choose **iOS** (IPA) or **Android** (APK) |
| **Select Device** | Yes | Pick a device from the available device pool (options load based on selected platform) |
| **App Build** | Yes | Select the app build to test. If no builds are found, click **Go to Upload Page** to upload one first. |
| **Desired Capabilities** | No | Review and edit key-value capability pairs. Some fields (like `app_url` and `os_type`) are read-only. |
Click **Start Execution** to launch the mobile test. If maximum concurrency is reached, ContextQA queues the test and you can click **Skip and continue** to close the dialog while the test waits in the queue.
For more details on mobile test setup, see the [Mobile Testing](/mobile-testing/mobile-testing) section.
***
## Verifying generated test cases
After AI generates test cases (from the AI Assistance or Import Files methods), a verification screen displays the results.
Each generated test case shows:
* **Title** with an internal ID badge (e.g., `TC-1`)
* **Description** of the test scenario
* **Steps** with detailed actions
* **Expected Result** for the test case
* **Source badges** indicating where the test case was derived from
**Actions available:**
* Click **Save** on an individual test case to save it to your project
* Click **Save All Test Cases** to save all generated test cases at once
* Click **Cancel** to discard the generated test cases
If any test cases were skipped during generation, a **Skipped Test Cases** section appears with the reason each case was skipped.
***
## Frequently asked questions
How long does it take to create a test case?
Creation time varies with workflow complexity, the selected authoring method, and the application under test. Review every generated or recorded step before publishing the test case.
Can I import existing test cases from spreadsheets?
Yes. Select **Import Files** in the creation dialog, choose **Import Test Cases** mode, and upload an `.xlsx` or `.xls` file. Download the sample format to see the expected column structure. ContextQA maps your spreadsheet columns to test case fields automatically.
What browsers and devices are supported?
ContextQA supports all major browsers for test execution:
* **Chrome** (desktop + headless)
* **Firefox**
* **Safari** (macOS)
* **Edge**
* **Mobile Chrome / Safari** (via device emulation)
For real-device mobile testing, see the [Mobile Testing](/mobile-testing/mobile-testing) section.
Are screenshots and videos stored automatically?
ContextQA can attach screenshots, video, and trace evidence to a run result when recording is enabled and the execution type supports those artifacts. Open the completed result and check the **Screenshots**, **Video**, and **Trace** tabs before relying on the evidence. Availability and retention can depend on workspace configuration, permissions, and policy.
Can I run the same test case across multiple environments?
Yes. ContextQA supports environment-based test execution. You can define multiple environments (Development, Staging, Production) and run any test case against any environment by selecting it at execution time. Environment-specific variables (base URLs, credentials, API keys) are managed separately so your test cases remain portable.
How does self-healing work if my application changes?
ContextQA's AI Configuration (self-healing) continuously monitors element locators. When an element changes — for example, a button moves or an ID changes — the AI automatically finds the updated element using visual context, text content, and semantic analysis. The system flags failed locators for review and heals them with one click. See [Self-Healing Tests](/web-testing/self-healing) for configuration details.
What are the AI Smartness modes?
AI Smartness controls how the AI generates test steps:
* **Expert** — The AI takes more time to analyze the application and produces thorough, detailed steps
* **Fast** — The AI prioritizes speed and generates steps quickly with less analysis
* **Strict** — The AI follows your description exactly with minimal interpretation
* **Organization Default** — Uses the AI Smartness setting configured by your organization administrator
What is the difference between Auto Publish and Required Approval?
When importing test cases via the **Import Files** method, you can choose a publish mode:
* **Auto Publish** saves and publishes generated test cases immediately — they are ready to run right away.
* **Required Approval** saves generated test cases in a pending state. A team member must review and approve each test case before it becomes available for execution. This is useful for teams that require peer review of test content.
***
## Best practices
{% hint style="success" %}
**Name tests descriptively** — Use the format `[Page] - [Action] - [Expected Result]` (e.g., `Login Page - Valid Credentials - Dashboard Loads`). This makes test results immediately understandable.
{% endhint %}
{% hint style="info" %}
**Start with happy-path tests** — Create and validate your positive test cases first, then add negative scenarios (invalid inputs, error states) once the base flow is verified.
{% endhint %}
{% hint style="warning" %}
**Avoid hard-coded waits** — Don't use `Wait 5 seconds` steps. Instead, use `Wait for element` or `Wait for network idle` actions. ContextQA's AI handles timing automatically.
{% endhint %}
***
## Related documentation
* [Requirements Management](/web-testing/requirements-management) — Upload requirements, review AI analysis, and track coverage gaps
* [Debugging Test Cases](/web-testing/debugging-test-cases) — Step through execution with breakpoints and live variables
* [Test Steps Editor](/web-testing/test-steps-editor) — Detailed guide to all available step actions
* [Version History](/web-testing/version-history) — Track, compare, and restore previous test case versions
* [Managing Test Suites](/web-testing/managing-test-suites) — Organize test cases into suites for batch execution
* [Self-Healing Tests](/web-testing/self-healing) — AI-powered test maintenance
* [Test Data Management](/web-testing/test-data-management) — Variables, CSV imports, and data-driven testing
* [AI Test Generation](/ai-features/ai-test-generation) — All 10 AI test generation methods
* [Mobile Testing](/mobile-testing/mobile-testing) — Mobile test creation and execution
* [Execution & Reporting](/execution/execution) — Run tests, view results, set up CI/CD
* [Execution and Test Results](/reporting/test-results) — Monitor a live run and inspect steps, logs, screenshots, video, and trace evidence
***
{% hint style="info" %}
**Ready to create your first test?**
[Open ContextQA Platform](https://app.contextqa.com) · [View Test Steps Reference](/web-testing/test-steps-editor) · [Book a Demo](https://contextqa.com/book-a-demo/)
{% endhint %}
# Managing Test Cases
Inspect, bulk-update, edit, duplicate, trash, restore, or permanently delete ContextQA test cases with safeguards.
## Quick answer
Open **Test Cases** to search and filter coverage, select cases for a bulk **Change Status**, or open one case to review its steps, variables, relationships, run history, and **Created by** owner. Use **Duplicate** for a safe starting copy and **Delete** for recoverable Trash. **Delete Forever** is available only from Trash and permanently removes the case and its run history.
You manage a ContextQA test case from its details page. Open a case to inspect its steps and metadata, update it, make a copy, or move it to Trash. Use these procedures when maintaining automated coverage after requirements or application behavior change.
## Prerequisites
* You can access the appropriate workspace and workspace version.
* Your role includes the action you intend to perform. A missing or disabled control can indicate a permission or feature restriction.
* For destructive testing, use a disposable case whose name clearly identifies it, such as `DOCS-DELETE-ME — Temporary deletion example`.
## Open and inspect a test case
1. Select **Test Cases** in the left navigation.
2. In the **Test Cases** list, locate the case by its `TC-` identifier or title.
3. Select the test case row or title.
4. Review **Test Steps**, **Relationships**, or **Version History**.
5. In the side panel, review **Test Case**, **Variables**, **Used in Test**, and **Run History**.
The details page shows the case name, status, priority, **Created by**, creation date, environment, version, platform, description, and execution and AI configuration. Use **Created by** to identify the owner to contact before changing or retiring shared coverage.
## Edit test case metadata
1. Open the test case.
2. Select **Edit** in the **Description** section.
3. Update the description, **Status**, **Priority**, **Type**, or labels.
4. Update execution, AI, wait and retry, device, or key-flag settings only when the test requires them.
5. Select **Save Changes**.
6. Confirm the new values appear in the **Test Case** panel.
ContextQA enables **Save Changes** after a value changes. Select **Cancel** to discard changes made in the edit form.
## Change the status of multiple test cases
1. In **Test Cases**, search or filter until the intended cases are visible.
2. Select the cases with their row checkboxes. Use the header checkbox only after confirming the current filtered scope.
3. Select **Change Status** from the bulk toolbar.
4. Choose the new lifecycle status and confirm the update.
5. Refresh or reopen the list and verify the selected rows show the new status.
Bulk status changes affect shared coverage. Review the **Created by** owner and suite relationships before changing cases you do not own.
## Rename a test case
1. Open the test case.
2. Select the edit icon beside the test case name.
3. Enter the new name.
4. Confirm the change using the control shown by the inline editor.
5. Verify the new name appears in the header and in the **Test Cases** list.
Use names that describe one observable outcome, for example `Authentication — Sign in — Invalid password`.
## Edit test steps
Use the **Test Steps** tab to add, edit, reorder, or remove actions and assertions. Verify the final sequence and review **Version History** after saving. For field-level instructions, see [Edit test steps](/web-testing/test-steps-editor).
## Duplicate a test case
1. Open the source test case.
2. Open the three-dot actions menu in the header.
3. Select **Duplicate**.
4. In **Copy Test Case**, leave **Test Case** selected.
5. Replace the default `copy of (...)` name with a name that describes the new behavior.
6. Select **Create**.
7. Confirm the copied case opens and a **Test Case copied successfully** notification appears.
The same dialog can copy the content as a **Step Group**. Use that option only when the copied steps are a reusable sequence rather than an independently executable scenario.
## Move a test case to Trash
Deleting a test case first moves it to Trash. This operation is recoverable.
1. Confirm that you opened the intended case. For research or cleanup, confirm its name includes `DOCS-DELETE-ME`.
2. Open the three-dot actions menu.
3. Select **Delete**.
4. In **Delete Test Case**, review the test case name and the message that the case can be restored from Trash.
5. Select **Yes, Delete**.
6. Confirm the **Test Case deleted successfully** notification appears.
## Restore a deleted test case
In **Trash (Deleted Test Cases)**, each row's **More actions** menu shows **View**, **Restore**, and **Delete**. Restore a case directly from its row, or from the read-only trashed case page.
### Restore from the case row
1. Select **Test Cases** in the left navigation.
2. Open the **All Test Cases** selector and select **Trash (Deleted Test Cases)**.
3. Locate the deleted case and open its **More actions** menu.
4. Select **Restore**.
5. Confirm the **Test Case restored successfully** notification appears.
6. Return to **All Test Cases** and verify the case is present and editable.
### Restore from the trashed case page
1. In **Trash (Deleted Test Cases)**, open the case's **More actions** menu and select **View**.
2. On the read-only **Trashed Test Case** page, select **Restore**.
3. Return to **All Test Cases** and verify the case is present and editable.
## Permanently delete a test case
{% hint style="danger" %}
**Delete Forever cannot be undone.** ContextQA warns that all run reports and run configuration associated with the test case will be lost.
{% endhint %}
1. Open **Test Cases** and select **Trash (Deleted Test Cases)**.
2. Open the trashed test case with **More actions** > **View**.
3. Confirm that the page identifies it as the exact disposable case you intend to remove.
4. Select **Delete Forever**.
5. In **Delete Test Case**, review the permanent-deletion warning.
6. Enter `delete` in **Type 'delete' to confirm**.
7. Select **Yes, Delete**.
8. Verify the case no longer appears in Trash.
## Practical example
Suppose `Authentication — Sign in — Valid credentials` needs an invalid-password variant. Duplicate the case, rename the copy `Authentication — Sign in — Invalid password`, replace the success assertion with an error-message assertion, and save. If the copy is not needed, move only the copy to Trash; keep the original and its run history intact.
## Troubleshooting
| Problem | Likely cause | Resolution |
| ---------------------------------------- | ----------------------------------------------------- | -------------------------------------------------------------------- |
| **Save Changes** is disabled | No editable value has changed | Change a field, or select **Cancel** to leave edit mode. |
| A trashed case cannot be edited | Trashed cases are read-only | Select **Restore**, then edit the active case. |
| The case is missing from the active list | It may be in Trash or hidden by search/filter state | Clear search and filters, then check **Trash (Deleted Test Cases)**. |
| **Delete Forever** is disabled | The confirmation text is missing or incorrect | Enter the lowercase word `delete` exactly. |
| An action is missing or disabled | Your role or workspace configuration may not allow it | Ask a workspace administrator to confirm your permissions. |
## Limitations and permissions
* The current UI exposes **Duplicate**, **Delete**, **Restore**, and **Delete Forever**. It does not expose a separate **Archive** action on the tested case.
* A trashed test case is read-only until restored.
* Permanent deletion removes run reports and run configuration and has no undo action.
* Permission differences were not safely testable with the available administrator session; do not infer access from role names alone.
## Related documentation
* [Create test cases](/web-testing/creating-test-cases)
* [Find and organize test cases](/web-testing/finding-and-organizing-test-cases)
* [Edit test steps](/web-testing/test-steps-editor)
* [Manage test suites](/web-testing/managing-test-suites)
## Frequently asked questions
### Does ContextQA save test case metadata automatically?
No. In the verified metadata editor, you select **Save Changes**. The button becomes available after a value changes.
### Can I restore a deleted test case?
Yes. A normal **Delete** moves the case to **Trash (Deleted Test Cases)**, where you can select **Restore** directly from the case row's **More actions** menu or from its read-only page.
### What happens when I permanently delete a test case?
ContextQA removes the case and warns that its run reports and run configuration will be lost. The action cannot be undone.
# Finding and Organizing Test Cases
Find ContextQA test cases by ID, title, requirement, result, or creator; organize them with folders and labels; and change status in bulk.
## Quick answer
Open **Test Cases** to search by test ID or title, or use **Filter** for creator, lifecycle status, type, priority, completed run result, dates, labels, and linked requirements. Use **Modular** view for folders and **List** view for sorting and comparison. To move a review batch to the same lifecycle stage, select its rows, choose **Change Status**, select the new status, and submit.
The ContextQA **Test Cases** page is the searchable inventory for test cases and reusable step groups. Use it to locate coverage, inspect lifecycle state, organize cases with folders and labels, and select cases for list actions.
## Navigate to the test case list
1. Sign in to the required ContextQA workspace.
2. Confirm the intended workspace and version are active.
3. Select **Test Cases** in the left navigation.
4. Confirm the page heading is **Test Cases** and the subtitle reads **Manage and Execute all your Test Cases**.
Use the **Test Cases** and **Step Groups** tabs to switch between executable cases and reusable step sequences.
## Understand the list
The default **List** view contains these verified columns:
| Column | What it shows |
| -------------- | ------------------------------------------------------------------------ |
| **Test Cases** | Generated `TC-` identifier and title |
| **Type** | Platform, such as Browser or Mobile |
| **Priority** | Assigned priority or Unassigned |
| **Result** | Latest observed result, such as Passed, Failed, Aborted, or Not Executed |
| **Status** | Lifecycle status, such as Ready or In Review |
| **Labels** | Assigned labels or No labels |
| **Created By** | Creator or System |
| **Folder** | Folder name or Unorganized |
| **Created At** | Creation timestamp |
| **Updated At** | Last update timestamp |
| **Last Run** | Last run timestamp or `-` |
| **Action** | Row-level **More actions** menu |
The header also includes **Search**, **Export**, the active/trash selector, **Filter**, column settings, refresh, **New Test Case**, and **List**/**Modular** view controls.
## Search for a test case
1. In **Search by ID or Title**, enter a complete or partial `TC-` identifier or title.
2. Review the matching rows and result count.
3. Open the required case from the result list.
4. Clear the search value to return to the full list.
The placeholder explicitly limits the verified search scope to ID or title. Do not rely on this control to search descriptions or steps.
## Filter test cases
1. Select **Filter**.
2. Choose one or more available criteria: **Created By**, **Status**, **Test Type**, **Type**, **Priority**, **Latest Run Result**, **Created Date**, **Updated Date**, **Labels**, or **Requirements**.
3. Select **Apply Filter**.
4. Confirm the returned rows satisfy every visible criterion.
5. Clear the applied filter state before concluding that a case is missing.
An empty filtered result means no visible cases match the current criteria; it does not mean the cases were deleted.
The **Latest Run Result** filter contains completed outcomes: **Passed**, **Failed**, **Aborted**, and **Not Executed**. **Queued** and **Stopped** are not offered because they describe interrupted or in-flight execution rather than a settled test result.
### Filter by requirement
The **Requirements** filter narrows the list to test cases linked to specific requirement files. It appears on the **Test Cases** tab only, not on **Step Groups**.
1. Select **Filter**, then open the **Requirements** filter.
2. In **Select requirement files**, search for a requirement, then select one or more entries. Each entry is labeled by its requirement ID and name, such as `REQ-42: Checkout flow`. A requirement with no name still appears as its ID alone, such as `REQ-42`, so you can always select it.
3. Select **Apply Filter**.
To create requirement files and link them to test cases, see [Requirements management](/web-testing/requirements-management).
## Sort the list
Select a sortable column heading to change its order. The verified sortable headings are **Test Cases**, **Priority**, **Created By**, **Folder**, **Created At**, **Updated At**, and **Last Run**. Select the same heading again to reverse the direction, then verify the first rows follow the selected order.
## Move between result pages
1. At the bottom of the table, open **Rows per page** to choose how many cases appear.
2. Review the displayed range and total, for example `1–10 of 7172`.
3. Use the next or previous page controls.
4. Confirm that the displayed range and rows change.
## Select test cases
Use **Select row** to select one case or **Select all rows** to select the rows available to the table selection control. The bulk-action toolbar appears after you select at least one row.
### Change the status of several test cases
1. Select the required test case rows.
2. In the bulk-action toolbar, select **Change Status**.
3. Choose **Draft**, **In Review**, **Ready**, **Obsolete**, **Rework**, or **Approved**.
4. Select **Submit**.
5. Confirm the updated status appears on every selected case.
Use bulk status changes when a review batch moves to the same lifecycle stage. Review the selection count before submitting; the change applies to every selected case, including selections retained across result pages.
Other bulk actions can include moving cases, editing fields, adding labels, exporting, or deleting, depending on the current view and permissions. Review the displayed action and selection count before proceeding, and use disposable cases when validating a destructive action.
## Use List and Modular views
* **List** presents sortable metadata in a table and is best for search, status review, and comparison.
* **Modular** presents folder-based organization and is best when browsing the functional structure.
The list shows **Unorganized** when a test case has no folder assignment.
## Create a test case folder
Folder creation is available in **Modular** view. If you are in **List** view, switch views before looking for the folder action.
1. Open **Test Cases** and select the **Test Cases** tab.
2. Select **Modular**.
3. In the **Folders** panel, select the **+** (**New folder**) action.
4. Enter a folder name. If needed, choose a parent folder and color.
5. Select **Create folder**.
ContextQA selects the new folder after creating it. To organize existing cases, select the cases, choose **Move to Folder**, select the destination, and confirm the move. Moving a case changes its location; it does not delete or duplicate the case.

## Organize cases with folders and labels
Folders provide the primary visible hierarchy in the test case inventory. Labels provide cross-cutting classification and filtering.
* Use a folder for a stable functional area, such as `Authentication` or `Checkout`.
* Use labels for attributes that can span folders, such as `Smoke`, `Security`, or `Integration`.
* Use **Status** for workflow state, not functional grouping.
* Use **Priority** for business or failure impact, not test type.
A case can display a folder and multiple labels in the list. The current list also supports **Unorganized** for cases without a folder.
## Test case, step group, test suite, and test plan
| Object | Use it for |
| ---------- | ---------------------------------------------------------------------- |
| Test case | One independently maintainable scenario and expected outcome |
| Step group | A reusable sequence, such as shared sign-in setup |
| Folder | Navigating a functional hierarchy in the test inventory |
| Label | Filtering cases across folders by a shared attribute |
| Test suite | Grouping cases that should be managed or executed together |
| Test plan | Defining an execution strategy and configuration for selected coverage |
Do not duplicate a test case only to place the same behavior in another execution grouping. Reuse the case through the supported suite or plan relationship instead.
## Practical authentication example
Create these cases using the naming pattern `[Area] — [User action] — [Expected outcome]`:
* `Authentication — Sign in — Valid credentials`
* `Authentication — Sign in — Invalid password`
* `Authentication — Reset password — Registered email`
For each case, use a fictional test account and add steps that navigate to the sign-in page, perform the named action, and verify the observable result. Place the cases in the `Authentication` folder if that folder exists, and apply `Smoke` only to the minimum release-blocking path. Add the related cases to an authentication suite when they should execute together; configure execution in a test plan rather than encoding browser or environment names in each case title.
To verify the organization, search for `Authentication`, filter by the chosen label, open each case to confirm its steps, and inspect its relationships. A common mistake is using `Ready` as a functional category; correct it by using a folder or label and reserve **Status** for review state.
## Organization guidelines for large teams
* Name cases after observable behavior and keep one primary outcome per case.
* Search before creating a case to avoid duplicate coverage.
* Use a step group for genuinely reusable setup.
* Keep volatile environment details out of names; use execution configuration.
* Create a new suite only for a meaningful reusable grouping.
* Create a new plan only when the execution selection or configuration differs.
* Move obsolete cases to Trash only after reviewing relationships and history; permanently delete only when retention is not required.
## Troubleshooting
| Problem | Likely cause | Resolution |
| ---------------------------- | ---------------------------------------------------------------------- | ------------------------------------------------------------------------------------------- |
| Search returns no rows | The text is not in the ID or title | Search with a shorter title fragment or the `TC-` identifier. |
| An expected case is missing | Search, filters, pagination, workspace/version, or Trash state differs | Clear search and filters, check the workspace/version and result pages, then inspect Trash. |
| A case shows **Unorganized** | No folder is assigned | Assign the case to the appropriate functional folder if your process uses folders. |
| A sort appears ineffective | Values on the current page are identical or blank | Check the sort indicator and compare a column with distinct values. |
## Limitations and permissions
* Search was verified for the UI contract **Search by ID or Title**; description and step search were not verified.
* Saved views and reusable saved filters were not present in the tested list.
* A separate archive lifecycle was not present; the verified lifecycle uses Trash, Restore, and Delete Forever.
* Available bulk actions and selection limits can vary by view and permission. **Change Status** is available on the active Test Cases list.
* Permission differences were not verified across multiple roles.
## Related documentation
* [Create test cases](/web-testing/creating-test-cases)
* [Manage test cases](/web-testing/managing-test-cases)
* [Manage test suites](/web-testing/managing-test-suites)
* [Create and run test plans](/web-testing/test-plans)
* [Reuse steps with step groups](/web-testing/step-groups-tutorial)
## Frequently asked questions
### How do I find a test case in ContextQA?
Open **Test Cases** and search by its `TC-` identifier or title. Clear filters and check Trash if it is not in the active results.
### What is the difference between a folder and a label?
A folder provides a navigable functional location; a label provides a cross-cutting filter that can classify cases from different folders.
### Does ContextQA support archive?
No separate **Archive** action was present in the verified test case UI. Use recoverable Trash for removal, and reserve **Delete Forever** for irreversible cleanup.
# Tutorial: Record Your First Test
Install the ContextQA Recorder, capture a real browser workflow as test steps, and run the recorded test — building a complete web test case without writing code or describing a single step.
## Quick answer
Install the ContextQA Recorder, capture a real browser workflow as test steps, and run the recorded test — building a complete web test case without writing code or describing a single step. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** New users and testers who want to create their first web test by clicking through their application. You install the ContextQA Recorder, record a live browser workflow, and run the test — no code and no written steps required.
{% endhint %}
Recording is the fastest way to turn an existing workflow into an automated test. You interact with your application the way a user would — signing in, navigating, filling forms — and the ContextQA Recorder captures every click, text entry, and navigation as an editable test step. This is ideal for click-heavy flows where describing each step would take longer than performing it.
In this tutorial you will:
1. Install the ContextQA Recorder Chrome extension
2. Start a recording session against a live URL
3. Capture a real workflow as test steps
4. Save the recorded test and run it
**End result:** A complete web test case, built entirely from your recorded browser actions, that runs against a real browser and captures screenshots, video, and network logs on every execution.
[Watch the Record & Play walkthrough](https://drive.google.com/file/d/13Gab4J-oTb7XZVNxAZJNpDvXme-nE-iX/preview).
## Prerequisites
* A ContextQA account with at least one workspace ([sign up](https://accounts.contextqa.com/onboard))
* A plan with the Record & Play feature enabled (recording requires a paid plan)
* Google Chrome or Microsoft Edge
* The URL of a web application you can interact with, and one workflow to record (for example, signing in or running a search)
* Familiarity with [core concepts](/getting-started/core-concepts) — specifically test cases and steps
{% hint style="info" %}
Recording works for **web** applications only. To automate mobile apps, see [Creating mobile tests](/mobile-testing/creating-mobile-tests). To create web tests by describing them in plain English instead, see the [Quickstart guide](/getting-started/quickstart).
{% endhint %}
***
## Step 1: Install the ContextQA Recorder
The recorder runs as a Chrome extension that captures your browser actions and streams them into ContextQA as test steps.
1. In the left sidebar, select **Test Cases**.
2. Click the **+** button and select **Record & Play**.
3. If the extension is not installed, the panel shows a **ContextQA Chrome Extension Required** card. Click **Install ContextQA Extension** to open the [ContextQA Test Automation extension](https://chromewebstore.google.com/detail/context-qa/akmoahgeffemjioncblbogjnmjeeiplg) in the Chrome Web Store.
4. On the Chrome Web Store page, click **Add to Chrome**, then confirm the installation.
5. Enable the extension in incognito mode so it can capture actions in private windows. Open `chrome://extensions`, find **ContextQA Test Automation**, click **Details**, and turn on **Allow in Incognito**.
6. Return to ContextQA and select **I already have the extension installed →** to recheck for the extension.
**Verify it worked:** The Record & Play panel shows a green **ContextQA Extension detected** banner with the message "You're ready to start recording test actions." If you still see the installation card, close and reopen the creation panel to trigger a fresh detection.
{% hint style="info" %}
The extension is free, installs in seconds, and works with both Chrome and Microsoft Edge (Edge uses the same Chrome Web Store listing).
{% endhint %}
***
## Step 2: Configure the recording session
With the extension detected, tell ContextQA which page to open and what must happen before recording starts.
1. In the **Target URL** field, enter the starting URL for your workflow. For example:
```
https://app.example.com/login
```
2. (Optional) Under **Prerequisites**, select one or more existing test cases that must run before this one — for example, a test that puts the application into a logged-in state. Leave this empty if your recording starts from a clean session.
3. Review the **What happens next** note. It confirms that clicking **Start Recording** opens your URL in a new tab with the recorder active.
**Verify it worked:** The **Target URL** field shows a valid URL with no error message, and the **Start Recording** button is enabled. If the button stays disabled, check that the URL starts with `http://` or `https://`.
***
## Step 3: Record your workflow
Now capture the actual workflow. Every interaction you perform in the new tab becomes a test step.
1. Click **Start Recording**. ContextQA opens your target URL in a new browser tab with the recorder active.
2. Interact with your application exactly as a user would. For a login flow, for example:
* Enter an email address in the email field.
* Enter a password in the password field.
* Click the **Sign in** button.
* Wait for the dashboard or landing page to load.
3. Continue through the rest of the workflow you want to test. The recorder captures each click, text entry, and navigation as a discrete step in real time.
4. When you finish the workflow, click the **ContextQA Recorder** icon in your browser toolbar and select **Stop** to end the session and save.
**Verify it worked:** ContextQA closes the recording tab and returns you to the test case, where each action you performed appears as a numbered step in the [Test Steps Editor](/web-testing/test-steps-editor).
The recorder saves browser interactions and element metadata as editable steps. It does not execute those saved steps or prove that they are repeatable; that happens later when the ContextQA runner starts a managed browser session and plays the test.
{% hint style="warning" %}
**Record deliberate actions.** The recorder captures everything you do, including accidental clicks and dead-end navigations. Move through the workflow at a steady pace and avoid clicking outside your intended flow. You can delete or reorder any captured step afterward in the Test Steps Editor.
{% endhint %}
***
## Step 4: Review, name, and run the test
Recorded steps are ordinary ContextQA steps — you can edit them, add assertions, and run the test like any other.
1. Give the test case a descriptive name, such as `Sign in — recorded`.
2. Review the captured steps in order. Each step shows the action performed and the element it targeted.
3. Add a verification step to confirm the workflow succeeded. Click **Add Step**, then describe what to check — for example, "Verify the dashboard heading is visible".
4. Remove any accidental steps by selecting the step and clicking the delete icon.
5. Click **Run** in the top toolbar, select an execution environment, and click **Run** again.
When execution finishes, click **View Detailed Report** to review the results.
**Verify it worked:** The execution report shows each step with a pass or fail indicator, a screenshot, and captured network and console logs. A passing run confirms your recorded workflow is now a repeatable automated test.
### Review recorded elements before relying on the test
For each important click or input step, open its edit view and inspect the selected element or locator information:
* Prefer a unique accessible label, role, field name, or stable visible text.
* Replace generated IDs, `nth-child` expressions, and long DOM-position paths when a stable alternative exists.
* Remove accidental clicks and duplicate navigation.
* Add explicit verification steps at business checkpoints; a recorded click alone does not verify its outcome.
* Run once from a clean session. If self-healing changes an element, review the evidence before treating the repair as permanent.
| Result | What it means |
| --------------------------- | ------------------------------------------------------------------------------------------------------------------- |
| All steps pass | The recorded workflow runs cleanly end to end |
| A navigation step fails | The starting URL or a link changed — update the step's target |
| A click or input step fails | The element moved or was renamed — [AI self-healing](/web-testing/self-healing) repairs most of these automatically |
***
## Summary
You built a web test case entirely from recorded browser actions:
1. **Installed the ContextQA Recorder** Chrome extension and confirmed ContextQA detected it
2. **Configured a recording session** with a target URL and optional prerequisites
3. **Recorded a live workflow**, capturing each interaction as an editable test step
4. **Named, reviewed, and ran** the test, then inspected the per-step evidence
Recording gives you a working test in the time it takes to click through a flow once — a strong starting point you can refine with assertions, data, and reusable steps.
## Next steps
* **Add assertions:** Strengthen the test by verifying outcomes at key points. See the [Test Steps Editor](/web-testing/test-steps-editor).
* **Make the test data-driven:** Run the same recorded flow across many input sets. See [Tutorial: Data-driven testing](/web-testing/data-driven-testing-tutorial).
* **Extract reusable steps:** Turn the recorded sign-in sequence into a step group you can share across tests. See [Tutorial: Creating and reusing step groups](/web-testing/step-groups-tutorial).
* **Handle tricky flows:** Configure a [knowledge base](/ai-features/knowledge-base) so the test agent can dismiss cookie banners or handle multi-factor authentication during recording and playback.
* **Run in CI/CD:** Add the test to a plan and trigger it from your pipeline. See [GitHub Actions](/integrations/github-actions).
## Related pages
* [Creating test cases](/web-testing/creating-test-cases) — all four authoring methods, including Record & Play, AI assistance, import, and manual creation
* [Test Steps Editor](/web-testing/test-steps-editor) — edit, reorder, and enrich recorded steps
* [Debugging test cases](/web-testing/debugging-test-cases) — diagnose and fix steps that fail on playback
* [AI self-healing](/web-testing/self-healing) — how ContextQA repairs recorded steps when the UI changes
* [Running tests](/execution/running-tests) — execution options for test cases, suites, and plans
{% hint style="info" %}
**Record your first test in minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see recording with your own application.
{% endhint %}
# Requirements Management
Upload requirements to ContextQA, generate and review test cases, distinguish test-data, environment, and global variables, and analyze coverage gaps.
## Quick answer
Open **Assets → Requirements → New Requirement**, choose a file, connected work tracker, or live crawl, then select **Require Approval** or **Auto Publish**. Generation continues in the background. Before publishing, review variables and use the existing-case marker to distinguish new coverage from a test already in the repository.
{% hint style="info" %}
**Who is this for?** QA engineers, testers, and product managers who want to generate test cases from requirement documents and track coverage gaps automatically.
{% endhint %}
## Overview
The **Requirements Library** is a centralized workspace where you upload requirement files, review AI-generated questionnaires, monitor test case generation, and inspect coverage gaps. Each uploaded file gets a dedicated **Requirements Details** page that keeps the source, AI interpretation, generated coverage, review decisions, and metadata together.
```mermaid
flowchart LR
A[File, work item, or live crawl] --> B[AI analysis and clarifications]
B --> C[Generate candidate test cases]
C --> D{Already in the repository?}
D -->|Yes| E[Mark the existing case and link its test ID]
D -->|No| F[Keep as new coverage]
E --> G[Reviewer checks evidence and gaps]
F --> G
G --> H{Publish mode}
H -->|Require Approval| I[Approve or reject]
H -->|Auto Publish| J[Publish to suite or plan]
```
***
## Opening the Requirements Library
{% stepper %}
{% step %}
### Navigate to test development
Open and sign in to your workspace. Select **Test Cases** from the left sidebar.
{% endstep %}
{% step %}
### Open the Requirements Library
Select **Assets → Requirements** from the left sidebar. The Requirements Library displays all uploaded requirement files in a searchable, filterable table.
{% endstep %}
{% endstepper %}
***
## Requirements Library table
The table displays one row per uploaded file with the following columns:
| Column | Description |
| ------------------ | ---------------------------------------------------------------------------------------------------------------- |
| **Name** | File name prefixed with a requirement ID (e.g., `REQ-42`). Click the name to open the Requirements Details page. |
| **Type** | File type — *Requirements* or *Test case* — with a platform icon (Web, Mobile, or API). |
| **Status** | Current processing status displayed as a colored badge. |
| **Estimated Time** | Time taken to process the file. |
| **Test Cases** | Number of generated test cases (visible when status is *Completed*). |
| **Created by** | The user who uploaded the file. |
| **Created Date** | Date and time of upload. |
**Status values:**
| Status | Meaning |
| ---------------------------- | ------------------------------------------------------------------------------------------------------ |
| **Completed** | Processing finished — test cases are ready for review. |
| **Pending action** | The AI needs clarification before generating test cases. Click the row to answer the AI questionnaire. |
| **Processing / In progress** | File is being analyzed. You can continue working — ContextQA notifies you when generation completes. |
| **Failed / Error** | Processing failed. Check the error details and re-upload if needed. |
**Table features:**
* **Search** — Filter files by name or ID.
* **Filters** — Filter by format, status, date range, or test plan.
* **Auto-refresh** — Automatically reload the table to check for status updates.
* **Upload requirement** button — Start a new upload directly from the library.
***
## Uploading a requirement file
{% stepper %}
{% step %}
### Click New Requirement
Click **New Requirement** in the Requirements Library header. The source chooser opens.
{% endstep %}
{% step %}
### Select the import mode
Choose the source that matches the requirement:
| Source | Description |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Import Test Cases** | Upload an Excel spreadsheet (`.xlsx`, `.xls`) containing test case definitions. |
| **Import Requirements** | Upload requirements documents, images, or video files to generate test cases from specifications. |
| **Generate from Integrations** | Choose a connected work tracker, then browse Jira tickets or Azure DevOps work items and generate tests from their content. During the staged rollout, some workspaces may still label the entry **Generate from Jira**. |
| **Generate from Crawl** | Give an AI agent a starting URL and goal so it can explore a live web flow and create requirement-backed tests. |
| {% endstep %} | |
{% step %}
### Select the target platform
| Platform | Available in |
| ------------------- | ---------------------------- |
| **Web Application** | Both modes |
| **Mobile** | Both modes |
| **API** | Import Requirement mode only |
| {% endstep %} | |
{% step %}
### Upload your files
Drag and drop or click to browse. You can upload up to **10 files** per upload in Import Requirements mode. Accepted file types depend on the mode and platform:
| Mode | Platform | Accepted formats |
| ------------------- | ------------ | --------------------------------------------------------------------------------------------------------------------------------------- |
| Import Test Cases | All | `.xlsx`, `.xls` |
| Import Requirements | Web / Mobile | `.csv`, `.txt`, `.xlsx`, `.docx`, `.pdf`, image (`.png`, `.jpg`, `.jpeg`, `.webp`), or video (`.mp4`, `.mov`, `.webm`, `.mpeg`, `.mkv`) |
| Import Requirements | API | `.json`, including a valid Swagger or OpenAPI JSON document |
{% hint style="warning" %}
Document and image files have a maximum size of **100 MB** each. Video files have a maximum size of **500 MB** and a maximum duration of **30 minutes** — only one video per upload.
{% endhint %}
After selecting files, each file appears in the **Inputs Attached** list below the drop zone. Expand any file card to add **Additional information** describing what the file contains or how it should be used. Click the delete icon on a file card to remove it before uploading.
Optionally, fill in the **Name** and **Additional information** fields above the drop zone to provide overall context for the requirement set.
{% endstep %}
{% step %} 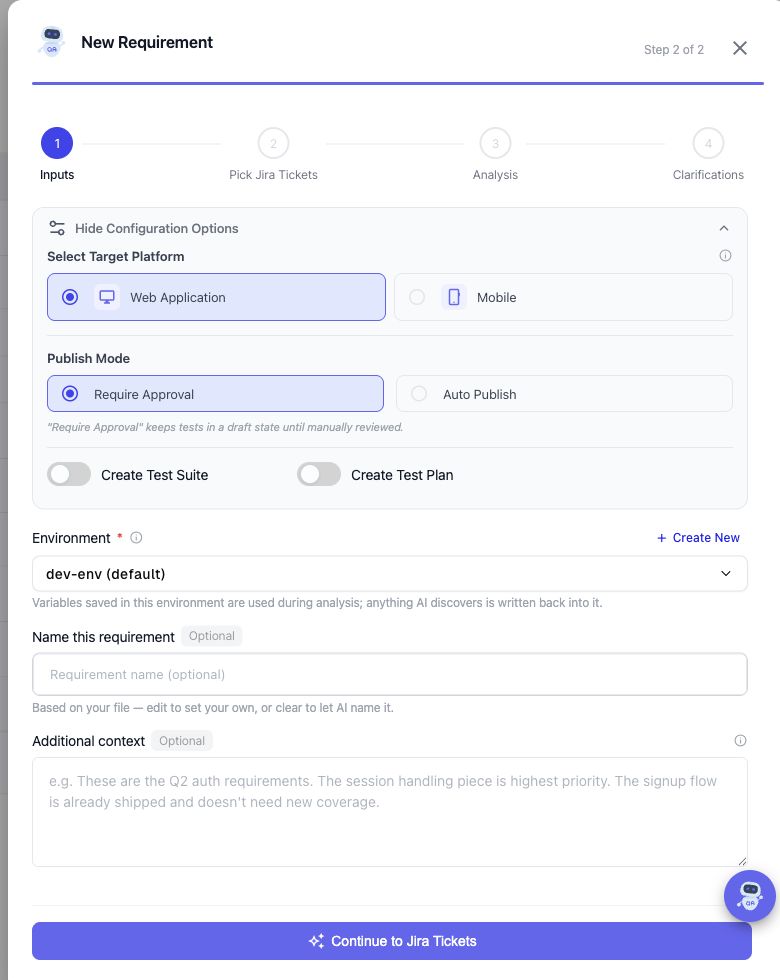 {% endstep %}
{% step %}
{% hint style="info" %}
For tracker-based generation, choose the integration before the configuration step. Jira and Azure DevOps connections are managed under **Integrations & Plugins**. The Azure DevOps picker supports search by work-item ID or title and filters by project and work-item type.
{% endhint %}
{% endstep %}
{% step %}
### Select a publish mode
Choose how generated test cases are handled after analysis:
| Mode | Description |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Require Approval** (default) | Generated test cases are saved in a pending state. You must manually review and approve them from the Test Cases tab before they are published. The **Create Test Suite**, **Create Test Plan**, and **Execute Test Plan** options are disabled in this mode. |
| **Auto Publish** | Generated test cases are published immediately after analysis. You can optionally configure test suite, test plan, and execution settings (see next step). |
{% hint style="info" %}
Publish mode is available in **Import Requirement** mode only. When you select **Require Approval**, use the **Approve All** or **Reject All** buttons on the Test Cases tab to manage generated test cases (see [Test Cases tab](#test-cases-tab)).
{% endhint %}
{% endstep %}
{% step %}
### Configure optional settings
These options are available when **Auto Publish** is selected as the publish mode:
| Option | Description |
| --------------------- | --------------------------------------------------------------------------------------------------------- |
| **Create Test Suite** | Automatically group generated test cases into a new test suite. Enter a suite name. |
| **Create Test Plan** | Create a test plan for the generated cases. Enter a plan name. Automatically enables test suite creation. |
| **Execute Test Plan** | Run the test plan immediately after generation. Available when **Create Test Plan** is enabled. |
When the advanced connection section is available, you can also assign an organization-level **Proxy** or **Remote Browser** profile to the plan created from the import. These values apply to the generated plan, not to every generated test case. See [Proxy and remote browser profiles](/execution/proxy-and-remote-browser-profiles).
{% endstep %}
{% step %}
### Start generation
Click **Create Test Cases**. ContextQA uploads the file and begins processing.
* If the AI needs clarification, the **AI questionnaire** opens automatically (see [Answering the AI questionnaire](#answering-the-ai-questionnaire)).
* Otherwise, ContextQA generates test cases in the background. The file appears in the Requirements Library with status *Processing*.
{% endstep %}
{% endstepper %}
{% hint style="info" %}
When the Figma feature is enabled on your plan, you can select **Figma** as the source instead of uploading a file. Enter a Figma file URL (e.g., `https://www.figma.com/file/...` or `https://www.figma.com/design/...`).
{% endhint %}
***
## Answering the AI questionnaire
When the AI determines that your requirements need clarification, it generates a set of questions. This happens either automatically after upload or when you click a file with **Pending action** status.
The questionnaire dialog displays:
* The file name and the AI's initial analysis message
* One or more clarification questions, each with context explaining why the question is relevant
Type your answer for each question in the provided text area. Then:
* Click **Submit** to send your answers and continue generation.
* Click **Skip & Generate Test Cases** to proceed without answering. This option is available only before you enter any answers.
After submission, a confirmation message appears: *"The requirements are currently being processed. Please review the test cases once they are ready."*
***
## Requirements Details page
Click any file in the Requirements Library to open its **Requirements Details** page. The header displays:
* File name and processing status
* Metadata (file type, test type, requirement code, creator, date)
* Test case count and type badges (Positive, Negative, Edge)
* Actions menu with **View Details**, **Download Original**, **Export Test Cases**, **Re-import / Update**, and **Delete**
Below the header, up to six tabs provide different views of the requirement: **Test Cases**, **Questionnaire**, **Requirement Data**, **History**, **Metadata**, and **Gaps**. The source type controls availability: test-case and video imports omit unsupported tabs, **History** is marked **Coming soon**, and crawl requirements currently show **Gaps** as **Coming soon**.
***
### Test Cases tab
The default tab. Displays all test cases generated from the requirement file in a searchable, filterable table.
**While generation is in progress**, a progress indicator shows:
* Percentage complete and a note that processing may take a few minutes
* A message confirming that generation runs in the background
The details page remains usable while generation runs. You can leave the page and continue other work; ContextQA keeps processing and notifies you when the cases are ready. If the run takes longer than expected, the page changes to a delayed message instead of blocking navigation.
**After generation completes**, the table shows each test case with:
* Name and description
* Variables, including test-data references and detected environment or global-variable references
* Type (Positive, Negative, Edge, Functional, Boundary Value, End to End, Field Validation)
* Priority, prerequisite, and review decision
If a generated candidate matches a test already in the repository, ContextQA places an **existing test case** icon beside its `TC-` link and displays the match reason below the title. Select the linked test ID to inspect the existing case before deciding whether additional coverage is necessary. A newly generated candidate uses an under-review `UR-` until it is accepted.
**Available actions:**
* **Search** test cases by name
* **Filter** by type, priority, prerequisite, or decision
* **Approve All** or **Reject All** to batch-manage generated test cases
* Click a test case row to open a detail drawer with full step information
**Table row actions:**
* View, edit, or delete individual test cases from the row action menu
#### Review detected variables
Open a generated test case and select **Variables** in the detail drawer before approving it.
* `${name}` identifies a value stored with the generated test data.
* `*|name|` identifies a value supplied by the selected environment.
* `{{name}}` identifies a global variable.
The table and drawer display environment and global references as labeled badges so you can distinguish their source. Environment and global values are managed from their respective configuration pages; do not create a second test-data variable with the same purpose. When a variable already has a value that you supplied during the requirement flow, that value is retained instead of being replaced by an environment value. ContextQA also avoids adding a duplicate name to the selected environment.
Special characters that are valid for the selected variable type are preserved after test-case generation. Resolve any syntax warning in the drawer before approving or publishing the case, then confirm the step still references the intended variable.
***
### Questionnaire tab
Displays the AI-generated questions and your answers from the clarification step.
Each entry shows:
* The question text
* Your answer (or a note that the question was skipped)
Use this tab to review what context the AI used when generating test cases. If a question was skipped, a placeholder indicates: *"Question skipped. Regenerate the test case to add an answer."*
***
### Requirement Data tab
The **Requirement Data** tab keeps both the uploaded source material and the AI's interpretation in one place. Switch between the **Requirement Files** and **AI Analysis** sub-tabs.
#### Requirement Files
Displays the files that were uploaded as part of this requirement. Each file appears as an expandable card.
**Each file card shows:**
* **File name** — The name of the uploaded file with a document icon
* **Download** button — Click to download the original file. If the download link is unavailable, the button is disabled with a tooltip explaining the status.
* **Expand/collapse** toggle — When the file has additional context, click the chevron to expand the card and view it
**Expanded card content:**
* **Context** — The additional information provided during upload that describes what the file contains or how it should be used
When no files are associated with the requirement, an empty state message is displayed.
{% hint style="info" %}
This view is most useful when multiple files were uploaded together for one requirement set. It preserves each source file and its context annotation for later review.
{% endhint %}
#### AI Analysis
Shows the AI's analysis of your uploaded requirements, organized into four sections:
| Section | Description |
| -------------------- | ------------------------------------------------------------------------------ |
| **AI Understanding** | A summary of how the AI interpreted your requirements document. |
| **Assumptions Made** | A numbered list of assumptions the AI made during analysis. |
| **Coverage Notes** | Areas covered by the generated tests, with a summary and bullet-point details. |
| **Warnings & Gaps** | Areas that may need attention — flagged with warning indicators. |
A **Confidence Score** (0–100%) indicates how confident the AI is in its analysis. Higher scores mean the requirements were clear and complete.
***
### History tab
{% hint style="info" %}
This tab is coming soon. It will display a timeline of changes made to the requirement file, including re-imports, test case modifications, and status transitions.
{% endhint %}
***
### Metadata tab
Displays detailed information about the uploaded file in three sections:
**File information:**
| Field | Description |
| ---------- | --------------------------------------------------- |
| File Type | Format of the uploaded file (e.g., XLSX, JSON, MP4) |
| File Size | Size of the uploaded file |
| Page Count | Number of pages in the document |
| Word Count | Total word count |
| Version | Current version number |
**Configurations:**
| Field | Description |
| ----------------------- | ----------------------------------------------------- |
| Test Plan | Associated test plan name (if created during upload) |
| Test Suite | Associated test suite name (if created during upload) |
| Platform | Target platform (Web, Mobile, or API) |
| Browser / Mobile Device | Target browser or mobile device |
| Environment | Environment selected for generation or execution |
**Timestamps:**
| Field | Description |
| ------------- | --------------------------------------- |
| Created By | User who uploaded the file |
| Created At | Upload date and time |
| Last Modified | Date and time of the most recent change |
**Labels:** Any tags applied to the requirement file.
***
### Gaps tab
Identifies coverage gaps between your requirements and the generated test cases. The page displays each gap as a card in a two-column grid.
**Each gap card shows:**
* **Title** — A short description of the missing coverage area
* **Similarity score** — How closely the gap relates to existing test cases (displayed as a progress bar)
* **Tags** — Requirement ID, test case priority, test case type, and prerequisite warnings
* **Why missing** — An explanation of why this area lacks coverage
Click **View details** on any gap card to open a detail drawer with:
* **Similarity score** — A visual ring chart with a description of the score level
* **Summary** — Detailed explanation of the gap
* **What's missing** — A numbered list of specific items not covered
* **Suggested test cases** — AI-recommended test cases to close the gap
**Gap drawer actions:**
* **Add** individual suggested test cases to your project
* **Add All Suggestions** to close the gap at once
* **Dismiss** the gap if it is not relevant
***
## Row actions in the Requirements Library
Right-click or use the action menu on any file in the Requirements Library for quick actions:
| Action | Description |
| ---------------------- | -------------------------------------------------------- |
| **View Details** | Open the Requirements Details page |
| **Download Original** | Download the originally uploaded file |
| **Export Test Cases** | Export generated test cases |
| **Re-import / Update** | Upload a new version of the requirement file |
| **Delete** | Remove the requirement file and its generated test cases |
***
## Related documentation
* [Creating Test Cases](/web-testing/creating-test-cases) — All test case creation methods including file import
* [AI Test Generation](/ai-features/ai-test-generation) — All 10 AI test generation methods
* [Managing Test Suites](/web-testing/managing-test-suites) — Organize test cases into suites
* [Test Data Management](/web-testing/test-data-management) — Variables and data-driven testing
* [Azure DevOps integration](/integrations/azure-devops) — Generate requirements from work items and report failures
* [PR Impact Analysis](/ai-features/pr-impact-analysis) — Map pull-request changes to affected tests
* [Proxy and remote browser profiles](/execution/proxy-and-remote-browser-profiles) — Route generated plans through saved connections
# Test Steps Editor
A comprehensive reference for the ContextQA step editor, covering all step types, field options, variable syntax, AI verification steps, and conditional and loop logic.
## Quick answer
A comprehensive reference for the ContextQA step editor, covering all step types, field options, variable syntax, AI verification steps, and conditional and loop logic. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers and SDETs who need fine-grained control over test step logic — including conditional branches, loops, API calls, and AI verification assertions.
{% endhint %}
The test steps editor is where you build, review, and refine the sequence of actions and assertions that make up a test case. Each step represents one atomic instruction — a click, a typed value, a navigation, an API call, or a verification. The editor supports multiple step types, giving you precise control over complex flows that include conditional logic, data iteration, API interactions, database verification, custom code, document generation, and AI-powered assertions.
## Prerequisites
* You have created or opened a test case.
* You understand the difference between action steps and verification steps (see [Core Concepts](/getting-started/core-concepts)).
***
## Opening the Test Case Details Screen
From the Test Cases list, click on a test case name to open it. The test case details screen has three main areas:
* **Header bar** — Displays the test case name (click the edit icon to rename inline), status badge, priority badge, and action buttons (**Record**, **Run**, and a **More** menu with options like Debug, Duplicate, Delete, and Generate API test case). Warning badges appear if test data or prerequisites are missing.
* **Main content area** — Contains a collapsible **Prerequisites** section at the top, followed by a tab bar with **Test Steps** and **Relationships** tabs. The **Test Steps** tab is selected by default.
* **Side panel** (collapsible) — A right-side panel with three icon tabs:
* **Test Case** — View and edit the description, metadata, labels, status, and AI settings (Default AI Action, AI Smartness level).
* **Variables** — Manage local key-value parameters for the test case. Add, edit, delete, and bulk-delete variables directly from this panel.
* **Run History** — View past execution results for this test case.
### Adding steps
Click **Add Step** at the bottom of the step list. A **Create a New Step** modal opens with a category sidebar on the left (see [Step builder categories](#step-builder-categories) below). You can also add a step at the first position using the **+** icon above the step list, or insert a step between two existing steps using the inline add action.
### Reordering steps
Click the **Reorder** button in the tab bar to enter reorder mode. Drag steps using the handles to rearrange them, then click **Done** to save or **Cancel** to discard changes.
> **Note**: Step group steps cannot be reordered from within the parent test case. Open the step group to reorder its internal steps.
### Bulk step actions
Select multiple steps using the checkboxes to reveal a floating toolbar at the bottom of the screen with these actions:
| Action | Description |
| ------------- | ---------------------------------------------------------------------- |
| **Group** | Wrap the selected steps into a new step group |
| **Loop** | Wrap the selected steps inside a new loop |
| **Condition** | Wrap the selected steps inside a new conditional branch |
| **Duplicate** | Copy the selected steps |
| **Skip** | Mark the selected steps as skipped so they do not run during execution |
| **Unskip** | Restore the selected skipped steps so they run again |
| **Delete** | Remove the selected steps |
**Skip** appears when at least one selected step still runs, and **Unskip** appears when at least one selected step is already skipped. Both actions update all selected steps in a single request.
When you select a container step such as a loop or condition, its nested steps are selected with it and follow the same skip or unskip action. A step that sits under a skipped parent inherits its parent's state: if you do not include that parent in the selection, the step remains unchanged.
After a bulk action completes successfully, ContextQA clears the selected steps and dismisses the floating toolbar. This makes it clear that the grouping, loop, condition, duplication, skip, or delete operation has finished. If validation prevents an action from completing, review the message before changing the selection.
### Relationships tab
The **Relationships** tab shows two sub-views:
* **Test Plans** — Lists all test plans that include this test case.
* **Used as Prerequisite in** — Lists test cases that depend on this test case as a prerequisite, with an option to replace it.
***
## Step Builder Categories
When you click **Add Step**, the step builder modal opens with nine categories in the left sidebar. Select a category to see its builder form on the right.
| Category | Description |
| --------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Actions** | Standard browser actions — click, type, navigate, select, scroll, hover, upload. The default category. |
| **Loops** | Create For Loop or While Loop steps to repeat a set of inner steps. |
| **Conditions** | Create If / Else If / Else conditional branches based on variable comparisons. |
| **Database** | Run database verification queries against a connected database. |
| **Api** | Make REST API calls (GET, POST, PUT, PATCH, DELETE) and store responses in variables. Uses a three-step wizard: (1) configure the request, (2) store the response in a variable, (3) verify the response. |
| **Ai Agent** | Write a plain-English instruction for the AI execution engine to interpret and perform. |
| **Custom Code** | Execute custom JavaScript code within the test flow. |
| **Document** | Generate TXT or CSV documents with configurable delimiters, templates, and key-value data mappings. |
| **Step Group** | Insert a reusable step group by searching and selecting from available groups in the workspace. |
### Edit in Depth
Right-click or use the step menu on any existing step and select **Edit in Depth** to open a full-screen editor. This modal provides access to the step's template selector, template variable fields, and advanced settings — useful for fine-tuning steps that require precise configuration beyond the inline editor.
***
## Step Types
The following sections describe each step type in detail. These correspond to the categories available in the step builder modal.
### AI Agent Step (Default)
The AI Agent step is the default step type and the most commonly used. You write a plain-English instruction and the AI execution engine interprets it and performs the corresponding browser action at runtime.
**When to use:** Any browser interaction — clicking, typing, selecting, hovering, scrolling, navigating — that can be described in a sentence.
**Action field examples:**
```
Click the Sign In button
Type test@example.com in the Email Address field
Select "United States" from the Country dropdown
Scroll down to the footer
Hover over the Profile menu
Press the Tab key
Upload the file /test-data/sample.pdf to the Document Upload area
```
**Tips:**
* Use the exact text that appears on the element in the UI (button labels, field placeholders, dropdown option text).
* For fields identified by placeholder or label text, reference that text: "Type hello in the field labelled Search products".
* For elements with no visible text, describe their visual appearance or position: "Click the blue Download icon next to the first row".
***
### Navigate
The Navigate step directs the browser to a specific URL. Unlike the AI Agent step, the Navigate step uses the browser's direct URL navigation rather than simulating a user click on a link.
**When to use:** When you need to jump to a specific URL directly — a deep link to a page that requires direct URL access, or an absolute URL that includes query parameters.
**Fields:**
* **URL** — the destination URL. Supports environment variable substitution: `${ENV.BASE_URL}/settings/billing`.
**Example:**
```
URL: ${ENV.BASE_URL}/admin/users?role=admin&active=true
```
***
### REST API Call
The REST API Call step makes an HTTP request from within the test, independent of the browser. The response can be stored in a variable and used in subsequent steps.
**When to use:** Setting up test data before the UI test (e.g., creating a user via API before testing the UI that displays that user), tearing down test data after a test, or verifying backend state that is not visible in the UI.
The step builder uses a three-step wizard for API steps:
**Step 1 — Configure the request:**
| Field | Description |
| ------------- | ---------------------------------------------------------------------- |
| Method | GET, POST, PUT, PATCH, DELETE |
| URL | The full endpoint URL. Supports variables: `${ENV.BASE_URL}/api/users` |
| Headers | Key-value pairs. Use `${ENV.API_KEY}` for authorization tokens |
| Authorization | No Auth, Bearer Token, or OAuth 2.0 |
| Request Body | Raw JSON, form-urlencoded, or form-data. Supports variables |
| Parameters | Query parameters as key-value pairs |
| Environment | Select an environment to use its base URL |
**Step 2 — Store the response:**
| Field | Description |
| -------------------------- | ------------------------------------------------- |
| Store response in variable | Name of the variable to store the response object |
**Step 3 — Verify the response (optional):**
| Field | Description |
| -------------------- | -------------------------------------------------------------- |
| JSON path | Path to a specific field in the response body for verification |
| Comparison | Comparison operator (equals, contains, etc.) |
| Data type | Expected data type of the response field |
| Expected value | The value to compare against |
| Expected status code | If set, the step fails if the response status does not match |
**Using API response data in later steps:**
If you set "Store response in variable" to `loginResponse`, subsequent steps can reference:
* `${loginResponse.status}` — HTTP status code
* `${loginResponse.body.token}` — a field from the JSON response body
* `${loginResponse.body.user.id}` — nested JSON path access
* `${loginResponse.headers.content-type}` — a response header value
**Example flow:**
```
Step 1 (REST API): POST ${ENV.BASE_URL}/api/auth/login
Body: { "email": "${ENV.ADMIN_EMAIL}", "password": "${ENV.ADMIN_PASSWORD}" }
Store response in: authResponse
Step 2 (AI Agent): Navigate to ${ENV.BASE_URL}/dashboard
(Uses the session cookie set by the API login)
Step 3 (REST API): GET ${ENV.BASE_URL}/api/users/${authResponse.body.userId}
Headers: Authorization: Bearer ${authResponse.body.token}
Store response in: userProfile
Step 4 (AI Verification): Verify the username displayed on the profile page
matches ${userProfile.body.name}
```
***
## Interactive demo: conditions and loops
Use this detailed walkthrough to see how conditional branches, For Loops, and While Loops model data-dependent or repeated behavior inside one test. The surrounding reference below explains the fields and execution behavior for each control-flow step.
{% embed url="" %}
### What to notice
* If, Else If, and Else branches make alternate application states explicit.
* For Loops repeat a known number of actions, while While Loops repeat only while a condition remains true.
* Child steps remain visible in the editor, making review and failure diagnosis easier than duplicated test cases.
### Conditional (If / Else If / Else)
The Conditional step creates branching logic in the test execution. You can chain multiple conditions together: an **If** branch, one or more **Else If** branches, and an optional **Else** branch. The test engine evaluates conditions from top to bottom and executes the steps inside the first branch whose condition is true. If no condition matches, the Else branch runs (when defined).
**When to use:** When the test must handle different application states — for example, a feature flag that changes which UI is shown, a user role that determines which dashboard loads, or a form field whose value depends on test data.
**Fields:**
* **Condition** — a variable comparison expression. Each If or Else If branch has its own condition:
* `${localVar} == "expected value"`
* `${apiResponse.body.status} == "active"`
* `${ENV.FEATURE_FLAG} == "true"`
* **If-true steps** — the steps to execute when the If condition is met.
* **Else If condition and steps** — additional branches, each with its own condition and steps. You can add as many Else If branches as you need.
* **Else steps** — optional final branch that executes when no preceding condition is true.
**Creating a conditional step:**
1. Click **Add Step** and select the **Conditions** category in the step builder.
2. Define the If condition and add the steps for the If-true branch.
3. To add an Else If branch, hover over the If step in the step list and select **Else If** from the step menu. Define the new condition and its steps.
4. Repeat step 3 for additional Else If branches.
5. To add an Else branch, hover over the last Else If step and select **Else**.
6. Drag steps into the appropriate branch containers using reorder mode if needed.
> **Tip**: You can also create a conditional from existing steps. Select multiple steps using the checkboxes, then click **Condition** in the floating toolbar to wrap them inside a new If branch.
**Simple example (If / Else):**
```
If ${userType} == "admin"
Then: Click the Admin Panel link
Else:
Click the My Account link
```
**Multi-branch example (If / Else If / Else):**
```
If ${qualification} == "skills"
Then: Select "Skill" from the Qualification dropdown
Else If ${qualification} == "education"
Then: Select "Education" from the Qualification dropdown
Else If ${qualification} == "experience"
Then: Select "Experience" from the Qualification dropdown
Else:
Select "Other" from the Qualification dropdown
```
**How evaluation works:**
* The engine evaluates each condition from top to bottom.
* It stops at the first branch where the condition is true and executes those steps.
* All remaining branches are skipped.
* If no condition matches and an Else branch exists, the Else steps run.
* After the conditional block completes, execution continues with the next step in the test case.
***
### For Loop
The For Loop step repeats a set of inner steps a fixed number of times or once per item in a data set.
**When to use:** When you need to add 5 items to a cart, dismiss a recurring modal, iterate over rows in a table, or repeat a form submission multiple times.
**Modes:**
**Count-based:** Repeat N times.
```
Repeat 5 times:
Click the Add Item button
Verify the cart count increased
```
**Data-based:** Iterate over a list variable. If `${productList}` contains `["Widget A", "Widget B", "Widget C"]`, the loop runs three times with `${item}` set to each value in turn:
```
For each item in ${productList}:
Type ${item} in the Search field
Click Search
Verify at least one result is displayed
```
***
### While Loop
The While Loop step repeats a set of inner steps until a specified condition becomes false (or until a maximum iteration count is reached, as a safety guard).
**When to use:** When you need to wait for an asynchronous process to complete — polling for a background job to finish, waiting for a status field to change, retrying until a dynamic element appears.
**Fields:**
* **Condition** — the loop continues while this condition is true: `${jobStatus} != "complete"`
* **Max iterations** — safety limit to prevent infinite loops (default: 25, maximum: 50). The loop fails at this step once it reaches this many iterations if the condition is still true. You can set this cap when you create the while-loop step or when you edit it in the Edit-in-depth modal.
* **Inner steps** — the steps to execute on each iteration
The editor limits the child-step choices inside a While Loop to supported operations. If **For Loop** or **Step Group** is not offered while adding an inner step, create a flatter flow or move the reusable sequence outside the While Loop instead of trying to force an unsupported nested structure.
**Example:**
```
While ${jobStatus} != "complete" (max 20 iterations):
Wait 3 seconds
REST API: GET ${ENV.BASE_URL}/api/jobs/${jobId}
Store response in: jobPollResponse
Set ${jobStatus} = ${jobPollResponse.body.status}
```
***
### Step Group
The Step Group step inserts a named, reusable step group at a specific point in the test case. At execution time, the step group expands and its individual steps run in sequence as if they were inline steps.
**When to use:** Any repeated setup or teardown pattern — login sequences, navigation to a module, closing persistent UI elements (cookie banners, chat widgets), completing a checkout flow that precedes the actual test assertion.
**Fields:**
* **Step Group** — search and select from the available step groups in the workspace.
**Behavior:**
* Changes to the step group are reflected in all test cases that use it without requiring the test cases to be re-saved.
* Step group steps appear individually in the execution report, not as a collapsed entry — each step shows its own pass/fail status and screenshot.
***
### AI Verification
The AI Verification step uses a vision-language AI model to evaluate a natural language condition against the current browser state. It is the most flexible assertion type, handling dynamic, non-deterministic content that cannot be verified with exact string matching.
**When to use:**
* Verifying that a dynamically generated value (order ID, timestamp, random token) exists and is plausible.
* Confirming visual states ("the chart rendered successfully", "the map shows a marker in London").
* Checking relative conditions ("the error message is displayed below the Password field").
* Any condition that requires understanding context rather than matching a literal string.
**Action field examples:**
```
Verify the dashboard loaded and the main navigation menu is visible
Verify a confirmation message is displayed indicating the order was placed
Verify the table contains at least three rows of data
Verify the user's profile photo is displayed in the top-right corner
Verify the error message states that the email address is already in use
Verify the chart displays data for the last 30 days
Verify that the displayed Total equals Subtotal plus Tax, using two decimal places
```
**How it differs from a standard AI Agent step:** A standard AI Agent step performs an action. An AI Verification step produces a pass/fail result based on evaluating the current screenshot against the stated condition. Use the AI Verification type explicitly for assertion steps so the execution report correctly categorizes them as verifications rather than actions.
### Verification data sources
When a verification includes an expected value, choose its source in the test-data value picker:
| Source | Example use |
| ------------------------ | ---------------------------------------------------------------------------------------------- |
| **Plain Text** | Verify a fixed heading or message. |
| **Test Data Profile** | Verify the expected outcome for the active data row. |
| **Runtime** | Verify an ID or value captured earlier in this execution. |
| **Environment Variable** | Verify an environment-specific non-secret label or URL. |
| **Global Data** | Verify an approved workspace-wide constant. |
| **Random** | Generate a value for an earlier action; capture it before using it as an expected value later. |
Build mixed values by typing the fixed portion and inserting the dynamic portion with the picker. Do not paste environment secrets into the natural-language verification prompt. For exact financial, schema, or contract checks, prefer deterministic REST API or Custom Code validation; AI Verification is best for contextual or visual conditions.
***
## Step Editor Fields Reference
Every step, regardless of type, has the following common configuration fields:
| Field | Description |
| --------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Step Name / Description** | The plain-English instruction or assertion. This is what appears in the step list and in the execution report. |
| **Step Type** | Dropdown selecting the step type (AI Agent, Navigate, REST API Call, Conditional, For Loop, While Loop, Step Group, or AI Verification). |
| **Wait Condition** | Optional condition that must be satisfied before this step executes: Wait for element visible, Wait for URL to contain, Wait for network idle, Wait N seconds. |
| **Screenshot Capture** | Controls when a screenshot is captured: Always (default), On Failure Only, Never. |
| **Mark as Optional** | If enabled, a failure on this step does not fail the overall test case. Useful for non-critical UI enhancements or known-flaky elements. |
| **Timeout** | Maximum time (in seconds) to wait for the step action to complete before marking it as failed. Default: 30 seconds. |
***
## Variables in Steps
ContextQA supports local, global, environment, and Test Data Profile values. Their stored token formats differ, so insert them with the value-source picker rather than assuming one universal `${variableName}` syntax.
### Local Variables
Scoped to the test case. Defined in the **Variables** tab of the side panel or set dynamically by REST API Call steps.
```
${username}
${orderId}
${searchTerm}
```
**Setting a local variable dynamically:** In a REST API Call step, use "Store response in variable" to save the response. Individual fields are accessed via dot notation on the stored object.
### Global Variables
Workspace-scoped. Available to every test case in the workspace. Defined in **Environment & Data → Global Data**.
```
${globalAdminEmail}
${defaultTimeout}
${testProjectId}
```
Global variables are useful for values that are shared across many test cases but are not environment-specific — a default admin account email, a test project name, a default search term.
### Environment Parameters
Values from the currently selected environment. Insert them through the data picker; for example, `baseURL` appears as `*|baseURL|*`.
```
*|baseURL|*
```
Environment parameters allow the same test step to work against staging, QA, and production without modification. Select the environment on the test case or in the plan configuration that executes it.
### Test Data Profile Variables
When a test case has a test data profile attached, each column in the profile becomes a variable available in the test steps.
Map each relevant input or verification step to a profile column through the **Parameter** picker. When a Test Data Profile loop is configured, the selected steps repeat across the chosen row range.
***
## Tips & Best Practices
* **Keep AI Agent step descriptions action-oriented.** Start with a verb: "Click", "Type", "Select", "Scroll", "Verify", "Navigate". The AI execution engine recognizes these action verbs and dispatches them to the correct browser interaction handler.
* **Use AI Verification steps for all assertions.** Even when an assertion could theoretically be expressed as a standard AI Agent step ("verify the heading says Dashboard"), using the explicit AI Verification type ensures the step is tracked as an assertion in the execution report and counted in pass/fail statistics correctly.
* **Set timeouts explicitly for slow operations.** If your application has pages that take more than 30 seconds to load (reports, data exports, dashboard renders), increase the timeout on the relevant steps to avoid premature failures.
* **Mark setup steps as Optional when appropriate.** Cookie banner dismissal steps, onboarding tour dismissal, and similar incidental actions that may or may not appear can be marked Optional so they don't fail the test if the UI state doesn't require them.
* **Use For Loop for repetitive data entry.** When a test needs to add multiple rows to a table or submit a form multiple times with the same structure, use For Loop with a data set variable rather than duplicating steps.
## Troubleshooting
**An AI Agent step is clicking the wrong element** Refine the step description to be more specific. Add context about the element's location ("in the header", "in the confirmation dialog"), its label ("the button labelled Submit Order, not the Cancel button"), or its visual appearance ("the blue primary action button").
**A REST API Call step fails with a 401 Unauthorized response** Verify that the Authorization header is correctly formatted and that the token variable it references has been set by an earlier step. Check the network log in the execution report to see the exact request headers that were sent.
**A Conditional step is not taking the expected branch** Add a temporary AI Agent step before the conditional that logs the value of the condition variable: "Verify the page shows the value of ${myVar}". Run the test and check the screenshot to see what value the variable actually holds.
**Step Group steps are not appearing individually in the report** This behavior was changed in a recent release. If you are on an older workspace version, the step group may appear as a collapsed entry. Contact support to upgrade your workspace to the current execution engine.
**While Loop is hitting the max iteration limit** The default limit is 25 iterations. If your polling loop needs more iterations, increase the **Max iterations** field, up to the maximum of 50. Also consider increasing the wait time between iterations to give the background process more time to complete before each poll.
## Related Pages
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Debugging Test Cases](/web-testing/debugging-test-cases)
* [Database Steps](/web-testing/database-steps)
* [Custom Code Steps](/web-testing/custom-code-steps)
* [Document Generation Steps](/web-testing/document-generation-steps)
* [Test Data Management](/web-testing/test-data-management)
* [AI Self-Healing](/web-testing/self-healing)
* [Core Concepts](/getting-started/core-concepts)
* [Running Tests](/execution/running-tests)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Debugging Test Cases
Debug test cases interactively with breakpoints, live variable inspection, step-by-step execution, and real-time browser or device viewing.
## Quick answer
Debug test cases interactively with breakpoints, live variable inspection, step-by-step execution, and real-time browser or device viewing. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers, SDETs, and developers who need to troubleshoot failing test cases by stepping through execution, inspecting variables, and editing steps in real time.
{% endhint %}
## Overview
The debug screen provides an interactive environment for diagnosing and fixing test case failures. Instead of running a test end-to-end and reviewing results afterward, debug mode lets you pause execution at any step, inspect the live browser or device state, view variable values, and make changes on the fly — all without leaving the execution screen.
**Key capabilities:**
* Set breakpoints on specific steps to pause execution automatically
* Step through execution one step at a time with **Step Over**
* Inspect live variable values at each pause point
* Add, edit, skip, delete, and restore steps during a debug session
* Jump to any step in the test case
* Review all session changes before saving
* View the live browser or device via VNC streaming
***
## Starting a debug session
{% stepper %}
{% step %}
### Open a test case
Navigate to **Test Cases**, open a test case, and click the **More** menu (three dots) in the header bar.
{% endstep %}
{% step %}
### Select Debug
Click **Debug** from the menu. The debug screen opens with a three-panel layout:
| Panel | Location | Purpose |
| --------------- | -------- | --------------------------------------------------------------------- |
| **Header** | Top | Test case name, execution status, debug controls |
| **Steps panel** | Left | Step list, console, network, live variables, and AI conversation tabs |
| **Live view** | Right | Real-time browser or device screen via VNC |
| {% endstep %} | | |
{% step %}
### Start execution
Click the **Start** button in the header. ContextQA connects to a browser or device instance and begins executing from the first step. If breakpoints are set, execution pauses automatically when it reaches a breakpoint.
{% endstep %}
{% endstepper %}
***
## Debug controls
The header bar provides the following controls during an active debug session:
| Control | Description |
| ---------------- | ------------------------------------------------------------------------------------------ |
| **Start** | Begin debug execution from the first step. |
| **Step Over** | Execute the current step and pause at the next step. |
| **Continue** | Resume execution until the next breakpoint or the end of the test. |
| **Pause** | Pause execution at the current step. |
| **Stop** | Stop the debug execution. Changes made during the session are preserved. |
| **Restart** | Restart execution from the first step. |
| **Jump to Step** | Open a dialog to select a specific step to jump to and continue execution from that point. |
When execution is paused, the header displays a **Paused at Step N** indicator with the current step number and a timer showing how long the session has been paused.
***
## Setting breakpoints
Breakpoints pause execution automatically when the test reaches a specific step. You can set breakpoints before or during a debug session.
**To set a breakpoint:**
1. Hover over a step in the steps panel.
2. Click the breakpoint indicator (circle) in the left gutter of the step, or use the step context menu and select **Toggle Breakpoint**.
**To view all breakpoints:**
Click **View Breakpoints** in the header. A modal lists all active breakpoints with options to:
* Remove individual breakpoints
* Remove all breakpoints at once
**To remove a breakpoint:**
Click the active breakpoint indicator on the step, or remove it from the breakpoints modal.
***
## Steps panel
The left panel contains tabbed views for different aspects of the debug session.
### Steps tab
Displays the full step list for the test case (including prerequisite steps). Each step shows:
* Step number and description
* Execution status (pending, running, passed, failed, skipped)
* Breakpoint indicator
* Context menu with debug actions
**Step context menu actions:**
| Action | Description |
| --------------------- | ---------------------------------------------------------------------- |
| **Edit Step** | Open the step editor to modify the step action, locators, or settings. |
| **Add Step** | Insert a new step before or after the current step. |
| **Skip Step** | Mark the step to be skipped during execution. |
| **Unskip Step** | Remove the skip flag from a previously skipped step. |
| **Delete Step** | Remove the step from the test case. |
| **Restore Step** | Undo a deletion and restore the step. |
| **Duplicate Step** | Create a copy of the step. |
| **Toggle Breakpoint** | Add or remove a breakpoint on the step. |
| **Start from Step** | Begin execution from this specific step. |
Steps inside loops and conditions display their nested structure. You can add steps inside loop bodies and add else/else-if branches to condition steps directly from the debug screen.
### Console tab
Displays console log output from the browser during execution, with timestamps for each entry.
### Network tab
Shows network requests made during execution in a table format, useful for diagnosing API-related failures.
### Live variables tab
Displays the current values of all variables at the paused step. Variables are shown in a flat table with:
| Column | Description |
| --------- | ---------------------------------------- |
| **Key** | Variable name |
| **Value** | Current value |
| **Type** | Data type (string, number, object, etc.) |
You can refresh variables to get the latest values. Nested object values are flattened for readability.
### AI conversation tab
When debugging with AI assistance, this tab shows the AI agent conversation. You can send messages to the AI agent to help diagnose issues or perform actions.
### AI Prompt tab
The AI Prompt tab displays an archive of all AI agent prompts used during the debug session. Every time you create, edit, duplicate, or delete an AI agent step, its prompt text is recorded here with a timestamp and operation label (`created`, `edited`, `duplicated`, `deleted`, or `converted`).
Each entry shows the step number, the prompt text, and whether the step passed or failed. When you edit an AI agent step, the archive records the previous prompt text (before the edit) so you can trace how a prompt evolved.
The archive resets when the debug session ends.
***
## Editing steps during debugging
You can modify the test case while debugging without leaving the debug screen.
{% hint style="info" %}
Step editing controls (add, edit, delete, and context menu options) are only available when execution is paused. While execution is actively running, these controls are disabled to prevent conflicts.
{% endhint %}
**Editing an existing step:**
1. Click the step context menu and select **Edit Step**.
2. The step edit modal opens with the step's current configuration.
3. Modify the action, locators, or settings.
4. Click **Save** to apply changes.
**Adding a new step:**
1. Click the step context menu on an adjacent step and select **Add Step**.
2. The step builder modal opens with all available step types (Actions, Loops, Conditions, Database, API, AI Agent, Custom Code, Document, Step Group).
3. Configure the new step and click **Create**.
> **Note**: On mobile debug sessions, the Custom Code step type is not available in the step builder.
***
## AI agent steps approval
When an AI agent step executes during a debug session, ContextQA generates sub-steps from the agent's actions. Before the steps are added, you review and approve them.
1. The AI agent step executes and ContextQA analyzes the actions performed.
2. A **Review AI-generated steps** dialog appears with a preview of the generated steps.
3. Review the steps and select an option:
* **Create Steps** — stages the steps as session changes. The original AI agent step is marked as deleted, and the new steps appear after it.
* **Discard Changes** — drops the steps. You can edit the AI agent step and re-run it, or continue past it.
{% hint style="warning" %}
The approval dialog has a 5-minute timeout. If no action is taken, the steps are automatically discarded.
{% endhint %}
While the approval dialog is open, execution controls (**Step Over**, **Continue**, **Pause**, **Jump to Step**) are disabled.
***
## On-demand video capture
You can capture a video clip during a debug session while paused at a breakpoint.
1. Pause execution at a breakpoint or step.
2. Click the **Capture Video** button in the live view panel header.
3. A progress dialog tracks the capture: **Starting** → **Capturing** → **Ready**.
4. Click **Watch Now** to switch to the captured view, or **Close** to dismiss.
Use the **Live / Captured** toggle in the panel header to switch between the live browser stream and captured clips. When the debug execution completes, the full session video replaces individual clips.
***
## Session restoration
If the browser session becomes invalid (session timeout, authentication expiration), a **Session Restoration** dialog appears:
| State | Description | Actions |
| ---------------------- | -------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------ |
| **Restoring** | ContextQA is restoring browser state. | Wait for completion. |
| **Session expired** | Session validation failed. Shows specific failures (URL verification, authentication token). | **Restart from Beginning**, **Stop Debug**, or **Override & Continue anyway**. |
| **Restoration failed** | Browser state could not be restored. | **Restart from Beginning** or **Stop Debug**. |
**Override & Continue anyway** forces execution to continue despite validation failure. Use this when you are confident the browser state is still usable.
***
## Reviewing session changes
During a debug session, every modification you make (adding, editing, deleting, or skipping steps) is tracked. Before closing the debug session, you can review all changes.
Click **Review Session Changes** in the header or steps panel to open a summary of all modifications made during the session.
***
## Execution results
When the debug execution completes (or is stopped), an execution result modal displays:
* **Status** — Passed, Failed, Aborted, or Timed Out
* **Step summary** — Total steps, completed steps, and failed steps
* **Timing** — Total time, application time, and tool time
**Available actions after execution:**
| Action | Description |
| --------------------------- | ---------------------------------------------------------------- |
| **View Run Results** | Navigate to the full run results screen. |
| **Re Run** | Start a new debug execution. |
| **Back to Debug** | Return to the debug screen to continue working. |
| **Save & Close Debug Mode** | Save all session changes and exit the debug screen. |
| **Copy Run Link** | Copy a link to the run results (available on passed executions). |
***
## Best practices
{% hint style="success" %}
**Set breakpoints before the failing step** — Place breakpoints one or two steps before the suspected failure point. This gives you context on the application state leading up to the failure.
{% endhint %}
{% hint style="info" %}
**Use live variables to diagnose data issues** — Check variable values at each pause point to verify that API responses, environment parameters, and test data are what you expect.
{% endhint %}
{% hint style="warning" %}
**Review session changes before saving** — Click **Review Session Changes** before closing the debug session to verify that all modifications are intentional. Changes are applied to the test case when you save.
{% endhint %}
***
## Related documentation
* [Test Steps Editor](/web-testing/test-steps-editor) — Reference for all step types and the step builder
* [Creating Test Cases](/web-testing/creating-test-cases) — Test case creation methods
* [Version History](/web-testing/version-history) — Track and restore test case versions
* [Running Tests](/execution/running-tests) — Standard (non-debug) test execution
# Uploaded Test Files
Review imported requirement files, generated tests and variable sources, AI analysis, coverage gaps, selected environment, and upload metadata.
## Quick answer
Open **Assets → Requirements** and select an uploaded file to review its generated test cases, questionnaire, AI analysis, gaps, metadata, and history. In a generated case's **Variables** drawer, ContextQA distinguishes test-data values from environment (`*|name|`) and global (`{{name}}`) references. The **Metadata** tab shows the selected environment when the upload used one.
{% hint style="info" %}
**Who is this for?** QA engineers and test managers who import requirements documents into ContextQA and need to review, filter, and manage the generated test cases.
{% endhint %}
## Overview
When you import a requirements file (Excel spreadsheet, video, JSON, or Figma design) using the **Import File** method in the [test case creation dialog](/web-testing/creating-test-cases), ContextQA processes the file and generates test cases automatically. The **Uploaded Test Files** section provides a dedicated view for managing these imported files and their generated test cases.
The detail view for each uploaded file includes six tabs:
| Tab | Purpose |
| ----------------- | ---------------------------------------------------------------- |
| **Test Cases** | Browse, search, filter, and manage generated test cases |
| **Questionnaire** | Review and answer AI-generated questions about your requirements |
| **AI Analysis** | View AI-powered analysis of the uploaded file |
| **Gaps** | Identify coverage gaps in the generated test cases |
| **Metadata** | View file metadata and upload details |
| **History** | Track changes to the uploaded file (coming soon) |
***
## Opening uploaded test files
1. Navigate to **Assets → Requirements** from the left sidebar. The imported files list displays all uploaded requirement files.
Each row in the list shows:
| Column | Description |
| ------------------ | ----------------------------------------------------- |
| **ID** | Unique identifier for the uploaded file |
| **Name** | File name |
| **Type** | File format (Excel, CSV, etc.) |
| **Status** | Processing status — Completed, Pending, or Processing |
| **Estimated Time** | Estimated processing time |
| **Test Cases** | Number of generated test cases |
| **Created By** | Team member who uploaded the file |
| **Created Date** | Upload timestamp |
Click any row to open the file detail view.
***
## File detail view
The detail view header displays:
* **File name** and **status badge**
* **File type** and **test type** labels
* **Requirement code** identifier
* **Created by** and **date** information
* **Test case count** badge
* **Export** button to download generated test cases
* **Add More Context** button to provide additional information for AI generation
### Test cases tab
The default tab displays all test cases generated from the uploaded file in a searchable, filterable table.
**Search and filter:**
* Use the search bar to find test cases by name or description
* Click the **Filter** button to open the filter panel with options for status, type, and other attributes
* Active filters appear as removable chips above the table
**Table columns:**
Each test case row displays:
| Column | Description |
| ------------- | ------------------------------------------------------------- |
| **Test Case** | Name and inline description (click to open the detail drawer) |
| **Type** | Color-coded test type badge |
| **Status** | New or Existing |
| **Decision** | Pending, Approved, or Rejected |
| **Actions** | Edit, Approve, Reject, and Revert to Review buttons |
Click a row to open the **test case detail drawer**. The drawer uses a tabbed layout with **Details** and **Variables** tabs:
* **Details** — test case name, description, test type, priority, linked prerequisite (if any), variables in use, and ordered steps with expected results
* **Variables** — test-data values plus detected environment (`*|name|`) and global (`{{name}}`) references used by the generated steps
Available actions in the drawer:
* **Approve & Move to Repository** — accept the test case
* **Reject** — decline the test case
* **Revert to Review** — return a rejected test case to the pending state
* **Edit** (icon button) — switch to edit mode to modify fields before deciding
* **Save Changes** / **Cancel Changes** — persist or discard edits (or press `Enter` to save, `Escape` to cancel)
**Bulk actions:**
Select multiple test cases using the checkboxes to access bulk operations from the toolbar.
**Generation in progress:**
If the AI is still generating test cases, a progress indicator displays:
* Progress percentage and estimated time remaining
* A message that generation runs in the background and you can continue working
### Questionnaire tab
After generating test cases from a requirements file, the AI may identify areas where additional context is needed. The questionnaire tab displays these questions.
* Review each question and provide answers in the input fields
* Answers help the AI refine and improve the generated test cases
* Skipped questions display a note indicating they were not answered
### AI analysis tab
Displays AI-powered analysis of the uploaded file content. This tab provides insights about the requirements document, including coverage assessment, complexity analysis, and recommendations for test case generation.
### Gaps tab
Identifies coverage gaps in the generated test cases — scenarios or requirements from the source document that may not be adequately covered.
Each gap entry includes:
* **Gap description** — What requirement or scenario is missing coverage
* **Details** — Expanded view with additional context
**Actions:**
| Action | Description |
| ---------------------- | --------------------------------------------------- |
| **View Details** | Open the gap detail drawer for full context |
| **Add to Test Cases** | Generate a test case to cover this specific gap |
| **Add All Test Cases** | Generate test cases for all identified gaps at once |
### Metadata tab
Displays detailed information about the uploaded file:
* File name, type, and size
* Upload date and time
* Uploaded by (team member name)
* Processing status and duration
* Associated workspace and project details
* Selected environment, when one was configured during upload
### History tab
{% hint style="info" %}
The history tab is coming soon. It will display a timeline of changes made to the uploaded file and its generated test cases.
{% endhint %}
***
## Related documentation
* [Creating Test Cases](/web-testing/creating-test-cases) — Import files using the creation dialog
* [AI Test Generation](/ai-features/ai-test-generation) — All AI test generation methods
* [Managing Test Suites](/web-testing/managing-test-suites) — Organize generated test cases into suites
# Imported Files
View and manage test cases generated from imported files, review AI analysis results, and track import history.
## Quick answer
View and manage test cases generated from imported files, review AI analysis results, and track import history. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers and test managers who import test cases or requirements from files and need to review, verify, and manage the generated results.
{% endhint %}
## Overview
The Imported Files page displays all files you have uploaded through the [Import File](/web-testing/creating-test-cases) creation method. Each imported file shows its processing status, the number of generated test cases, and access to AI analysis and review. Generation continues in the background, and an inline marker identifies candidates that match a test already in the repository.
***
## Navigating to imported files
1. Select **Assets → Requirements** from the left sidebar
The imported files list loads with your most recent imports.
***
## Imported files list
The list displays all imported files in a searchable, paginated table.
**Table columns:**
| Column | Description |
| ------------------ | ---------------------------------------------------------------- |
| **Id** | Unique file identifier |
| **Name** | File name (click to open file details) |
| **Type** | Import type (e.g., test case import, requirement import) |
| **Status** | Processing status badge |
| **Estimated Time** | Estimated processing duration |
| **Test Cases** | Number of test cases generated (shown when processing completes) |
| **Created by** | Name of the user who uploaded the file |
| **Created Date** | Upload date and time |
**Status indicators:**
| Status | Description |
| ---------------------------- | ------------------------------------------------------------------------------------ |
| **Completed** | File processed successfully and test cases are available |
| **Pending Action** | AI needs additional information to process the file — click to provide clarification |
| **Processing / In Progress** | File is currently being analyzed and test cases are being generated |
| **Failed / Error** | Processing encountered an error |
Use the **search bar** to filter files by name. The table supports server-side pagination and auto-refresh.
***
## File details
Click a file name to open the file details view. The details view shows:
### File information
A metadata bar at the top displays:
* **Created** — Upload date
* **File URL** — Link to the original uploaded file
* **Created By** — Name of the uploader
* **Test Plan** — Link to the associated test plan (if created during import)
* **Test Suite** — Link to the associated test suite (if created during import)
### Test case type breakdown
For requirement imports, a breakdown shows the count of generated test cases by type:
| Type | Description |
| ------------ | ----------------------------------------------------- |
| **Positive** | Tests that verify expected behavior with valid inputs |
| **Negative** | Tests that verify error handling with invalid inputs |
| **Edge** | Tests that verify boundary conditions and edge cases |
### Generated test cases
The **Test Cases** tab displays generated candidates in a searchable table. New candidates use an under-review `UR-` until accepted. When a candidate matches a case already in the repository, an **existing test case** icon appears beside the linked `TC-`, a legend explains the marker, and the match reason replaces the normal description. Open the linked ID before adding coverage so you can compare the existing test with the requirement.
While processing is still in progress, the page shows completion progress and confirms that generation continues in the background. You can navigate away and return later without interrupting it. If processing fails, the error message appears in the empty state.
***
## AI clarification questionnaire
When you import a requirements file, the AI may need additional context to generate accurate test cases. If the file status is **Pending Action**, clicking it opens the AI clarification questionnaire.
**The questionnaire includes:**
* A summary message explaining what the AI found in your file
* One or more clarification questions with context about why each answer helps
* A text field for each answer
**Actions:**
| Button | Description |
| ------------------------------ | ------------------------------------------------------------------------- |
| **Submit** | Send your answers and start test case generation |
| **Skip & Generate Test Cases** | Skip the questions and generate test cases with the information available |
After submission, the file status changes to **Processing**. Review the generated test cases once processing completes.
***
## Importing files
Files are imported through the **Import File** method in the test case creation dialog. For step-by-step instructions, see [Creating Test Cases — Import File](/web-testing/creating-test-cases).
**Supported file types:**
| Mode | File types |
| ------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Import Test Cases** | `.xlsx`, `.xls` |
| **Import Requirement (Web / Mobile)** | `.xlsx`, `.xls`, `.docx`, `.csv`, `.txt`, `.pdf`, image (`.png`, `.jpg`, `.jpeg`, `.webp`, `.gif`), video (`.mp4`, `.mov`, `.webm`, `.mpeg`, `.mkv`) |
| **Import Requirement (API)** | `.json` |
{% hint style="info" %}
Attach UI mockups, screenshots, wireframes, or screen-flow documents along with your requirements. Visual context helps ContextQA's AI generate more relevant and complete test cases.
{% endhint %}
***
## Frequently asked questions
What happens when a file has Pending Action status?
The AI analyzed your file and needs clarification to generate accurate test cases. Click the file to open the questionnaire, answer the questions, and submit. You can also skip the questions and let the AI generate test cases with the available information.
Can I re-import the same file?
Yes. Each import creates a new entry in the imported files list. Candidates that match existing coverage are marked with the existing-case icon and linked to the repository test case.
Where do generated test cases appear?
Generated test cases appear in the **Test Cases** list. If you created a test suite or test plan during import, the test cases are automatically organized into those containers. Click the file name in the details view to navigate to the filtered test cases list.
***
## Related documentation
* [Creating Test Cases](/web-testing/creating-test-cases) — All test case creation methods including Import File
* [Managing Test Suites](/web-testing/managing-test-suites) — Organize imported test cases into suites
* [Test Data Management](/web-testing/test-data-management) — Variables and data-driven testing
* [AI Test Generation](/ai-features/ai-test-generation) — AI-powered test generation methods
# Version History
Track, compare, and restore previous versions of your test cases with ContextQA's built-in version history.
## Quick answer
Track, compare, and restore previous versions of your test cases with ContextQA's built-in version history. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
ContextQA automatically tracks changes to your test cases over time. The **Version History** tab on the test case details screen lets you browse previous versions, inspect what changed, compare any two versions side by side, and restore an earlier version when needed.
## Overview
Every time you modify a test case — whether by editing steps, updating configuration, or importing changes — ContextQA creates a new version. Each version captures:
* **Version number** — Sequential identifier (v1, v2, v3, ...)
* **Change type** — How the version was created (Create, Update, Restore, or Import)
* **Change summary** — Brief description of what changed
* **Author** — The team member who made the change
* **Timestamp** — When the change occurred
* **Detailed changes** — Field-level before/after values grouped by category
## Opening version history
1. Navigate to **Test Cases** and open any test case.
2. On the test case details screen, click the **Version History** tab in the main content tab bar.
The version history view loads with two panels: a **version list** on the left and a **detail panel** on the right.
## Version list
The left panel displays all versions for the test case, ordered from newest to oldest. Each entry shows:
| Field | Description |
| ------------------ | ---------------------------------------------------------------- |
| **Version number** | Label such as `v12`, `v11`, etc. |
| **Current badge** | Indicates the active version of the test case. |
| **Change type** | Badge showing Create, Update, Restore, or Import. |
| **Change summary** | Short description of the changes in this version. |
| **Author** | Avatar initials and name of the team member who made the change. |
| **Relative time** | How long ago the version was created (e.g., "2 hours ago"). |
Click any version to view its details in the right panel. The list supports infinite scroll — additional versions load automatically as you scroll down.
## Version detail view
When you select a version, the right panel displays:
* **Version header** — Version number, "Current" badge (if applicable), author name, and exact date.
* **Change summary** — The description of changes for this version.
* **Grouped changes** — Changes organized by category.
### Change categories
Changes are grouped into the following categories:
| Category | What it tracks |
| ------------------------- | --------------------------------------------------------------- |
| **Step changes** | Steps added, removed, or modified (with step number reference). |
| **Logic changes** | Updates to loops, conditions, and control flow. |
| **Configuration changes** | Test case settings and AI configuration changes. |
| **Test case changes** | Metadata changes such as name, tags, URL, or priority. |
Each individual change displays:
* **Operation badge** — Added (green), Removed (red), or Changed (amber).
* **Field name** — Which field was affected.
* **Before value** — The previous value (for Changed and Removed operations).
* **After value** — The new value (for Changed and Added operations).
## Comparing versions
To compare any two versions side by side:
1. Select a version from the list (any version other than the current one).
2. Click **Compare with Current** in the detail panel header.
3. The comparison view opens with the selected version on one side and the current version on the other.
In the comparison view, you can:
* **Select different versions** — Use the dropdown selectors to compare any two versions, not only the selected version and the current one.
* **Swap sides** — Click the swap icon to reverse the comparison direction.
* **View the difference summary** — Badges at the top show the total count of added, modified, removed, and unchanged items.
The comparison displays two sections:
* **Test case changes** — Field-level differences in test case metadata, shown as before/after cards.
* **Step changes** — Step-level differences with step number references and before/after cards.
Click **Close** to return to the standard detail view.
## Restoring a previous version
To revert a test case to an earlier state:
1. Select the version you want to restore from the version list.
2. Click **Restore this Version** in the detail panel header.
3. A confirmation dialog appears explaining that restoring creates a new version based on the selected version.
4. Click **Restore** to confirm.
ContextQA creates a new version (with change type "Restore") that contains the state of the selected version. The original version history is preserved — restoring does not delete any previous versions.
> **Important**: Restoring a version updates the test case steps, configuration, and metadata to match the selected version. Review the version details or use the comparison view before restoring to confirm the changes.
## Related documentation
* [Creating Test Cases](/web-testing/creating-test-cases) — Test case creation workflow and details screen overview
* [Test Steps Editor](/web-testing/test-steps-editor) — Detailed guide to all available step actions
* [Test Data Management](/web-testing/test-data-management) — Variables, CSV imports, and data-driven testing
# Requirements Library
Upload requirements documents, review AI-generated test cases, analyze coverage gaps, and manage your requirements library in ContextQA.
## Quick answer
Upload requirements documents, review AI-generated test cases, analyze coverage gaps, and manage your requirements library in ContextQA. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
The Requirements Library lets you manage uploaded requirement files and the test cases generated from them. After you import a requirements document through the [Create Test Case](/web-testing/creating-test-cases) dialog, the file appears in the library where you can track its processing status, review generated test cases, inspect AI analysis, identify coverage gaps, and view file metadata.
## Opening the requirements library
1. Select **Assets → Requirements** from the left sidebar.
The Requirements Library list view opens, showing all uploaded requirement files for the current workspace.
{% hint style="info" %}
**Library versus details:** **Assets → Requirements** opens the workspace-level Requirements Library. Clicking a requirement row opens that record's **Requirements Details** page. Tabs such as **Test Cases**, **Questionnaire**, **Requirement Data**, **Metadata**, and **Gaps** belong to the selected record; they are not separate top-level Requirements pages.
{% endhint %}
## Requirements list view
The list view displays a table of all uploaded files with the following columns:
| Column | Description |
| ------------------ | ----------------------------------------- |
| **Id** | Numeric identifier for the upload |
| **Name** | File name (click to open the detail view) |
| **Type** | File format (e.g., EXCEL, CSV) |
| **Status** | Current processing status (see below) |
| **Estimated Time** | Processing duration |
| **Test Cases** | Number of generated test cases |
| **Created by** | Team member who uploaded the file |
| **Created Date** | Upload date and time |
### Status values
| Status | Meaning |
| -------------------------------- | --------------------------------------------------- |
| **Completed** | Processing finished and test cases are available |
| **Pending action** | AI needs clarification before generating test cases |
| **Processing** / **In progress** | File is currently being analyzed |
| **Failed** / **Error** | Processing encountered an error |
Use the search bar to filter files by name. The list supports server-side pagination and auto-refresh.
### Badges, statuses, and highlights
The badge beside a requirement describes its processing or review state, such as **Pending action**, **Processing**, **Completed**, or **Failed**. It is distinct from:
* A red badge in a coverage view, which marks an unresolved coverage issue.
* A selected or visually highlighted row, which only indicates the current UI selection.
* Test-case type and decision badges inside Requirements Details.
There is no separate current Requirements control named **highlight flag**. If instructions use that phrase, identify the visible badge and its surrounding page before acting; do not treat a red coverage indicator as a requirement-processing status.
### Answering clarification questions
When a file has the **Pending action** status, click its name to open a clarification dialog. ContextQA's AI analyzed your requirements and needs additional context before generating test cases.
The dialog displays:
* The AI's analysis message explaining what it understood
* A list of clarification questions with text fields for your answers
You can either answer the questions and click **Submit**, or click **Skip & Generate Test Cases** to proceed without providing additional context.
***
## Requirement detail view
Click any file name in the list to open its detail view. The header displays:
* **File name** and **status badge**
* **Metadata row** — file type, test type (Web or Mobile), requirement code, creator name, and creation date
* **Generated test cases count**
* **Filter badges** — filter test cases by type (Positive, Negative, Edge, etc.) and status (Approved, Rejected, Pending)
* **Export** button — download the requirement data
* **Back** button — return to the library list
The detail view contains six tabs:
* [Test Cases](#test-cases-tab)
* [Questionnaire](#questionnaire-tab)
* [AI Analysis](#ai-analysis-tab)
* [Gaps](#gaps-tab)
* [Metadata](#metadata-tab)
* History (coming soon)
***
## Test cases tab
The default tab displays all test cases generated from the uploaded requirement file in a searchable, filterable table.
### Table columns
Each test case row displays:
| Column | Description |
| ------------- | ------------------------------------------------------------------------------------------------ |
| **Test Case** | Name and inline description (click to open the detail drawer) |
| **Type** | Color-coded test type badge (Positive, Negative, Edge, etc.) |
| **Status** | New or Existing |
| **Decision** | Pending, Approved, or Rejected |
| **Actions** | Row action buttons (see [Approving or rejecting test cases](#approving-or-rejecting-test-cases)) |
### Searching and filtering
Use the search bar to find test cases by name. Click the **Filter** button to open the filter panel and narrow results by type, status, or priority. Active filters appear as removable chips above the table. Filters persist across navigation within the same session.
### Reviewing a test case
Click any test case row to open the **test case detail drawer**. The drawer contains two tabs — **Details** and **Variables** — accessed through the segment control under the header.
**Header badges and actions:**
| Element | Description |
| ------------------ | --------------------------------------------------------------------- |
| **Status badge** | Current status (e.g., Pending, Approved, Rejected) |
| **Case ID** | Unique identifier (`UR-` prefix for pending, `C-` prefix for created) |
| **Type badge** | Color-coded test type |
| **Decision badge** | Pending review, Accepted, or Rejected (view mode only) |
| **Edit** button | Switch to edit mode (view mode only) |
| **Copy** button | Copy the test case name and ID to the clipboard |
| **Close** button | Close the drawer |
**Details tab:**
| Field | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------------ |
| **Prerequisite** | Linked prerequisite title, if one exists |
| **Name** | Test case name (editable in edit mode) |
| **Description** | Detailed description of the test scenario |
| **Test Type** | Classification dropdown (Positive, Negative, Edge, Field Validation, End to End, Functional, Boundary Value) |
| **Priority** | Priority level with color-coded badge (Critical, High, Medium, Low, or Unassigned) |
| **Variables in use** | Variables referenced in test steps, displayed as `${name}` badges (view mode) |
| **Steps** | Ordered list of test steps with expected results; variable references appear as inline chips |
**Variables tab:**
The Variables tab displays all variables as a key-value table. In view mode, each row shows the variable name and its current value. In edit mode, you can:
* Edit variable names and values inline
* Click **Add variable** to create a new row
* Delete a variable by clicking its remove button (a confirmation prompt appears if any steps reference the variable)
Validation feedback appears for duplicate names, invalid characters, and empty keys.
### Approving or rejecting test cases
From the test case detail drawer, you can:
1. Click **Approve & Move to Repository** to accept the test case and add it to your test case repository.
2. Click **Reject** to decline the test case.
3. Click the **Edit** icon in the header to modify the title, description, test type, priority, variables, or steps before making a decision.
For rejected test cases, click **Revert to Review** to return the test case to the pending state.
When editing, click **Save Changes** to keep your modifications or **Cancel Changes** to discard them. You can also press `Enter` to save or `Escape` to cancel. A confirmation dialog appears if you attempt to close the drawer with unsaved changes.
***
## Questionnaire tab
The Questionnaire tab displays the clarification questions that ContextQA's AI generated during requirement analysis, along with any answers you provided.
Each item shows the question text and an answer field. If no questions were generated, an empty state message appears.
***
## AI analysis tab
The AI Analysis tab provides a detailed breakdown of how ContextQA's AI interpreted your requirements document. The tab displays four information cards:
### AI understanding
A summary of what the AI understood from your requirements document. This appears as a highlighted section at the top of the tab.
### Assumptions made
A numbered list of assumptions the AI made during analysis. Review these to verify the AI correctly interpreted ambiguous or incomplete requirements.
### Coverage notes
A summary of which areas the generated test cases cover, with a bullet list of specific coverage points. Use this to verify that all critical requirements have corresponding test cases.
### Warnings and gaps
A list of potential issues the AI identified, such as:
* Requirements that could not be fully covered
* Ambiguous specifications that may need clarification
* Areas where additional test cases might be needed
### Confidence score
A progress bar showing how confident the AI is in its analysis (0–100%). A higher score indicates the requirements were clear and well-structured. The score includes a descriptive label explaining the confidence level.
***
## Gaps tab
The Gaps tab identifies areas where your requirements may not be fully covered by the generated test cases. Gaps appear as cards in a two-column grid layout.
### Gap cards
Each gap card displays:
* **Title** — what the gap is about
* **Similarity score** — a progress bar showing how closely existing test cases match this requirement area (lower scores indicate larger coverage gaps)
* **Tags** — requirement ID, test case priority, test case type, and prerequisite warnings
* **Why missing** — explanation of why this gap exists
* **View details** — opens the gap detail drawer
### Gap detail drawer
Click **View details** on any gap card to open a side panel with:
| Section | Description |
| --------------------------- | ------------------------------------------------------------------------------------------------ |
| **Similarity score** | A ring chart showing the similarity percentage with a descriptive explanation |
| **Summary** | Detailed summary of the coverage gap |
| **What's missing** | Numbered list of specific items not covered by existing test cases |
| **AI-suggested test cases** | Test cases the AI recommends to fill the gap, each with a confidence percentage and status badge |
### Adding suggested test cases
From the gap detail drawer:
* Click **Add to Test Cases** on an individual suggestion to add it to your test case repository.
* Click **Add All** in the footer to add all pending suggestions at once.
Suggestions that have already been added display an "Already Added" badge with the linked test case ID.
To dismiss a gap you do not need to address, click **Close** to return to the gap list.
***
## Metadata tab
The Metadata tab displays detailed information about the uploaded file, organized into four sections:
### File information
| Field | Description |
| -------------- | ------------------------------- |
| **File Type** | Format of the uploaded file |
| **File Size** | Size of the uploaded file |
| **Page Count** | Number of pages in the document |
| **Word Count** | Total word count |
| **Version** | Document version |
### Configurations
| Field | Description |
| -------------------------------- | ------------------------------------------------ |
| **Test Plan** | Associated test plan (if created during import) |
| **Test Suite** | Associated test suite (if created during import) |
| **Platform** | Target platform (Web or Mobile) |
| **Browser** or **Mobile Device** | Target browser or device (depends on platform) |
### Timestamps
| Field | Description |
| ----------------- | --------------------------------- |
| **Created By** | Team member who uploaded the file |
| **Created At** | Upload date and time |
| **Last Modified** | Most recent modification date |
### Labels
Displays any labels or tags associated with the requirement file. Click **+N** to expand and view all labels when more than five are assigned.
***
## Related documentation
* [Creating Test Cases](/web-testing/creating-test-cases) — How to import files and generate test cases
* [AI Test Generation](/ai-features/ai-test-generation) — All AI-powered test generation methods
* [Managing Test Suites](/web-testing/managing-test-suites) — Organize test cases into suites
* [Test Data Management](/web-testing/test-data-management) — Variables and data-driven testing
# Database Steps
How to add database verification steps to your test cases — run SQL queries, store results in variables, and assert expected values.
## Quick answer
How to add database verification steps to your test cases — run SQL queries, store results in variables, and assert expected values. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs and testers who need to verify backend data directly by running SQL queries during test execution.
{% endhint %}
Database steps let you execute SQL queries against a configured database environment and verify the results — all within a test case. Use them to confirm that a UI action actually wrote the correct data, to set up preconditions by checking existing records, or to validate data transformations that are not visible in the UI.
## Prerequisites
* You have created or opened a test case.
* A **database environment** is configured in **Environment & Data → Environments** with `type: Database` and valid connection credentials.
* You are familiar with the [Test Steps Editor](/web-testing/test-steps-editor) basics.
***
## Adding a database step
1. Open a test case and click **Add Step**.
2. In the step builder sidebar, select **Database**.
3. Configure the fields described below.
4. Click **Create Step** to add the step to your test case.
***
## Fields
| Field | Required | Description |
| ------------------------ | -------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| **Database Environment** | Yes | Select the database environment to connect to. Only environments configured with `type: Database` appear in this dropdown. |
| **Normal Environment** | No | Select a standard environment for variable resolution. Use this when your queries reference environment variables like `${ENV.TABLE_PREFIX}`. |
| **Queries** | Yes | One or more SQL queries to execute. Each query has its own variable name and optional assertions. |
### Query configuration
Each query row contains:
| Field | Description |
| ----------------- | ----------------------------------------------------------------------------------------------------------------- |
| **Query** | The SQL statement to execute. Supports variable substitution: `SELECT * FROM users WHERE email = '${userEmail}'`. |
| **Variable Name** | The variable that stores the query result. Reference it in later steps with `${variableName}`. |
| **Assertions** | Optional verification rules applied to the query result (see below). |
### Assertions
Each query can have one or more assertions to verify the returned data:
| Field | Description |
| --------------------- | ------------------------------------------------------------------------------------------------- |
| **JSON Path** | Path to the value in the result set to verify (e.g., `$.rows[0].status`). |
| **Verification Type** | The comparison operator. Default: `equals`. |
| **Expected Type** | The data type of the expected value: `string`, `number`, `boolean`, `null`, `object`, or `array`. |
| **Expected Value** | The value to compare against. |
***
## Running a query preview
Before saving the step, you can test your query directly in the step builder:
1. Enter your SQL query and select the **Database Environment**.
2. Click the **Run Query** button.
3. The query executes against the selected database, and the results display below the query field.
Use this to verify your query syntax and confirm the data you expect is present before adding assertions.
***
## Example: Verify a user was created
```
Step 1 (AI Agent): Navigate to the registration page
Step 2 (AI Agent): Fill in the registration form with test data
Step 3 (AI Agent): Click the Submit button
Step 4 (AI Verification): Verify the success message is displayed
Step 5 (Database):
Database Environment: QA Database
Query: SELECT email, status FROM users WHERE email = '${testEmail}'
Variable: newUser
Assertion: $.rows[0].status equals string "active"
```
After execution, reference the stored result in later steps:
* `${newUser.rows[0].email}` — the email value from the first row
* `${newUser.rows[0].status}` — the status value from the first row
***
## Example: Validate data after an API call
```
Step 1 (REST API): POST ${ENV.BASE_URL}/api/orders
Body: { "product": "Widget A", "quantity": 3 }
Store response in: orderResponse
Step 2 (Database):
Database Environment: QA Database
Query: SELECT quantity, total_price FROM orders WHERE id = '${orderResponse.body.orderId}'
Variable: orderRecord
Assertion 1: $.rows[0].quantity equals number 3
Assertion 2: $.rows[0].total_price equals number 29.97
```
***
## Advanced settings
| Setting | Description |
| -------------------- | ----------------------------------------------------------------------- |
| **Skip Step** | Skip this step during execution without removing it from the test case. |
| **Mark as Optional** | If enabled, a failure on this step does not fail the overall test case. |
***
## Tips & best practices
* **Use environment variables in queries** to keep test cases portable across environments. Reference `${ENV.DB_SCHEMA}` or `${ENV.TABLE_PREFIX}` instead of hardcoding schema names.
* **Add a wait step before database verification** if the data is written asynchronously. The UI action may return before the database commit completes.
* **Use the Run Query preview** to validate your SQL syntax before saving the step. This prevents execution failures caused by typos in column or table names.
* **Keep queries read-only.** While the step executes arbitrary SQL, avoid INSERT, UPDATE, or DELETE statements in verification steps. Use REST API steps for data setup and teardown.
* **Combine with assertions** to make database steps true verification steps. A query without assertions only stores data — it never fails on its own.
## Troubleshooting
**The Database Environment dropdown is empty** No environments with `type: Database` are configured. Go to **Environment & Data → Environments**, create a new environment, and set its type to **Database** with valid connection credentials (host, port, database name, username, password).
**Query fails with a connection error** Verify the database credentials in the environment configuration. Ensure the database server is accessible from the ContextQA execution network. If running behind a firewall, confirm that the execution agent has network access to the database host and port.
**Assertions pass but the data looks wrong** Check the JSON path syntax. Query results are returned as a JSON object — use `$.rows[0].columnName` to access the first row. Use the **Run Query** preview to inspect the exact result structure before writing assertions.
## Related pages
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Environments](/execution/environments)
* [Test Data Management](/web-testing/test-data-management)
* [Creating Test Cases](/web-testing/creating-test-cases)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Custom Code Steps
How to write and execute custom JavaScript code as test steps — for complex logic, calculations, and DOM interactions that go beyond natural language steps.
## Quick answer
How to write and execute custom JavaScript code as test steps — for complex logic, calculations, and DOM interactions that go beyond natural language steps. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs and developers who need to execute custom JavaScript within a test case for logic that cannot be expressed as a natural language step.
{% endhint %}
Custom code steps let you write JavaScript that executes during test runtime. Use them for complex calculations, custom data transformations, direct DOM manipulation, or any scenario where a natural language instruction is insufficient.
## Prerequisites
* You have created or opened a test case.
* You are familiar with the [Test Steps Editor](/web-testing/test-steps-editor) basics.
* You have working knowledge of JavaScript.
***
## Adding a custom code step
1. Open a test case and click **Add Step**.
2. In the step builder sidebar, select **Custom Code**.
3. Select **JavaScript** from the **Language** dropdown.
4. Write your code in the code editor.
5. Click **Create Step** to add the step to your test case.
***
## Fields
| Field | Description |
| --------------- | --------------------------------------------------------------------------------------------- |
| **Language** | The scripting language. Currently supports **JavaScript**. |
| **Code** | The JavaScript code to execute at runtime. |
| **Description** | A plain-English summary of what the code does. Appears in the step list and execution report. |
***
## Example: Generate a unique identifier
```javascript
// Generate a unique email for registration testing
const timestamp = Date.now();
const uniqueEmail = `testuser_${timestamp}@example.com`;
return uniqueEmail;
```
***
## Example: Calculate and verify a total
```javascript
// Calculate expected cart total from individual prices
const prices = [19.99, 24.50, 7.99];
const expectedTotal = prices.reduce((sum, price) => sum + price, 0).toFixed(2);
return expectedTotal;
// => "52.48"
```
***
## Example: Parse and transform data
```javascript
// Extract order IDs from a JSON response stored in a variable
const response = JSON.parse(context.variables.orderListResponse);
const orderIds = response.body.orders.map(order => order.id);
return orderIds.join(', ');
```
## Use an AI Ask result in custom code
An **AI Ask** action can save its answer to a runtime variable. A later Custom Code step can consume that value:
1. Add an **AI Ask** step, write a focused question, and set its output variable to a valid name such as `invoiceSummary`.
2. Place the Custom Code step after the AI Ask step.
3. Read the stored value by its exact, case-sensitive name—for example, `context.variables.invoiceSummary`.
4. Validate or parse the value before using it in a calculation or request.
```javascript
const summary = String(context.variables.invoiceSummary ?? '').trim();
if (!summary) {
throw new Error('AI Ask did not return invoiceSummary');
}
return summary.toUpperCase();
```
AI output is generated text, so do not treat it as a trusted number, selector, command, or JSON object without validation. For an exact value already displayed in the DOM, use **Store text from the element … into variable …** instead of AI Ask.
## Calculation and assertion pattern
For a calculation such as `total = subtotal + tax`, keep capture, calculation, and verification separate:
1. Store the displayed subtotal and tax in runtime variables.
2. Use Custom Code to parse the currency strings and calculate the expected total with the application's rounding rule.
3. Store or return the calculated value using the output supported by the selected Custom Code template.
4. Add a verification step that compares the displayed total with that expected value.
For a visual, non-critical check, an AI Verification prompt can read: `Verify that the displayed Total equals Subtotal plus Tax, using two decimal places.` For payment, ledger, or settlement validation, use an exact numeric assertion or API response validation instead of relying only on visual AI reasoning.
***
## Advanced settings
| Setting | Description |
| -------------------- | ----------------------------------------------------------------------- |
| **Skip Step** | Skip this step during execution without removing it from the test case. |
| **Mark as Optional** | If enabled, a failure on this step does not fail the overall test case. |
***
## Tips & best practices
* **Add a descriptive Description field** so the step is understandable in the execution report without reading the code.
* **Keep code minimal.** Custom code steps are for logic that natural language steps cannot handle. If a task can be described in plain English, use an AI Agent step instead.
* **Use custom code for data transformation** between steps — formatting dates, calculating expected values, parsing complex response structures.
* **Avoid long-running operations.** The step has a default timeout of 30 seconds. If your code needs more time, increase the step timeout.
## Troubleshooting
**Custom code step fails with a syntax error** Check the browser console output in the execution report. JavaScript syntax errors surface as step failures with the error message in the step details. Validate your code in a browser console before pasting it into the step editor.
**Variables from previous steps are not accessible** Verify the variable name is spelled correctly and that the step that sets the variable runs before the custom code step. Variable names are case-sensitive.
## Related pages
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Test Data Management](/web-testing/test-data-management)
* [Creating Test Cases](/web-testing/creating-test-cases)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Document Generation Steps
How to generate TXT, CSV, and Excel files during test execution for file upload, import, export, and document-dependent workflows.
## Quick answer
Add a **Document** step when a test must create a file before uploading or validating it. Choose `txt`, `csv`, or `excel`, provide a file name and output variable, map each field to a static value, variable, expression, or reference, and use the output variable in the later upload step. Choose `excel` with an `.xlsx` name for workbook-based import flows.
{% hint style="info" %}
**Who is this for?** Testers and SDETs who need to generate TXT, CSV, or Excel files dynamically during test execution for use in file upload, import, or data processing workflows.
{% endhint %}
Document generation steps create files during test runtime with configurable content. Use them when your test needs to upload a file with specific data, verify an import workflow with known values, or test document processing features with controlled inputs.
## Prerequisites
* You have created or opened a test case.
* You are familiar with the [Test Steps Editor](/web-testing/test-steps-editor) basics.
***
## Adding a document generation step
1. Open a test case and click **Add Step**.
2. In the step builder sidebar, select **Document**.
3. Configure the document type, file name, and data mappings.
4. Click **Create Step** to add the step to your test case.
***
## Fields
| Field | Required | Description |
| ------------------- | -------- | ----------------------------------------------------------------------------- |
| **Document Type** | Yes | The file format to generate: `txt`, `csv`, or `excel` (an Excel workbook). |
| **Output Variable** | Yes | The variable name that stores the generated file reference. Default: `Input`. |
| **File Name** | Yes | The name of the generated file (e.g., `test-data.csv`). |
### TXT-specific fields
| Field | Description |
| ---------------------- | --------------------------------------------------- |
| **Separator** | The string used to separate values within the file. |
| **File Format Header** | Header content written at the top of the file. |
### CSV-specific fields
| Field | Description |
| ------------- | ------------------------------------------------------------------------------------------------------ |
| **Delimiter** | The character used to separate columns: **Comma** (`,`), **Semicolon** (`;`), **Tab**, or **Pipe** (\` |
### Excel-specific behavior
Select **excel** when the application requires a spreadsheet workbook rather than delimited text. Define the column names and values with the same data-mapping rows used for CSV. Use an `.xlsx` file name, such as `users-import.xlsx`, so the generated artifact is easy to identify in later upload steps and run results.
### Template source
You can populate the document from a template or define content from scratch:
| Option | Description |
| -------------- | ----------------------------------------------------------------------------------- |
| **Create New** | Define a new template with a name and description. The template is saved for reuse. |
| **Existing** | Select a previously saved template by ID. |
| **Upload** | Upload a template file to use as the base. |
### Data mappings
Each mapping row defines a column or field in the generated file:
| Field | Description |
| -------------- | ------------------------------------------------------------------------------------------------------------------------- |
| **Key** | The column or field name. |
| **Value Type** | How the value is sourced: **Variable**, **Static**, **Expression**, **Reference**, or **Text** (legacy alias for Static). |
| **Value** | The actual value or variable reference (e.g., `${testEmail}` for Variable type, or `John Doe` for Static type). |
***
## Example: Generate a CSV for bulk import testing
```
Step 1 (Document Generation):
Document Type: csv
File Name: users-import.csv
Delimiter: Comma
Template Source: Create New
Mappings:
| Key | Value Type | Value |
| email | Variable | ${testEmail} |
| firstName | Static | Test |
| lastName | Static | User |
| role | Static | viewer |
Step 2 (AI Agent): Click the Import Users button
Step 3 (AI Agent): Upload the file ${Input} to the file upload area
Step 4 (AI Verification): Verify the import success message is displayed
```
***
## Example: Generate a TXT configuration file
```
Step 1 (Document Generation):
Document Type: txt
File Name: config.txt
Separator: =
Output Variable: configFile
Mappings:
| Key | Value Type | Value |
| host | Variable | ${ENV.APP_HOST} |
| port | Static | 8080 |
| debug | Static | true |
Step 2 (AI Agent): Upload ${configFile} to the Configuration Upload field
Step 3 (AI Verification): Verify the configuration was applied successfully
```
***
## Example: Generate an Excel workbook for an import flow
```
Step 1 (Document Generation):
Document Type: excel
File Name: users-import.xlsx
Output Variable: importWorkbook
Mappings:
| Key | Value Type | Value |
| email | Variable | ${testEmail} |
| firstName | Static | Test |
| role | Static | viewer |
Step 2 (AI Agent): Upload ${importWorkbook} to the spreadsheet import field
Step 3 (AI Verification): Verify the imported user appears in the preview
```
***
## Advanced settings
| Setting | Description |
| -------------------- | ----------------------------------------------------------------------- |
| **Skip Step** | Skip this step during execution without removing it from the test case. |
| **Mark as Optional** | If enabled, a failure on this step does not fail the overall test case. |
***
## Tips & best practices
* **Use Variable value types** to make generated documents dynamic. Reference test data profile columns or environment variables so the file content changes per test run.
* **Save templates for reuse.** If multiple test cases need the same file structure with different data, create a template once and select it with the **Existing** option in subsequent steps.
* **Reference the output variable** in later AI Agent steps to upload the generated file. The variable holds the file reference that the upload step uses.
* **Match the file format** to what your application expects. If the import feature requires semicolon-delimited CSV, set the delimiter to **Semicolon**. If it validates workbook uploads, choose **excel** and use an `.xlsx` file name.
## Troubleshooting
**The uploaded file is rejected by the application** Check that the document type, delimiter, and column names match the format your application expects. Generate the file, download it from the execution report artifacts, and inspect its contents.
**Variable values are not substituted in the file** Verify the variable name syntax (`${variableName}`) and that the referenced variable is set by an earlier step. Variable names are case-sensitive.
**Template not found** If using the **Existing** template option, confirm the template was saved in the same workspace. Templates are scoped to the workspace version.
## Related pages
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Test Data Management](/web-testing/test-data-management)
* [Creating Test Cases](/web-testing/creating-test-cases)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Managing Test Suites
Create, review, update, clone, and safely delete test suites; manage suite membership, folders, labels, platforms, and prerequisites.
## Quick answer
Create, review, update, clone, and safely delete test suites; manage suite membership, folders, labels, platforms, and prerequisites. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers and SDETs who organize reusable test cases into feature, smoke, or regression collections before assigning them to a test plan.
{% endhint %}
A test suite is a reusable collection of test cases. Suites organize coverage; test plans assign suites to browsers or devices and provide the executable configuration.
## Interactive course: create suites and start a test plan
This first course segment shows how reusable cases become an organized suite and how that suite begins its transition into an executable test plan. No ContextQA account is required to follow the captured workflow.
{% embed url="" %}
### What to notice
* The suite defines the coverage boundary and target platform before execution settings are applied.
* Test cases remain reusable library assets even when they belong to more than one suite.
* Labels, folders, prerequisites, and descriptions make ownership and release purpose easier to understand.
Continue with [Part 2: configure and run the test plan](/web-testing/test-plans#interactive-course-configure-and-run-a-test-plan).
## Before you begin
* Open **Plans → Test Suites** in the left navigation.
* Create test cases first if you want to populate the suite immediately. You can also create an empty suite and add cases later.
* Decide whether the suite targets **Web App**, **Mobile**, or **API** tests. The selected platform controls which compatible cases can be added.
## Find and review suites
The Test Suites page supports **List** and **Modular** views. Search by suite ID, title, or label, or use **Filter** to narrow the list. Each row shows the suite ID, name, platform, case count, latest result, dates, folder, and a **More actions** menu.
Click a suite to open its detail page. The header shows its ID, case count, platform, folder, and latest result. Use these tabs:
| Tab | Use |
| ---------------------- | -------------------------------------------------------------------------------- |
| **Test Cases** | Review and change the cases in the suite. |
| **Used in Test Plans** | See which plans currently reference the suite. |
| **History** | Review changes to the suite. |
| **Settings** | Update the suite name, prerequisites, folder, platform, labels, and description. |
## Create a test suite
1. On the Test Suites page, click **Create Test Suite**.
2. Complete **Suite Basics**:
* **Suite Name** (required): use a short name that communicates the feature and purpose.
* **Folder / Location**: leave the suite unorganized or place it in an existing folder.
* **Prerequisites** (optional): select prerequisite test cases that must complete before the suite.
* **Labels** (optional): add searchable classification such as `smoke`, `checkout`, or `release-gate`.
* **Select Target Platform**: choose **Web App**, **Mobile**, or **API**.
* **Description**: explain the coverage, owner, and intended trigger.
3. Choose one of the following:
* **Add Test Cases** to continue to the case-selection step.
* **Skip & create empty** to save the suite now and populate it later.
4. If adding cases, search or filter the compatible cases, select them, and finish creating the suite.
After ContextQA creates the suite, it opens the new suite's detail page so you can immediately review its cases, relationships, history, and settings.
### Example
| Field | Example value |
| ----------- | ----------------------------------------------------------------------------- |
| Suite name | `Checkout smoke` |
| Folder | `Commerce / Checkout` |
| Label | `smoke` |
| Platform | `Web App` |
| Description | `Critical checkout coverage for pull-request validation. Owner: QA Platform.` |
The example below shows the same fields on an existing suite's **Settings** tab.

## Add or remove test cases
1. Open the suite and stay on **Test Cases**.
2. Click **Manage Test Cases**.
3. Use **List** or **Modular** view, then search by test case ID or name. The **All**, **Added**, and **Not Added** tabs make the current membership explicit.
4. Select cases to add, or clear selected cases that should be removed.
5. Review the **to add** and **to remove** totals in the footer.
6. Click **Apply changes**.
Changing suite membership does not delete a test case from the workspace library. The case can remain in other suites.
{% hint style="warning" %}
Before removing a case, check **Used in Test Plans** and consider the effect on plan coverage and case totals.
{% endhint %}
## Update a suite
1. Open the suite.
2. Select **Settings**.
3. Change the name, prerequisite cases, folder, target platform, labels, or description.
4. Click **Save Changes**.
Use the **Used in Test Plans** tab after changing the platform or membership to confirm that every consuming plan still has the intended coverage.
## Create a test suite folder
The **New Folder** action is available only in **Modular** view.
1. Open **Plans → Test Suites**.
2. Select **Modular**.
3. To create a top-level folder, click **New Folder** in the page toolbar. To create a folder from the folder tree, use the **+** action in the **Folders** panel.
4. Enter the **Folder name** and click **Create folder**.
Use a folder for stable product or functional areas, such as `Commerce / Checkout`. Creating a folder does not move suites automatically; move existing suites into it after creation.

## Move suites into a folder
Folders give the Test Suites page a hierarchy. You can place a suite in a folder when you create it, from its **Settings** tab, or by moving one or more suites together from the selection action bar.
1. On the Test Suites page, select the checkbox next to each suite you want to move. A selection action bar appears and shows the number of selected suites.
2. Click **Move to Folder**.
3. In the move dialog, select the destination folder. To leave the suites unorganized, select the root location.
4. Confirm the move. ContextQA moves the selected suites, reports how many moved, and refreshes the list.
To deselect every suite without moving anything, click **Clear selection** (the **X** icon) in the selection action bar.
{% hint style="info" %}
The selection action bar also provides **Delete** for the selected suites and **Edit** when exactly one suite is selected.
{% endhint %}
## Clone a suite
Cloning is useful when a new suite should start with the same membership as an existing one.
1. On the Test Suites page, open the suite's **More actions** menu.
2. Select **Clone suite**.
3. Give the clone a distinct name, review its configuration and membership, and save it.
4. Update any test plans that should use the clone.
## Delete a suite
1. Open the suite's **More actions** menu and select **Delete suite**, or open the suite's **Settings** tab and use the delete action.
2. Review the confirmation carefully. ContextQA warns that the suite and its associated run reports will be permanently removed.
3. Type `delete` to enable **Yes, Delete**.
4. Click **Yes, Delete** only after confirming that no active plan depends on the suite.
{% hint style="danger" %}
Deleting a suite cannot be undone. Test cases remain in the test case library, but the suite and its associated run reports do not.
{% endhint %}
## Practical organization patterns
| Pattern | Example | Use |
| ------------------------- | --------------------- | --------------------------------------------- |
| `[Feature] smoke` | `Checkout smoke` | Small, release-blocking coverage. |
| `[Feature] regression` | `Checkout regression` | Broad coverage for scheduled or release runs. |
| `[API resource] contract` | `Orders API contract` | API coverage grouped by resource. |
| `[Platform] [feature]` | `iOS onboarding` | Mobile coverage with an explicit platform. |
Use folders for hierarchy and labels for cross-cutting concerns. For example, put suites in `Commerce / Checkout`, then use `smoke` and `regression` labels to distinguish execution scope.
## Troubleshooting
**A case is missing from Manage Test Cases**
Confirm that the suite platform matches the test case type, clear filters, and search by the test case ID.
**Apply changes is disabled**
The button becomes active only after at least one membership change. Select a case to add or remove.
**The suite appears in a plan with zero cases**
Open the suite, select **Manage Test Cases**, and add cases. An empty suite can be assigned to a plan but contributes no executable cases.
**A suite is difficult to find**
Use a distinct name, move it to the appropriate folder, and add labels that match how the team searches for coverage.
## MCP automation
Use `get_test_suites` to discover suite IDs and `create_test_suite` to create a suite from test case IDs. Suite execution happens through a test plan. The current MCP suite/plan tools do not expose suite update or delete operations; use the portal for those actions.
See [Test Suites & Plans Tools](/mcp-server/tool-reference/suites-and-plans) for parameters and examples.
## Related pages
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Test Plans](/web-testing/test-plans)
* [Running Tests](/execution/running-tests)
* [Scheduling Tests](/execution/scheduling)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Test Plans
Create and run ContextQA test plans, monitor execution capacity and live progress, stop active runs, and manage suites, devices, settings, and schedules.
## Quick answer
A ContextQA test plan is the reusable configuration that runs one or more test suites against selected browsers or devices, an environment, and saved execution settings. Open **Plans → Test Plans**, select a plan, review the **Running**, **Capacity**, and **Queued** values, and choose **Run Now**. During execution, open **Runs → Live execution** to see running and queued cases; use **Stop Run** when the remaining work should not continue.
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who turn reusable suites into browser or device-specific execution plans.
{% endhint %}
A test plan is the executable configuration in ContextQA. It maps one or more test suites to browsers or devices and defines parallelism, timeouts, screenshots, environments, knowledge, notifications, and recovery behavior.
[Watch the suites-and-test-plans walkthrough](https://drive.google.com/file/d/1sZGxrvhFYCIyAL5iKCOi6y7upmpluS-2/preview).
## Interactive course: configure and run a test plan
This second course segment continues from an organized suite into browser or device mapping, execution settings, and a repeatable plan run. Start with [Part 1](/web-testing/managing-test-suites#interactive-course-create-suites-and-start-a-test-plan) if you have not created the suite yet.
{% embed url="" %}
### What to notice
* A test plan keeps its suites, execution targets, environment, and recovery settings together.
* Saved configuration makes on-demand, scheduled, and pipeline-triggered runs comparable.
* Run history and live execution provide shared visibility without changing the underlying tests.
## Before you begin
* Create at least one [test suite](/web-testing/managing-test-suites). A suite can be empty while you configure a plan, but it will contribute zero executable cases.
* Open **Plans → Test Plans**.
* Decide which browser or device should run each suite and whether the plan needs an environment or knowledge base.
## Find and review plans
The page has **Test Plans** and **Schedules** tabs. Search by ID, title, or label, use **Filter** to narrow the list, or combine a search term with filters to find a precise subset. ContextQA applies both conditions to the same result set. Clear the search term and active filter chips to return to the full list.
The execution-capacity card in the page header shows the organization name and three live values: **Running**, **Capacity**, and **Queued**. The ring summarizes running executions against the organization's parallel limit. Auto-refresh is on by default; use the refresh control to pause or resume it. Review this card before starting a large plan so you can tell whether it can begin immediately or will wait for capacity.
A plan row shows its name, suite and case totals, latest run result, and actions for **Schedule**, **Reports**, **Clone**, and **Run**.
Click a plan name to open its detail page. The header provides **Run Now** and a menu for **Copy**, **Edit**, and **Delete**. The redundant **Run Manually** action is no longer shown on the test-plan detail page. The summary shows suite and case totals and the current schedule state.
The detail page includes:
| Tab | Use |
| --------------------- | ----------------------------------------------------------------------------------------------------------- |
| **Overview** | Review plan metadata and the suite-to-browser/device mapping. Add suites or view their cases. |
| **Runs** | Search and review recent runs. During an active run, switch between **Run history** and **Live execution**. |
| **Reports** | Open run reports. |
| **Schedules** | Create and manage recurring execution. |
| **CI / CD** | Review pipeline integrations and programmatic triggers. |
| **Settings** | Update execution, notification, and recovery settings. |
| **Execution History** | Compare execution outcomes over time. |
| **Version History** | Audit plan configuration changes. |

## Review CI/CD options
Open a plan and select **CI / CD** to review the automation surfaces currently presented by your workspace.
The verified production page lists these integration targets: **GitHub**, **GitLab**, **Bitbucket**, **Azure DevOps**, **CircleCI**, **Codeship**, **Bamboo**, **Jenkins**, **AWS**, **TravisCI**, and **Generic shell**. It also presents two REST operations:
* **Start Test Plan** — returns a run ID for status polling.
* **Check Status** — returns status, result, and suite breakdown information.

{% hint style="warning" %}
The verified production page does not publish REST endpoint paths. Do not build a pipeline from portal network calls or legacy examples that use `/auth/login`, `/testplans/{id}/execute`, or `/executions/{id}/status`. Use only a public API contract displayed in your workspace or supplied through an official ContextQA reference.
{% endhint %}
For an automated client, create a dedicated, narrowly scoped [API token](/administration/api-tokens) and store it in the pipeline's secret manager. The token is a credential; it does not define which endpoint or payload to use. Configure the plan's suites, browsers or devices, environment, and recovery settings in ContextQA before connecting the external pipeline.
## Create a test plan
Click **New Test Plan** to open the three-step wizard.
### Step 1: Create Test Plan
Enter the plan's identity and presentation settings:
* **Test Plan Name** (required)
* **Labels** and **Description** (optional)
* **Hide on Dashboard**
* **Send Notification** for email and connected Slack notifications when the plan runs
* **Viewport**: Desktop, Laptop, Tablet, or Mobile
* **Resolution**
Example:
| Field | Example value |
| ----------- | ----------------------------------------------------------------------------------- |
| Name | `Checkout PR gate` |
| Description | `Runs the checkout smoke suite before each production release. Owner: QA Platform.` |
| Viewport | `Desktop` |
| Resolution | `Full HD (1920×1080)` |
Click **Next**.
### Step 2: Test Machines & Suites Selection
1. Click **Add Test Suites**.
2. Search by suite name and optionally filter by label.
3. Select suites in **Available Test Suites**, move them to **Selected Test Suites**, and click **Add**.

4. Select one or more suite rows and click **Add Machine/Device**.
5. Enter a configuration name, such as `Chrome desktop`.
6. Choose the test lab type, platform, and browser or device. Browser choices can include Firefox, Safari, Microsoft Edge, Chromium, and Chrome (Beta), depending on workspace availability.
7. Click **Create** to attach the machine or device to the selected suites.
8. Repeat the mapping when different suites need different targets, then click **Next**.

{% hint style="info" %}
A plan can contain multiple machine or device configurations. The same suite can be mapped to more than one target for cross-browser or cross-device coverage.
{% endhint %}
### Step 3: Test Plan Settings
Set **Parallel Execution** to the number of execution nodes the plan may use. Start with `1` while validating a new plan.
Expand **Additional Settings** to configure:
| Setting | Purpose |
| -------------------------- | ---------------------------------------------------------- |
| **Page Load Timeout** | Seconds to wait for navigation to complete. |
| **Element Timeout** | Seconds to wait for a target element. |
| **Environments** | Supplies environment-specific URLs and variables. |
| **Capture Screenshots** | Controls when step screenshots are captured. |
| **Knowledge Base** | Supplies application context to the execution agent. |
| **Proxy Profile** | Routes the plan through a reusable organization proxy. |
| **Remote Browser Profile** | Executes the plan against a saved remote browser endpoint. |
Expand **Recovery Actions** to configure:
| Failure condition | Available responses |
| ------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Major test step failure | Abort and run the next test case; report and continue to the next test step. |
| Test step prerequisite failure | Abort and run the next test case; report and continue to the next test step. |
| Test case prerequisite failure | Abort the test plan; report and continue to the next test case. |
| Test case abort | Clean up and reuse the current session; start with a new session. |
| Test suite prerequisite failure | Abort the test plan; report and continue to the next suite. |
| Rerun on failure | None; all test cases; all failed and not-executed test cases. The targeted option includes cases skipped because an earlier failure stopped their execution. |

Click **Create**. ContextQA opens the plan's **Overview** page after saving it.
## Update a test plan
Use either update path, depending on what you need to change.
### Edit details, mappings, or creation settings
1. Open the plan.
2. Open the header menu and select **Edit**.
3. Move through the same three-step wizard. Change the name, description, labels, dashboard visibility, notifications, viewport, suite-to-device mappings, or plan settings.
4. Click **Update** on the final step.
### Edit runtime settings directly
1. Open the plan and select **Settings**.
2. Change **Parallel Nodes**, screenshot capture, page or element timeouts, knowledge base, environment, notification toggles, or recovery actions.
3. Click **Save Changes**. Use **Discard** to abandon unsaved changes.
To clear the plan's selected knowledge base, choose **None** in **Knowledge Base** and save. This removes the plan-specific selection instead of retaining its prior value.
ContextQA records plan changes in **Version History**. Use this tab to audit changes and, when available, compare or restore a prior plan version.
## Change suite membership
* To add coverage from **Overview**, click **Add Test Suite**, choose suites, and assign the required browser or device configuration.
* To inspect membership without editing it, click **View Test Cases** on a suite row.
* To remove or remap suites, open **Edit** and use step 2 of the wizard.
After any membership change, confirm the suite and test case totals shown in the header.
## Clone or copy a plan
Use **Clone** from the Test Plans list or **Copy** from the plan header menu when a new plan should start from an existing configuration. Give the copy a distinct name, then review its suites, devices, environment, notifications, and schedule before running it.
## Run and monitor a plan
* Use **Run Now** for an immediate execution using the saved configuration.
* While the plan is queued or executing, the run control changes to **Stop Run**. Select it when the remaining cases should not continue.
* Open **Runs** and select **Live execution** to monitor the active plan. The summary shows the running and queued counts, run ID, and elapsed start time. Executing cards identify the test case, suite, and browser or device; the queue lists cases waiting for a slot.
* Select the run summary to open its report. After the run finishes, use **Run history** to search by ID, title, or label, refresh the list, and switch between list and card views.
* Use **Reports** for run evidence and **Execution History** for outcome trends.
Running tests changes execution state and can consume capacity. Verify the target environment, data, and device mapping before starting a run.
{% hint style="info" %}
**Run Now** is disabled when the plan contains zero executable test cases. Add cases to a selected suite before trying again. An already queued run can still be stopped.
{% endhint %}
## Schedule a plan
Open **Schedules** on the plan detail page or use **Schedule** from the list. Create a schedule with a name, start date and time, recurrence, and notification recipient. Existing schedules can be activated, paused, edited, run immediately, or deleted.
For a dedicated walkthrough, see [Scheduling Tests](/execution/scheduling).
## Delete a test plan
1. Open the plan.
2. Open the header menu and select **Delete**.
3. Review the confirmation. ContextQA warns that the plan and all associated run reports will be permanently removed.
4. Type `delete` to enable **Yes, Delete**.
5. Click **Yes, Delete** only when the plan and its historical reports are no longer required.

{% hint style="danger" %}
Deleting a test plan cannot be undone. Deleting the plan does not delete its underlying suites or test cases, but it removes the plan and its associated run reports.
{% endhint %}
## MCP automation
The ContextQA MCP server supports this workflow:
1. Discover or create suites with `get_test_suites` and `create_test_suite`.
2. Discover browsers or mobile devices with `get_available_devices`.
3. Create the plan with `create_test_plan` and map each device configuration to one or more suite IDs.
4. Run it with `execute_test_plan`.
5. Poll with `get_test_plan_execution_status`; use `rerun_test_plan` when a previous execution should run again.
The current MCP suite/plan tools do not expose update or delete operations. Use the portal for those actions. See [Test Suites & Plans Tools](/mcp-server/tool-reference/suites-and-plans) for exact parameters and examples.
## Troubleshooting
**Add Machine/Device is disabled**
Select at least one suite row first.
**Next is blocked on the suite and machine step**
Confirm that at least one selected suite has a browser or device configuration.
**A suite contributes zero test cases**
Open the suite and use **Manage Test Cases** to add compatible cases.
**The plan is missing from the dashboard**
Open **Settings** and turn off **Hide on Dashboard**.
**Search and filters return no plans**
Clear the search term and remove active filter chips one at a time. Search and filters are cumulative, so a plan must satisfy both when they are used together.
**A run does not start**
If the run controls are disabled, confirm that the plan has at least one executable test case. Otherwise, review the execution-capacity card for queued work, confirm that another run is not already active, and verify that the mapped browser or device is available.
## Related pages
* [Managing Test Suites](/web-testing/managing-test-suites)
* [Running Tests](/execution/running-tests)
* [Scheduling](/execution/scheduling)
* [Parallel Execution](/execution/parallel-execution)
* [Environments](/execution/environments)
* [Proxy and remote browser profiles](/execution/proxy-and-remote-browser-profiles)
* [Mobile Test Plans](/mobile-testing/mobile-test-plans)
* [Integrations Overview](/integrations/integrations)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and run test plans for your web application.
{% endhint %}
# Test Data Management
How to manage local variables, global variables, test data profiles, environment parameters, API response variables, and random functions in ContextQA for data-driven and parameterized testing.
## Quick answer
How to manage local variables, global variables, test data profiles, environment parameters, API response variables, and random functions in ContextQA for data-driven and parameterized testing. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers and SDETs who need parameterized, data-driven testing — running the same test with multiple data sets without duplicating test cases.
{% endhint %}
ContextQA provides four complementary data management mechanisms: local variables scoped to one test case, global variables shared across the workspace, environment parameters that vary between deployment targets, and test data profiles for data-driven testing. Insert values through the step editor's data or parameter picker whenever possible. The visible syntax depends on the source: an environment value such as `baseURL` appears as `*|baseURL|*`, while a field captured from an earlier API response uses a runtime expression such as `${loginResult.body.token}`.
[Watch the local-versus-global variables walkthrough](https://drive.google.com/file/d/1iX_UkzEWYG52QiNoIl7em5qnNrxV7oeW/preview) and the [environments-and-profiles walkthrough](https://drive.google.com/file/d/1UbcQCoDLHLrjbau3Jfb9HqGF3lnsGR-m/preview).
{% hint style="success" %}
**Try the interactive walkthrough:** follow the guided workflow below to see where each variable scope is configured and when to use it. No ContextQA account is required.
{% endhint %}
{% embed url="" %}
### What to notice in the demo
* Local variables hold temporary values for one test case.
* Global variables make approved, non-secret values reusable across a workspace.
* Choosing the narrowest useful scope reduces duplicated setup and accidental coupling between tests.
For values that must be fresh and unique on every run — a new email address, a current timestamp, a random amount — ContextQA also provides [random functions](#generating-random-test-data-with-random-functions), which generate a new value each time the test executes.
{% hint style="info" %}
Global variables, environment variables, and test data profiles are managed together in the [Environment Data Management](/web-testing/environment-data-management) workspace. This page explains how each variable type resolves inside test steps.
{% endhint %}
## Prerequisites
* You have at least one test case created.
* You have access to the workspace settings (you are a workspace member with Editor or Admin role).
* For data profiles: you have an environment and a test case that can use the selected profile rows.
***
## Variable naming rules
Every variable name you define — local variables, global variables, environment parameters, test data profile columns, and the variables that store an API response or a step's output — follows one consistent set of naming rules. ContextQA validates the name as you type and blocks saving until the name is valid, so a malformed name never reaches a test run where it is harder to debug.
### Format rules
A valid variable name:
* Starts with a letter (`A`–`Z`, `a`–`z`) or an underscore (`_`).
* Contains only letters, numbers, and underscores after the first character.
* Contains no spaces or other special characters.
* Is case-sensitive — `orderId` and `orderid` are two different variables.
| Example | Valid? | Reason |
| ----------- | ------ | ---------------------------------------------------- |
| `orderId` | Yes | Starts with a letter; letters and digits only |
| `_token` | Yes | A leading underscore is allowed |
| `user_2` | Yes | Digits are allowed after the first character |
| `2ndUser` | No | Cannot start with a number |
| `user name` | No | Spaces are not allowed |
| `user-name` | No | Hyphens and other special characters are not allowed |
| `123` | No | Cannot be only numbers |
### Reserved keywords
A variable name cannot match a reserved keyword. Reserved keywords are identifiers that ContextQA and the underlying test runtime already use — JavaScript keywords, runtime globals, and internal execution variables. Naming a variable after one of them shadows the built-in and breaks the generated test, so ContextQA rejects these names.
Reserved keywords are matched case-insensitively, so `os`, `OS`, and `Os` are all rejected.
Common reserved keywords include:
* Runtime globals such as `os`, `path`, `fs`, `moment`, `shell`, `otpauth`, and `page`.
* JavaScript keywords such as `const`, `let`, `function`, `return`, `class`, and `await`.
* HTTP method names such as `get`, `post`, `put`, and `delete`.
If a name is rejected as reserved, add a prefix or suffix to make it unique — for example, use `osName` instead of `os`, or `userPath` instead of `path`.
### Referencing nested values
When you *reference* a variable that holds structured data, you can access its members and array elements with dot and index notation — `${loginResponse.body.token}` or `${items[0]}`. This applies only where you reference a variable. When you *declare* a variable name, the name itself must be a plain identifier with no `.` or `[]`.
### Error messages
When a name breaks a rule, the field shows the specific reason:
| Message | Cause | Fix |
| ------------------------------------------------------------------------------------------- | ---------------------------------------------- | -------------------------------------------------- |
| `Name cannot start with a number.` | The name begins with a digit | Start with a letter or underscore |
| `Name cannot start with a special character.` | The name begins with a symbol | Start with a letter or underscore |
| `Name cannot be only numbers.` | The name contains only digits | Include at least one letter or underscore |
| `Name can only contain letters, numbers, and underscores, no spaces or special characters.` | The name contains a space or special character | Remove spaces and symbols; use underscores instead |
| `Name cannot be a reserved keyword.` | The name matches a reserved keyword | Choose a different, unique name |
{% hint style="info" %}
The AI Agent step's **What should the agent achieve?** field phrases these same messages as "Variable name …" instead of "Name …". The rules are identical.
{% endhint %}
***
## Local Variables
Local variables are scoped to a single test case. They exist only during the execution of that test case and are not visible to any other test case. Use local variables for values that are specific to one test scenario — a dynamically generated ID, a test-run timestamp, an intermediate value computed from an API response.
### Defining Local Variables
1. Open the test case.
2. Select the **Variables** tab in the test editor.
3. Select the add-variable action.
4. Enter the variable **Name** and optional **Default Value**.
5. Save the test case.
Alternatively, local variables are created implicitly when a REST API Call step stores its response: set "Store response in variable" to `myVar` and the variable `myVar` becomes available in all subsequent steps.
### Using Local Variables in Steps
Use the **Runtime** or variable picker in the step editor to insert a local variable into a supported field. The picker preserves the exact name and syntax expected by that field.
For example, choose a local `userId` from the Runtime picker when a later step needs the identifier captured earlier in the same test.
### Setting a Local Variable Dynamically
You can set or update a local variable at runtime using a **Set Variable** action in an AI Agent step:
```
Set the variable searchTerm to "blue running shoes"
```
Or capture a value displayed on the page:
```
Read the Order ID displayed on the confirmation page and store it as ${capturedOrderId}
```
The AI agent reads the specified element's text content and assigns it to the named variable. This captured value can then be used in subsequent steps or REST API calls.
For a deterministic DOM-text capture that does not ask AI to infer the value, choose the action template **Store text from the element … into variable …**:
1. Select the page element whose text you need.
2. Enter a valid local variable name, such as `orderId`.
3. Run the capture step before every step that consumes the value.
4. In the consuming field, choose `orderId` from the **Runtime** value source.
This stores the selected element's text. It does not calculate, summarize, or interpret what the text means.
### Value sources and interpolation
The step editor identifies where a value comes from. Use its value-source picker so the saved expression matches the selected field:
| Value source | Use it for |
| ------------------------ | --------------------------------------------------------------- |
| **Plain Text** | A literal value that is safe to keep in the test. |
| **Test Data Profile** | A column from the active profile row. |
| **Runtime** | A local value captured or produced by an earlier step. |
| **Environment Variable** | An environment-specific URL, account, Password, or Vault value. |
| **Global Data** | A workspace-wide non-secret value. |
| **Random** | A value generated when the step runs. |
A field can combine fixed text with supported inserted values. For example, type the literal prefix `order-`, then use **Random** to insert `cqaRandom.alphanum(10)`, producing a saved value such as `order-{cqaRandom.alphanum(10)}`. At runtime, only the expression is replaced. Prefer the picker over manually typing source syntax, because the displayed token format differs by source and field.
***
## Global Variables
Global variables are workspace-scoped — they are available to every test case in the workspace. Use global variables for values that are shared across many test cases but are not environment-specific: a default admin account email, a standard test product name, a default search query.
### Creating Global Variables
1. Navigate to **Environment & Data → Global Data**.
2. Select **New global variable**.
3. Enter the variable **Name** and **Value**, then select its type.
4. Click **Save**.
### Using Global Variables in Steps
Insert global variables through the step editor's data picker. If a global variable and a local variable share the same name, verify the selected source in the picker rather than typing the reference manually.
For example, choose a workspace-wide `defaultSearchTerm` from the picker when many tests should use the same approved value.
### When to Use Global vs Local Variables
| Scenario | Use |
| --------------------------------------------------- | -------------------------------------- |
| Admin email used in 30+ test cases | Global variable |
| User ID returned by an API call in one test | Local variable |
| Default search term used across multiple test cases | Global variable |
| Intermediate calculation within one test | Local variable |
| Test data row values from a data profile | Local (auto-populated per profile row) |
***
## Test Data Profiles
Test data profiles enable data-driven testing: running the same test case multiple times, each time with a different set of input values. A profile is a table where each column is a named variable and each row is one complete test run.
### Creating a Test Data Profile
1. Navigate to **Environment & Data → Test Data Profiles**.
2. Select **New test data profile**.
3. Enter a **Profile Name** (e.g., `LoginScenarios_MultiRole`).
4. Save the profile, open it, and select **Manage columns** to add each value your test uses.
* Enter the column name exactly as it will be referenced in the test steps (case-sensitive).
5. Click **+ Add Row** for each data scenario.
6. Fill in the values for each cell.
7. Assign the profile to the environment that will supply its row values, then save.
### Example Data Profile
Profile name: `LoginScenarios_MultiRole`
| `username` | `password` | `expected_dashboard_title` | `expected_role_label` |
| ------------------ | ------------- | -------------------------- | --------------------- |
| `admin@test.com` | `Admin123!` | `Admin Dashboard` | `Administrator` |
| `manager@test.com` | `Manager456!` | `Manager Dashboard` | `Manager` |
| `viewer@test.com` | `Viewer789!` | `Reports Dashboard` | `Read Only` |
| `billing@test.com` | `Billing000!` | `Billing Dashboard` | `Billing Admin` |
When this profile is attached to a test case and executed, the test repeats across the selected rows. The Parameter picker maps `username`, `password`, `expected_dashboard_title`, and `expected_role_label` to the corresponding input or verification steps.
### Attaching a profile to a test case
Profiles are selected on the test case, with a start and end row controlling the data range:
1. Open the test case and edit its configuration.
2. Select the execution environment. Only profiles assigned to that environment are available.
3. Enable data-driven execution, select the **Test Data Profile**, and choose the start and end row.
4. Save the test case.
5. In the step editor, select the actions that should repeat and choose **Loop → Test data profile**.
6. Confirm the environment, profile, and row range, then create the looped steps.
7. Open each input step and use the **Parameter** picker to map the correct profile column.
The test now reuses one workflow across the selected rows. Run it directly for a focused check or include it in a suite and plan when you need scheduled or multi-device execution.
### Importing Profile Data from a Spreadsheet
If you have existing test data in Excel or CSV format, you can import it directly:
1. In the Data Profile editor, click **Import from Spreadsheet**.
2. Ensure your spreadsheet has column headers matching the profile's column names.
3. Upload the file.
4. ContextQA maps the columns and imports the rows. Review the preview and confirm the import.
### Exporting and importing whole profiles
You can also export and import entire test data profiles — not just individual rows — from the **Test Data Profiles** tab in Environment Data Management, in JSON or Excel format. Export a profile to back it up or move it to another workspace, and import a profile from a file to recreate it. See [Importing and exporting data](/web-testing/environment-data-management#importing-and-exporting-data) for the full workflow, including how to handle duplicate rows during import.
***
## Environment Parameters
Environment parameters are key-value pairs stored in an environment configuration. They represent values that differ between deployment targets — base URLs, API keys, database hostnames, feature flag settings.
### Creating Environment Parameters
1. Navigate to **Environment & Data → Environments**.
2. Open an existing environment or select **New environment**.
3. Open **Environment variables** and select **Add variable**.
4. Enter the **Name** and **Value**.
5. Select the **Type** and permission:
* **String** — plain text such as a base URL.
* **Password** or **Vault** — masked secret data such as credentials or API keys.
* **RO / RW** — controls whether the value is read-only or can be changed by tests.
6. Save the environment.
### Using Environment Parameters in Steps
Use the step editor's data picker to insert environment values. For example, an environment variable named `baseURL` is inserted as `*|baseURL|*`:
```
Navigate to *|baseURL|*/login
```
### Environment Parameter vs Global Variable
Both can store reusable string values. The distinction is:
* **Environment parameters** vary between environments (staging BASE\_URL is different from production BASE\_URL).
* **Global variables** are the same across all environments.
If a value is the same whether running against staging or production, use a global variable. If it differs by environment, use an environment parameter.
***
## Using API Response Data as Variables
REST API Call steps can capture response data and make it available to subsequent steps as variables. This is the primary mechanism for chaining API calls and mixing API interactions with UI interactions within a single test case.
### Storing an API Response
In a REST API Call step, set the **Store response in variable** field to a variable name. The entire response object is stored under that name:
```
Step: REST API Call
Method: POST
URL: ${ENV.BASE_URL}/api/auth/login
Body: { "email": "${ENV.ADMIN_EMAIL}", "password": "${ENV.ADMIN_PASSWORD}" }
Store response in variable: loginResponse
```
### Accessing Response Data
The stored variable exposes the following sub-properties:
| Expression | Description | Example Value |
| --------------------------------------- | -------------------------- | --------------------- |
| `${loginResponse.status}` | HTTP status code | `200` |
| `${loginResponse.body.token}` | Top-level JSON body field | `eyJhbGci...` |
| `${loginResponse.body.user.id}` | Nested JSON body field | `42` |
| `${loginResponse.body.user.email}` | Nested JSON body field | `admin@test.com` |
| `${loginResponse.headers.content-type}` | Response header | `application/json` |
| `${loginResponse.headers.set-cookie}` | Cookie set by the response | `session=abc; Path=/` |
### Chaining Multiple API Calls
```
Step 1 (REST API): POST /api/auth/login
Store response in: authResponse
Step 2 (REST API): POST /api/projects
Headers: Authorization: Bearer ${authResponse.body.token}
Body: { "name": "Test Project ${timestamp}" }
Store response in: projectResponse
Step 3 (AI Agent): Navigate to ${ENV.BASE_URL}/projects/${projectResponse.body.id}
Step 4 (AI Verification): Verify the project name "Test Project" is displayed
in the page heading
Step 5 (REST API): DELETE /api/projects/${projectResponse.body.id}
Headers: Authorization: Bearer ${authResponse.body.token}
(Cleanup: delete the test project)
```
This pattern — create test data via API, test the UI that displays it, clean up via API — produces tests that are fully self-contained and do not leave orphaned data in the test environment.
***
## Generating Random Test Data with Random Functions
Random functions generate a fresh value every time a test runs. Use them when a step needs data that must be unique or realistic without you maintaining a fixed list — a new signup email on each run, a current timestamp, a random order amount, or a plausible name and address for a form.
Unlike variables, a random function is not a stored value you define ahead of time. You insert the function directly into a step's test data, and ContextQA evaluates it at execution time. Two runs of the same test produce two different values.
{% hint style="info" %}
Random functions are evaluated at runtime, so the same test run never reuses a value across executions. This makes them ideal for fields that reject duplicates, such as email addresses or usernames.
{% endhint %}
### Interactive demo: generate dynamic test data
Explore how ContextQA inserts runtime-generated values and validates the resulting workflow without maintaining a fixed data list.
{% embed url="" %}
#### What to notice
* Random functions are selected from the value picker and evaluated only when the test runs.
* Readable prefixes and constrained generators keep synthetic data useful for investigation.
* Dynamic data prevents duplicate-value collisions while the business validation remains deterministic.
### Inserting a Random Function
1. Open the test case and edit the step whose test data you want to randomize.
2. In the test data field, open the value picker.
3. Select the **Random** value source.
4. Browse the functions by category, or search by name.
5. Select a function. If the function accepts parameters, enter values for them (for example, a length, a minimum and maximum, or a date format).
6. Apply the selection.
ContextQA inserts the function into the step as a braced expression, for example `{cqaRandom.email('test.com', 'Jane', 'Smith')}`. At execution time, the expression resolves to a generated value such as `jane.smith47@test.com`.
The **Random** value source is available anywhere you set a step's test data, including action steps, condition steps, and loop steps.
You can also keep fixed text around a random expression. For example, `invoice-{cqaRandom.numeric(6)}` generates values such as `invoice-482731` while preserving the readable prefix. Insert the random portion with the picker so its braces and arguments are saved correctly.
### Syntax
Random functions use single braces and the `cqaRandom` prefix:
```
{cqaRandom.functionName(arguments)}
```
This syntax is distinct from the `${variableName}` reference used by local variables, global variables, and environment parameters. You do not need to type it by hand — the value picker inserts the correct expression — but recognizing it helps when you read a step's test data.
### Function Categories
ContextQA includes 167 random functions grouped into 18 categories. The value picker lists every function with a short description; the following table summarizes the categories and gives representative examples.
| Category | Functions | Examples |
| --------------------- | --------- | ------------------------------------------------------------------------------------------- |
| Date & Time | 11 | `cqaRandom.date(7)`, `cqaRandom.pastDate(2)`, `cqaRandom.weekday()` |
| Numbers | 9 | `cqaRandom.int(1, 10)`, `cqaRandom.float(0, 1, 4)`, `cqaRandom.percentage()` |
| Geo | 3 | `cqaRandom.latitude()`, `cqaRandom.longitude()` |
| Identifiers & Strings | 8 | `cqaRandom.uuid()`, `cqaRandom.alphanum(10)`, `cqaRandom.numeric(6)` |
| Arrays | 3 | `cqaRandom.sample(['a', 'b', 'c'])`, `cqaRandom.shuffle([1, 2, 3, 4])` |
| Lorem / Text | 8 | `cqaRandom.word()`, `cqaRandom.sentence(10)`, `cqaRandom.slug()` |
| Person | 12 | `cqaRandom.firstName()`, `cqaRandom.lastName()`, `cqaRandom.jobTitle()` |
| Internet / Contact | 20 | `cqaRandom.email('test.com', 'Jane', 'Smith')`, `cqaRandom.phone('US')`, `cqaRandom.ipv4()` |
| Location / Address | 12 | `cqaRandom.city()`, `cqaRandom.state()`, `cqaRandom.zipCode('#####')` |
| Company / Commerce | 13 | `cqaRandom.companyName()`, `cqaRandom.productName()`, `cqaRandom.department()` |
| Finance | 17 | `cqaRandom.creditCardNumber('visa')`, `cqaRandom.iban(true)`, `cqaRandom.currencyCode()` |
| Vehicle | 8 | `cqaRandom.manufacturer()`, `cqaRandom.vin()`, `cqaRandom.vehicleColor()` |
| Database / System | 4 | `cqaRandom.databaseType()`, `cqaRandom.column()` |
| File System | 10 | `cqaRandom.fileName(2)`, `cqaRandom.mimeType()`, `cqaRandom.semver()` |
| Music & Food | 8 | `cqaRandom.songName()`, `cqaRandom.dish()`, `cqaRandom.fruit()` |
| Animals | 11 | `cqaRandom.dog()`, `cqaRandom.cat()`, `cqaRandom.animalType()` |
| Color | 7 | `cqaRandom.colorName()`, `cqaRandom.rgb()`, `cqaRandom.hsl()` |
| Images | 2 | `cqaRandom.image(800, 600)`, `cqaRandom.avatar()` |
### Functions with Parameters
Many functions accept parameters that shape the generated value. The value picker prompts you for each parameter when you select the function.
| Function | Parameters | Generates |
| ---------------------------------------------- | ----------------------------- | ------------------------------------------ |
| `cqaRandom.date(7)` | Offset days, format | A formatted date offset from today |
| `cqaRandom.int(1, 10)` | Min, max | An integer within the range |
| `cqaRandom.alphanum(10)` | Length | An alphanumeric string of the given length |
| `cqaRandom.email('test.com', 'Jane', 'Smith')` | Domain, first name, last name | An email address on the given domain |
| `cqaRandom.phone('US')` | Country | A phone number in the country's format |
| `cqaRandom.creditCardNumber('visa')` | Provider | A test credit card number for the provider |
| `cqaRandom.image(800, 600)` | Width, height | An image URL at the given dimensions |
Functions without parameters — such as `cqaRandom.uuid()` or `cqaRandom.firstName()` — generate a value with no further input.
### Example: Randomized Signup Test
Random functions make it possible to run a signup test repeatedly without duplicate-data conflicts:
```
Step 1 (AI Agent): Type {cqaRandom.firstName()} in the First Name field
Step 2 (AI Agent): Type {cqaRandom.lastName()} in the Last Name field
Step 3 (AI Agent): Type {cqaRandom.email('example.com', 'Test', 'User')} in the Email field
Step 4 (AI Agent): Type {cqaRandom.phone('US')} in the Phone Number field
Step 5 (AI Agent): Click the Create Account button
```
Each run submits a unique name, email, and phone number, so the account-creation form never rejects the input as already registered.
### Random Functions vs Variables
| Use | Choose |
| ----------------------------------------------------- | ---------------------------------------- |
| A value that must be unique or fresh on every run | Random function |
| A value that must stay the same across steps or runs | Variable (local, global, or environment) |
| A value reused by many test cases | Global variable |
| A value that differs by environment | Environment parameter |
| A value captured from an earlier step or API response | Local variable |
***
## Tips & Best Practices
* **Use password-type parameters for all credentials and tokens.** Even in test environments, API keys, passwords, and session tokens should be stored as password-type parameters. This prevents them from appearing in screenshots, logs, or exported test data.
* **Build one data profile per functional scenario.** Do not mix different types of test data in one profile (e.g., valid credentials and invalid credentials in the same profile). Keep each profile focused on one scenario type so the profile name is self-describing and test results are easy to interpret.
* **Use API calls for test data setup, not manual data entry.** If a test requires a specific record to exist (a user, an order, a product), create it via a REST API Call step at the start of the test rather than relying on pre-existing test data that might be deleted or modified between runs.
* **Clean up after yourself with API teardown steps.** Add REST API Call steps at the end of tests to delete records created during the test. This keeps the test environment clean across repeated runs and prevents tests from interfering with each other.
* **Document global variable purpose in the description field.** As the workspace grows, it becomes hard to remember what each global variable is for. Add a clear description when creating global variables, including which test cases use them and when they should be updated.
## Troubleshooting
**A variable name fails to save and shows a validation error** Variable names must start with a letter or underscore, contain only letters, numbers, and underscores (no spaces or special characters), and must not match a reserved keyword such as `os`, `path`, or `get`. See [Variable naming rules](#variable-naming-rules) for the full rules and what each error message means.
**A variable token is visible in the result instead of its value** This means the selected value was not resolved at runtime. Check that:
1. The variable name in the step exactly matches the variable name as defined (case-sensitive).
2. For local variables set by a previous step, confirm the previous step passed — failed steps do not produce variable output.
3. For environment variables, confirm the environment was selected on the test case or executing plan.
4. Reinsert the value from the step editor's picker instead of typing the token manually.
**A REST API response variable is accessible in one step but not in a later step** Variable scope is sequential — a variable set by step N is available to all steps after step N. If you are referencing a variable before the step that sets it, reorder the steps.
**The data profile is attached but the intended steps do not repeat** Confirm that data-driven execution is enabled on the test case, the start/end row range is correct, and the actions are inside a **Test data profile** loop. Also confirm that every input step is mapped to the intended column with the Parameter picker.
**Password-type environment parameters are appearing in test step descriptions** Password values are masked in the UI and execution evidence, but literal text in a step description is not rewritten. Always insert the approved Password or Vault value through the picker—never hard-code credentials in step text.
## Related Pages
* [Tutorial: Data-Driven Testing](/web-testing/data-driven-testing-tutorial) — step-by-step tutorial for parameterized tests
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Configuring Environments](/execution/environments)
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Core Concepts](/getting-started/core-concepts)
* [Running Tests](/execution/running-tests)
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Environment Data Management
Create ContextQA environments, manage variables and database connections, and reuse safe test data across test runs and deployment targets.
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who manage the data their tests depend on — environment variables, database connections, data-driven profiles, and workspace-wide global variables — from a single place.
{% endhint %}
## Quick answer
Use **Environment & Data Management** to keep deployment-specific environments, reusable test data profiles, and workspace-wide global data separate. This lets one test run safely across development, staging, or production-like targets without duplicating steps or hard-coding URLs and input values.
## What this page covers
* An **environment** is *where* the test runs. It contains deployment-specific variables, database connections, and links to data profiles.
* A **test data profile** is *what* the test uses. It defines reusable columns and rows whose values can differ by environment.
* **Global data** contains workspace-wide values that do not change between environments.
This separation lets one test run against development, staging, or production-like targets without duplicating the test steps or hard-coding URLs and input data.
{% hint style="success" %}
**See it in ContextQA:** use the interactive walkthrough below to explore how environments and data profiles separate target-specific configuration from reusable test inputs. No ContextQA account is required.
{% endhint %}
{% embed url="" %}
### What to notice in the demo
* Environments keep deployment-specific URLs and configuration outside test steps.
* Data profiles supply reusable test inputs without duplicating the test flow.
* Separating configuration from data makes the same regression scenario easier to repeat across approved targets.
Open **Environment & Data** from the left navigation. The **Environment & Data Management** page opens on the **Environments** tab and provides three tabs:
| Tab | Manages |
| ---------------------- | ----------------------------------------------------------------------------------------------------------------- |
| **Environments** | Per-environment variables, database connections, and the test data profiles linked to each environment |
| **Test Data Profiles** | Data-driven tables whose structure is shared across environments and whose values are independent per environment |
| **Global Data** | Environment-agnostic variables available to every test case in the workspace |
ContextQA inserts variables from the step editor's data picker. An environment variable named `baseURL`, for example, is referenced as `*|baseURL|*`. Choose the variable from the picker when possible so the name and syntax are inserted correctly.
[Watch the environments-and-data-profiles walkthrough](https://drive.google.com/file/d/1UbcQCoDLHLrjbau3Jfb9HqGF3lnsGR-m/preview).
## Prerequisites
* You have a workspace created with at least one environment.
* You are a workspace member with permission to edit data (Editor or Admin role).
***
## Permissions: read-only and read-write
Most values in this workspace carry a permission setting shown as a toggle:
* **RW** (read-write) — test cases and team members can both read and update the value.
* **RO** (read-only) — the value is visible and usable in test steps, but protected from edits.
Set a value to **RO** to lock down shared data — such as a stable account ID or a reference table — so that a test run or another team member cannot change it accidentally. Switch back to **RW** when you need to edit it.
***
## Variable naming rules
Every name you enter in this workspace — environment variables, global variables, and test data profile columns — must be a valid variable identifier:
* Start with a letter or an underscore (`_`).
* Use only letters, numbers, and underscores after the first character — no spaces or special characters.
* Names are case-sensitive.
* A name cannot match a reserved keyword such as `os`, `path`, `fs`, `moment`, `get`, or `post` (matched case-insensitively).
ContextQA validates the name as you type and blocks saving until it is valid; if a name is rejected, the field explains which rule it broke. See [Variable naming rules](/web-testing/test-data-management#variable-naming-rules) for the complete rules, the reserved-keyword list, and every error message.
***
## Environments tab
The **Environments** tab lists every environment in the workspace. Each environment is a named deployment target (for example, `Staging`, `QA`, or `Production`) that holds its own variables, database connections, and linked profiles.
### Browsing environments
* Use the **Search environments...** box to filter by name.
* Use the view toggle to switch between **grid** (cards) and **list** (table) views.
* The environment marked **DEFAULT** is used when no other environment is selected. You cannot delete the default environment.

*An environment keeps deployment-specific values together. This documentation example uses a fictional `example.test` URL and contains no production credentials.*
### Creating an environment
1. Click **New environment**.
2. Enter a **Name** and an optional **Description**.
3. Save the environment. It appears in the list, and you can open it to add variables, databases, and profiles.
### Environment actions
From an environment card or the environment detail header, you can:
* **Clone** — create a copy of the environment, including its configuration.
* **Edit details** — change the name or description.
* **Delete** — remove the environment. This is disabled for the default environment.
### Working inside an environment
Click an environment to open its detail view. The detail view has three sub-tabs:
#### Environment variables
Key-value pairs scoped to this environment. Test cases read and write them according to each variable's RO/RW permission. Reference a variable by selecting it in the step editor's data picker; for example, `baseURL` is inserted as `*|baseURL|*`.
The table shows four columns — **NAME**, **TYPE**, **VALUE**, and **PERMISSION** — plus row actions.
To add a variable:
1. Click **Add variable**.
2. Enter the **Name** and **Value**.
3. Select the **Type**:
| Type | Use for |
| ------------ | ------------------------------------------------ |
| **String** | Plain text values such as URLs and labels |
| **Number** | Numeric values |
| **Boolean** | `true` / `false` flags |
| **Password** | Sensitive values that should be masked in the UI |
| **Vault** | Sensitive values handled as vault-backed secrets |
4. Set the permission to **RW** or **RO**.
5. Save the variable.
{% hint style="warning" %}
Store credentials, API keys, and tokens as **Password** or **Vault** values. When you edit either secret type, ContextQA opens the value field blank; leave it blank to preserve the stored secret, or enter a new value to replace it. Never place real secrets in screenshots, examples, profile names, or descriptions.
{% endhint %}
Knowledge Base entries and literal step descriptions are not secret fields. A safe instruction names the protected variable—for example, “use `stageAdminPassword` from the selected environment”—without copying its value. See [Knowledge Base: Referencing credentials safely](/ai-features/knowledge-base#referencing-credentials-safely).
#### Databases
The **Data base configurations** sub-tab connects SQL databases to the environment. You can attach multiple databases and use them alongside variables — there is no forced choice between the two.
To add a connection:
1. Click **Add DB config**.
2. Enter a **Connection name**.
3. Select the **Driver** (for example, MySQL).
4. Enter the **Host** and **Port**.
5. Save the configuration.
Database connections defined here are available to [Database Steps](/web-testing/database-steps) running in this environment.
#### Profiles
The **Linked test data profiles** sub-tab lists the profiles visible to test cases running in this environment. Only linked profiles appear in the step picker for this environment.
* Click **New profile** to create a profile and link it to this environment in one step.
* Click **Link profile** to attach an existing profile.
When you link an existing profile, the **Link profile** dialog lets you search profiles, select one or more, and choose a source environment under **Copy from which environment**. The selected source's row values become the starting point for this environment and can be edited afterward. A profile with no existing data is linked with no rows.
***
## Test data profiles
The **Test Data Profiles** tab manages data-driven test tables. A profile defines a set of named columns once; each linked environment then stores its own independent set of row values. The column structure is shared across environments, but the values are independent — so the same test logic can run against staging data and production data without duplicating the profile.
### Browsing profiles
* Use the **Search profiles…** field to filter by name.
* Use the environment filter to show only profiles linked to a specific environment.
* Use the permission filter to show only read-only or read-write profiles.
### Creating a test data profile
1. On the **Test Data Profiles** tab, click **New test data profile**.
2. Enter the profile **Name** and optional **Description**.
3. Save the profile.
You can also create a profile directly from an environment's **Data profiles** sub-tab using **New profile**, which links the new profile to that environment automatically.

*The profile structure is shared across environments, while each environment keeps independent row values.*
## Tutorial: create reusable registration data for a staging test
This example creates a staging environment, adds a base URL, builds a registration data profile, and connects the two. All names and values are fictional; replace them with safe values for your own non-production system.
### 1. Create the staging environment
1. Select **Environment & Data** in the left navigation.
2. On **Environments**, select **New environment**.
3. Enter `Stage Environment` as the name.
4. Add a description that tells teammates what the environment is for.
5. Save the environment, then open it from the environment list.
### 2. Add the base URL variable
1. Open the environment's **Environment variables** tab.
2. Select **Add variable**.
3. Enter `baseURL` for **Name**.
4. Select **String** for **Type**.
5. Select **RW** while you are setting up the example. Use **RO** later if the value should be protected from changes.
6. Enter a non-production URL, such as `https://example.test`, for **Value**.
7. Save the variable.
In a test step, use the data picker to insert the variable. ContextQA displays it as:
```
Navigate to *|baseURL|*
```
{% hint style="info" %}
`*|baseURL|*` is an environment-variable reference. Expressions such as `${loginResponse.body.token}` serve a different purpose: they access data stored by an earlier API or database step.
{% endhint %}
### 3. Create the registration data profile
1. Return to **Environment & Data Management**.
2. Select **Test Data Profiles**.
3. Select **New test data profile**.
4. Enter `Registration Data` as the profile name.
5. Add a description explaining that the profile contains fictional registration inputs.
6. Set the permission to **RW** while you build the profile.
7. Assign the profile to **Stage Environment**, then save it.
### 4. Define the shared columns
1. Open the new profile.
2. Select **Manage columns**.
3. Add these columns:
| Column | Type | Example purpose |
| ----------- | -------- | ------------------------- |
| `firstName` | String | User's given name |
| `lastName` | String | User's family name |
| `email` | String | Unique registration email |
| `password` | Password | Masked test-only password |
4. Apply the changes.
Column definitions are shared across every assigned environment. If you change a column type later, review the confirmation carefully: converting to **Number** or **Boolean** replaces existing values, while converting to **String** or **Password** preserves them.
### 5. Add a row for the staging environment
1. Select the **Stage Environment** tab inside the profile.
2. Select **Add row**.
3. Enter a unique row name such as `registration_1`.
4. Add fictional values, for example `Avery`, `Tester`, `avery.tester@example.test`, and a test-only password.
5. Save the row.
The same profile can now be assigned to another environment. Its columns remain the same, but you can enter different row values for that environment.
### 6. Use the environment and profile in a test
1. Open or create a test case.
2. Select **Stage Environment** as its execution environment.
3. Attach or select **Registration Data** when configuring the test's data.
4. Insert environment and profile values with the step editor's data picker.
5. Run the test and confirm that the execution used the selected environment and expected data row.
If the profile is missing from the picker, confirm that it is assigned to the selected environment.
### Editing profile data
Open a profile to view its detail page. The detail page shows one sub-tab per linked environment, each with that environment's row values.
* The banner reads **"Structure is shared across environments, values are independent"** when you view an environment tab.
* Click an environment sub-tab to edit that environment's rows.
* Click **Assign to more environments** (the **+** tab) to link the profile to additional environments.
* Click **Manage columns** to add, rename, remove, or set the data type of columns. Column changes apply across all environments because the structure is shared.
* Click **Add row** to append a row to the active environment's data.
{% hint style="info" %}
Profiles created before per-environment data may show a **master data (deprecated)** tab. These legacy rows are read-only. Assign the profile to an environment to start editing per-environment data.
{% endhint %}
### Column data types
Each profile column has a data type that controls how you enter its values and how they display in the table. Set the type when you add or edit a column in the **Manage columns** dialog — every column has a type selector, and new columns default to **String**. The type is part of the shared column structure, so it applies across all environments.
| Type | How you enter and view values |
| ------------ | ---------------------------------------------------------------------------------------- |
| **String** | Free-text input. The default for new columns. |
| **Number** | Numeric input that accepts digits and a decimal point. New cells start at `0`. |
| **Boolean** | A **True** / **False** dropdown. New cells default to **True**. |
| **Password** | A masked input. Select the reveal icon to show or hide the value. New cells start empty. |
#### Changing a column's data type
When you change an existing column's type in the **Manage columns** dialog, the **Confirm column type changes** dialog appears before the change applies. For each affected column, it shows the current type, the new type, and what happens to existing values:
* Changing to **Number** resets every value in the column to `0`.
* Changing to **Boolean** resets every value to `true`.
* Changing to **String** or **Password** keeps existing values unchanged.
{% hint style="warning" %}
Replacing values cannot be undone. Select **Apply changes** to confirm the conversion, or **Cancel** to keep the columns as they are.
{% endhint %}
### Profile detail actions
The profile detail header provides:
* A **permission toggle** to set the profile read-only or read-write.
* **Clone to environments** — copies the profile's data into other environments.
* **Edit** — changes the profile name and description.
* **Delete** — removes the profile. If the profile is linked to test cases or environments, the confirmation dialog lists them first.
***
## Global data
The **Global Data** tab manages workspace-wide variables. These variables are environment-agnostic: they are accessible from every test case regardless of which environment is selected, and their names must be unique across the entire workspace.
### Creating a global variable
1. On the **Global Data** tab, click **New global variable**.
2. Enter the variable **Name** and **Value**.
3. Select the **Type** — **String**, **Number**, **Boolean**, or **Password**.
4. Optionally add **tags** to group related variables.
5. Save the variable.
### Filtering and exporting
* Use the **Search global variables…** field to filter by name.
* Use the tag chip bar to filter by one or more tags.
* Click **Export all** and choose **Export as JSON** or **Export as Excel** to download every global variable, or select rows and click **Export** to download only those. See [Importing and exporting data](#importing-and-exporting-data) for the full workflow.
### Global variable vs environment variable
| Use a... | When the value... |
| ------------------------ | ---------------------------------------------------------------------------------------------- |
| **Global variable** | Is the same across every environment (a standard test product name, a default search term). |
| **Environment variable** | Differs by environment (the base URL, credentials, or API keys for staging versus production). |
***
## Importing and exporting data
Environment Data Management supports JSON and Excel (`.xlsx`) export across its environments, database configurations, profiles, and global data. Import support varies by surface, as described below. Export data to back it up, move it between workspaces, or review it offline.
{% hint style="info" %}
Treat every exported file as potentially sensitive. Review the file before sharing it, store it securely, and never use real credentials in documentation examples.
{% endhint %}
### Exporting data
Export is available from these places:
| Location | What exports | How |
| ------------------------------------ | -------------------------------------------------------------------------- | ------------------------------------------------------------------------ |
| **Environments** tab | One or more environments, with their variables and database configurations | Click **Export all**, or select environments and click **Export** |
| An open environment | That environment's data | Click **Export** in the header, then choose what to include and a format |
| **Environment variables** sub-tab | The environment's variables only | Click **Export all** |
| **Data base configurations** sub-tab | The environment's database configurations | Click **Export all**, or select rows and click **Export** |
| **Test Data Profiles** tab | Selected profiles | Select profiles and click **Export** |
| A profile detail page | The profile's rows, for all environments or specific ones | Click **Export**, then choose a scope and a format |
| **Global Data** tab | Every global variable, or a selection | Click **Export all**, or select variables and click **Export** |
When you export an environment, a **What to include** step lets you choose:
* **All** — variables and database configurations together.
* **Variables** — environment variables only.
* **Database configs** — database configurations only.
Exporting **All** across several environments produces a `.zip` file. A single, scoped export produces one `.json` or `.xlsx` file.
### Importing data
Import is available for global variables, database configurations, test data profiles, and new environments. Direct import from an open environment's **Environment variables** section is not currently available.
| Surface | Current import workflow |
| ---------------------------- | ----------------------------------------------------------------------------------------------------------- |
| **Environments** tab | Creates a new environment from separate variable and database-configuration files |
| **Data base configurations** | Imports into the open environment and provides duplicate-handling choices |
| **Test Data Profiles** | Imports profile data with the applicable environment and conflict choices |
| **Global Data** | Uploads global variables and reports the import result; it does not show a separate duplicate-handling step |
The general import sequence is:
1. Click **Import** on the relevant tab or sub-tab.
2. Upload a `.json` or `.xlsx` file. To start from a correctly structured file, download the sample template offered in the wizard for the format you want.
3. When the wizard provides a duplicate-handling step, choose the applicable strategy.
4. Confirm the import. The result step reports how many rows succeeded, how many failed, and the reason for each failure.
#### Test data profile file shape
Download **JSON Template** or **Excel Template** from the import dialog before preparing a file. The downloaded template is the contract for the portal version you are using; do not reuse the similarly named test-case import template.
For profile data, the fields map as follows:
| Profile concept | JSON field | Excel representation | Rules |
| ---------------- | ------------------------------------------------------------------------------------ | -------------------------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| Profile name | `testDataName` in a whole-profile export, or the **Name** field in the import dialog | Supplied by the import dialog or workbook metadata | Required when creating a profile; must be unique unless importing into an existing profile. |
| Data-set name | `data[].name` | One row-name cell per record | Required and unique within the profile. |
| Description | `data[].description` | Description cell | Optional text. |
| Expected failure | `data[].expectedToFail` | Expected-failure column | Boolean: `true` or `false`. |
| Profile values | `data[].data` object | One column per profile field | Object keys/column headers become case-sensitive profile variables and must follow the variable naming rules. |
Example JSON exported for a profile:
```json
{
"testDataName": "RegistrationData",
"data": [
{
"name": "valid_phone",
"description": "Fictional registration input",
"expectedToFail": false,
"data": {
"phone": "+15555550100",
"countryCode": "US"
}
}
]
}
```
When the import dialog asks for the profile name separately, keep the row structure from its downloaded template and enter the profile name in the dialog. Do not add an unrecognized wrapper merely to match the example above. For Excel, keep the template's system columns unchanged and add profile fields only where the template indicates. A duplicate column, invalid variable name, unsupported value type, or malformed JSON is rejected before import; the import summary identifies failed rows.
#### Handling duplicates
When a supported import wizard presents conflict handling, the available options depend on the surface:
| Option | What it does |
| --------------- | --------------------------------------------------------- |
| **Override** | Updates records that match by name and adds new ones. |
| **Replace all** | Clears the existing records first, then imports the file. |
| **Ignore** | Keeps existing records and skips duplicates. |
{% hint style="warning" %}
**Replace all** deletes existing records before importing. Export the current data first if you need a backup.
{% endhint %}
#### Importing a new environment
On the **Environments** tab, click **Import** to create a new environment seeded from files. Enter a name for the environment, then upload separate files for **Environment variables** and **Database configs**. A sample template is available for each.
{% hint style="info" %}
Imported database configurations start as **Not verified yet**. Run **Verify** on each connection to confirm connectivity.
{% endhint %}
***
## Tips and best practices
* **Set a default environment early.** The default environment is used whenever no other environment is selected, so configure it before your first run.
* **Use secret variable types for credentials.** Store credentials, API keys, and tokens as Password or Vault environment variables, or Password global variables, and keep them out of screenshots and examples.
* **Keep profile structure stable, vary the values.** Because a profile's columns are shared across environments, design the column set once and let each environment supply its own rows. Avoid one-off columns that only apply to a single environment.
* **Link only the profiles a test needs.** Only profiles linked to an environment appear in that environment's step picker, so linking selectively keeps the picker focused.
* **Tag global variables.** As the global variable list grows, tags make it fast to find related variables with the tag filter.
## Frequently asked questions and troubleshooting
**A variable or column name doesn't save and shows a validation error** The name must start with a letter or underscore, contain only letters, numbers, and underscores, and must not match a reserved keyword such as `os`, `path`, or `get`. See [Variable naming rules](/web-testing/test-data-management#variable-naming-rules) for details.
**A test data profile doesn't appear in the step picker** The profile must be linked to the environment the test case runs against. Open the environment's **Data profiles** sub-tab and link the profile, or open the profile and assign it to the environment.
**A profile shows a "master data (deprecated)" tab with read-only rows** These are legacy rows from before per-environment data. Assign the profile to an environment to create editable, per-environment rows.
**Can't delete an environment** You can't delete the default environment. Promote another environment to default first, then delete the original.
**A global variable can't be saved because the name already exists** Global variable names must be unique across the entire workspace. Choose a different name, or check whether the value belongs in an environment variable instead.
What is the difference between an environment variable and a test data profile?
An environment variable is a single deployment-specific value, such as a base URL or API host. A test data profile is a reusable table of columns and rows, such as several registration users. Think of the environment as *where* the test runs and the profile as *what data* the test uses.
Can one profile have different values in different environments?
Yes. The profile's column structure is shared, but each assigned environment stores independent row values. This lets the same test logic use staging-safe data in staging and a different approved data set elsewhere.
Why is my test data profile missing from the test picker?
The profile must be assigned to the environment selected for the test. Open the profile and select **Assign to more environments**, or open the environment's **Data profiles** tab and link the profile.
What happens when I delete an environment or profile?
Deleting an environment permanently removes its variables, database configurations, and profile links; it does not delete the profiles themselves. Deleting a profile removes the profile and its environment links. Review the confirmation dialog and affected-link count before proceeding, and export a backup when recovery may be required.
## Related pages
* [Test Data Management](/web-testing/test-data-management) — variable reference syntax and data-driven testing patterns
* [Importing and Exporting Data](/web-testing/importing-and-exporting-data) — move data in and out with JSON or Excel
* [Configuring Environments](/execution/environments)
* [Database Steps](/web-testing/database-steps)
* [Tutorial: Data-Driven Testing](/web-testing/data-driven-testing-tutorial)
* [Running Tests](/execution/running-tests)
# Importing and Exporting Data
Export and import ContextQA environments, variables, database configurations, and test data profiles with JSON or Excel templates and duplicate handling.
## Quick answer
Export and import ContextQA environments, variables, database configurations, and test data profiles with JSON or Excel templates and duplicate handling. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who need to move test data between workspaces, back it up, seed a new environment, or bulk-edit values outside ContextQA.
{% endhint %}
You can export and import everything in the [Environment Data Management](/web-testing/environment-data-management) workspace — environments, environment variables, database configurations, test data profiles, and global variables. Export a surface to download its data as a file, edit or archive it, then import a file to load values back in. Both directions support two file formats:
* **JSON** — best for version control, scripting, and moving data between tools.
* **Excel** (`.xlsx`) — best for editing values in a spreadsheet before importing.
## Prerequisites
* You have a workspace with at least one environment.
* You are a workspace member with permission to edit data (Editor or Admin role).
***
## Supported surfaces
You can export from — and, where noted, import into — each of these surfaces:
| Surface | Where to find it | Export | Import |
| --------------------------- | ----------------------------------------------------- | ------ | ------------------------------- |
| **Environments** | Environments tab | Yes | Yes (creates a new environment) |
| **Environment variables** | An environment's **Variables** section | Yes | Yes |
| **Database configurations** | An environment's **Data base configurations** section | Yes | Yes |
| **Test data profiles** | Test Data Profiles tab | Yes | Yes |
| **Global variables** | Global Data tab | Yes | Yes |
***
## Exporting data
Export downloads the selected data as a JSON or Excel file. Depending on the surface, you can export everything, export only the items you select, or narrow the export to specific content.
### Export all items on a surface
1. Open the surface you want to export — for example, the **Global Data** tab.
2. Click **Export all**.
3. Select a format: **Export as JSON** or **Export as Excel**.
4. ContextQA generates the file and your browser downloads it.
### Export only selected items
Global variables, test data profiles, and database configurations support selective export:
1. Select the checkbox next to each item you want to export. Your selection persists as you move between pages, and a bottom action bar shows the running count.
2. Click **Export** in the action bar.
3. Select a format, then confirm. ContextQA exports only the selected items.
### Choose what an environment export includes
When you export a single environment or the Environments tab, the wizard adds a **What to include** step. Select one of:
| Option | Exports |
| --------------------------- | -------------------------------------------------------------------------------------- |
| **All** | Every variable and database configuration in the environment (downloaded as a `.zip`). |
| **Variables** | Environment variables only. |
| **Database configurations** | Database connection configurations only. |
Selecting two or more environments exports them together in a single file.
{% hint style="info" %}
If a surface has nothing to export, ContextQA reports that there is no data to download instead of producing an empty file.
{% endhint %}
***
## Importing data
Import reads a JSON or Excel file and loads its values into the surface. Every import runs through a short wizard: upload the file, choose how to handle duplicates, and review a result summary.
### Download a template first
If you are building an import file from scratch, start from a template so your columns and keys match what ContextQA expects. On the **Global Data** import wizard, select the **JSON** or **Excel** template option to download a sample file, fill in your values, and import it back.
### Import a file
1. Open the surface you want to import into and click **Import**.
2. On the **file** step, upload a `.json` or `.xlsx` file.
3. On the duplicate-handling step, select a strategy (see the following table).
4. Submit the import. ContextQA processes the file and shows a result summary.
### Handle duplicates
When an imported item matches an existing one by name, ContextQA applies the strategy you select:
| Strategy | What it does | Available on |
| --------------- | ------------------------------------------------------------------------- | ---------------------------------------------------------------- |
| **Override** | Updates existing items that match by name and adds new ones. | Global variables, environment variables, database configurations |
| **Replace all** | Clears every existing item on the surface, then imports the file's items. | Environment variables, database configurations |
| **Ignore** | Keeps existing items and skips any duplicates in the file. | Global variables, environment variables, database configurations |
{% hint style="warning" %}
**Replace all** deletes the surface's current items before importing. This cannot be undone. Export a backup first if you might need the existing values.
{% endhint %}
### Review the import result
After the import runs, the wizard shows a result step with:
* A status message from ContextQA.
* **Succeeded**, **Failed**, and **Total** counts.
* A per-row list of any errors, so you can correct the source file and import again.
The list behind the wizard refreshes automatically, so the imported values appear as soon as you close the wizard.
### Import notes by surface
* **Global variables and environment variables** — Password-type values are shown masked in the wizard preview.
* **Database configurations** — Imported configurations start as **Not verified yet**. Run **Verify** on each one to confirm connectivity before your tests use it.
* **Environments** — Importing on the Environments tab creates a **new** environment and seeds it from the uploaded JSON or Excel files, rather than merging into an existing environment.
***
## Troubleshooting
**The import finished but some rows failed** Open the result step and read the per-row error list. Fix the flagged rows in your source file — a common cause is a missing required column or a value that does not match the column's data type — then import the corrected file again.
**A database configuration shows "Not verified yet" after import** Imported configurations are never auto-verified. Open the configuration and run **Verify** to test the connection.
**Export downloaded a `.zip` instead of a single file** Exporting an environment with **All** selected bundles its variables and database configurations into a `.zip`. Choose **Variables** or **Database configurations** in the **What to include** step to download a single file.
**Nothing downloaded when I clicked Export** The surface has no data to export. Add at least one variable, profile, or configuration and try again.
## Related pages
* [Environment Data Management](/web-testing/environment-data-management) — manage environments, profiles, and global variables
* [Test Data Management](/web-testing/test-data-management) — variable reference syntax and data-driven testing
* [Database Steps](/web-testing/database-steps) — use imported database configurations in test steps
* [Configuring Environments](/execution/environments)
# Tutorial: Data-Driven Testing
Build one login test that repeats across selected rows in an environment-linked test data profile, without duplicating test cases.
## Quick answer
Build one login test that repeats across selected rows in an environment-linked test data profile, without duplicating test cases. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers and SDETs who want one ContextQA test to cover several approved data rows without copying the workflow.
{% endhint %}
Data-driven testing separates the workflow from its input values. The test case contains the actions; a test data profile contains reusable columns and environment-specific rows. ContextQA repeats the selected steps across the row range you choose.
[Watch the environments-and-data-profiles walkthrough](https://drive.google.com/file/d/1UbcQCoDLHLrjbau3Jfb9HqGF3lnsGR-m/preview).
**Business use case:** Validate the same registration flow for several user records in staging, then reuse the shared profile structure with different values in another environment.
## Prerequisites
* A test case containing the input and verification steps you want to repeat.
* An environment for the target application.
* Safe, fictional or approved non-production data.
* Permission to edit environment data and the test case.
## Step 1: Create the environment
1. Open **Environment & Data → Environments**.
2. Select **New environment** and enter a purpose-based name, such as `Stage Environment`.
3. Save and open the environment.
4. On **Environment variables**, select **Add variable**.
5. Create a String variable named `baseURL` with a non-production URL.
6. Save the variable.
Use the test editor's data picker to insert this value. ContextQA displays it as `*|baseURL|*`.
## Step 2: Create the test data profile
1. Return to **Environment & Data** and open **Test Data Profiles**.
2. Select **New test data profile** and enter `Login Scenarios`.
3. Assign it to **Stage Environment** and save.
4. Open the profile and select **Manage columns**.
5. Add these example columns:
| Column | Type | Purpose |
| --------------- | -------- | --------------------------------- |
| `username` | String | Test account name |
| `password` | Password | Masked test-only password |
| `expectedTitle` | String | Expected page heading after login |
6. Apply the column changes.
7. On the **Stage Environment** tab, add one row for each approved scenario. Give each row a clear name such as `admin_user` or `viewer_user`.
The column structure can be shared with other assigned environments, while each environment keeps its own row values.
## Step 3: Bind the profile to the test case
1. Open the login test case and edit its configuration.
2. Select **Stage Environment** as the execution environment.
3. Enable data-driven execution.
4. Select **Login Scenarios** as the test data profile.
5. Choose the start and end row that should participate in the run.
6. Save the test case.
If the profile is missing, confirm that it is assigned to the selected environment.
## Step 4: Create the profile loop
1. In the step editor, select the input and verification steps that should repeat for each data row.
2. Choose **Loop**, then select **Test data profile** as the source.
3. Confirm the environment, profile, and row range.
4. Select **Create steps**.
5. Edit each relevant step and use the **Parameter** picker to map the correct profile column:
* Email or username input → `username`
* Password input → `password`
* Heading verification → `expectedTitle`
6. Save the steps and review their order before running.
Use the picker instead of typing variable syntax manually. This prevents spelling, case, and source-selection mistakes.
## Step 5: Run and review
Run the test directly for a focused check, or include it in a suite and plan when you need scheduling, notifications, or a device/browser matrix.
For each selected row, confirm:
* The expected row supplied the input values.
* Password values remain masked in the interface and evidence.
* The repeated steps ran in the intended order.
* The expected title or business outcome was verified.
* A failing row can be identified without exposing its secret values.
## When to use each data type
| Need | Use |
| --------------------------------------------------- | -------------------- |
| One intermediate value used only by this test | Local variable |
| One approved value shared by many tests | Global data |
| A value that changes between staging and production | Environment variable |
| Several related input rows that repeat one workflow | Test data profile |
## Related pages
* [Environment Data Management](/web-testing/environment-data-management)
* [Test Data Management](/web-testing/test-data-management)
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Test Plans](/web-testing/test-plans)
# Tutorial: Step Groups
Build a reusable login step group, insert it into multiple test cases, pass variables to it, and update it once to fix every test that uses it.
## Quick answer
Build a reusable login step group, insert it into multiple test cases, pass variables to it, and update it once to fix every test that uses it. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers and SDETs who want to eliminate duplicate steps across test cases. You will build one reusable step group and share it across multiple tests.
{% endhint %}
Step groups let you save a sequence of test steps as a reusable unit — like a function in code. Instead of copying the same login steps into 20 test cases, you create one `SG_Login` step group and insert it wherever authentication is needed. When the login flow changes, you update the step group once and every test case that uses it picks up the change automatically.
In this tutorial you will:
1. Create a step group from existing test steps
2. Insert the step group into a second test case
3. Pass variables to the step group for different credentials
4. Update the step group and verify the change propagates
**End result:** A reusable login step group shared across two test cases, parameterized with variables so each test can pass its own credentials.
## Prerequisites
* A ContextQA account with at least one workspace ([sign up](https://accounts.contextqa.com/onboard))
* A web application with a login page you can test against
* For the extraction workflow, at least one existing test case that includes login steps (see [Quickstart guide](/getting-started/quickstart) or [Creating test cases](/web-testing/creating-test-cases))
* Familiarity with [core concepts](/getting-started/core-concepts) — specifically test cases, steps, and variables
***
## Alternative: create an empty step group
You do not need an existing test case when you want to build a reusable sequence from scratch:
1. Open **Test Cases** and switch the list to **Step Groups**.
2. Select **New Step Group**.
3. Enter a unique, descriptive name and optional description, then save.
4. Open the new group and use **Add Step** to build the reusable sequence in execution order.
5. Add an outcome verification, save, and validate the group from a test case before reusing it broadly.
Use this path for a new setup or teardown component. Use the extraction workflow below when the steps already exist and have been proven in a test case.
***
## Step 1: Identify the steps to extract
Open an existing test case that includes a login sequence. A typical login flow has three to five steps:
```
Step 1: Navigate to ${ENV.BASE_URL}/login
Step 2: Type admin@example.com in the Email field
Step 3: Type SecurePass123! in the Password field
Step 4: Click the Sign In button
Step 5: Verify the dashboard page loads
```
These steps appear in many test cases — any test that requires an authenticated user starts with this same sequence. Extracting them into a step group eliminates the duplication.
***
## Step 2: Create a step group from the selected steps
1. In the test case details screen, select the checkbox next to each login step (steps 1–5 in the example above).
2. A floating toolbar appears at the bottom of the screen. Click **Group**.
3. The **Create Step Group** dialog opens. Enter a name for the step group: `SG_Login`.
> **Important:** Prefix step group names with `SG_` by convention. This makes them easy to find when searching and immediately identifies them as reusable components in the step list.
4. Click **Create**.
ContextQA creates the step group and replaces the selected steps in your test case with a single **Step Group** step that references `SG_Login`. The original steps now live inside the step group.
**Verify it worked:** The test case step list now shows a single step labeled `SG_Login` where the five login steps used to be. Click **Show Step Group Steps** on the step to expand and see the individual steps inside.
***
## Step 3: Add variable placeholders to the step group
Hard-coded credentials limit the step group to one user account. Replace the fixed values with `${variable}` placeholders so each test case can pass its own credentials.
1. In the left sidebar, navigate to **Test Cases → Step Groups** to see all step groups in the workspace.
2. Click `SG_Login` to open it.
{% hint style="warning" %}
**Any edits made to the step group will reflect in all test cases that use this step group.** This is the power of step groups — and the reason to be intentional about changes.
{% endhint %}
4. Find the step that types the email address. Click the step to edit it and replace the hard-coded email with a variable placeholder:
```
Type ${sg_username} in the Email field
```
5. Find the step that types the password. Replace the hard-coded password:
```
Type ${sg_password} in the Password field
```
6. Save the step group.
The step group now expects two runtime variables: `${sg_username}` and `${sg_password}`. When you insert this step group into a test case, ContextQA prompts you to provide values for these variables.
> **Tip:** Prefix step group variable names with `sg_` to distinguish them from test case local variables and environment parameters. This avoids accidental name collisions.
***
## Step 4: Insert the step group into a second test case
1. Open a different test case that also requires authentication — for example, a test that verifies the settings page.
2. Click **Add Step** at the position where the login sequence should run (typically the first step).
3. In the step builder, select the **Step Group** category from the left sidebar.
4. Search for `SG_Login` in the step group list. Only step groups in **Ready** or **In Review** status appear here — if your step group is missing, check its status in Test Cases → Step Groups.
5. Select it. ContextQA displays the runtime variables the step group expects: `sg_username` and `sg_password`.
6. Enter the values for this test case:
| Variable | Value |
| ------------- | ---------------------------- |
| `sg_username` | `settings-admin@example.com` |
| `sg_password` | `SettingsPass456!` |
7. Click **Create Step** to add the step group to the test case.
The test case now shows `SG_Login` as its first step. At execution time, the step group expands into the individual login steps with the credentials you provided.
***
## Step 5: Run both test cases and verify
Run each test case to confirm the step group works correctly with different credentials.
1. Open the first test case (the one you extracted the step group from). Click **Run**.
2. In the execution results, expand the `SG_Login` step. Each individual step within the group has its own pass/fail status and screenshot — the step group is transparent in the report.
3. Open the second test case. Click **Run**.
4. Verify that the login steps used the different credentials (`settings-admin@example.com`) and the test passed.
**What to check in the results:**
| What to verify | Where to look |
| ------------------------------------------- | ------------------------------------------------------------- |
| Step group expanded into individual steps | Step-by-step breakdown in the execution report |
| Correct credentials were used per test case | Screenshots of the email and password fields during execution |
| Each step has its own pass/fail status | Status indicators next to each expanded step |
***
## Step 6: Update the step group and see changes propagate
Suppose the login page adds a "Remember me" checkbox that you want to select during login. Update the step group once and both test cases inherit the change.
1. Navigate to **Test Cases → Step Groups**.
2. Open `SG_Login`.
3. Click **Add Step** after the "Click the Sign In button" step.
4. Add a new step before the sign-in click:
```
Select the Remember me checkbox
```
5. Reorder the step so it appears before the "Click the Sign In button" step.
6. Save the step group.
Now re-run both test cases. Both executions include the new "Remember me" step without any changes to the test cases themselves.
***
## Summary
You built a reusable step group in six steps:
1. **Identified** repeated login steps across test cases
2. **Created** a step group (`SG_Login`) from selected steps using the **Group** action
3. **Parameterized** the step group with `${sg_username}` and `${sg_password}` variables
4. **Inserted** the step group into a second test case with different credential values
5. **Verified** both test cases run correctly with their own credentials
6. **Updated** the step group once and confirmed the change propagated to both test cases
One step group now serves as the single source of truth for the login sequence across your workspace.
## Next steps
* **Create step groups for common patterns:** Navigation sequences (`SG_Navigate_To_Settings`), form completion (`SG_Fill_Contact_Form`), teardown actions (`SG_Logout`), and dismissing persistent UI elements (`SG_Dismiss_Cookie_Banner`).
* **Combine with data-driven testing:** Use step group variables alongside test data profile variables to run the same step group with dozens of credential sets. See [Tutorial: Data-driven testing](/web-testing/data-driven-testing-tutorial).
* **Clone an existing test case as a step group:** If you already have a standalone test case that you want to reuse as setup in other tests, use the three-dot menu → **Clone → As Step Group** instead of rebuilding it.
* **Track step group dependencies:** Open any step group and click the **Test Cases** tab to see every test case that references it. Use this view before making breaking changes.
## Related pages
* [Test steps editor](/web-testing/test-steps-editor) — reference for all step types including step group configuration
* [Core concepts](/getting-started/core-concepts#step-groups) — step groups in the platform hierarchy
* [Tutorial: Data-driven testing](/web-testing/data-driven-testing-tutorial) — parameterizing tests with data profiles
* [Creating test cases](/web-testing/creating-test-cases) — test case creation methods
{% hint style="info" %}
**Reuse once, update everywhere — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see step groups with your application.
{% endhint %}
# AI Self-Healing Tests
Learn how ContextQA self-healing detects web element drift, applies or suggests reliable locator repairs, persists healed references, and preserves genuine failures.
{% hint style="info" %}
**Who is this for?** Testers and SDETs who want to reduce test maintenance overhead — letting AI automatically repair broken locators when the application UI changes.
{% endhint %}
Self-healing is ContextQA's AI capability that automatically detects and repairs broken test steps when the application UI changes. Instead of triggering a test failure every time a button is renamed or an element is moved in the DOM, the self-healing agent finds the correct element on the current page and updates the step's element reference — allowing execution to continue without human intervention. This dramatically reduces test maintenance overhead as applications evolve.
## Quick answer
ContextQA self-healing handles routine web element-location drift during test execution. When the expected element cannot be found, the platform analyzes the current page, ranks semantically equivalent candidates, and either applies a sufficiently reliable repair or records a suggestion for review. It does not correct failed assertions, server errors, deleted workflows, or other genuine product failures.
## Interactive demo: self-healing and conditional validation
Explore how ContextQA responds when a web element changes while the business expectation remains the same. The walkthrough also shows how conditional validation keeps alternate application states explicit instead of masking a product failure.
{% embed url="" %}
### What to notice
* Self-healing is limited to recoverable element-location drift; it does not rewrite the intended assertion.
* Conditional validation models an approved alternate state and keeps both branches reviewable.
* Execution evidence shows whether the original step, a healed element, or a conditional branch produced the outcome.
## Prerequisites
* You have test cases running against a live application.
* You understand how test steps reference UI elements (see [Test Steps Editor](/web-testing/test-steps-editor)).
* Self-healing is enabled by default for all workspaces. No configuration is required to activate it.
***
## How Self-Healing Works
Self-healing activates automatically when a step execution fails to locate an expected element. The process runs within the normal execution pipeline as Stage 8 (see [Platform Architecture](/getting-started/architecture-overview)).
### The Healing Process
**1. Element not found** The step execution agent attempts to locate the element described by the step (e.g., "Click the Sign In button"). The element is not found at its previously known location in the DOM.
**2. Page analysis** The self-healing agent takes a full DOM snapshot and a screenshot of the current page state. It has access to the complete HTML structure, computed element attributes, and visual layout.
**3. Semantic search** The agent uses the step description ("Click the Sign In button") as a semantic query. It searches the current page for elements that are functionally equivalent to the one described, considering:
* Visible text content
* ARIA labels and roles
* Input type and surrounding form labels
* Position and visual context relative to other known elements
* Historical element history (attributes recorded from previous successful runs)
**4. Confidence scoring** Each candidate element is scored against the step's intent and the historical element history. The confidence level reflects how likely the candidate is to be the same logical element the step originally targeted.
**5. Auto-heal or flag**
* If the top candidate meets the confidence threshold: the step is automatically healed. The step's element reference is updated to the new locator, the step is re-executed against the healed element, and execution continues.
* If the top candidate does not meet the confidence threshold: the step is marked as failed. The healing suggestion (the best candidate found and its confidence level) is recorded for manual review.
**6. Persistent update** When auto-healing succeeds, the updated element reference is saved to the test case definition. Future executions of the same test case start with the healed locator, so the same step does not need to be healed again.
***
## What Triggers Self-Healing
Self-healing handles the routine UI drift that occurs as applications are maintained and redesigned.
| Change Type | Example | Healed? |
| ------------------------ | -------------------------------------------------- | ------------------ |
| Button text change | "Sign In" → "Log In" | Yes |
| Input placeholder change | "Enter email" → "Your email address" | Yes |
| CSS class rename | `.btn-primary` → `.button-primary` | Yes |
| ID attribute change | `#submit-btn` → `#submitButton` | Yes |
| `data-testid` rename | `data-testid="login"` → `data-testid="signin-btn"` | Yes |
| Element moved within DOM | Button relocated to different container | Yes (if same page) |
| Design system migration | Bootstrap → Tailwind CSS class changes | Yes |
| ARIA label update | Accessibility improvement renames aria-label | Yes |
***
## What Does NOT Trigger Self-Healing
Self-healing is designed to repair locator drift, not to handle genuine functional failures.
| Change Type | Example | Healed? |
| ------------------------------ | ------------------------------------------------------- | ------------------------------ |
| Element completely removed | Sign In button deleted, page now shows a different flow | No — genuine failure |
| Entire page replaced | Login page replaced by OAuth redirect | No — test needs rewriting |
| New multi-step flow introduced | Sign In now requires a CAPTCHA that wasn't there before | No — test needs updating |
| Data validation failure | Form submission fails with a server error | No — application bug |
| Low-confidence candidate only | Best match is only 65% confident | No — flagged for manual review |
For changes in the bottom half of the table, the test failure is intentional and correct — it signals that the application has changed in a way that requires human review.
***
## Viewing Healed Steps in the Execution Report
After an execution that included self-healing events, the execution report highlights healed steps with a distinct visual indicator.
1. Navigate to **Plans → Test Plans → Run Results** (or open the test plan execution results).
2. Click **View Detailed Report** on the relevant execution.
3. In the step-by-step results panel, steps that were auto-healed display a **Auto-Healed** badge.

4. Click on a healed step to expand its detail view. The detail panel shows:
* **Original locator** — the element reference used before healing
* **Healed locator** — the new element reference applied after healing
* **Confidence level** — the AI's confidence that the healed element is the correct one (always at or above the threshold for auto-healed steps)
* **Screenshot before healing** — the page state when the element was not found
* **Screenshot after healing** — the page state after the healed step was re-executed
***
## Healing Suggestions for Manual Review
When the confidence level for the best candidate does not meet the threshold, the self-healing agent records a **healing suggestion** rather than auto-healing. These suggestions appear in a dedicated panel in the execution report.
1. In the execution report, click the **Healing Suggestions** tab.
2. Each suggestion shows:
* The step that failed
* The proposed replacement element
* The confidence level
* A screenshot with the proposed element highlighted
3. Review each suggestion:
* If the proposed element is correct, click **Apply Healing** to update the test step.
* If the proposed element is wrong, click **Dismiss** and manually edit the test step.
{% hint style="info" %}
Healing suggestions repair **locator drift** — a step whose element moved or changed. For failures the AI classifies as broader script issues (a missing step, an invalid step, or a data problem), ContextQA can also propose and apply fixes through the root cause analysis panel. See [Suggested fixes](/reporting/failure-analysis#suggested-fixes).
{% endhint %}
***
## Manual Healing Approval via MCP
If you are using the ContextQA MCP server with an AI coding assistant, you can retrieve and approve healing suggestions programmatically.
### Retrieving Suggestions
```python
# Get all pending healing suggestions for an execution
suggestions = get_auto_healing_suggestions(execution_id=12345)
# Returns a list of suggestions:
# [
# {
# "healing_id": "heal_abc123",
# "step_id": 456,
# "step_description": "Click the Sign In button",
# "original_locator": "#sign-in",
# "proposed_locator": "#log-in-button",
# "confidence": 0.87,
# "screenshot_url": "https://..."
# },
# ...
# ]
```
### Approving a Healing
```python
# Apply a specific healing suggestion to the test case
approve_auto_healing(
healing_id="heal_abc123",
execution_id=12345
)
```
Approving a healing via MCP has the same effect as clicking Apply Healing in the portal: the test step's element reference is updated persistently.
### Programmatic Healing Review Workflow
A common pattern when using ContextQA with CI/CD pipelines is to check for healing suggestions after every run and automatically approve high-confidence ones while routing low-confidence ones to a human review queue:
```python
# After test suite execution completes
suggestions = get_auto_healing_suggestions(execution_id=suite_execution_id)
for s in suggestions:
if s["confidence"] >= 0.85:
# High enough confidence — auto-approve
approve_auto_healing(
healing_id=s["healing_id"],
execution_id=suite_execution_id
)
else:
# Route to human review by filing a defect ticket
create_defect_ticket(
execution_id=suite_execution_id,
project_id=""
)
```
***
## Configuring Self-Healing
Self-healing is enabled by default at the workspace level.
### Disabling self-healing for a specific test case
1. Open the test case.
2. Click the **Test Case** tab in the side panel.
3. Toggle **Self-Healing** to Off.
4. Save the test case.
Disabling self-healing for a test case means that if any element is not found, the step fails immediately without attempting to find an alternative. Use this for tests where you explicitly want failures when any UI element changes — for example, tests that validate a specific element's exact DOM structure as part of a design compliance check.
***
## Tips & Best Practices
* **Do not disable self-healing globally.** Self-healing saves significant maintenance time for typical application evolution. Only disable it for specific test cases where strict element matching is a test requirement.
* **Review healed steps periodically.** Even when self-healing is correct, it is good practice to review healed steps after a sprint or release. Accumulating healed steps without review can obscure significant UI refactoring that warrants a deliberate test update.
* **Use descriptive, semantically rich step descriptions.** Self-healing works by matching the step description's intent to the current page. The more specific your step descriptions ("Click the blue 'Add to Cart' button in the product card", not "click the button"), the more accurately the AI can locate the intended element even after changes.
* **Combine self-healing with Knowledge Base entries.** If your application has a recurring UI pattern that consistently confuses the self-healing agent (e.g., multiple similarly-named buttons), add a Knowledge Base entry explaining which button to choose in which context.
* **Alert on low-confidence suggestions in CI/CD.** If your CI/CD pipeline runs tests automatically, configure alerts (via Slack or Jira integration) when healing suggestions with low confidence are generated. These signals indicate UI changes significant enough to need human attention.
## Troubleshooting
**Self-healing is activating on elements that should not be changing** Check if your application is generating dynamic `id` or `class` attributes (e.g., `id="btn-1742831600"`). Elements with non-deterministic attributes will appear to change on every page load. Add a Knowledge Base entry to instruct the AI to use stable attributes (ARIA labels, element text, visible label) for these elements instead.
**Self-healing is consistently failing for the same step** This usually indicates one of two things: (1) the element has genuinely changed enough that the AI cannot confidently identify it, or (2) the step description is too vague for the AI to have a clear search target. Edit the step description to be more specific, and manually update the element reference by editing the step.
**The healed locator was applied incorrectly — it healed to the wrong element** In very rare cases, a high-confidence healing can select the wrong element (for example, two buttons with nearly identical text on the same page). If you notice an incorrect healing in the report, apply the correct element reference manually via the step editor and file feedback with ContextQA support so the edge case can be addressed in the AI model.
**Healing suggestions are not appearing in the Healing Suggestions tab** The Healing Suggestions tab only appears in executions where at least one step failed the element lookup and a suggestion was generated. If all steps either passed or failed for non-locator reasons (network errors, verification failures), the tab will not appear.
## Related Pages
* [Platform Architecture](/getting-started/architecture-overview)
* [Test Steps Editor](/web-testing/test-steps-editor)
* [Running Tests](/execution/running-tests)
* [MCP Server](/mcp-server/overview)
* [Core Concepts](/getting-started/core-concepts)
## Frequently asked questions
What does ContextQA self-healing repair?
It targets element-location drift: renamed labels, changed attributes, moved elements, and comparable UI refactoring where the intended control still exists. The current page and the step's intent provide the evidence for selecting an equivalent element.
What does self-healing not repair?
It does not make an incorrect business result pass, fix a backend error, restore a removed feature, solve an unreachable environment, or rewrite a materially different workflow. Those conditions should remain visible as failures or require deliberate test changes.
Does a healed element persist for future executions?
When an automatic repair succeeds, the updated element reference is saved so later executions can start with the healed reference rather than repeat the same recovery.
Can I disable self-healing for a strict test?
Yes. Open the test case, use the **Test Case** side-panel settings, turn **Self-Healing** off, and save. This is appropriate when an element's exact structure is itself part of the requirement.
How can I make self-healing more reliable?
Write precise, intent-rich steps; prefer stable accessible labels in the application; keep recurring UI guidance in the Knowledge Base; and review low-confidence or surprising suggestions rather than approving them automatically.
{% hint style="info" %}
**70% less manual test maintenance with AI self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA create and maintain tests for your web application.
{% endhint %}
# Interactive Demo
See how ContextQA's AI Self-Healing detects broken locators when the UI changes and repairs test steps automatically — without any engineer intervention.
## Quick answer
See how ContextQA's AI Self-Healing detects broken locators when the UI changes and repairs test steps automatically — without any engineer intervention. Use this page to preview the workflow and its visible results before following the linked written instructions.
## What this page covers
When your application's UI changes between releases, test locators that relied on old element attributes will break. ContextQA's self-healing engine detects these failures at runtime, finds the best matching element on the updated page, and repairs the step automatically — or flags it for manual review when confidence is lower. Select a scenario to see how each case is handled.
{% tabs %}
{% tab title="Button Renamed" %}
{% stepper %}
{% step %}
### UI Change Detected
A button on the checkout page was renamed and its ID was updated between releases.
**What changed:**
* Element ID: `btn-submit` → `checkout-submit-btn`
* Button text: "Submit Order" → "Place Order"
The stored locator in the test step no longer matches any element on the page. Without self-healing, the test would fail immediately.
{% hint style="info" %}
**AI Agent:** Detects that the element referenced in the test step cannot be found using the stored locator, and activates the healing engine.
{% endhint %}
{% endstep %}
{% step %}
### AI Healing Engine Activates
The self-healing engine evaluates candidate elements on the updated page using visual appearance, semantic role, and surrounding context.
**Healing timeline:**
1. Element not found with stored locator
2. AI locator engine activated
3. Candidate elements scored by visual and semantic similarity
4. Best match selected: "Place Order" button, `role=button`
5. Locator updated in test step
{% hint style="info" %}
**AI Agent:** Multiple candidate elements are evaluated and scored. The best match is selected based on how closely it resembles the original element in terms of visual position, role, and surrounding page context.
{% endhint %}
{% endstep %}
{% step %}
### Auto-Healed ✓
**Confidence score: 96%** — exceeds the auto-heal threshold.
The locator is automatically updated in the test step. The test continues executing and passes. No engineer action is required.
{% hint style="success" %}
**AI Agent:** When confidence exceeds the auto-heal threshold, the repair is applied immediately and the test proceeds. The healed step is logged in the execution results so teams can review what changed.
{% endhint %}
| Outcome | Detail |
| ---------------- | --------------------------------------- |
| Decision | Auto-Healed |
| Action Required | None |
| Test Result | Passes after healing |
| Audit Trail | Healed step logged in execution results |
| {% endstep %} | |
| {% endstepper %} | |
| {% endtab %} | |
{% tab title="Element Moved" %}
{% stepper %}
{% step %}
### UI Change Detected
An element was relocated to a different position in the page layout — a common result of UI redesigns or responsive layout changes.
**What changed:**
* Grid position: row 1, col 3 → row 2, col 1
* DOM nesting depth changed
The element still exists on the page, but path-based or position-based locators no longer point to it correctly.
{% hint style="info" %}
**AI Agent:** Detects the locator mismatch and activates the healing engine to find the element in its new location.
{% endhint %}
{% endstep %}
{% step %}
### AI Evaluates Match Quality
The healing engine locates the element in its new position and evaluates how confident it is that this is the correct match.
**Healing timeline:**
1. Element not found with stored locator
2. AI locator engine activated
3. Candidate elements scored by visual and semantic similarity
4. Best match selected in new grid position
5. Locator updated in test step
{% hint style="info" %}
**AI Agent:** A position change introduces more uncertainty than a simple rename — the element looks the same but its relationship to surrounding elements has changed, which lowers the overall confidence score.
{% endhint %}
{% endstep %}
{% step %}
### Healed with Warning ✓
**Confidence score: 78%** — within the 70–89% range.
The repair is applied, but the step is flagged for manual review. The test is marked as "healed with warning" in the execution results.
{% hint style="success" %}
**AI Agent:** Healing is applied so the test can continue running, but the team is notified to review the healed step and confirm the correct element was selected. This prevents false positives from silently accumulating.
{% endhint %}
| Outcome | Detail |
| ---------------- | ------------------------------ |
| Decision | Healed with Warning |
| Action Required | Manual review recommended |
| Test Result | Passes after healing (flagged) |
| Notification | Team notified for review |
| {% endstep %} | |
| {% endstepper %} | |
| {% endtab %} | |
{% tab title="Class Changed" %}
{% stepper %}
{% step %}
### UI Change Detected
A button's CSS class was significantly changed and a new `data-testid` attribute was added — a scenario common when a design system is updated or components are refactored.
**What changed:**
* CSS class: `primary-btn` → `btn btn-primary-v2`
* A new test ID attribute was added to the element
{% hint style="info" %}
**AI Agent:** The combination of a class name change and structural refactoring makes it harder to determine with certainty whether the candidate element is the same one the test was originally targeting.
{% endhint %}
{% endstep %}
{% step %}
### AI Evaluates — Low Confidence
The healing engine finds candidate elements but cannot determine with sufficient confidence that any one of them is the correct match.
**Healing timeline:**
1. Element not found with stored locator
2. AI locator engine activated
3. Candidate elements scored by visual and semantic similarity
4. Multiple candidates with similar scores — confidence below threshold
5. Healing not applied — queued for manual review
{% hint style="info" %}
**AI Agent:** When multiple candidates score similarly and none reaches the minimum threshold, applying an automatic repair risks silently changing what the test is actually testing. In this case, human judgment is required.
{% endhint %}
{% endstep %}
{% step %}
### Manual Review Required
**Confidence score: 62%** — below the minimum threshold for automatic healing.
No repair is applied. The test step is queued for manual review and the team is notified. The test is marked as requiring attention in the dashboard.
{% hint style="success" %}
**AI Agent:** Low-confidence cases are surfaced in the dashboard with the full context of what changed and which candidate elements were evaluated. A team member can review the candidates and confirm or select the correct one with a single click.
{% endhint %}
| Outcome | Detail |
| --------------- | ------------------------------------ |
| Decision | Manual Review Required |
| Action Required | Team must review and confirm element |
| Test Result | Not updated automatically |
| Notification | Team notified immediately |
| Confidence Range | Decision |
| ---------------- | -------------------------------------------- |
| 90% and above | Auto-Healed — no action needed |
| 70% – 89% | Healed with Warning — review recommended |
| Below 70% | Manual Review Required — healing not applied |
| {% endstep %} | |
| {% endstepper %} | |
| {% endtab %} | |
| {% endtabs %} | |
***
{% hint style="success" %}
**See ContextQA with your own workflow** — [Book a Demo →](https://contextqa.com/book-a-demo/)
{% endhint %}
## Related documentation
[Understand AI self-healing behavior](/web-testing/self-healing)
# Mobile Testing Overview
Upload Android APK or iOS IPA builds, create AI-assisted mobile tests, select devices, run tests, and review execution evidence in ContextQA.
{% hint style="info" %}
**Who is this for?** QA engineers, SDETs, and test leads who create and run Android or iOS tests in ContextQA.
{% endhint %}
## Quick answer
ContextQA mobile testing lets a team upload an Android APK or iOS IPA, create an AI-assisted mobile test, select a compatible device and build, execute the test, and review the resulting evidence. Use mobile suites and plans when the workflow needs repeatable or scheduled coverage.
## Interactive demo: mobile testing overview
Explore the mobile workflow without uploading an application or signing in. The tour connects app builds, device configuration, AI-assisted test creation, execution, and result evidence.
{% embed url="" %}
### What to notice
* Android and iOS tests use an explicit app build and compatible device.
* Generated steps stay reviewable before they become shared regression coverage.
* Screenshots, logs, and available recordings help a team verify and investigate the run.
## What this page covers
[Watch the mobile testing overview](https://drive.google.com/file/d/1wAtefl0InGTTJ3Gq5qPckIBvkwCZo3uh/preview).
1. Add an Android **APK** or iOS **IPA** in **Uploads**.
2. Create a test case and select **Mobile** as the target platform.
3. Choose the platform, device, and uploaded app build.
4. Generate and execute the test, then review its result evidence.
The same mobile test cases can be grouped into a **Mobile** test suite and added to a test plan for repeatable or scheduled execution.
## Mobile testing workflow
| Stage | Where | Outcome |
| ------------------- | ------------------------------ | ------------------------------------------------------------ |
| Prepare the build | **Uploads** | An APK or IPA is available as an app build |
| Create the test | **Test Cases → New Test Case** | A reusable mobile test case |
| Configure execution | Mobile configuration step | Platform, device, and app build are selected |
| Organize regression | **Plans** | Mobile cases are grouped into suites and plans |
| Review evidence | Test result or plan report | Status, step details, screenshots, logs, and available video |
## Android and iOS at a glance
| Platform | Build type | Select during execution |
| -------- | ---------- | ----------------------------------- |
| Android | `.apk` | Android device and an APK app build |
| iOS | `.ipa` | iOS device and an IPA app build |
Obtain a test-installable build from your mobile engineering team. Signing and device compatibility requirements depend on how your organization builds and distributes the application.
## How mobile tests differ from browser tests
| Browser test | Mobile test |
| ----------------------------- | -------------------------------------------------------- |
| Starts from a target URL | Starts from an uploaded app build |
| Selects a browser or viewport | Selects Android/iOS and a device |
| Uses browser interactions | Uses mobile actions such as tap, type, swipe, and scroll |
## Navigation
* **Uploads** — create an APK or IPA folder and manage its build.
* **Test Cases** — create, filter, edit, and run mobile tests.
* **Plans → Test Suites** — group related mobile cases.
* **Plans → Test Plans** — select suites, machines/devices, settings, and schedules.
## Recommended learning path
1. [Check the prerequisites](/mobile-testing/prerequisites).
2. [Upload an APK or IPA](/mobile-testing/uploading-apps).
3. [Create and run a mobile test](/mobile-testing/creating-mobile-tests).
4. Follow [Your first mobile test](/mobile-testing/mobile-testing-tutorial) for a complete example.
5. [Organize mobile suites and plans](/mobile-testing/mobile-test-plans).
## Frequently asked questions
Does ContextQA support both Android and iOS?
Yes. The verified platform selector provides **Android** and **iOS** options. Upload an APK for Android or an IPA for iOS.
Why is the App Build field empty?
The selected platform must have a compatible completed upload. Go to **Uploads**, confirm that the APK or IPA appears with **Completed** status, and then reopen the mobile configuration step.
Can I organize mobile and browser tests separately?
Yes. Test cases display their type, and test suites have a **Select Target Platform** setting. Choose **Mobile** when creating a mobile-only suite.
## See mobile testing with your own app
Bring a test-installable APK or IPA and one important mobile journey. The ContextQA team can show how build selection, device configuration, AI-assisted creation, execution, and evidence work for that journey.
[**Book a Demo →**](https://contextqa.com/book-a-demo/)
# Prerequisites
Prepare an Android APK or iOS IPA, confirm workspace access, choose a safe test account, and verify device capacity before running a mobile test.
## Quick answer
Prepare an Android APK or iOS IPA, confirm workspace access, choose a safe test account, and verify device capacity before running a mobile test. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
Before creating a mobile test, prepare the application build, test data, and expected device coverage.
## Prerequisite checklist
* Access to the correct ContextQA workspace.
* An Android `.apk` or iOS `.ipa` that can be installed in your organization's test environment.
* Permission to add files in **Uploads** and create test cases.
* A non-production test account and fictional or approved test data.
* A concise user flow with at least one observable expected result.
* A target platform and device requirement agreed with the mobile team.
## Get a test-installable app build
Ask the mobile engineering team for a build intended for automated testing. Record:
* App name and version
* Platform: Android or iOS
* Supported OS versions and devices
* Backend environment used by the build
* Required test account or seeded data
* Any permissions, deep links, feature flags, or setup steps
Do not assume that a store-distributed build can be installed in a test device environment. Confirm signing and distribution requirements with the team that produced the build.
## Choose a safe first scenario
Start with a short, deterministic flow such as:
* Launch the app and verify the welcome screen.
* Sign in with a dedicated test account and verify the dashboard.
* Search for a known fictional record and verify the result.
Avoid production credentials, personal data, one-time codes owned by real users, and destructive operations.
## Prepare the test prompt
A useful prompt names the screen, action, input, and expected outcome:
```
Launch the sample app. Tap Sign in, enter the approved test account,
submit the form, and verify that the Dashboard heading is visible.
```
Use environment variables or approved test data instead of placing secrets directly in the prompt.
## Confirm execution capacity
The mobile configuration step shows the workspace's current **Parallel** and **Queued** counts. If capacity is busy, the run may wait before a device becomes available.
## Troubleshooting prerequisites
Why does my build not appear after I select Android or iOS?
Confirm that the upload uses the matching type—APK for Android or IPA for iOS—and that its status is **Completed**.
Which device should I choose?
Use the device and OS versions in your product's support matrix. For a first smoke test, choose one representative supported device; expand coverage in a test plan after the flow is stable.
Next, [upload the app build](/mobile-testing/uploading-apps).
# Uploading Apps (APK & IPA)
Create an APK or IPA upload folder in ContextQA, add a mobile app build, verify processing, and manage versions safely.
## Quick answer
Open **Uploads**, select **Create Folder**, enter a descriptive name, and choose **APK** or **IPA** as the file type. Add the matching application build and wait for **Completed** status before using it. After execution, the run result identifies the saved build name and offers **Download build** while that artifact is retained.

## Supported mobile upload types
| Upload type | Use for |
| -------------- | --------------------------------------------------------------- |
| **APK** | Android application builds |
| **IPA** | iOS application builds |
| **Attachment** | General test files; do not use this type for a mobile app build |
## Upload an app build
### 1. Open Uploads
Select **Uploads** from the left navigation. The table shows the upload name, type, file path, last-modified date, folder size, status, and actions.

### 2. Create the build folder
1. Select **Create Folder**.
2. Enter a name that identifies the app, platform, and release, such as `Sample App — Android 2.4.1`.
3. Under **File Type**, choose **APK** for Android or **IPA** for iOS.
4. Review **Versioning** and **Overwrite existing file**:
* With versioning enabled, later uploads can create versions.
* With overwrite enabled, a same-name upload replaces the existing file.
5. Select **Create**.
Folder names must contain 4–30 characters. Choose the upload type carefully: after the folder is created, its **File Type** is locked.
### 3. Add the application file
Open the new folder and follow the upload control to select the matching `.apk` or `.ipa` from your computer. Do not rename the extension.
### 4. Verify processing
Return to the Uploads list and confirm:
* The expected name and platform type appear.
* **File Path** shows the uploaded build.
* **Folder Size** is greater than zero.
* **Status** is **Completed**.
Do not start a test while the upload is still processing or has failed.
## Naming and versioning recommendations
Use a predictable pattern:
```
—
```
Example: `Sample App — Android 2.4.1 Staging`.
Keep old builds only while they are needed for regression comparisons. Before replacing or deleting a build, confirm that no active suite, plan, or scheduled execution depends on it.
### Manage versions and audit history
Open an upload folder to view **Folder Details**. From this panel you can:
* Review or change **Versioning** and **Overwrite existing file**.
* See the **Default Version**, including its date, uploader, and size.
* Select **Upload New Version** when versioning is enabled.
* Select **Upload Replacement File** when overwrite is enabled.
* Rename a version, set or unset the default version, and download a version.
* Review **Version History** and **Audit History**.
* Use **Copy Path** when another configuration needs the stored build reference.
Versioning and overwrite are mutually exclusive. Enabling versioning disables overwrite; turning versioning off enables replacement behavior.
## Use the build in a mobile test
During mobile test configuration:
1. Select **Android** or **iOS**.
2. Select a compatible **Device**.
3. Select the upload under **App Build**.
4. Start generation and execution only after all required fields are complete.
After execution, open the run result and confirm the header shows the saved build name used by that run. When the artifact is still retained, the adjacent **Download build** action retrieves the same package for reproduction. This helps distinguish failures across app versions without relying on an opaque build identifier.
## Troubleshooting uploads
The app build does not appear in the App Build list
Check that the upload type matches the selected platform and the upload status is **Completed**. Refresh the Uploads list and reopen the test-configuration dialog.
The upload shows zero bytes or no status
The folder may exist without an application file. Open it and upload the build, then confirm that a file path, non-zero size, and **Completed** status appear.
Should I enable versioning or overwrite?
Use versioning when you need rollback or run-to-run build comparison. Use overwrite only when your release process intentionally keeps a single replaceable build reference.
Can I change an APK folder into an IPA folder?
No. The upload type is locked after folder creation. Create a separate IPA folder and upload the iOS build there.
## Related pages
* [Create and run a mobile test](/mobile-testing/creating-mobile-tests)
* [Mobile testing prerequisites](/mobile-testing/prerequisites)
* [Build a mobile test plan](/mobile-testing/mobile-test-plans)
* [Review run evidence](/execution/video-and-screenshots)
If the upload workflow in your workspace differs from this guide, use the page-rating control below and include the visible field or status that needs clarification.
{% hint style="info" %}
**Want to validate a real Android or iOS release workflow?** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See build upload, device selection, execution, and evidence with your application.
{% endhint %}
# Creating Mobile Tests
Create an AI-assisted Android or iOS test, write an effective prompt, choose a device and app build, execute it, and review the result evidence.
## Quick answer
Go to **Test Cases → New Test Case → AI Assistance**, select **Mobile**, describe the flow, and continue. In the final configuration step, select **Android** or **iOS**, choose a device and app build, then select **Generate & Execute Test Case**.
[Watch the first mobile test walkthrough](https://drive.google.com/file/d/1jEH39OreAYE9eJYf3fpDFFek5wl4M-WO/preview).
## Interactive demo: configure gesture-based mobile testing
Follow the highlighted actions to configure a mobile scenario that uses touch gestures and visible validations. The demo is public and does not require a ContextQA account or app upload.
{% embed url="" %}
### What to notice
* Gesture intent and its target are described in user language instead of framework-specific code.
* Tap, swipe, scroll, pinch, and zoom actions stay paired with visible expected results.
* Platform, device, and app-build choices keep execution configuration explicit and repeatable.
## Create an AI-assisted mobile test
### 1. Choose the creation method
1. Open **Test Cases**.
2. Select **New Test Case**.
3. Choose **AI Assistance**.
The creation dialog also offers **Import Files**, **Record & Play**, and **Create manually**. This guide uses AI Assistance because it creates a test from a plain-English scenario.
### 2. Select Mobile
1. Under **Select Target Platform**, choose **Mobile**.
2. Optionally select a **Prerequisite** if another test must establish the app state first.
3. Describe the scenario in the text box.
Example:
```
Launch the sample app. Tap Sign in, enter the approved staging test
account, submit the form, and verify that the Dashboard heading appears.
```
### 3. Write a reliable prompt
Include:
* The starting screen or state
* Each important action in order
* The visible label of the target control
* Test data source or approved fictional value
* At least one expected result
Use mobile language such as **tap**, **swipe**, **scroll**, and **long press** when it matters. Keep one test focused on one user goal.
## Gesture-based mobile scenarios
Mobile journeys often depend on touch gestures that do not have a desktop click equivalent. Name the gesture, its target, its direction when relevant, and the visible outcome that proves it worked.
| Gesture | Example business scenario | What to verify |
| ---------- | --------------------------------------------- | --------------------------------------------------------- |
| **Tap** | Search for a restaurant or product | Results match the entered search term |
| **Swipe** | Move a promotional carousel to the next offer | The banner content or active pagination indicator changes |
| **Scroll** | Browse a long result or catalog list | New list items become visible |
| **Pinch** | Resize a product or food image | The image scale changes without distortion |
| **Zoom** | Inspect a delivery or tracking map | Map content scales and remains responsive |
Example prompt:
```
Open the Home screen. Tap the Search field, enter "Pizza", and verify
matching restaurants appear. Swipe the Featured banner left and verify the
next offer is visible. Scroll down the restaurant list. Open the first item,
pinch the product image, and verify its size changes.
```
Keep each gesture next to a visible verification. This makes a failure explain whether the interaction itself failed or the application did not update afterward.

[Watch the gesture-based mobile testing walkthrough](https://drive.google.com/file/d/1-2B2YsEDjeadues_CsWehVUutsPKdpTk/preview).
{% hint style="info" %}
**Business use case:** Validate carousels, infinite lists, product media, and maps on a real mobile device before a release—areas that a web-only click test cannot cover accurately.
{% endhint %}
### 4. Configure the run
Select **Generate & Execute Test Case** to open the third step.
1. Review the current **Parallel** and **Queued** counts.
2. Under **Select Platform**, choose **Android** or **iOS**.
3. Under **Select Device**, choose a compatible device.
4. Under **App Build**, choose the completed APK or IPA upload.
5. If **Desired Capabilities** appears, expand it and review the values supplied by the selected build. Capability names and types are read-only; `app_url` and `os_type` values are also protected.
6. Select **Generate & Execute Test Case**.
The action remains disabled until the required configuration is complete.
If the selected build has no required capability data, ContextQA displays **Required capabilities are missing in the selected build. Please re-upload your app.** The execution action remains disabled until you select or upload a valid build.
## Review the execution
During and after a run, use the evidence provided by the result screen to answer:
* Did the test use the intended platform, device, and build?
* Which steps passed or failed?
* What was visible when each significant action ran?
* Do the screenshots, logs, and available recording support the result?
If the generated steps do not match the prompt, edit the test before adding it to a regression suite.
## Organize mobile test cases
* Give each case a goal-based title, such as `Android — Sign in with valid account`.
* Add labels such as `mobile`, `android`, `ios`, `smoke`, or the feature name.
* Use the Test Cases filter to focus on **Mobile** records.
* Keep Android- and iOS-specific behavior in separate cases when expected results differ.
## Troubleshooting mobile execution
Why is Generate & Execute Test Case disabled?
Complete the required platform, device, and app-build fields. Also check for a missing-capabilities warning on the selected build. The dialog displays a warning when action is required.
Why did my platform change clear the device and build?
Device and App Build options are platform-specific. Switching between Android and iOS clears the previous selections so an incompatible device or build cannot be reused accidentally.
Why is App Build missing?
Confirm that a completed upload exists for the selected platform. Android requires an APK-type upload; iOS requires an IPA-type upload.
Why did the AI interact with the wrong control?
Make the prompt more specific. Use the exact visible label, identify the screen, and add an expected result immediately after the action. Then review and edit the generated steps before rerunning.
What should I capture when reporting a mobile failure?
Include the build, platform, device, failed step, expected result, actual result, and the relevant screenshot or recording timestamp.
For a complete walkthrough, see [Your first mobile test](/mobile-testing/mobile-testing-tutorial).
# Tutorial: Your First Mobile Test
Upload an Android APK, create an AI-assisted mobile smoke test, select a device and build, run it, and review the execution evidence.
## Quick answer
Upload an Android APK, create an AI-assisted mobile smoke test, select a device and build, run it, and review the execution evidence. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
This tutorial uses an Android example, but the same sequence applies to iOS when you select **IPA** and **iOS**.
## Interactive demo: run your first mobile test on a real device
Follow the complete captured workflow from an AI-assisted mobile scenario through device and build selection, live execution, and result review. Use the written tutorial below as the concise task checklist.
{% embed url="" %}
### What to notice
* The selected app build and device are part of the execution configuration, not hidden runner state.
* Generated steps remain editable and reviewable before promotion to a regression suite.
* Mobile evidence connects each action and validation to the device session that produced it.
## What you will create
A focused smoke test that launches a sample application and verifies its welcome screen. Use only an app build and data approved for testing.
## Before you begin
* Obtain a test-installable APK.
* Confirm the supported Android versions.
* Choose one representative device.
* Use a fictional or dedicated test account if authentication is required.
## Step 1: Add the Android build
1. Select **Uploads** in the left navigation.
2. Select **Create Folder**.
3. Enter `Sample App — Android 2.4.1 Staging` for **File Name**.
4. Select **APK** for **File Type**.
5. Keep versioning enabled if you want to retain later revisions.
6. Select **Create**.
7. Open the folder and upload the approved `.apk`.
8. Wait until the Uploads table shows a file path, non-zero size, and **Completed** status.
{% hint style="warning" %}
Do not put production credentials or customer data in the folder name, app filename, or documentation screenshots.
{% endhint %}
## Step 2: Start a mobile test case
1. Open **Test Cases**.
2. Select **New Test Case**.
3. Choose **AI Assistance**.
4. Under **Select Target Platform**, select **Mobile**.
5. Leave **Prerequisites** empty for this independent smoke test.
## Step 3: Describe the scenario
Enter:
```
Launch the sample app and verify that the Welcome heading is visible.
Tap Get started and verify that the Sign in screen opens.
```
This prompt is effective because it identifies the starting action, visible controls, and expected results.
Select **Generate & Execute Test Case** to continue to mobile configuration.
## Step 4: Select the platform, device, and build
1. Review the **Parallel** and **Queued** capacity indicators.
2. Select **Android** under **Select Platform**.
3. Select a compatible Android device.
4. Select `Sample App — Android 2.4.1 Staging` under **App Build**.
5. Confirm that the final action is enabled.
6. Select **Generate & Execute Test Case**.
## Step 5: Review the live run
Verify that the execution uses the selected build and device. Follow the step status as the test launches the app, verifies the welcome screen, taps **Get started**, and verifies the sign-in screen.
If a step fails, use the nearest screenshot or recording timestamp to determine whether:
* The wrong screen was open.
* The visible label differed from the prompt.
* The app needed more time or prerequisite state.
* The selected build behaved differently from the expected version.
## Step 6: Review and refine the generated case
After execution:
1. Open the saved test case.
2. Check that its type is **Mobile**.
3. Compare each generated step with the original prompt.
4. Make the title goal-based, for example `Android — Open the sign-in screen`.
5. Add `mobile`, `android`, and `smoke` labels.
6. Rerun the case after any meaningful edit.
## Step 7: Review result evidence
Open the latest result and record:
| Evidence | What to verify |
| --------------------- | -------------------------------------------- |
| Overall status | The final pass or fail state |
| Step details | The exact action or verification that failed |
| Screenshots | What was visible at the relevant step |
| Logs | Device, timing, and execution context |
| Video, when available | The sequence leading to the failure |
## Definition of done
Your first mobile test is ready for a suite when:
* It uses an approved completed build.
* Its title and labels are searchable.
* Generated steps match the intended flow.
* It passes on the selected supported device.
* Its evidence is sufficient to explain a failure.
Next, [add the test to a mobile suite and plan](/mobile-testing/mobile-test-plans).
# Mobile Test Plans
Group ContextQA mobile cases into suites, add suites and devices to a test plan, configure notifications and schedules, and review reports.
## Quick answer
A **test suite** groups related mobile cases. A **test plan** combines suites with machine or device configuration, execution settings, and scheduling. Stabilize individual cases first, then promote them into a suite and plan.
[Watch the mobile suites and test plans walkthrough](https://drive.google.com/file/d/1nS5FIKuOMw2oHlaWSan2n-J6WpYy-YYi/preview).
## Interactive demo: organize mobile suites and plans
See how stable mobile cases are grouped into a platform-aware suite, mapped to a compatible device and build, and prepared for repeatable plan execution.
{% embed url="" %}
### What to notice
* Mobile suites keep related device journeys together without duplicating individual cases.
* The test plan makes the device, application build, environment, and execution behavior explicit.
* One plan can report Android and iOS release coverage while preserving platform-specific evidence.
## Create a mobile test suite
1. Open **Plans**. The Test Suites page lists suite name, platform, case count, latest result, dates, folder, and actions.
2. Select **Create Test Suite**.
3. Enter a goal-based **Suite Name**, such as `Mobile — Authentication smoke`.
4. Optionally select a folder, prerequisites, and labels.
5. Expand the configuration options if needed.
6. Under **Select Target Platform**, choose **Mobile**.
7. Add a description explaining the scope and exclusion criteria.
8. Select **Add Test Cases**, choose the intended mobile cases, and finish creation.

Use **Skip & create empty** only when you intentionally want to populate the suite later.
## Decide how to organize suites
Use one primary organizing dimension per suite:
| Strategy | Example | Best for |
| -------- | ----------------------------- | ---------------------------- |
| Feature | `Mobile — Authentication` | Ownership and failure triage |
| Risk | `Mobile — Release smoke` | Fast release gates |
| Platform | `Android — Regression` | Platform-specific behavior |
| Cadence | `Mobile — Nightly regression` | Scheduled execution |
Avoid one oversized suite that mixes unrelated features, platforms, and release gates.
## Create a test plan
1. Open **Plans → Test Plans**.
2. Select **New Test Plan**.
3. In **Create Test Plan**, enter the name, labels, and description.
4. Configure dashboard visibility and notifications as required.
5. Choose the viewport and resolution appropriate for the plan.
6. Select **Next**.
7. In **Test Machines & Suites Selection**, select **Add Test Suites**.
8. Find and add the mobile suite.
9. Select the suite, then select **Add Machine/Device**.
10. Configure the compatible device and app build required by the mobile suite.
11. Continue to **Test Plan Settings**, review the configuration, and create the plan.
The current plan wizard has three stages: **Create Test Plan**, **Test Machines & Suites Selection**, and **Test Plan Settings**.
### Map Android and iOS suites explicitly
For a combined mobile release plan, map each suite to a compatible device and build:
| Suite | Device configuration | App build |
| ------------------------- | --------------------------------------- | ------------- |
| `Android — Release smoke` | Supported Android device, such as Pixel | Candidate APK |
| `iOS — Release smoke` | Supported iOS device, such as iPhone | Candidate IPA |
A single Mobile suite can contain cross-platform intent, but separate Android and iOS suites make platform ownership, build selection, and failure triage clearer when behavior differs. Add both suites to one plan when stakeholders need a combined release report.
{% hint style="info" %}
**Business use case:** Run the Android and iOS release smoke suites together while preserving the exact build and device used for each platform's evidence.
{% endhint %}
## Run or schedule the plan
The Test Plans list provides actions for:
* **Run** — start an on-demand execution.
* **Schedule** — configure recurring execution.
* **Reports** — open results when a run exists.
* **Clone** — copy a plan as a starting point for another configuration.
Before running, confirm that every mobile suite has an appropriate device and completed app build.
The Schedules view supports one-time and recurring cadences, including hourly, daily, weekly, monthly, and yearly schedules. Confirm the displayed next-run time and workspace timezone before activating a schedule.
## Review plan results
Use the report to compare outcomes by suite, test case, and configured device. For a failure, capture:
* Plan and run name
* Suite and test-case ID
* Platform, device, and app build
* Failed step and expected result
* Screenshot, logs, and available video
## Maintenance recommendations
* Include platform and purpose in suite and plan names.
* Keep smoke and full-regression plans separate.
* Update the app build deliberately; do not silently replace a build used for release evidence.
* Remove flaky cases from release gates until the failure cause is understood.
* Review scheduled plans after device-support or build-distribution changes.
## Frequently asked questions
Should Android and iOS use one suite?
Use one suite when the test intent and expected behavior are the same. Split them when steps, permissions, labels, or expected outcomes differ by platform.
Why is Add Machine/Device disabled?
Add at least one test suite first, then select the suite that needs a machine or device configuration.
Why is Reports unavailable?
Reports is disabled when the plan has no completed run. Run the plan first, then return to the Test Plans list.
What should a mobile release plan contain?
Include stable cases for the supported platform/device matrix, the exact candidate build, clear pass criteria, and notifications for the people responsible for release decisions.
## Related documentation
[Mobile testing overview](/mobile-testing/mobile-testing) · [Create and run a mobile test](/mobile-testing/creating-mobile-tests)
# API Testing Overview
Automate REST API testing in ContextQA — request configuration, response validation, API chaining, and hybrid API-plus-UI test flows, all with no code.
{% hint style="info" %}
**Who is this for?** Developers and SDETs who need to test REST APIs, validate response contracts, and chain API calls — including hybrid flows that combine API setup with UI verification.
{% endhint %}
ContextQA provides a built-in API testing layer that lets you write, execute, and validate REST API requests without leaving the platform. API steps live alongside UI steps in the same test case, which means you can build hybrid flows that call an endpoint and then verify the result in a browser — or seed data through an API before a UI workflow begins.
## Quick answer
ContextQA API testing lets a team configure REST requests, assert status and response content, capture response values, and reuse those values in later API or UI steps. It is useful for contract validation, fast test-data setup, authentication-token chaining, OpenAPI-derived coverage, and end-to-end workflows that cross backend and frontend boundaries.
[Watch the API testing overview](https://drive.google.com/file/d/1KHQnWchIXiVLFka7a0ZGrtgYJw7Mt0hy/preview).
## Interactive demo: API testing overview
Explore the API testing workflow without signing in. The guided tour shows how a tester moves from a service request to response validation, reusable data, execution, and evidence.
{% embed url="" %}
### What to notice
* Request configuration, response assertions, and reusable variables stay in one governed test definition.
* API tests can validate payload content and structure in addition to HTTP status.
* Results provide repeatable evidence that developers, SDETs, and release owners can review together.
## What API testing covers
**REST API requests.** You can configure any HTTP method (GET, POST, PUT, PATCH, DELETE), set request headers, supply a JSON body, and capture the response in a named variable. All of this is done through the API testing panel inside the test case editor.
**Response validation.** Two validation modes are available:
* *Payload validation* — assert that a specific field in the JSON response matches an expected value. You point to the field using a JSON path expression (for example, `result.email`) and compare it against a string, number, or boolean.
* *Structure validation* — compare the entire response object against an expected shape. This catches unexpected additions or removals of fields across API versions.
Status code assertions are configured in the same validation section, letting you confirm a `200`, `201`, `401`, or any other expected code in the same step.
**Variables and secrets.** Store reusable secrets in an approved environment or secret store, then insert them through the step editor's variable picker. Values captured from an earlier API response use `${variable.path}` syntax. This keeps credentials out of request definitions and lets tests use fresh runtime tokens.
**API chaining.** Responses from one API step are stored in named variables and can be read by any later step — API or UI. The canonical pattern is a `POST /auth` call that captures a short-lived access token, which is then injected into the `Authorization` header of subsequent requests. Field values extracted from an API response can also be typed into UI form fields, closing the loop between backend and frontend validation.
**Swagger / OpenAPI import.** ContextQA can consume a Swagger or OpenAPI specification file and generate a full suite of test cases from it — one test per endpoint and status-code combination documented in the spec. This gives teams a coverage baseline on day one without any manual step authoring.
**Hybrid test flows.** API and UI steps coexist in a single test case. A typical pattern: call an API to create a resource, capture the resource ID, navigate to the corresponding UI record page using that ID, and assert the data is rendered correctly.
## In this section
| Page | What it covers |
| --------------------------------------------------------- | -------------------------------------------------------------------- |
| [Creating API Tests](/api-testing/creating-api-tests) | Configuring requests, using variables, sending calls, Swagger import |
| [Validating Responses](/api-testing/validating-responses) | Payload validation, structure validation, status codes, headers |
| [API Chaining](/api-testing/api-chaining) | Extracting response values and passing them between steps |
## When to use API testing in ContextQA
* Validate that backend changes have not broken published contracts before merging a PR
* Set up test state (create records, generate tokens) faster than a UI flow would allow
* Assert API behavior in parallel with UI behavior in the same test run
* Generate a first-pass test suite from an existing OpenAPI spec in minutes
## ContextQA API testing compared with browser testing
| API testing | Browser testing |
| ------------------------------------------------------ | ------------------------------------------------------------------ |
| Validates an endpoint, response, and contract directly | Validates the rendered user experience and browser behavior |
| Creates or queries test state quickly | Proves that users can complete the workflow through the interface |
| Captures response data for later steps | Captures screenshots, video, browser logs, and rendered assertions |
| Best for service behavior and backend setup | Best for user journeys and frontend integration |
Use both in one test when an API can prepare the state efficiently and the browser must verify the visible outcome.
## Frequently asked questions
Which HTTP methods can ContextQA API tests use?
The documented request builder supports GET, POST, PUT, PATCH, and DELETE requests, with headers, a request body where applicable, response storage, and validations.
How does API chaining work?
Store an earlier response under a variable name, then reference the required field in a later request. A common example captures an authentication token from a login response and inserts that live value into the next request's authorization header.
Can ContextQA generate tests from Swagger or OpenAPI?
Yes. ContextQA can use a supported Swagger or OpenAPI source to propose API test coverage. Review the generated cases and their expected responses before adding them to a shared suite or release gate.
Can API and browser steps exist in the same test?
Yes. API and UI steps can form one hybrid flow. For example, create a record through an API, store its identifier, open that record in the browser, and verify the rendered data.
Where should API credentials and tokens be stored?
Use the approved environment, variable, or secret-management workflow for the workspace. Do not put reusable credentials directly in test descriptions, request examples, screenshots, or documentation.
{% hint style="info" %}
**Generate API tests from your Swagger spec in minutes** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Creating API Tests
Step-by-step guide to creating API test cases in ContextQA — configuring requests, using variables, capturing responses, chaining calls, and importing from Swagger.
## Quick answer
Step-by-step guide to creating API test cases in ContextQA — configuring requests, using variables, capturing responses, chaining calls, and importing from Swagger. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Developers and SDETs who want to create REST API test cases in ContextQA — including importing tests directly from a Swagger or OpenAPI specification.
{% endhint %}
This page walks through creating an API test case from scratch, wiring up variables, and generating tests from a Swagger specification.
[Watch the API test creation walkthrough](https://drive.google.com/file/d/1OyuSh20YojL-qkQs9-5rG2yYR4YqjQ98/preview).
## Interactive demo: create and execute an API test
Follow this guided workflow to configure an API request, add validation, execute the test, and inspect the result without accessing a live workspace.
{% embed url="" %}
### What to notice
* The request method, endpoint, headers, payload, and expected response remain reviewable before execution.
* A saved response can supply values to later API or UI steps.
* Execution results connect the request, response, and validation outcome for faster investigation.
## Creating an API test case
1. Open **Test Cases** and select **New Test Case**.
2. Choose **Create manually**, then select **Open step builder**.
3. Enter a test-case name, such as `API — Create user`, and select **Create Test Case**.
4. Open the new test's step builder and select **Add Test** (or the add-step action).
5. In **Create a New Step**, choose **API**. The API step opens on **Request Details**.

The panel exposes the following fields:
| Field | Purpose |
| -------------- | --------------------------------------------------------------------- |
| HTTP method | Select GET, POST, PUT, PATCH, or DELETE |
| URL | The endpoint URL; environment values can supply the reusable base URL |
| Headers | Key-value pairs; supports variable interpolation |
| Body | JSON or other payload for POST/PUT/PATCH requests |
| Store response | Name of the variable that will hold the response |
| Validation | Assertions to run against the response |
6. Select the HTTP method and enter the endpoint. For a JSON request, add `Content-Type: application/json`, open **Body**, select the JSON format, and enter a non-production payload.
7. Select **Send Request** to preview the response before saving. Use the preview to confirm the status and JSON structure.
8. Continue to **Store Response** and enter a variable name such as `result`. The response becomes available to later steps under that name.
9. Continue to **Validation** and add at least one status assertion, such as **status equals 200**.
10. Create the step, then select **Run** to execute the test.
11. Open **Run History** and inspect the request headers/body, response headers/body, and expected versus actual status.
{% hint style="info" %}
**Business use case:** Create an API test before the user interface is ready to verify that a service accepts the expected payload, returns the agreed status, and exposes the response fields the UI will depend on.
{% endhint %}
## Using variables in API requests
Variables prevent you from hard-coding sensitive values such as tokens, base URLs, or environment-specific hostnames directly into test steps.
### Defining a variable
1. Open your API test case.
2. Click the **variables** option in the test editor.
3. Enter a key (for example, `token`) and paste the value. Click **Create** to save it.
### Referencing a variable
Use the step editor's variable picker for local, global, and environment data. An environment variable such as `baseURL` is inserted as `*|baseURL|*`. Runtime response fields use `${variable.path}` syntax:
* **Authorization header from an earlier step:** `Bearer ${loginResult.body.token}`
* **URL with an environment variable:** `*|baseURL|*/api/v1/users`
* **Body field from an earlier step:** `"user_id": "${createUserResult.body.id}"`
Variable values are resolved at execution time. Use the picker whenever possible so ContextQA inserts the correct syntax and exact variable name.
### Variable scopes
* **Local variables** are defined at the test-case level and are available only within that test case.
* **Global variables** are available across all test cases in the workspace.
* **Runtime variables** are captured from API responses using the **Store response** field and are available to subsequent steps within the same execution.
## Sending the request and capturing the response
When you click **Send** in the API panel, ContextQA executes the request immediately and displays the response body, status code, and headers in the panel. Use this preview to:
* Confirm the JSON structure before writing JSON path assertions
* Copy the exact JSON path to a field (for example, `result.body.email`) for use in payload validation
* Verify that authentication headers are being resolved correctly from variables
After saving the step and running the test case, full response details are accessible in **Run History** under the **Response Body** tab.
## Chaining API calls
When one API step's response must feed into a later step, store the response in a named variable and reference its fields using dot notation.
**Example:** A `POST /auth` call stores its response as `result`. Double-click the token in the response preview to copy its JSON path, then set the next step's `Authorization` header to `Bearer ${result.body.access_token}` (adjust the path to match your response).
For a detailed walkthrough including hybrid API + UI chaining, see [API Chaining](/api-testing/api-chaining).
## Generating tests from a Swagger or OpenAPI specification
ContextQA can import a Swagger or OpenAPI file and produce a test case for each endpoint-and-status-code combination defined in the spec.
1. Click the **plus (+) icon** on the ContextQA dashboard.
2. Select **Import File**.
3. Choose **Import Requirement**, then select **API**.
4. Upload your `.json` or `.yaml` Swagger / OpenAPI file.
5. Review the imported endpoints and response codes in the preview panel.
6. Navigate to **Imported Files** and refresh the view to see the generated test cases.
Each generated test case reflects a documented endpoint and expected status code — for example, separate cases for `200`, `400`, `401`, and `500` responses on the same endpoint. You can then edit individual steps to add authentication headers, payloads, and more specific assertions.
This is also available through the `generate_tests_from_swagger` MCP tool, which accepts the same Swagger/OpenAPI content and produces the equivalent test cases programmatically.
{% hint style="info" %}
**Generate API tests from your Swagger spec in minutes.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA generate and execute REST API tests for your backend.
{% endhint %}
# Validating Responses
Response validation techniques in ContextQA — payload validation, structure validation, status codes, and header assertions.
## Quick answer
Response validation techniques in ContextQA — payload validation, structure validation, status codes, and header assertions. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Developers and SDETs who need to assert API response payloads, status codes, headers, and full response structure in automated tests.
{% endhint %}
ContextQA provides two distinct validation modes for API responses: payload validation for asserting the value of individual fields, and structure validation for asserting the shape of the entire response object. Both are configured in the **Validation** section of the API testing panel.
## Status code validation
Status code validation is the minimum assertion for any API test step and is configured alongside payload or structure checks.
1. Open the API testing panel (three dots on the REST API step).
2. In the **Validation** section, set the data type to **status**.
3. Choose a comparator: **equal**, **not equal**, **less than**, or **greater than**.
4. Enter the expected status code, for example `200` for a successful call or `401` for an unauthorized request.
The test step will fail if the actual status code does not satisfy the comparator condition. This catches unintended changes to authentication requirements, missing routes, or broken server-side logic.
## Payload validation
Payload validation asserts that a specific field in the JSON response body matches an expected value. This is the right approach when you care about one or a few targeted fields rather than the entire response.
### Setting up a payload assertion
1. Run your API request once and open its result. Select the REST API step, then open **API Data** to inspect the response status, body, and headers.
2. In the JSON response viewer, select the property or value you want to validate. When the path-selection control is available, use the generated JSON path—for example, `$[0].userId` for `userId` in the first array item. Otherwise, identify and enter the path manually.
3. Return to the test step editor and open the **Validation** section.
4. Enter the JSON path in the **JSON path** field.
5. Set the comparator (for example, **Equals**) and the data type (for example, **string** for an email address).
6. Enter the expected value — the exact string, number, or boolean you expect the field to contain.
7. Click **Create Update** to save the validation rule.
Always compare the selected path with the retained response body. Arrays, optional fields, and dynamically keyed objects can require a manually adjusted path.
### Diagnosing failures
When a payload assertion fails, ContextQA surfaces the mismatch in Run History. The execution detail shows both the expected and actual values, letting you immediately identify whether the failure is a data change, an environment-specific issue, or a regression in the API.
To test that your assertion works in both directions, temporarily change the expected value to something incorrect, rerun, and confirm the test fails. Then restore the correct expected value.
## Structure validation
Structure validation compares the entire response object against an expected object rather than a single field. Use this when you want to catch any unexpected additions, removals, or renames of fields across API versions.
### Setting up a structure assertion
1. Run the API request and retrieve the response from **Run History**.
2. Remove dynamic fields from the response body before using it as the expected value. Fields whose values change on every call (such as timestamps, generated IDs, or session tokens) will cause the assertion to fail on every run if included. Remove them from the expected object.
3. In the **Validation** section of the test step, add a new assertion. Set the data type to **object** rather than string or number.
4. Paste the cleaned response body as the expected value.
5. Name the expected value to keep validations organized.
6. Click **Create** to save.
When the test executes, ContextQA compares the full response body to the expected object. Any difference in field names or structure — even if individual values differ — will cause the assertion to fail.
### Payload vs. structure validation — choosing the right approach
| Concern | Use |
| ----------------------------------------------------- | ---------------------------------------------------------------------------------- |
| A specific field has the right value | Payload validation with a JSON path assertion |
| The response shape hasn't changed between deployments | Structure validation with an object assertion |
| Both field values and shape matter | Combine a structure assertion with one or more payload assertions in the same step |
## Header validation
Header assertions follow the same pattern as payload assertions. In the **Validation** section, reference the header using its path under the stored response variable (for example, `result.headers.content-type`), set the comparator and expected value, and save.
## Reviewing results
All validation outcomes appear in **Run History**. For each test step:
* A green status indicates all assertions passed.
* A red status indicates at least one assertion failed. Open the step detail to see which assertion failed and the expected vs. actual values.
For complex response bodies, copying the raw JSON into an external notepad can help you construct the correct JSON path expressions before entering them in the validation panel.
{% hint style="info" %}
**Generate API tests from your Swagger spec in minutes.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA generate and execute REST API tests for your backend.
{% endhint %}
## Related documentation
[API testing overview](/api-testing/api-testing) · [Chain values across API requests](/api-testing/api-chaining)
# API Chaining
Connect multiple API calls in a single test case by extracting response fields into variables and passing them to subsequent steps — including hybrid API and UI flows.
## Quick answer
Connect multiple API calls in a single test case by extracting response fields into variables and passing them to subsequent steps — including hybrid API and UI flows. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Developers and SDETs who need to pass data between API calls — such as capturing an auth token and injecting it into subsequent requests or UI steps.
{% endhint %}
API chaining lets you build multi-step request sequences where the output of one call becomes the input of the next. The most common pattern is authentication: a login endpoint returns a short-lived access token that must be injected into every subsequent request. Because the token expires quickly, you cannot hard-code it — chaining is the correct approach.
[Watch the API chaining walkthrough](https://drive.google.com/file/d/1zU67osZy0xyo7pTme0wy8720FsHx0QU1/preview).
ContextQA also supports hybrid chains where a value extracted from an API response is passed directly into a UI interaction, and vice versa.
## Interactive demo: chain API calls and reuse a token
Use this walkthrough to see how an authentication response is captured and its token is passed into a later request at runtime.
{% embed url="" %}
### What to notice
* Each response is stored under a meaningful variable name for later steps.
* Runtime token extraction avoids hard-coded, expired, or manually copied credentials.
* The chain is executed and reported as one continuous business workflow.
## How chaining works
Every API step stores its full response — status code, headers, and body — in a named variable that you define in the **Store response** field. The variable is available to every step that follows it in the same test case execution. Fields within the stored response are accessed using dot notation:
```
result.body.access_token
result.body.firstName
result.headers.content-type
```
Any subsequent step — API or UI — can reference these paths using `${variable_name.path}` syntax.
## Practical example: POST /auth then GET /protected-endpoint
### Step 1 — Authenticate and capture the token
1. Add an API step. Set the HTTP method to **POST** and enter the authentication endpoint URL (for example, `https://api.example.com/auth`).
2. In the request body, supply the login credentials.
3. Under **Store response**, enter `result`. This stores the full auth response.
4. In **Validation**, add a status code assertion: `status` **equal** `200`.
5. Click **Create** to save the step.
After the step runs, the access token returned by the endpoint is available as `result.body.access_token` (adjust the path to match your actual response structure).
### Step 2 — Call the protected endpoint with the token
1. Add a second step and choose **API**.
2. Enter the protected endpoint URL. If the test has an environment, use its base-URL variable from the data picker instead of repeating the host.
3. In **Headers**, add an `Authorization` key with the value `Bearer ${result.body.access_token}`.
4. Under **Store response**, enter a new variable name, for example `result1`.
5. Add a status code assertion: `status` **equal** `200`.
6. Click **Create** to save.
When the test suite executes, both steps complete. ContextQA resolves the `${result.body.access_token}` reference at runtime using the live token from step 1, so the assertion in step 2 passes even though the token value changes between runs.
## Hybrid API + UI chaining
Values extracted from an API response can be injected directly into UI actions. This enables data-driven UI tests that do not rely on hard-coded test fixtures.
**Example:** After the two API steps above, add a UI step that navigates to a web page and enters a value from the API response into a form field.
1. Add a UI step with the **Navigate** action and enter the target URL.
2. Add another UI step to type into an input field. When entering the value, reference the API response using dot notation — for example, `result1.body.firstName`.
3. Provide the field's metadata (element label, role, or other locator context) so ContextQA can find it.
4. Click **Create** to save.
When the test runs, ContextQA reads `firstName` from the API response captured in `result1` and types it into the correct UI element. This confirms that data returned by the API actually appears in the interface.
## Extracting specific fields
When constructing a JSON path for chaining, preview or run the producing request first:
1. Select **Send Request** in the API step to display the response preview.
2. Double-click the response value you want, such as the access token, to copy its JSON path.
3. Use the stored-response variable plus that path in the next step, for example `${result.body.data.token}`.
4. After running the full test, open **Run History**, select the producing step, and use **Response Body** to verify the path if the dependent request fails.
{% hint style="info" %}
**Business use case:** Authenticate once, then reuse the live token across read, update, and delete requests. This verifies the complete service workflow without storing an expiring token in the test definition.
{% endhint %}
## Error handling in chained sequences
If an earlier step in a chain fails — for example, the auth endpoint returns a `401` instead of `200` — ContextQA stops the execution of that test case and marks all downstream steps as not run. This prevents false failures caused by missing variable values rather than actual bugs in the downstream API.
To make a chained sequence robust:
* Always include a status code assertion on the step that produces the variable. A failing assertion surfaces the root cause (the auth step) rather than a confusing downstream error.
* Use descriptive variable names (`authResult`, `userResult`) rather than generic names (`result`, `result1`) to make step references easier to read and debug.
* When a chain breaks, check **Run History** for the first failed step — that is where the root cause will be, not in the steps that never ran.
{% hint style="info" %}
**Generate API tests from your Swagger spec in minutes.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA generate and execute REST API tests for your backend.
{% endhint %}
## Related documentation
[API testing overview](/api-testing/api-testing) · [Validate API responses](/api-testing/validating-responses)
# Tutorial: Your First API Test
Build a two-step API test that authenticates against a REST endpoint, captures the access token, chains it into a second request, and validates the response — all without writing code.
## Quick answer
Build a two-step API test that authenticates against a REST endpoint, captures the access token, chains it into a second request, and validates the response — all without writing code. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Developers and SDETs new to API testing in ContextQA. You will build one test case that authenticates against an API, chains the token into a second request, and validates the response.
{% endhint %}
API testing in ContextQA lets you send HTTP requests, assert response values, and chain data between calls — all from the same visual test editor you use for browser tests. Instead of writing scripts in Postman or pytest, you add REST API steps to a test case and let ContextQA handle execution, evidence capture, and failure analysis.
In this tutorial you will:
1. Create an API test case with a GET request
2. Add status code and payload validation
3. Store the response and chain it into a second request
4. Run the test and review per-step results
**End result:** A two-step API test that authenticates, captures a token, calls a protected endpoint with that token, and validates the returned data — with full execution evidence (request/response logs, timing, and pass/fail status per step).
## Prerequisites
* A ContextQA account with at least one workspace ([sign up](https://accounts.contextqa.com/onboard))
* A REST API you can test against (a public API or your own staging environment)
* The API's base URL, an authentication endpoint (if applicable), and at least one data endpoint
* Familiarity with [core concepts](/getting-started/core-concepts) — specifically test cases, steps, and variables
***
## Step 1: Create a test case with an API step
Start by creating a test case that sends a single GET request and confirms the API responds successfully.
1. In the left sidebar, select **Test Cases**.
2. Select **New Test Case**, choose **Create manually**, and select **Open step builder**.
3. Enter `API — User endpoint validation` and select **Create Test Case**.
4. In the new test, select **Add Test** (or the add-step action).
5. In **Create a New Step**, choose **API**. The API request panel opens on **Request Details**.
The panel displays fields for HTTP method, URL, headers, body, response storage, and validation.
6. Set the HTTP method to **GET**.
7. Enter your target endpoint URL. For example:
```
https://api.example.com/users/1
```
8. Click **Send** to execute the request interactively. The panel displays the response body, status code, and headers.
**Verify it worked:** The response panel shows a `200` status code and a JSON body containing user data. If you see a `401` or `403`, you need authentication — skip ahead to [Step 3](#step-3-chain-an-authenticated-request) to add an auth step first.
{% hint style="info" %}
**Tip:** Use the interactive **Send** button to preview responses before saving the step. This lets you inspect the JSON structure and plan your validation assertions before committing to a test step.
{% endhint %}
***
## Step 2: Add response validation
A test that sends a request without asserting the response passes even when the API returns wrong data. Add validation to catch regressions.
### Add a status code assertion
1. In the API step, continue to **Validation**.
2. Set the data type to **status**.
3. Set the comparator to **equal**.
4. Enter `200` as the expected value.
This assertion fails the step if the API returns any status other than `200`.
### Store the response for later use
1. In the **Store response** field, enter a variable name: `userResult`.
2. Click **Create** to save the step.
The full response — status code, headers, and body — is now stored in `userResult`. You can reference any field using dot notation: `userResult.body.email`, `userResult.body.name`, `userResult.headers.content-type`.
### Add a payload assertion
1. Edit the saved API step and reopen **Validation**.
2. In the **Validation** section, add a second assertion.
3. Enter a JSON path to a field you want to verify. For example, if the response contains an `email` field:
```
userResult.body.email
```
4. Set the data type to **string**, the comparator to **Equals**, and enter the expected value (for example, `user@example.com`).
5. Click **Create Update** to save.
**Verify it worked:** The step now shows two validation badges — one for status code, one for the payload field. Run the test case by clicking **Run** in the top toolbar. Open the execution results and confirm both assertions pass with green checkmarks.
> **Important:** If you are unsure of the exact JSON path, run the step once without payload validation. Open **Run History**, select the step, and navigate to the **Response Body** tab to see the full JSON structure. Use that structure to construct the correct path.
***
## Step 3: Chain an authenticated request
Most real APIs require authentication. In this step, you add an authentication call before the GET request and chain the resulting token into the second step's headers.
### Add an auth step
1. In the test case step list, click **Add Step** above your existing GET step so the auth step runs first.
2. Select **API** in **Create a New Step**.
3. Configure the authentication request:
| Field | Value |
| --------------- | ------------------------------------------------------------------ |
| **HTTP method** | POST |
| **URL** | `https://api.example.com/auth/login` (your auth endpoint) |
| **Headers** | `Content-Type`: `application/json` |
| **Body** | `{"username": "testuser@example.com", "password": "TestPass123!"}` |
4. Under **Store response**, enter `authResult`.
5. In **Validation**, add a status code assertion: **status** equal `200`.
6. Click **Create** to save.
After this step runs, the access token is available at `authResult.body.access_token` (adjust the path to match your API's response structure).
### Inject the token into the GET step
1. Open the API testing panel on your existing GET step (step 2 in the test case).
2. In the **Headers** section, add a new header:
| Key | Value |
| --------------- | ---------------------------------------- |
| `Authorization` | `Bearer ${authResult.body.access_token}` |
3. Click **Create Update** to save.
At execution time, ContextQA resolves `${authResult.body.access_token}` using the live token from step 1. Because the token is captured fresh on every run, the test works even when tokens expire between sessions.
**Verify it worked:** Run the full test case. Both steps should pass:
| Step | Expected outcome |
| ------------------------- | ----------------------------------------------------------------------- |
| Step 1 (POST /auth/login) | Status `200`, token stored in `authResult` |
| Step 2 (GET /users/1) | Status `200`, `Authorization` header resolved, payload assertion passes |
{% hint style="warning" %}
**Common mistake:** If step 2 fails with a `401` status, check that the `Authorization` header value exactly matches the path to the token in the auth response. Open **Run History** for step 1, navigate to the **Response Body** tab, and confirm the path — for example, some APIs return the token under `authResult.body.token` rather than `authResult.body.access_token`.
{% endhint %}
***
## Step 4: Run and review the results
With both steps configured, run the complete test case and review the evidence.
1. Click **Run** in the top toolbar.
2. Select an execution environment from the dialog and click **Run**.
3. The execution begins. Each API step shows a real-time pass/fail indicator as it completes.
When execution finishes, click **View Detailed Report**.
### What to check in the results
**Step-by-step breakdown** — each step shows:
* Pass/fail status for every validation assertion
* The full request sent (method, URL, headers, body)
* The full response received (status code, headers, body)
* Execution duration per step
**Response Body tab** — select any step to inspect the raw JSON response. Use this to:
* Confirm variable values were resolved correctly (check that `${authResult.body.access_token}` was replaced with an actual token in step 2's request headers)
* Copy JSON paths for additional assertions you want to add later
* Diagnose unexpected response structures
**Network log** — the **Network** tab shows every HTTP request made during execution, including timing and status codes. Use this to identify slow endpoints or unexpected redirects.
| Result | What it means |
| --------------------------- | ----------------------------------------------------------------------------------------------- |
| Both steps pass | Authentication and data retrieval work correctly |
| Step 1 fails (auth) | Credentials are wrong, the auth endpoint changed, or the API is down |
| Step 1 passes, step 2 fails | The token is valid but the data endpoint has an issue — check the status code and response body |
***
## Summary
You built a complete API test in four steps:
1. **Created an API test case** with a GET request using the REST API step type
2. **Added validation** — a status code assertion and a payload assertion targeting a specific JSON field
3. **Chained an authentication call** by storing the auth response in a variable and injecting the token into the next step's headers
4. **Ran the test** and reviewed per-step results including request/response details and assertion outcomes
One test case now validates authentication and data retrieval in a single automated flow.
## Next steps
* **Add more assertions:** Validate additional response fields — check that `userResult.body.id` is a number, that `userResult.body.roles` contains the expected values, or that `userResult.headers.content-type` equals `application/json`.
* **Import from a Swagger specification:** If your API has an OpenAPI spec, import it to generate test cases for every endpoint and status code combination automatically. See [Creating API tests](/api-testing/creating-api-tests#generating-tests-from-a-swagger-or-openapi-specification).
* **Add structure validation:** Assert the full response shape to catch field additions or removals between deployments. See [Validating responses](/api-testing/validating-responses#structure-validation).
* **Build hybrid API + UI tests:** Chain an API response into a browser step — for example, create a user via the API and then verify the user appears in the UI. See [API chaining](/api-testing/api-chaining#hybrid-api--ui-chaining).
* **Run in CI/CD:** Add your API test to a test plan and trigger it from GitHub Actions or Jenkins on every pull request. See [GitHub Actions](/integrations/github-actions) or [Jenkins](/integrations/jenkins).
## Related pages
* [API Testing Overview](/api-testing/api-testing) — capabilities and concepts for API testing in ContextQA
* [Creating API tests](/api-testing/creating-api-tests) — all methods for creating API test cases, including Swagger import
* [Validating responses](/api-testing/validating-responses) — payload validation, structure validation, and header assertions
* [API chaining](/api-testing/api-chaining) — passing data between API calls and hybrid API + UI flows
* [Mock API testing](/api-testing/mock-api-testing) — recording and replaying API responses for stable tests
* [Running tests](/execution/running-tests) — execution options for test cases, suites, and plans
{% hint style="info" %}
**Test your API in minutes — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see API testing with your endpoints.
{% endhint %}
# Mock API Testing
Capture real API responses during test execution and replay them as mocks on future runs for faster, more stable tests.
## Quick answer
Capture real API responses during test execution and replay them as mocks on future runs for faster, more stable tests. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA engineers, and developers who want to isolate UI tests from backend variability by recording and replaying API responses.
{% endhint %}
Mock API testing lets ContextQA automatically capture every API response made during a test run and replay selected responses on subsequent runs. This eliminates flaky failures caused by slow or unreliable backend services and makes test execution faster by skipping live network calls for known endpoints.
The feature operates in two modes:
* **Recording (store)** — the test executes against the live backend. Every fetch and XHR call is intercepted, and its response is saved to the mock configuration for that test case.
* **Replaying (restore)** — on future runs, matching API calls receive the previously recorded response instead of hitting the live backend.
You control which APIs are mocked and which remain live on a per-test-case basis through the **Mock Config** drawer.
## Prerequisites
* Mock API testing is enabled at the organization level (see [Enable mock API testing](#enable-mock-api-testing-organization-level) below).
* You have at least one test case that has been executed at least once so that API responses have been captured.
***
## Enable mock API testing (organization level)
An organization administrator enables mock API testing for the entire workspace. Once enabled, ContextQA automatically captures API responses on the first execution of each new test case.
### Steps
1. Navigate to **Settings → Organization Setting**.
2. Select the **AI Configuration** tab (or scroll to the **Mock API Testing** section).
3. Enable the **Enable Mock API Testing** toggle.
4. Click **Save**.
A confirmation banner appears: *"Mock API Testing is enabled. Users can configure per-API mock settings on individual test cases."*
| Setting | Description |
| --------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------ |
| **Enable Mock API Testing** | When enabled, ContextQA automatically captures API responses on the first execution of each new test case and replays them in future runs. |
{% hint style="warning" %}
Disabling mock API testing at the organization level stops new API responses from being captured. Existing mock configurations on individual test cases are preserved but not replayed until the setting is re-enabled.
{% endhint %}
***
## View mock API results in a test run
After a test case executes with mock API testing enabled, the run results screen includes a **Mockup APIs** tab alongside the existing **Analysis**, **Configuration**, and **Recent Runs** tabs. This tab appears only when the run has mock API activity.
### What the Mockup APIs tab shows
**Run header** — displays the run status (Passed, Failed, Aborted, Queued, Stopped, or Not Executed), run number, execution date, and duration.
**Mode pill** — indicates the mock mode for this run:
| Pill label | Meaning |
| ---------------- | --------------------------------------------------------------------------- |
| **Recording** | API responses were captured and saved during this run (store mode). |
| **Replaying** | Saved mock responses were replayed for matching API calls (restore mode). |
| **Auto-capture** | Mock API capture is enabled and responses are being recorded automatically. |
| **Capture off** | Mock API capture is disabled for this test case. |
**API capture summary card** — shows three metrics:
| Metric | Description |
| ----------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Browser calls** | Total number of browser-initiated network calls during the run. |
| **Total APIs captured** | Number of fetch/XHR calls recorded as mocks (in recording mode) or served from mocks (in replay mode). Click the count to jump to the **Network** tab. |
| **REST step calls** | Number of API calls made from dedicated REST test steps. |
A footer note links to **Mock Config** where you can select which APIs to replay as mocks on future runs.
{% hint style="info" %}
If the test case failed, the Mockup APIs tab shows a placeholder message instead of the summary card: *"Mock API results are not available. This test case failed during execution, so mock API responses were not captured or stored."*
{% endhint %}
***
## Network log mock status
The **Network** tab in the run results now includes a **Mock Status** column for each network request. Each request displays one of three badges:
| Badge | Color | Meaning |
| ------------ | ----- | ------------------------------------------------------------------- |
| **Recorded** | Blue | This API response was captured and saved as a mock during this run. |
| **Mocked** | Green | This API response was served from a previously stored mock. |
| **Live** | Grey | This API call hit the live backend and was not mocked. |
Use the mock status column to verify which endpoints are being mocked and which are still hitting the live server.
***
## Configure mocks per test case
The **Mock Config** drawer lets you choose exactly which captured APIs should be replayed as mocks on future runs. You access it from the test case detail side panel.
### Open the Mock Config drawer
1. Open a test case from **Test Cases**.
2. In the test case detail side panel, locate the **API Mocking** card.
3. Click **Configure** (or the equivalent button on the card) to open the Mock Config drawer.
### Mock Config drawer layout
The drawer displays:
* **Header** — title, mocked count (e.g., "12 / 45 mocked"), and a close button.
* **Stats row** — four summary cards:
* **Captured from** — the run number and date the mocks were captured.
* **Total APIs** — total number of captured API endpoints.
* **Mocked** — number of APIs currently set to mock.
* **Coverage** — a progress bar showing the percentage of APIs mocked.
### Filter and search
Use the toolbar to filter the API list:
| Filter | Options |
| --------------- | ------------------------------------- |
| **Mock status** | **All**, **Mocked**, **Live** |
| **HTTP method** | **GET**, **POST**, **PUT** |
| **Search** | Search by URL, method, or status code |
### Toggle mocking for individual APIs
Each row in the table shows the HTTP method, URL, status code, call count, and a **Use Mock** toggle. Enable the toggle to mock that API on future runs; disable it to let the call hit the live backend.
### Bulk actions
* **Mock all** — enables mocking for every captured API.
* **Clear all** — disables mocking for every captured API.
### Save your configuration
1. Review the selected mock/live assignments.
2. Click **Save Configuration** to persist your choices.
3. Click **Cancel** to discard changes and close the drawer.
The mocked API count on the test case side panel updates to reflect the saved configuration.
***
## Toggle capture vs. replay mode
Each test case has a **Renew API responses** toggle on the API Mocking card in the side panel. This toggle controls the mock mode for the next run:
| Toggle state | Next run behavior |
| ---------------- | ------------------------------------------------------------------------------------------------------ |
| **On** (restore) | Matching API calls receive previously recorded responses. New or unmatched calls hit the live backend. |
| **Off** (store) | All API responses are captured fresh, overwriting previously stored mocks. |
The toggle saves automatically when changed outside of edit mode. If you are editing the test case details, the toggle change is saved when you click **Save Changes**.
***
## How it works end-to-end
1. **Enable** mock API testing in **Settings → Organization Setting**.
2. **Run** a test case for the first time. ContextQA records all API responses (store mode).
3. **Review** the captured APIs in the **Mockup APIs** tab of the run results.
4. **Configure** which APIs to mock by opening the **Mock Config** drawer from the test case side panel.
5. **Toggle** the test case to restore mode (Renew API responses on).
6. **Re-run** the test case. Mocked APIs return recorded responses; other calls hit the live backend.
7. **Verify** in the Network tab that the expected requests show a **Mocked** badge.
***
## Tips and best practices
* **Start with full capture, then prune.** Let the first run capture all APIs, then disable mocking for endpoints that return dynamic data (timestamps, random IDs) that your assertions do not validate.
* **Re-record after backend changes.** When the backend API contract changes, turn off the Renew API responses toggle and run the test case once to capture fresh responses, then re-enable replay.
* **Use the Network tab to troubleshoot.** If a test fails unexpectedly in replay mode, check the Mock Status column. A **Live** badge on an endpoint you expected to be mocked may indicate the request signature changed (different URL parameters, headers, or body).
* **Combine with API chaining.** Mock API testing works alongside API chaining. Responses captured from chained API steps are also eligible for mocking.
## Troubleshooting
**The Mockup APIs tab does not appear in the run results** Mock API testing may not be enabled at the organization level, or the test run did not make any fetch/XHR calls. Verify the organization setting is enabled and that the test case includes steps that trigger API calls.
**Mocked responses are outdated and causing test failures** Turn off the **Renew API responses** toggle on the test case, run the test once to capture fresh responses, then re-enable the toggle. Open the Mock Config drawer to verify the updated status codes and response data.
**The Mock Config drawer shows "No mock configurations found"** Adjust the active filters or search term. If no filters are active, the test case may not have been run with mock API testing enabled. Run the test case at least once with the organization-level setting enabled.
**Coverage percentage is lower than expected** Some API calls may not be eligible for mocking (for example, WebSocket connections or non-HTTP requests). The coverage metric reflects only fetch and XHR calls.
## Related pages
* [API Testing Overview](/api-testing/api-testing)
* [Creating API Tests](/api-testing/creating-api-tests)
* [API Chaining](/api-testing/api-chaining)
* [Running Tests](/execution/running-tests)
* [Debugging Tests](/execution/debugging-tests)
{% hint style="info" %}
**Eliminate flaky tests caused by unreliable backends.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See how ContextQA's mock API testing stabilizes your test suite.
{% endhint %}
# Salesforce Testing Overview
Overview of Salesforce testing in ContextQA — why Salesforce requires a different automation approach, what ContextQA handles automatically, and how to get started.
## Quick answer
Overview of Salesforce testing in ContextQA — why Salesforce requires a different automation approach, what ContextQA handles automatically, and how to get started. Use this page to choose the relevant workflow guide, understand the available capabilities, and navigate to the supporting instructions.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs and QA managers responsible for testing Salesforce orgs — including Lightning Experience, dynamic DOM changes, and multi-step business process workflows.
{% endhint %}
Salesforce is a packaged CRM platform, and that makes it a genuinely difficult target for automated testing. Standard web automation approaches that work well on custom-built applications tend to be brittle against Salesforce because the platform's DOM changes frequently — element IDs and attributes are regenerated across releases, patches, and even between page loads.
ContextQA is built to handle this. Its AI layer captures richer element metadata than a locator alone, which means test steps can survive Salesforce UI changes that would break selector-based scripts.
## Interactive demo: Salesforce automation overview
Explore the Salesforce automation lifecycle before building a test. The guided tour connects resilient Lightning interactions, reusable data, execution, and evidence for business workflows that cross records and systems.
{% embed url="" %}
### What to notice
* Test intent and element context remain reviewable instead of being reduced to generated DOM identifiers.
* Reusable login, environment, and data configuration keep business cases focused on their actual outcome.
* Salesforce UI actions can be combined with API validation when a visible screen alone does not prove the result.
## Why Salesforce testing is unique
**Dynamic DOM and changing IDs.** Salesforce Lightning generates element identifiers programmatically. A locator that worked last week may point to nothing after a Salesforce update. Tests that rely solely on CSS selectors or XPath expressions degrade quickly.
**Frequent platform updates.** Salesforce releases three major updates per year (Winter, Spring, Summer) plus continuous patch releases. Any of these can change the DOM structure of Lightning components, list views, or record pages.
**Packaged UI patterns.** Salesforce uses its own component library (Lightning Web Components and Aura). These components use Shadow DOM boundaries and non-standard markup that standard automation frameworks do not handle well out of the box.
**Core workflow coverage.** QA engineers testing Salesforce are typically responsible for verifying end-to-end business processes: lead conversion, opportunity management, case handling, account data entry, and approval workflows. These involve multiple pages, lookups, related lists, and conditional logic — all of which must be covered accurately.
## What ContextQA handles automatically
**AI-driven element resolution.** When ContextQA records a test session, it captures both the element locator and additional metadata about the element's role, label, position, and surrounding context. When the locator changes after a Salesforce update, the AI uses the stored metadata to locate the correct element. This substantially reduces the number of broken tests following a platform upgrade.
**Intelligent wait state handling.** Salesforce pages and background jobs load asynchronously. ContextQA waits for each required element or page to be ready before proceeding to the next step, rather than using fixed time delays. This keeps parallel test runs stable even when different test cases are interacting with records that are being saved or pages that are still loading.
**Parallel execution.** Multiple Salesforce test cases can run simultaneously against the same environment or different environments. Each test case manages its own wait state independently, so slow-loading records in one test do not block other tests from proceeding.
## Test case generation options
ContextQA supports recording-based test case creation for Salesforce:
* Start a recording session from the ContextQA dashboard.
* Perform the Salesforce workflow you want to automate — navigating to a record, filling in fields, clicking action buttons, submitting forms.
* ContextQA captures each interaction as a test step with full element metadata.
The result is a test case that can be edited, extended with data profiles, and organized into test plans for scheduled or on-demand execution.
### Author stable Lightning steps
Recording is a starting point, not proof that a locator will survive a Salesforce release. After recording:
1. Open each captured step and review the selected element and locator metadata.
2. Prefer accessible labels, roles, field names, and visible text over generated IDs, positional selectors, or deep CSS/XPath paths.
3. Add an outcome verification after important saves, conversions, approvals, or navigation changes.
4. Re-run the test in a clean session and review any self-healing evidence before accepting a changed locator.
ContextQA can use stored metadata to resolve many Lightning elements, but it cannot pierce every closed Shadow DOM boundary, cross-origin iframe, or Salesforce security restriction. When a surface is inaccessible, use a Salesforce-supported interaction or API for that operation and keep a UI verification at the point where the user-visible outcome matters. Validate critical suites after each Salesforce seasonal release.
## Data handling
Salesforce tests frequently need to run the same workflow with multiple sets of input data — different users, different record types, or different field values. ContextQA's test data profiles support this through **parameters** (external input values injected into steps) and **variables** (values captured at runtime and reused in later steps). A for-loop construct iterates over each row in a data profile, running the enclosed steps once per data set.
See [Test Generation and Execution](/salesforce-testing/test-generation-and-execution) for the full walkthrough.
## Key considerations
**Sandbox vs. production.** Always develop and run tests against a Salesforce sandbox. Running automation against a production org risks modifying live records. Use environment variables or test data profiles to target the correct org URL and credentials per environment.
**Data isolation.** Tests that create Salesforce records should not rely on those records persisting between runs unless the test explicitly reads them back. Plan for cleanup steps, or use sandbox refresh cycles to restore a clean data state.
**Test plan structure.** Organize Salesforce test cases into test plans grouped by module or workflow (for example, Leads, Opportunities, Cases). This makes it straightforward to run only the tests relevant to a specific Salesforce change.
{% hint style="info" %}
**AI-assisted Salesforce testing without Salesforce expertise** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Test Generation & Execution
Recording Salesforce test cases in ContextQA, managing test data with profiles and parameters, and running tests in parallel with execution logs.
## Quick answer
Recording Salesforce test cases in ContextQA, managing test data with profiles and parameters, and running tests in parallel with execution logs. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs and QA managers who need to record, parameterize, and execute Salesforce test cases — including data-driven runs and parallel execution across sandboxes.
{% endhint %}
This page covers the full lifecycle of a Salesforce test case in ContextQA: recording, data management, execution, and reviewing logs.
## Interactive course: create and run your first Salesforce test
The two course segments show how a reusable Salesforce test is authored and then run. They are ungated, so you can follow the captured workflow without a ContextQA or Salesforce login.
### Part 1 — Create the test case
{% embed url="" %}
### Part 2 — Run the Salesforce login test
{% embed url="" %}
### What to notice
* A reusable login case can become a prerequisite instead of being copied into every Salesforce scenario.
* Captured steps retain human-readable intent and element context for review after Lightning changes.
* The run result connects each action, validation, and evidence item to the same execution.

The example above verifies an opportunity stage and stage-history outcome after reusing a dedicated Salesforce session prerequisite. This keeps authentication separate from the business assertion and makes the same logged-in setup available to multiple lead, opportunity, CPQ, and service scenarios. For lifecycle-level coverage and measurable business outcomes, see [Salesforce and enterprise workflows](/business-use-cases/salesforce-and-enterprise-workflows).
## Recording a Salesforce test session
ContextQA creates test cases by recording your interactions with the Salesforce UI. The recorder captures not just the element locator but also metadata — label, role, surrounding context — so the AI can re-locate elements even after Salesforce regenerates its DOM identifiers.
1. In ContextQA, click the **plus (+) icon** to start a new scenario.
2. Select **Start recording** (or choose an existing scenario to extend).
3. Perform the Salesforce workflow you want to automate: navigate to a record, fill in fields, click action buttons, submit forms.
4. Stop the recording when the workflow is complete.
5. Click the **Edit icon** (three dots) on any step to review the captured locator and metadata. ContextQA stores both, which is what makes the test resilient to UI changes between Salesforce releases.
Because ContextQA records metadata alongside locators, you rarely need to update test steps after a Salesforce patch or seasonal update. The AI resolves the correct element using stored context even when the locator has changed.
## Executing a recorded test case
1. Open the test case in ContextQA.
2. Click **Run**.
3. Wait for execution to complete. ContextQA's intelligent wait state handling ensures each step proceeds only after the required Salesforce element or page is ready — no fixed delays needed.
4. Review the results in the execution view. A passing test confirms the workflow completed successfully despite any Salesforce UI changes since the last run.
## Interactive demo: execute a Salesforce test with dynamic data
Use this walkthrough to see a saved Salesforce case execute with data resolved at runtime instead of relying on hard-coded record values.
{% embed url="" %}
### What to notice
* Environment and profile values are selected independently from the Salesforce test logic.
* Dynamic values make repeated runs less likely to collide with existing sandbox records.
* The execution report preserves the resolved outcome while protected values remain outside the test description.
## Managing test data with profiles
Hardcoding values like usernames, passwords, or record field data into test steps makes tests brittle and difficult to maintain. ContextQA separates test data from test logic using **test data profiles**, **parameters**, and **variables**.
### Parameters vs. variables
| Concept | What it is | When to use it |
| --------- | ----------------------------------------------------------- | ------------------------------------------------------------------------------------- |
| Parameter | An input value injected from a test data profile | Usernames, passwords, record field values provided before the test runs |
| Variable | A value captured during execution and reused in later steps | Order IDs, confirmation numbers, or any value generated by the application at runtime |
### Creating a test data profile
A test data profile is a table of input values — each row is one data set. For a Salesforce login test, a profile might contain several rows, each with a different email address and password.
Navigate to the test data profiles section in ContextQA to view existing profiles or create a new one for your Salesforce module.
### Connecting a test case to a test data profile
1. Open the Salesforce test case you want to parameterize.
2. Click **Add step** and hover over the menu icon.
3. Choose **For loop**. Select your test data profile, set the loop boundaries to **Start Loop** and **End Loop**, and click **Create**.
4. Click **Reorder** and drag all relevant test steps underneath the for-loop step so they execute within the loop.
5. Click **Update** to save the reordered test case.
### Replacing hardcoded values with parameters
1. Find a step that contains a hardcoded value you want to replace (for example, a username or password field).
2. Click the **Edit icon** on that step.
3. Remove the hardcoded value from the field.
4. Click **Parameter** and select the parameter that corresponds to the column in your test data profile (for example, `user_email` or `password`).
5. Click **Update** to save the step.
Repeat for every step that contains data you want to drive from the profile.
### Running with a test data profile
1. Click **Run** on the test case.
2. Choose **execution** from the run options.
ContextQA fetches each row from the test data profile and executes the for-loop steps once per row. The execution history shows one result per data set, making it easy to see which inputs passed and which failed.
## Parallel execution and test plans
For large Salesforce test suites, parallel execution reduces total run time and provides faster feedback.
### Setting up a test plan for parallel execution
1. Navigate to **Plans → Test Plans** in ContextQA.
2. Open the test plan that contains your Salesforce test cases.
3. Click the **Edit icon** on the test plan.
4. Go to the **Test Machine and Issue** section. Add your test suite and select a browser (for example, **Chrome**).
5. Click **Add** to save the machine configuration.
6. Open **Test Plan Settings** and set the parallel execution count — options include 5, 10, 15, 20, or more depending on your project.
7. Click **Update** to save, then click **Run** to execute the test plan.
ContextQA runs the configured number of test cases simultaneously. Each test case manages its own wait state independently, so a test that is waiting for a Salesforce record to save does not block other tests from proceeding.
## Reading execution logs
After a test plan runs, open **Run History** to review results.
* The run history shows the pass/fail status for every test case in the plan.
* Click any test case entry to open the detailed execution log, which includes each step, its pass/fail status, and timestamps.
* For failed steps, the log shows what was expected and what actually occurred. Common causes in Salesforce tests: a field was not found because of a UI change, a record was not saved before the next step attempted to read it, or test data was invalid for the target environment.
Use the timestamps to identify slow steps that might indicate Salesforce performance issues or timing problems in a specific environment. If a test is consistently failing in a particular sandbox but passing elsewhere, compare the environment configuration and data state rather than assuming a test logic error.
{% hint style="info" %}
**AI-assisted Salesforce testing without Salesforce test expertise.** [**Book a Demo →**](https://contextqa.com/book-a-demo/?utm_source=learning_contextqa\&utm_medium=documentation\&utm_campaign=salesforce_interactive_demo\&utm_content=test_generation_execution) — See ContextQA automate Salesforce Lightning UI testing for your org.
{% endhint %}
# Execution Overview
Run, schedule, and monitor test executions across browsers and environments — with parallel runs, video evidence, and full execution traceability.
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who need to run tests reliably across environments, scale execution with parallelism, and review detailed evidence for every run.
{% endhint %}
ContextQA's execution engine handles everything from a single ad-hoc test run to scheduled parallel suites across multiple browsers and environments. Every execution captures video recordings, screenshots, HAR logs, and Playwright traces so you always have the evidence you need to diagnose failures and prove coverage.
## Quick answer
ContextQA can execute an individual case or a plan-based collection of suites immediately, on a schedule, through an approved CI/CD workflow, or through authenticated MCP tools. The selected plan controls its suites and execution settings, while the resulting run exposes status and available evidence for review. Validate a plan interactively before making it a release gate.
***
## How execution works
1. **Select what to run** — Pick an individual test case, a test suite, or an entire test plan.
2. **Choose the environment** — Select a preconfigured environment that defines the base URL, variables, and browser settings.
3. **Execute** — Run immediately, schedule for later, or trigger from a CI/CD pipeline or MCP tool.
4. **Monitor in real time** — Watch execution progress on the Execution Dashboard as results stream in.
5. **Review evidence** — Every run produces video, screenshots, network logs, and trace files for step-level debugging.
***
## Key capabilities
* **Parallel execution** — Run multiple test cases simultaneously across browsers and environments to cut total execution time.
* **Environment management** — Define named environments with base URLs, global variables, and execution parameters so the same tests work against dev, staging, and production.
* **Scheduling** — Set up recurring runs on hourly, daily, or weekly intervals without any external scheduler.
* **Execution evidence** — Video recordings, step-level screenshots, HAR network logs, and downloadable Playwright traces are captured automatically for every run.
* **CI/CD and MCP integration** — Trigger runs from GitHub Actions, Jenkins, GitLab CI, or directly from an AI coding agent through the ContextQA MCP Server.
* **Private-network and remote-grid execution** — Reuse organization proxy and remote-browser profiles from a test case or plan.
***
## In this section
| Page | What it covers |
| ------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------- |
| [Running Tests](/execution/running-tests) | Run individual test cases, suites, or plans manually or via MCP tools |
| [Parallel Execution](/execution/parallel-execution) | Execute tests in parallel across browsers and environments for faster results |
| [Environments](/execution/environments) | Configure test environments with base URLs, variables, and execution parameters |
| [Proxy & Remote Browser Profiles](/execution/proxy-and-remote-browser-profiles) | Route a case or plan through a saved proxy or remote WebSocket browser endpoint |
| [Scheduling](/execution/scheduling) | Schedule test runs on recurring intervals (hourly, daily, weekly) |
| [Video & Screenshots](/execution/video-and-screenshots) | Review execution evidence including video recordings, screenshots, HAR logs, and Playwright traces |
| [Interactive Demo](/execution/demo) | Interactive demo of execution features |
***
## Related sections
* [Creating Test Cases](/web-testing/creating-test-cases) — build the test cases that the execution engine runs
* [Reporting](/reporting/reporting) — analyze pass rates, failure trends, and execution history after runs complete
* [Integrations](/integrations/integrations) — trigger executions from CI/CD pipelines and push results to Jira or Azure DevOps
{% hint style="info" %}
**Cut execution time with parallel cross-browser runs** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Running Tests
Run individual ContextQA tests or test plans, monitor live case and plan execution, stop active plans, review results, and trigger runs through MCP.
## Quick answer
Run one test case from its **Test Cases** detail page for focused feedback. To execute a suite, add it to a test plan and choose **Run Now**. Monitor an active plan from **Runs → Live execution**, where ContextQA separates running cases from queued cases; select the run summary for its report or **Stop Run** to interrupt the remaining work.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA managers, and engineering managers who need to run test cases, suites, and plans — manually, on a schedule, or triggered from a CI/CD pipeline.
{% endhint %}
In the portal, you can run a single test case for focused feedback or run a test plan for suite-based coverage. A test suite organizes cases, while the test plan supplies the browser or device, environment, parallelism, and other execution settings. Depending on the test type and run configuration, evidence can include screenshots, video, network logs, console logs, and root cause analysis. Executions can also be triggered from supported automation surfaces.
## Prerequisites
* You have at least one test case created and saved.
* You have an environment configured with a valid base URL.
* For test plan execution: you have a test plan configured with at least one suite and an environment selected.
***
## Running a Single Test Case
Running a single test case is the primary feedback loop during test authoring. Use it to verify a new test case immediately after creation, or to investigate a failing step in isolation.
### Steps
1. Open the test case from **Test Cases**.
2. In the test case editor, click the **Run** button (▶) in the top toolbar.
3. A dialog appears asking you to confirm the execution environment. Select the environment from the dropdown and click **Run**.
4. The test is queued immediately. A banner appears at the top of the editor showing the execution status.
5. Click **View Live Execution** (or the execution ID link in the banner) to open the live execution viewer.
The test case executes step by step. Each step shows a real-time pass/fail indicator as it completes.
***
## Running a Test Suite Through a Test Plan
The Test Suite detail page does not have a direct **Run Suite** action. To run every case in a suite from the portal, add the suite to a test plan and run that plan. This keeps the execution target, environment, and parallelism explicit and reusable.
### Steps
1. Open **Plans → Test Plans**.
2. Create a plan or open an existing plan that contains the required suite.
3. Confirm the suite is mapped to the intended browser or device and that the plan uses the correct environment.
4. Return to the **Test Plans** list and click **Run** in the plan's **Actions** column. You can also open the plan and use **Run Now**.
5. Open the plan's **Runs** tab. During an active run, select **Live execution** to review running and queued cases, or **Run history** to inspect earlier runs.

The plan queues the cases in its suites according to its saved execution configuration. The resulting report groups outcomes by suite and test case.
***
## Running a Test Plan
A test plan execution is the most complete form of test execution. It runs multiple suites against configured browsers and an environment, and is the entry point for CI/CD automation and scheduled runs.
### Steps
1. Navigate to **Plans → Test Plans**.
2. Click on the test plan name to open it.
3. Click **Run Now** in the plan header. The execution starts immediately using the plan's configured suites, browsers, and environment.
The plan begins executing. All configured suites start based on the plan's parallelism settings. Results are grouped by suite and test case in the execution report.
If the plan has no executable test cases, **Run Now** is disabled. Add cases to a selected suite before retrying.
***
## Monitor a test plan in real time
The plan-level **Live execution** view answers a different question from the single-test viewer: it shows how work is distributed across the active plan.
1. Open the plan and select **Runs**.
2. Select **Live execution** while the plan is active.
3. Review **RUNNING** and **QUEUED** totals at the top.
4. In the executing list, confirm each case's suite and browser or device.
5. Review the queued list for cases waiting for an execution slot.
6. Select the run ID summary to open the corresponding report.
The **Test Plans** and **Schedules** page headers also show organization execution capacity: running executions, the parallel capacity limit, and queued work. Use this before starting a plan to anticipate whether it will run immediately.
To interrupt an active or queued plan, select **Stop Run** from the plan's run control. Completed work remains available in the run report; cases that did not finish are reflected in the final run outcome.
***
## Monitor an individual test in real time
### Open a live run from an external trigger
An Azure DevOps workflow, MCP agent, or another approved external trigger can return a ContextQA live-run link. After an authenticated user opens it, the entry page displays **Connecting to your run**, the test-case ID, and an elapsed timer while it looks for the execution session.
* If the run is live and joinable, ContextQA opens the live execution screen.
* If the run has already completed, ContextQA opens its result.
* If the live session is still starting, the page continues checking for up to approximately one minute before falling back to the saved result, the most recent result, or the test case.
Do not replace this link with a raw internal session URL. Share the published ContextQA live-run link only with users authorized for the same organization and workspace.
### Read the live execution viewer
When an individual test executes, clicking the execution link opens the live execution viewer. The viewer updates in real time via a WebSocket connection.
**Layout:**
```
┌─────────────────────────┬─────────────────────────────────────────┐
│ Step List │ Live Browser Screenshot │
│ │ │
│ ✓ Step 1: Navigate │ [Current browser state shown here] │
│ ✓ Step 2: Type email │ │
│ ✓ Step 3: Type password │ │
│ ▶ Step 4: Click Sign In │ │
│ Step 5: Verify dash │ │
│ │ │
├─────────────────────────┴─────────────────────────────────────────┤
│ Network Log: GET /api/session 200 OK POST /api/auth 200 OK │
└───────────────────────────────────────────────────────────────────┘
```
* **Left panel** — the full step list with real-time status icons:
* ✓ Green — step passed
* ✗ Red — step failed
* ▶ Blue — step currently executing
* ○ Grey — step not yet reached
* **Right panel** — a live screenshot of the browser at the current step. The screenshot refreshes after each step completes.
* **Bottom panel** — the network request log, showing each HTTP request as it is made during execution.
The live view remains open after execution completes, allowing you to scroll through screenshots and network entries without leaving the view.
***
## Execution disruption and automatic retry
If a live execution is disrupted, ContextQA tries to recover your run automatically instead of leaving it in a failed state.
When this happens, a recovery dialog opens over the live execution view with a short countdown. The dialog identifies the recovery action available for your run and starts it when the countdown ends.
### Recovery dialog controls
While the countdown runs, you can:
| Button | What it does |
| ------------------------------------------------- | ---------------------------------------------------------------------------- |
| **Rerun now** / **Reconnect now** | Starts the recovery immediately instead of waiting for the countdown. |
| **Cancel auto-rerun** / **Cancel auto-reconnect** | Stops the countdown and leaves the dialog open with a manual restart button. |
| **Back To Test Case** | Closes the dialog and returns to the test case without restarting. |
Closing the dialog in any way — clicking **Back To Test Case** or **Close**, pressing **Esc**, or clicking outside it — cancels the pending recovery, so nothing restarts unexpectedly.
If you cancel the countdown, the dialog stays open with a manual restart button. Use it to restart the run yourself whenever you are ready.
After ContextQA recovers a run for you, a banner confirms that your run has resumed. Dismiss the banner with its close button once you have read it.
The duration in the run header is re-anchored to the server-recorded execution start after a reconnect, rejoin, or temporary event gap. It therefore represents the run's total elapsed time rather than the time since you reopened the viewer.
{% hint style="info" %}
If ContextQA can't start a browser session when you begin a run — for example, during a period of high demand — the recovery dialog appears with a high-demand message and restarts your test.
{% endhint %}
***
## Viewing Results After Execution
When execution completes, click **View Detailed Report** from the execution summary banner or from the Execution History list.
The detailed report contains:
### Execution Summary
* Overall status: Passed / Failed / Aborted / Stopped
* Duration: total execution time
* Browser and version
* Environment used
* Number of steps: total, passed, failed, skipped
### Step-by-Step Breakdown
Each step is listed with:
* Pass/fail status
* Step description
* Screenshot captured at that step (click to view full size)
* Duration for that step
* Self-healing indicator (if the step was auto-healed)
* For failed steps: the AI-generated root cause analysis
### Video Recording
The report includes a full WebM recording of the browser session. Use the video to see exactly what happened in context — especially useful for failures that are hard to diagnose from static screenshots alone.
### Network Log
The network log is accessible from the **Network** tab in the report. Each request shows details such as the method, URL, status code, and response time, with request and response data where captured. Use the network log to:
* Identify 4xx or 5xx responses that caused UI failures
* Verify that the correct API endpoints were called with the correct payloads
* Diagnose authentication token expiry
### Console Log
The **Console** tab shows all browser console entries captured during execution, timestamped and correlated with the active step. Look for `console.error` entries to find JavaScript exceptions that may explain unexpected UI behavior.
### Root Cause Analysis
For any failed step, the **Root Cause** tab shows the AI-generated analysis. The root cause analysis:
* Identifies the most likely reason for the failure (element not found, assertion mismatch, network error, JavaScript exception)
* Distinguishes between test-level failures (the step was wrong) and application-level failures (the app has a bug)
* Suggests specific corrective actions (update the step description, fix the element reference, investigate the API error)
***
## Parallel Execution
Parallel execution runs multiple test cases or test suites simultaneously across multiple browser instances, reducing total execution time.
### Enabling Parallel Execution at the Test Plan Level
1. Open the test plan and click **Edit**.
2. In the plan settings step, set the **Parallel Node** count to control how many test cases execute simultaneously.
3. Enable the **Run Test Suites in Parallel** toggle to run all suites simultaneously, or leave it disabled to run suites one at a time.
4. Click **Save**.
**Concurrent browser limits** apply per workspace based on your subscription tier. If all concurrent slots are occupied, new test cases queue and start as slots become available.
***
## Execution from MCP / API
ContextQA exposes execution capabilities through the MCP server, allowing AI coding assistants and CI/CD scripts to trigger and monitor tests programmatically.
### Execute a Single Test Case
```python
# Via MCP tool call
execute_test_case(test_case_id=1234)
# Returns:
# { "execution_id": 9876, "status": "QUEUED" }
```
### Execute a Test Plan
```python
execute_test_plan(test_plan_id=789)
# Returns:
# { "execution_id": 9878, "status": "QUEUED", "suite_count": 3 }
```
### Polling for Execution Completion
```python
import time
test_case_id = 1234
while True:
status = get_execution_status(test_case_id=test_case_id, number_of_executions=1)
if "STATUS_COMPLETED" in status or "STATUS_FAILED" in status:
break
time.sleep(10)
print(f"Execution status: {status}")
```
### Retrieving Step Results
```python
# Get detailed step-by-step results
steps = get_test_step_results(result_id=47284)
for step in steps:
print(f"Step {step['stepIndex']}: {step['action']} — {step['status']}")
if step["status"] == "FAILED":
print(f" Screenshot: {step['screenshot_url']}")
# Use get_root_cause(execution_id=...) for the user-facing failure analysis.
```
***
## Re-running Failed Tests
After reviewing a failed execution, you can re-run either the full test case or only the failed steps.
**Re-run full test case:**
1. Open the execution report.
2. Click **Re-run Test Case** in the report header.
**Re-run from a specific step:**
1. Open the execution report.
2. Locate the first failed step.
3. Click the three-dot menu on that step → **Re-run from This Step**.
Re-running from a step is useful when the first few steps are setup steps that are known to be correct — skipping them saves time when iterating on a failing assertion.
***
## Tips & Best Practices
* **Always verify a new test case with a manual run before adding it to a test plan.** Running the test case once from the editor catches obvious issues before they pollute automated suite results.
* **Use parallel execution for independent tests.** If your test cases do not share state (each one starts from a fresh browser session), parallel execution provides the fastest feedback. Sequential execution should be reserved for cases with explicit state dependencies.
* **Monitor network logs for intermittent failures.** If a test fails sometimes and passes other times (flaky behavior), the network log often reveals an intermittent API timeout or a race condition in the application's data loading.
* **Set up Slack notifications for critical plan executions.** In the test plan settings, configure a Slack channel to receive execution results. This ensures failures are surfaced immediately rather than discovered during the next manual review.
* **Use the video recording for stakeholder communication.** When reporting a genuine application bug found by ContextQA, include the video recording in the bug report. Stakeholders who are not familiar with the test tool can immediately see what went wrong from the video.
## Troubleshooting
**Execution stays in QUEUED status for an extended period** Your workspace may have exhausted its concurrent execution slots. Check the Execution History list to see how many executions are currently RUNNING. If multiple long-running test plans are occupying all slots, wait for them to complete or contact support to increase your concurrency limit.
**Steps are failing due to "element not found" but the element is visible in the screenshot** The screenshot captures the browser state after the step attempted to act, not before. The element may have been present before the step but changed state (disappeared, became disabled, or was replaced by a loading spinner) during the step's execution. Check the network log for a slow API call that might have caused a loading state at the critical moment.
**The video recording is not playing in the report** Video recordings are processed asynchronously after execution completes, so a recording may not be available the moment the run finishes. If the video is not ready when you open the report, refresh the page after a short wait. If it remains unavailable, contact support.
**Parallel execution is producing intermittent failures that do not reproduce in sequential mode** This typically indicates that the test cases are sharing state they should not be sharing — for example, using the same user account in multiple parallel tests. Each parallel test should use a distinct user account or dataset to avoid conflicts.
## Related Pages
* [Scheduling Tests](/execution/scheduling)
* [Configuring Environments](/execution/environments)
* [AI Self-Healing](/web-testing/self-healing)
* [Platform Architecture](/getting-started/architecture-overview)
* [MCP Server](/mcp-server/overview)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full test suite in parallel CI/CD execution.
{% endhint %}
# Proxy & Remote Browser Profiles
Configure reusable proxy and remote browser profiles in ContextQA, assign them to test cases or plans, and keep connection secrets protected.
## Quick answer
Create organization-level connection profiles under **Settings → Organization Setting → Proxy** or **Remote Browser**, then select a profile in a test case or test plan. A proxy routes execution through an internal network; a remote browser sends execution to an external WebSocket browser endpoint. Remote browser profiles must pass **Test Connection** before they can be saved.
## What this page covers
{% hint style="info" %}
**Who is this for?** Administrators and SDETs who need ContextQA to reach private applications, route traffic through an approved network, or execute against a managed browser grid.
{% endhint %}
## Organization profile library

Profiles are reusable at organization scope. Create them once, then assign them from the test case or test plan that needs the connection.
| Profile | Required fields | Optional fields | Typical use |
| ------------------ | ------------------------------------------------------ | ------------------ | ----------------------------------------------------------------------- |
| **Proxy** | Name, **Proxy URL** such as `http://host:port` | Username, password | Reach an application through a corporate proxy or approved egress path. |
| **Remote Browser** | Name, **Remote Browser URL** such as `wss://host:port` | Username, password | Run against an external browser endpoint or browser grid. |
{% hint style="warning" %}
Use a dedicated automation credential with the minimum access required. Do not paste credentials into test-step text, test names, screenshots, or documentation.
{% endhint %}
## Add a proxy profile
{% stepper %}
{% step %}
### Open the Proxy section
Go to **Settings → Organization Setting**, then select **Proxy**.
{% endstep %}
{% step %}
### Enter the connection
Select **Add Proxy**. Enter a recognizable name and a proxy URL in `http://host:port` form. Add the username and password only when the proxy requires authentication.
{% endstep %}
{% step %}
### Save the profile
Select **Add Proxy**. The profile becomes available in test-case and test-plan settings.
{% endstep %}
{% endstepper %}
## Add a remote browser profile
{% stepper %}
{% step %}
### Open the Remote Browser section
Go to **Settings → Organization Setting**, then select **Remote Browser**.
{% endstep %}
{% step %}
### Enter the endpoint
Select **Add Remote Browser**. Enter a recognizable name and the WebSocket endpoint, normally in `wss://host:port` form. Add credentials only when the endpoint requires them.
{% endstep %}
{% step %}
### Test the connection
Select **Test Connection**. ContextQA enables saving only after the current URL and credentials pass the connection test. If you change the URL, username, or password after a successful test, test the connection again.
{% endstep %}
{% step %}
### Save the profile
Save the profile after the successful connection result appears.
{% endstep %}
{% endstepper %}
## Assign a profile
Choose the connection at the narrowest useful scope:
```mermaid
flowchart TD
A[Organization profile library] --> B[Test plan settings]
A --> C[Test case settings]
B --> D[Applies to cases run through that plan]
C --> E[Applies to that test case]
E --> F[Test-case selection takes precedence
when both scopes specify a profile]
D --> F
```
* Use the **test plan** setting when every mapped suite should use the same route or remote grid.
* Use the **test case** setting for a targeted exception.
* Select **None** when the case or plan should not use a saved profile.
* Requirement imports that create a plan can also expose proxy and remote-browser selections in their advanced configuration.
After assigning a profile, run a non-destructive smoke test before adding the profile to a broad regression plan.
## Secret-handling behavior
When you edit a saved profile, the password field opens blank. The stored secret is not loaded back into the browser.
* Leave the field untouched to keep the current credential.
* Enter a new value to replace it.
* If your organization rotates a password, retest the remote browser connection before saving.
This behavior reduces the chance of exposing a reusable credential in the portal or a screenshot.
## Troubleshooting
Save is disabled for a remote browser profile
Select **Test Connection**. Saving remains disabled until the current endpoint and credential values pass.
The profile does not appear in a test case or plan
Confirm that the profile was saved in the same organization, refresh the selector, and clear any search text. Profile lists are organization-specific.
The connection works locally but the ContextQA run cannot reach it
Confirm that the endpoint is reachable from the ContextQA execution environment, that the scheme and port are correct, and that network allowlists include the approved ContextQA execution source for your deployment.
## Related documentation
* [Test plans](/web-testing/test-plans)
* [Create test cases](/web-testing/creating-test-cases)
* [Environments](/execution/environments)
* [System configuration](/administration/system-configuration)
{% hint style="info" %}
**Need to test a private application or managed browser grid?** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See how ContextQA fits your network and execution architecture.
{% endhint %}
# Debugging Tests
Use the interactive debugger to step through test cases, set breakpoints, inspect live variables, capture video, review AI agent steps, and modify steps mid-session in ContextQA.
## Quick answer
Use the interactive debugger to step through test cases, set breakpoints, inspect live variables, capture video, review AI agent steps, and modify steps mid-session in ContextQA. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, testers, and developers who need to diagnose failing test steps, inspect runtime state, or iterate on test logic without re-running the entire test case from scratch.
{% endhint %}
The interactive debugger lets you execute a test case step by step with full control over the flow. You can pause execution at any step, set breakpoints, inspect live variable values, capture video clips, review AI-generated steps, and add, edit, or delete steps during the session. Changes you make can be saved back to the test case when the session ends.
## Prerequisites
* You have at least one test case with one or more steps.
* Your workspace license includes the **Debug** feature.
* You have an environment configured with a valid base URL.
***
## Starting a debug session
You launch a debug session from the test case details screen.
1. Open the test case from **Test Cases**.
2. Click the **More** menu (three-dot icon) in the test case header.
3. Select **Debug**.
4. The debug screen opens with a **Debug Mode** badge in the toolbar. Your test case steps load in the left panel and a live browser view appears in the right panel.
5. Click **Start Debugging** in the debug toolbar to begin execution.
The debugger connects to a live browser session via VNC. Execution pauses automatically at the first step so you can set breakpoints or review the step list before proceeding.
{% hint style="info" %}
ContextQA presents the live browser through an embedded noVNC viewer in the Debug screen. Users are not given a stable VNC host, password, or direct noVNC URL: connection details are internal, short-lived, and scoped to the execution. Open the session from the portal rather than copying or sharing its internal WebSocket endpoint.
{% endhint %}
{% hint style="info" %}
**Debug** is available for web test cases. For mobile test cases, VNC is disabled and a live screenshot stream is shown instead.
{% endhint %}
***
## Debug screen layout
The debug screen is a split-pane view with three main areas:
```
┌──────────────────────────────────────────────────────────┐
│ Header: Test case name · Status badge · Step progress │
│ Debug toolbar: Debug Mode · Pause/Step/Continue/Stop │
├────────────────────┬─────────────────────────────────────┤
│ │ │
│ Steps panel │ Live browser view / │
│ (left) │ video player (right) │
│ │ │
│ Tabs: │ VNC stream, screenshot │
│ Steps | Console │ preview, or captured │
│ Network | Live │ video playback │
│ Variables | │ │
│ AI Prompt │ │
│ │ │
├────────────────────┴─────────────────────────────────────┤
│ Inactivity warning banner (when idle) │
└──────────────────────────────────────────────────────────┘
```
### Header
Displays the test case name, a status badge (**Running**, **Paused**, **Completed**, **Failed**, or **Aborted**), a step progress bar (`X / Y Steps`), and platform metadata (browser, device, build name).
### Debug toolbar
Appears below the header when debug mode is active. Contains the **Debug Mode** badge, the current pause status (for example, "Paused at Step 5"), a session timer, and the execution control buttons described in the next section.
### Left panel tabs
| Tab | Description |
| ------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Steps** | Displays all test steps grouped by prerequisite and main test case. Each step shows its number, action, status, and duration. |
| **Console** | Shows browser console log entries (info, warning, error) with timestamps. |
| **Network** | Displays captured HTTP requests and responses in a table. |
| **Live Variables** | Shows a searchable, sortable table of all runtime variables and their current values. |
| **AI Prompt** | Displays an archive of AI prompts used during the session. Each entry shows the step number, step name, timestamp, prompt text, and the operation that triggered the archive (created, edited, duplicated, deleted, or converted). |
### Right panel
Shows a live VNC browser stream during execution, or a screenshot preview when the session is paused or complete. During a live debug session, the simulator header includes a **Live / Captured** toggle. The **Live** view shows the real-time VNC stream, while the **Captured** view shows video clips captured on demand during the session. After execution completes, the right panel switches to a video library containing the full session recording.
***
## Execution controls
The debug toolbar provides the following controls:
| Control | When available | What it does |
| ------------------- | ----------------------------------------- | -------------------------------------------------------------------------------------------------------------- |
| **Start Debugging** | Before the session starts | Begins step-by-step execution. Sends any pre-configured breakpoints and skipped steps to the execution engine. |
| **Step Over** | When paused at a step (not the last step) | Executes the current step and pauses at the next one. |
| **Continue** | When paused at any step | Resumes execution until the next breakpoint or the end of the test case. |
| **Pause** | While execution is running | Requests a pause after the current step completes. A spinner indicates the pause is pending. |
| **Stop** | While the debug session is active | Stops execution immediately and ends the debug session. |
| **Re Run** | After execution completes or is stopped | Resets the session and starts a fresh debug run. |
### More options menu
Click the **More** menu (vertical three-dot icon) in the debug toolbar for additional actions:
* **Jump to step** -- opens a dialog where you can select any step and restart execution from that point.
* **Restart from first step** -- restarts execution from the beginning of the test case.
* **View breakpoints** -- opens a dialog listing all breakpoints you have set.
* **Review session changes** -- opens a summary of all steps you added, edited, or deleted during the session (available after execution completes).
***
## Setting breakpoints
Breakpoints tell the debugger to pause execution before a specific step runs. You can set breakpoints before starting execution or while the session is paused.
### Adding a breakpoint
* In the **Steps** tab, click the breakpoint indicator on the left edge of a step row to toggle a breakpoint on or off.
* Alternatively, use the step's context menu and select **Toggle breakpoint**.
A breakpoint marker appears next to the step number. When execution reaches a step with a breakpoint, the debugger pauses and the toolbar shows "Paused at Step N".
### Viewing and removing breakpoints
1. Click the **More** menu in the debug toolbar and select **View breakpoints**.
2. The **Breakpoints** dialog lists every breakpoint with the step number and description.
3. To remove a single breakpoint, toggle it off from the step row in the **Steps** tab.
4. To remove all breakpoints at once, click **Remove all breakpoints** in the dialog.
***
## Skipping steps
You can mark steps to be skipped during the debug run. Skipped steps are excluded from execution but remain visible in the step list with a "skipped" status indicator.
* In the **Steps** tab, use the step's context menu and select **Skip step**.
* To restore a skipped step, use the context menu again and select **Unskip step**.
***
## Inspecting live variables
The **Live Variables** tab displays all runtime variables in a searchable table. Variables update as each step executes, so you can see the current value of any variable at the point where execution is paused.
| Column | Description |
| --------- | ------------------------------------------------------------ |
| **Name** | The variable name (for example, `username`, `ENV.BASE_URL`). |
| **Value** | The current runtime value. |
* Use the search bar to filter variables by name.
* Click the **Refresh** button to reload variable values manually.
* When the debug session is active, you can edit variable values inline by clicking on a value cell.
***
## AI Prompt Archive
The **AI Prompt** tab records a history of every AI prompt used during the debug session. When you add, edit, duplicate, delete, or convert an AI agent step, the prompt text is archived automatically.
Each archive entry shows:
| Field | Description |
| --------------- | ---------------------------------------------------------------------------------------------------------- |
| **Step number** | The position of the step in the test case (for example, `6.2`). |
| **Step name** | The display name of the AI agent step. |
| **Timestamp** | When the operation occurred (for example, "Today, 12:04 PM"). |
| **Prompt text** | The full AI prompt that was sent to the agent. |
| **Operation** | The action that triggered the archive entry: `created`, `edited`, `duplicated`, `deleted`, or `converted`. |
| **Status** | A failed indicator appears if the step failed during execution. |
A sub-header displays the test case name and the total number of AI prompts used in the current run.
When no AI agent steps have been used in the session, the tab shows an empty state with the message "No AI prompts yet."
{% hint style="info" %}
The AI Prompt Archive is cleared when a new debug run starts. It tracks prompts for the current session only.
{% endhint %}
***
## Modifying steps during a debug session
You can add, edit, or delete steps while the debug session is paused. Step edit controls (the edit icon, **Add step** button, and step context menu) are visible only when execution is paused at a step. While execution is actively running, these controls are hidden to prevent conflicts.
{% hint style="info" %}
Step editing controls (add, edit, delete, and context menu options) are only available when execution is paused at a breakpoint or step. While execution is actively running, these controls are disabled to prevent conflicts with the running test.
{% endhint %}
### Adding a step
1. While paused, click the **Add step** button that appears between steps in the step list.
2. The **Add Step** dialog opens with the standard step builder.
3. Configure the step and click **Save**.
4. The new step appears in the step list at the insertion point.
### Editing a step
1. While paused, click the edit icon on the step row.
2. The **Edit Step** dialog opens with the step's current configuration.
3. Make your changes and click **Save**.
### Deleting a step
* Use the step's context menu and select **Delete step**.
* The step is removed from the current session's step list.
### Session changes banner
When you modify steps, a **Changes detected since last run** banner appears at the top of the **Steps** tab. It shows the count of added, edited, and removed steps. Click **View Details** to open the full session changes summary.
### AI agent step approval
When an AI agent step executes during a debug session, it can generate sub-steps based on its prompt. Before these steps are applied, the debugger opens an **approval dialog** so you can review them.
1. The AI agent step executes and generates a set of proposed sub-steps.
2. The approval dialog opens, showing each proposed step with its action and details.
3. Review the proposed steps. You can select or deselect individual steps.
4. Click **Create** to approve the selected steps, or **Discard** to reject them all.
The debugger inserts approved steps into the step list directly after the AI agent step and tracks them as session changes. It marks the original AI agent step as deleted in the session. You can review all changes in the **Session Changes** dialog before saving.
{% hint style="warning" %}
The approval dialog has a **5-minute timeout**. If you do not respond within 5 minutes, the proposed steps are automatically discarded. A notification confirms the discard.
{% endhint %}
***
## AI agent steps approval
When an AI agent step executes during a debug session, ContextQA generates sub-steps based on the AI agent's actions. Before these steps are added to the test case, you review and approve them.
1. The AI agent step executes and ContextQA analyzes the actions performed.
2. A **Review AI-generated steps** dialog appears with a preview of the generated steps.
3. Review the proposed steps. The dialog shows the step count, action type, and a preview of each generated step.
4. Select one of the two options:
* **Create Steps** — stages the generated steps as session changes. The original AI agent step is marked as deleted, and the new steps are inserted after it. You can review all changes in the session changes summary before saving to the test case.
* **Discard Changes** — drops the generated steps without saving. You can edit the AI agent step and re-run it, or continue past it.
{% hint style="warning" %}
The approval dialog has a 5-minute timeout. If no action is taken within that time, the generated steps are automatically discarded.
{% endhint %}
While the approval dialog is open, the **Step Over**, **Continue**, **Pause**, and **Jump to Step** controls are disabled. Review the generated steps before continuing execution.
***
## AI Prompt Archive
The **AI Prompt** tab in the left panel keeps a running history of all AI agent prompts used during the debug session. Every time you create, edit, duplicate, or delete an AI agent step, its prompt text is archived here.
Each archive entry shows:
| Field | Description |
| --------------- | ----------------------------------------------------------------------------------------------- |
| **Step number** | The hierarchical step number (for example, `3` or `6.2`). |
| **Prompt text** | The AI agent prompt as written in the step action. |
| **Timestamp** | When the prompt was archived (for example, "Today, 2:04 PM"). |
| **Operation** | What triggered the archive entry: `created`, `edited`, `duplicated`, `deleted`, or `converted`. |
| **Status** | Whether the step passed or failed during execution. |
When you edit an AI agent step, the archive records the **previous** prompt text (before the edit), so you can trace how a prompt evolved across iterations.
The archive resets when the debug session ends.
***
## On-demand video capture
During a debug session, you can capture a video clip of the current execution segment while paused at a breakpoint.
1. Pause execution at a breakpoint or step.
2. Click the **Capture Video** button in the live browser view panel header.
3. A progress dialog appears showing the capture status:
* **Starting** — the capture request is being processed.
* **Capturing** — the video segment is being recorded.
* **Ready** — the clip is available for playback.
4. When the clip is ready, click **Watch Now** to switch to the **Captured** view, or click **Close** to dismiss the dialog.
The live browser view panel header includes a **Live / Captured** toggle. Use it to switch between the live VNC stream and any video clips captured during the session.
{% hint style="info" %}
Captured video clips are stored for the duration of the debug session. When execution completes, the full session video replaces the individual clips in the execution report.
{% endhint %}
***
## Session restoration
If the browser session becomes invalid during a debug session (for example, due to a session timeout or authentication expiration), a **Session Restoration** dialog appears instead of a simple error notification.
The dialog shows the restoration state and available actions:
| State | Description | Available actions |
| ---------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------ |
| **Restoring** | ContextQA is attempting to restore the browser state. | Wait for completion. |
| **Session expired** | Session validation failed. The dialog may show specific validation failures (page URL verification, authentication token, login redirect check). | **Restart from Beginning**, **Stop Debug**, or **Override & Continue anyway**. |
| **Restoration failed** | The browser state could not be restored. | **Restart from Beginning** or **Stop Debug**. |
* **Restart from Beginning** restarts execution from the first step of the test case.
* **Stop Debug** ends the debug session.
* **Override & Continue anyway** (available only on session expiry) forces execution to continue from the target step despite the validation failure. Use this when you are confident the browser state is still usable.
When restoration succeeds, the debugger scrolls to the restored step and displays a success notification.
***
## Reviewing and saving session changes
After the debug session ends, you can review all modifications you made and optionally save them back to the original test case.
1. Click the **More** menu in the debug toolbar and select **Review session changes**.
2. The **Session Changes** dialog displays three sections: **Added**, **Edited**, and **Deleted** steps.
3. Review each change. You can remove individual changes before saving.
4. Click **Save to test case** to commit the changes to the test case, or click **Cancel** to discard them.
{% hint style="warning" %}
Saving session changes modifies the original test case. Review all changes carefully before saving.
{% endhint %}
***
## Capturing video during a debug session
You can capture video clips on demand while a debug session is paused. This is useful for recording specific interactions or reproducing a visual issue without waiting for the full post-execution recording.
### Starting a capture
1. Pause execution at the step you want to record (using a breakpoint or the **Pause** button).
2. Click the **Capture Video** button in the simulator header. The button is available only when execution is paused during a debug session.
3. A progress dialog opens, showing the capture state:
* **Starting** -- the capture is initializing.
* **Capturing** -- the video is being recorded. The dialog updates as the capture progresses.
4. When the capture completes, the dialog shows a **Ready** state with two options:
* **Watch Now** -- switches the simulator to the **Captured** view and plays the clip.
* **Close** -- dismisses the dialog without switching views.
### Viewing captured clips
During a live session, the simulator header shows a **Live / Captured** toggle:
* **Live** -- displays the real-time VNC browser stream.
* **Captured** -- displays video clips captured during the session. Clips are listed in the order they were captured.
You can switch between **Live** and **Captured** at any time during the session.
### After execution completes
When the debug execution finishes, mid-session captured clips are replaced by the canonical session recording (the full WebM video produced by the execution engine). The post-execution video is available in the video library on the right panel, the same as for standard test executions.
{% hint style="info" %}
Video capture during debug is separate from the automatic session recording. The session recording captures the entire execution, while on-demand captures record only the segment you request.
{% endhint %}
***
## Session restoration
If you resume a debug session after a period of inactivity, the debugger attempts to restore the browser state to where you left off. A **Session Restoration** dialog appears to show the progress and any issues.
### Restoration states
| State | What it means | What you can do |
| ---------------------- | ------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------- |
| **Restoring** | The debugger is re-navigating the browser to the checkpoint page and re-applying state. | Wait for restoration to complete. No action is required. |
| **Session expired** | The browser session could not be fully validated. The page URL or DOM state does not match the expected checkpoint. | Choose **Restart from Beginning**, **Stop Debug**, or **Override & Continue anyway**. |
| **Restoration failed** | The restoration attempt failed entirely (for example, the server could not reconnect to the browser). | Choose **Restart from Beginning** or **Stop Debug**. |
### Restoration actions
| Action | What it does |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Restart from Beginning** | Starts a fresh debug run from step 1, discarding the previous session state. |
| **Stop Debug** | Ends the debug session and returns to the test case details screen. |
| **Override & Continue anyway** | Dismisses the warning and resumes execution at the checkpoint step, even though validation failed. Use this when you are confident the page state is acceptable despite the mismatch. |
{% hint style="warning" %}
**Override & Continue anyway** skips session validation. If the browser state does not match expectations, subsequent steps may fail or produce unexpected results.
{% endhint %}
***
## Inactivity timeout
If the debug session remains idle for an extended period, an **inactivity warning banner** appears below the debug toolbar. The banner displays a countdown timer showing how much time remains before the session is automatically terminated.
To keep the session active, perform any action (step over, continue, add a step, or interact with the browser view).
***
## Tips and best practices
* **Set breakpoints before starting** -- if you know which steps are likely to fail, set breakpoints on them before clicking **Start Debugging** to avoid stepping through every preceding step manually.
* **Use Jump to step for fast iteration** -- when debugging a step deep in the test case, use **Jump to step** to restart execution from a point close to the problem area instead of re-running from the beginning.
* **Inspect variables at pause points** -- switch to the **Live Variables** tab each time the debugger pauses to verify that variables hold expected values before continuing.
* **Save session changes only when confident** -- make sure edits work correctly within the debug session before committing them to the test case.
* **Capture video at key moments** -- use on-demand video capture when paused at a step to record a specific interaction, rather than relying only on the full session recording.
* **Review AI agent steps before approving** -- the approval dialog lets you select individual steps. Deselect any steps that look incorrect before clicking **Create**.
***
## Troubleshooting
**The Debug option does not appear in the test case menu**
Your workspace license may not include the Debug feature. Contact your ContextQA administrator to verify your license includes Debug support. The test case must also have at least one step.
**VNC connection fails and no browser view is displayed**
An error message appears in the debug toolbar when the VNC connection fails. Verify that your network allows WebSocket connections to the ContextQA execution servers. Try stopping the session and starting a new one.
**The step reports "no screen or HTML data was provided"**
The execution did not have a usable screenshot or DOM snapshot at the moment the AI-backed step ran. This can happen before the page finishes loading, after a navigation closes the current page, or when the browser session disconnects. Confirm the live page is open, add a wait for the expected URL or element before the affected step, and start a fresh run. If the page is visible but the message repeats, preserve the run ID and contact ContextQA support; repeatedly changing the AI prompt will not restore missing capture data.
**I need a direct VNC or noVNC connection URL**
Use the embedded **Live** view in the ContextQA Debug screen. Direct connection details are not an end-user configuration and expire with the managed session. If the embedded viewer cannot connect, allow secure WebSocket traffic to the ContextQA execution service or ask your network administrator to review the blocked request—do not expose or reuse an internal session endpoint.
**The session was terminated due to inactivity**
The debugger automatically terminates idle sessions to free execution resources. Start a new debug session and interact with the controls regularly to prevent timeout.
**Step Over or Continue buttons are disabled**
These controls require an active WebSocket connection. If the connection is interrupted, the buttons become disabled. Wait a moment for the connection to reconnect, or stop and restart the debug session.
**A "Session expired" dialog appears when resuming a debug session**
The debugger detected that the browser state no longer matches the checkpoint where you left off. This can happen after a long period of inactivity or a network interruption. Choose **Restart from Beginning** to start a fresh run, or **Override & Continue anyway** if you believe the current browser state is acceptable.
**AI agent steps were discarded automatically**
The approval dialog has a 5-minute timeout. If you did not respond in time, the proposed steps were discarded. Edit the AI agent step and re-run it to generate new steps.
**The Capture Video button is not visible**
The **Capture Video** button appears only when execution is paused during a debug session. If execution is actively running or the session has not started, the button is hidden. Pause execution at a step first, then look for the button in the simulator header.
***
## Related pages
* [Running Tests](/execution/running-tests) -- standard (non-debug) test execution
* [Test Steps Editor](/web-testing/test-steps-editor) -- creating and editing test steps
* [Video & Screenshots](/execution/video-and-screenshots) -- execution evidence and artifacts
* [Environments](/execution/environments) -- configuring execution environments
***
{% hint style="info" %}
**Debug smarter, not harder.** ContextQA's interactive debugger gives you full control over test execution — set breakpoints, inspect variables, and fix tests in real time.\
[**Book a Demo ->**](https://contextqa.com/book-a-demo/) — See how the interactive debugger accelerates test development and failure diagnosis.
{% endhint %}
# Parallel Execution
Configure parallel nodes in a ContextQA test plan, compare running work with organization capacity, and monitor cases waiting in the execution queue.
## Quick answer
Set **Parallel Nodes** in a test plan to control how many of that plan's cases can run concurrently. Before starting the plan, review the execution-capacity card on **Test Plans** or **Schedules**: **Running** shows slots in use, **Capacity** shows the organization limit, and **Queued** shows work waiting for a slot. Open **Runs → Live execution** to see the active plan's running and queued cases.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA managers, and engineering managers who want to reduce test plan run time by distributing test cases across multiple concurrent browser sessions.
{% endhint %}
> **Parallel execution:** A test plan configuration mode where ContextQA distributes independent test cases across multiple concurrent execution slots, reducing total wall-clock time proportionally to the degree of parallelism.
Waiting for hundreds of sequential test cases to finish defeats the purpose of continuous testing. ContextQA solves this through parallel execution slots controlled by the **Parallel Nodes** setting on every test plan. This page explains how parallelism works, how to configure it, and how to reason about dependency chains that must stay sequential.
## What is parallel test execution?
Parallel test execution means ContextQA launches more than one test case at the same time inside a single test plan run. ContextQA orchestrates execution through its `gcpn1.contextqa.com` service, which manages a pool of Playwright-backed browser sessions. When **Parallel Nodes** is set to a value greater than one, ContextQA assigns independent test cases to separate sessions and runs them concurrently. The final plan result is computed only after every session completes, then aggregated into a single pass/fail report.
ContextQA does not share browser state between parallel slots. Each slot receives its own browser context, cookies, and local storage — isolation is total. This is intentional: a flaky session in slot 2 cannot corrupt slot 1.
## How to configure parallel nodes in a test plan
1. Open **Test Plans** in the left navigation.
2. Select the test plan you want to configure.
3. Click the **Settings** tab inside the plan detail view.
4. Locate the **Parallel Nodes** field.
5. Enter a numeric value between `1` and the maximum allowed by your subscription tier.
6. Click **Save** to apply the change.
The new parallelism value takes effect on the next execution. In-flight runs are not affected.
## Check organization capacity and queued work
Open **Plans → Test Plans** or **Plans → Schedules** and review the execution-capacity card in the page header. It shows:
* **Running** — executions currently using a slot;
* **Capacity** — the organization's parallel execution limit; and
* **Queued** — work waiting for a slot.
The ring displays running executions against capacity, and the refresh control lets you pause or resume automatic updates. Plan-level **Parallel Nodes** defines how many nodes that plan can request; the organization card shows the shared capacity currently available across plans. When demand reaches capacity, additional cases remain queued until a slot becomes available.
During an active plan, open **Runs → Live execution** to see which cases are running and which are queued. Each running item identifies its suite and target browser or device. Use **Stop Run** when the remaining work should not continue.
## Parallel nodes reference
| parallelNode value | Behavior | Recommended for |
| ------------------ | ---------------------------------------------- | -------------------------------------------------------------------------------------- |
| 1 | Fully sequential; one test case runs at a time | Smoke suites where strict ordering is required, or plans with many prerequisite chains |
| 2 | Two test cases run simultaneously | Small teams, shared staging environment with limited capacity |
| 4 | Four concurrent sessions | Standard CI pipelines with moderate test suites (50–200 cases) |
| 8 | Eight concurrent sessions | Large regression suites (200+ cases) where execution time is the primary constraint |
| 16+ | Maximum throughput | Elite tier; nightly full-regression runs; dedicated execution environments |
Higher values reduce wall-clock time but increase concurrent load on the application under test (AUT). If your AUT's staging environment has rate limits, connection pool limits, or shared database locks, aggressive parallelism can cause failures that would not appear in production. Start at 4, measure, and scale up only when the AUT can sustain the load.
## Trade-offs: speed versus resource pressure
Every parallel slot opens a full Playwright browser session with its own network connection. The practical implications are:
**Faster results.** A 200-case suite that takes 40 minutes sequentially may complete in 10 minutes at parallelNode 4 — assuming no dependency constraints. The theoretical speedup is `sequential_time / parallelNode`, though real-world gains are slightly lower due to scheduling overhead and test cases with different durations.
**Increased AUT load.** Eight parallel sessions create eight simultaneous users. If your staging environment cannot handle that concurrency, some requests will time out or return errors that are infrastructure failures, not application bugs. ContextQA's AI root cause analysis will often classify these as environment issues, but the most reliable fix is to right-size parallelism to the AUT's capacity.
**Increased execution resource consumption.** Each slot consumes CPU and memory on the ContextQA execution infrastructure. Premium and Elite tiers offer higher slot ceilings because they have proportionally more allocated execution capacity. Attempting to set parallelNode above your tier's ceiling will be capped silently at the maximum allowed value — ContextQA will not error, it will run at the cap.
**Network artifact volume.** Every parallel session produces its own screenshot set, WebM video, HAR file, and console log. At high parallelism, storage and download times for evidence packages grow linearly. Plan accordingly if you are programmatically downloading artifacts after every run.
## Dependency chains and sequential execution within a parallel plan
ContextQA respects prerequisite relationships between test cases. When test case B declares test case A as a prerequisite, ContextQA will not start B until A has completed and passed — regardless of the parallelNode setting.
This means: in a plan with parallelNode 8 and a chain A → B → C → D, those four cases always run sequentially in that order. The eight slots are used for other independent test cases concurrently. Dependency chains are the exception, not the rule; most test cases in a well-designed suite are independent.
**Designing for maximum parallelism:**
* Keep test cases self-contained. Each case should set up its own preconditions (log in, navigate to the start URL) rather than relying on state left by a previous case.
* Use prerequisite chains only when the dependency is semantically required (for example, a test that verifies an edit can only run after a test that verifies creation).
* Group cases with many prerequisites into dedicated sequential suites, and run independent cases in a high-parallelism plan.
## How results are aggregated
After all parallel slots complete, ContextQA computes the test plan result as follows:
* **PASSED:** Every test case in the plan passed.
* **FAILED:** One or more test cases failed (regardless of pass count).
* **PARTIAL:** Execution was interrupted before all cases completed.
The aggregate result is what ContextQA sends to CI/CD integrations (GitHub Actions, Jenkins, GitLab CI) and to Slack or Jira notifications. The individual case results are always visible in the **Execution Report** regardless of the aggregate.
The **Execution Dashboard** in the Analytics section shows per-case results, timing, and failure classification for every case in the run. Parallel cases appear with overlapping timestamps in the timeline view, making it straightforward to verify that parallelism is actually occurring.
## Frequently Asked Questions
### Does parallelNode affect mobile test execution?
Yes, the same **Parallel Nodes** setting controls both web and mobile slots within a mixed plan. Mobile slots consume real or simulated device capacity. Check your mobile concurrency limit using the `get_mobile_concurrency` MCP tool before setting high parallelNode values on plans that include mobile test cases.
### Can I set different parallelism for different suites within one plan?
No. The **Parallel Nodes** setting applies to the entire test plan. If you need different parallelism for different groups of test cases, place them in separate test plans and trigger both from your CI pipeline.
### What happens if a test case in a parallel slot crashes the browser session?
ContextQA marks that test case as failed and releases the slot for the next queued case. The session crash does not block other parallel slots. The crashed session's HAR, console log, and partial video are still captured and available in the execution report.
### Why are some test cases still running sequentially even though parallelNode is set to 8?
The most common cause is prerequisite chains. Check whether the cases running sequentially have **Prerequisite** relationships configured. Removing unnecessary prerequisites, or restructuring tests to be self-contained, will allow ContextQA to dispatch them to parallel slots.
## Related
* [Running tests and test plans](/execution/running-tests)
* [Test plans](/web-testing/test-plans)
* [Execution environments](/execution/environments)
* [Video recording and screenshots](/execution/video-and-screenshots)
* [Failure analysis and root cause](/reporting/failure-analysis)
* [Analytics dashboard](/reporting/analytics-dashboard)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full test suite in parallel CI/CD execution.
{% endhint %}
# Running Tests Across Multiple Browsers
Run the same ContextQA test suite on Chrome, Firefox, and Safari in a single cross-browser test plan, then compare per-browser results to catch browser-specific failures before release.
## Quick answer
Run the same ContextQA test suite on Chrome, Firefox, and Safari in a single cross-browser test plan, then compare per-browser results to catch browser-specific failures before release. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA managers, and developers who need to confirm that a web application behaves the same way on Chrome, Firefox, and Safari — without maintaining a separate test plan for each browser.
{% endhint %}
A feature that works in Chrome can still break in Safari or Firefox. Layout shifts, unsupported APIs, and rendering differences only surface when you run the same flow on each browser engine. ContextQA runs your tests on real browsers — Chromium (Chrome), Firefox, and WebKit (Safari) — so you can verify cross-browser compatibility from one place.
This guide shows you how to build a single **Cross Browser Testing** plan that runs the same test suite on multiple browsers, run it, and read the per-browser results.
## Goal
Run one test suite on Chrome, Firefox, and Safari from a single test plan, and confirm each browser passed.
## Prerequisites
* A ContextQA account with at least one workspace ([sign up](https://accounts.contextqa.com/onboard)).
* A test suite that contains one or more passing web test cases. If you don't have one, see [Managing Test Suites](/web-testing/managing-test-suites).
* An environment configured with the base URL of the application you want to test. See [Configuring Environments](/execution/environments).
* Familiarity with [test plans](/web-testing/test-plans) — the configuration that defines what runs, where, and how.
***
## Step 1: Create a cross-browser test plan
A test plan defines which suites run, which browsers they target, and how the run behaves on failure. ContextQA creates a test plan through a three-step wizard.
1. Open the **Test Plans** tab in Test Development.
2. Click **Create Test Plan**.
3. Configure the plan basics:
* **Test Plan Name** — name it for its purpose, such as `Cross-Browser — Checkout — Staging`.
* **Environment** — select the environment whose base URL the tests run against.
* **Test plan type** — select **Cross Browser Testing**. This is the plan type that runs tests on multiple browsers. (Choose **Cross Device Testing** only for mobile suites.)
4. Click **Next**.
**Verify it worked:** The wizard advances to the **Test Machines & Suites Selection** step.
***
## Step 2: Add the first browser
Each browser you target is configured as a **test machine** — a combination of platform, browser, and resolution. Start by adding Chrome.
1. On the **Test Machines & Suites Selection** step, under **Select Platform**, choose the operating system to run on.
2. Under **Browser**, select **Chrome**.
3. Set the **Resolution** for the run.
4. Under **Selected Test Suites**, add the suite you want to run across browsers.
**Verify it worked:** The suite appears under **Selected Test Suites**, assigned to a Chrome machine.
***
## Step 3: Add Firefox and Safari
To test the same suite on additional browsers, add a machine for each one.
1. Click **Add Machine/Device**, then choose **Create new Machine**.
2. In the machine form, select the **Platform**, set **Browser** to **Firefox**, and choose a **Resolution**.
3. Add the same test suite to the new Firefox machine.
4. Repeat for Safari: click **Add Machine/Device**, choose **Create new Machine**, set **Browser** to **Safari**, and add the same suite.
You now have one plan with three machines — Chrome, Firefox, and Safari — each running the same suite.
{% hint style="info" %}
To reuse a browser machine you already configured for a different suite, choose **Add to existing Machine** instead of **Create new Machine**.
{% endhint %}
5. Set the suite execution behavior:
* **Run Test Suites in Parallel** — enable this to run the browsers at the same time for faster feedback. See [Parallel Execution](/execution/parallel-execution) for how concurrency is allocated.
* **Reset Session for Every Test Case** — enable this so each test case starts from a clean browser session.
6. Click **Next**.
**Verify it worked:** All three machines (Chrome, Firefox, Safari) are listed, each with the suite assigned.
***
## Step 4: Configure failure handling and save
On the final **Test Plan Settings** step, decide how the run handles failures.
1. Under **Recovery Actions**, enable **Rerun on failure** if you want ContextQA to retry a failed test case once before reporting it as failed. This filters out transient flakiness so a one-off network blip doesn't read as a real browser incompatibility.
2. Review the remaining recovery options, then adjust them to match your team's tolerance for partial runs.
3. Click **Save** (or **Create Test Plan**) to finish.
**Verify it worked:** The new plan appears in the **Test Plans** list with the name you gave it.
***
## Step 5: Run the plan
1. Open the plan from the **Test Plans** list.
2. Click **Run Now** in the plan header.
ContextQA runs the suite on all three browsers. With **Run Test Suites in Parallel** enabled, the browser runs execute concurrently.
***
## Verification
Confirm every browser ran and passed.
1. Open the run from the test plan execution results. The plan dashboard shows the overall pass/fail status for the run.
2. Expand the suite detail. Each test case row lists the **browser/device used**, so you can see the same case reported once per browser.
3. Confirm each browser shows a **PASSED** status.
If one browser fails while the others pass, you have found a browser-specific defect. Open that execution's [test results](/reporting/test-results) — the per-step screenshots, session video, and console log show exactly where the behavior diverged on that browser.
***
## Troubleshooting
**A browser I want isn't listed in the Browser dropdown** The available browsers depend on your workspace configuration and subscription tier. ContextQA supports Chromium (Chrome), Firefox, and WebKit (Safari). If a browser is missing, confirm your plan includes it or contact your workspace administrator.
**A suite ran on one browser but not the others** Open the plan's **Test Machines & Suites Selection** step and confirm the suite is listed under **Selected Test Suites** for every machine. A suite added to the Chrome machine only runs on Chrome unless you also add it to the Firefox and Safari machines.
**All browsers fail at the same step** A failure that reproduces on every browser is usually a genuine application issue or a test problem, not a compatibility defect. Review the failing step in the [test results](/reporting/test-results), and check [Failure Analysis](/reporting/failure-analysis) for AI root cause analysis.
**One browser is consistently slower or times out** Different browser engines render at different speeds. If a single browser intermittently fails on timing, enable **Rerun on failure** in the plan settings, and review [Flaky Test Detection](/reporting/flaky-test-detection) to confirm the failures are transient rather than a real defect.
***
## Related pages
* [Test Plans](/web-testing/test-plans) — the full test plan configuration reference
* [Parallel Execution](/execution/parallel-execution) — run browsers concurrently to cut total run time
* [Configuring Environments](/execution/environments) — point one plan at staging, QA, or production
* [Test Results](/reporting/test-results) — read per-browser execution reports
* [Tutorial: Build and Schedule a Regression Suite](/execution/regression-suite-tutorial) — schedule a cross-browser plan to run automatically
{% hint style="info" %}
**Run one test suite across every browser, in parallel.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your tests on Chrome, Firefox, and Safari at once.
{% endhint %}
# Environments
How to create and manage environment configurations in ContextQA, including base URLs, encrypted parameters, variable usage in test steps, and environment selection at execution time.
## Quick answer
How to create and manage environment configurations in ContextQA, including base URLs, encrypted parameters, variable usage in test steps, and environment selection at execution time. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs and QA managers who need to run the same test suite against multiple deployment targets — staging, QA, and production — without modifying any test steps.
{% endhint %}
An environment is a named configuration that stores a base URL and a set of key-value parameters for one deployment target of your application. Environments let you run the same test suite against staging, QA, and production without modifying a single test step — select a different environment at execution time and every `${ENV.KEY}` reference in your steps resolves to the appropriate value for that target.
{% hint style="info" %}
You create and edit environments, their variables, and their database connections in the [Environment Data Management](/web-testing/environment-data-management) workspace. This page focuses on how environments are used at execution time.
{% endhint %}
## Prerequisites
* You have a workspace created.
* You have the base URL for at least one of your application's deployment environments (e.g., `https://staging.myapp.com`).
* For encrypted parameters: you have the credentials, API keys, or other secrets to store.
***
## What is an Environment?
Every application you test exists in multiple deployment states simultaneously: developers work against local instances, QA teams test on staging, and end users interact with production. Each of these deployments has a different URL and typically uses different credentials, API endpoints, feature flags, and third-party service configurations.
Without environment management, teams hard-code URLs and credentials in test steps or maintain separate copies of test cases per environment — both approaches are error-prone and expensive to maintain.
ContextQA environments solve this by centralizing deployment-specific values. A test step like:
```
Navigate to ${ENV.BASE_URL}/login
Type ${ENV.TEST_USERNAME} in the Email field
```
...runs correctly against any environment — staging, QA, or production — as long as the selected environment has `BASE_URL` and `TEST_USERNAME` defined with the appropriate values.
***
## Creating an Environment
1. Navigate to **Test Development → Environments**.
2. Click **Create**.
3. Fill in the environment creation form:
**Name** A short, descriptive name. Convention: use the deployment tier name, optionally qualified by region or purpose. Examples: `Staging`, `Production`, `QA-US`, `Production-EU`, `Sandbox-Payments`.
**Description** Optional free-text notes. Document the purpose of this environment, who owns it, any known limitations, and the maintenance contact.
**Base URL** The root URL of the application in this environment. Include the protocol and domain, without a trailing slash:
```
https://staging.myapp.com
```
The base URL serves as the starting navigation point for test cases that use `${ENV.BASE_URL}` and appears prominently in execution reports for quick identification.
4. Click **Create**. The environment is created and the parameter configuration panel opens.
***
## Adding Parameters
Parameters are the key-value pairs that test steps reference using the `${ENV.KEY}` syntax. After creating the environment, add all the values your test cases need.
### Adding a Parameter
1. In the environment editor, under **Parameters**, click **Add Next Row**.
2. Enter the **Key** — the variable name exactly as it will be referenced in test steps. Keys are case-sensitive: `BASE_URL` and `base_url` are different keys.
3. Enter the **Value** — the value for this environment.
4. Select the **Type**:
* **Text** — plain string. The value is displayed in the UI and included in execution logs.
* **Password** — the value is encrypted at rest (AES-256) and masked in the UI with asterisks. It is redacted from execution logs, screenshots, and exported reports.
5. Click **Save**.
Repeat for each parameter your test cases need.
### Recommended Parameter Set
While every application differs, the following parameter set covers most test scenarios:
| Key | Type | Example Value | Purpose |
| -------------------- | -------- | ------------------------------- | -------------------------------- |
| `BASE_URL` | text | `https://staging.myapp.com` | Root URL for navigation steps |
| `API_BASE_URL` | text | `https://api-staging.myapp.com` | Base URL for REST API call steps |
| `ADMIN_EMAIL` | text | `admin@staging-test.com` | Admin user login |
| `ADMIN_PASSWORD` | password | `Admin-Staging-123!` | Admin user password |
| `TEST_USER_EMAIL` | text | `user@staging-test.com` | Standard user login |
| `TEST_USER_PASSWORD` | password | `User-Staging-456!` | Standard user password |
| `API_TOKEN` | password | `sk-staging-abc123` | API authentication token |
| `STRIPE_TEST_KEY` | password | `pk_test_abc...` | Payment provider test key |
***
## Parameter Types in Detail
### Text Parameters
Text parameters store values as plain strings. They appear in their original form everywhere: in the UI, in execution logs, and in step descriptions that reference them.
Use text parameters for:
* URLs and hostnames
* Non-sensitive configuration values (feature flag names, locale codes, timeout values)
* Email addresses used for testing
* Any value you might want to see in test logs for debugging
### Password Parameters
Password parameters are encrypted at rest using AES-256. They are masked in all UI views with asterisks and are never returned by the API in plain text. In execution logs, the variable reference (e.g., `${ENV.ADMIN_PASSWORD}`) is visible, but the resolved value is replaced with `[REDACTED]`.
Use password parameters for:
* User passwords
* API keys, bearer tokens, OAuth secrets
* Database connection strings
* Third-party service credentials
* Any value that presents a security risk if exposed in a log or screenshot
**Important:** Storing a value as a password parameter does not prevent it from appearing in screenshots if the application renders it on screen. If a page displays an API key in cleartext (e.g., a developer settings page), the screenshot will capture it. Structure your tests to avoid taking screenshots on pages that display sensitive values, or use the "Never" screenshot capture setting on such steps.
***
## Using Environment Variables in Tests
Once parameters are defined in an environment, reference them in test steps with the `${ENV.KEY}` syntax.
### In AI Agent Step Descriptions
```
Type ${ENV.TEST_USER_EMAIL} in the Email Address field
Type ${ENV.TEST_USER_PASSWORD} in the Password field
Click the Sign In button
Verify the heading reads "Welcome back, ${ENV.ADMIN_EMAIL}"
```
### In Navigate Steps
```
${ENV.BASE_URL}/admin/users
${ENV.BASE_URL}/reports?date=2026-01-01&format=pdf
```
### In REST API Call Steps
**URL field:**
```
${ENV.API_BASE_URL}/api/v2/users
```
**Headers:**
```
Authorization: Bearer ${ENV.API_TOKEN}
X-Tenant-ID: ${ENV.TENANT_ID}
```
**Request body:**
```json
{
"email": "${ENV.TEST_USER_EMAIL}",
"role": "viewer"
}
```
### Combining ENV Variables with Other Variable Types
Environment variables can be combined with local variables, global variables, and data profile variables in the same step:
```
Navigate to ${ENV.BASE_URL}/users/${userId}/edit
```
Here `${ENV.BASE_URL}` comes from the environment and `${userId}` is a local variable set by a previous API call step. Both are resolved at execution time.
***
## Selecting an Environment at Execution
You select the environment each time you trigger an execution. The same test plan can run against different environments by selecting a different environment at execution time.
### Manual Execution
1. Open the test plan.
2. Click **Run Now** in the plan header. The execution starts immediately using the environment configured in the plan settings.
The selected environment name appears in all execution records and reports produced by this run.
### In Scheduled Runs
Each schedule within a test plan specifies a default environment:
1. Navigate to **Test Plans → your plan → Schedules tab**.
2. Open a schedule.
3. In the **Environment** field, select the environment this schedule should use.
A test plan can have multiple schedules targeting different environments — for example, a nightly schedule running against `Staging` and a weekly schedule running against `Production`.
### Via MCP
```python
# Execute a test plan. The run uses the environment
# configured in the plan's settings.
execute_test_plan(
test_plan_id=789
)
```
List environments and their IDs — useful when configuring a plan or creating and updating environments programmatically:
```python
environments = get_environments()
# Returns a paginated list of environments, each with an "id", "name", and parameters
```
***
## Creating Environments via MCP
For teams that manage infrastructure as code or provision environments dynamically (e.g., ephemeral preview environments per pull request), the MCP server provides a tool to create environments programmatically:
```python
create_environment(
name="PR-1234-Preview",
description="Ephemeral preview environment for PR #1234",
parameters={
"BASE_URL": {
"type": "text",
"value": "https://pr-1234.preview.myapp.com"
},
"API_BASE_URL": {
"type": "text",
"value": "https://api-pr-1234.preview.myapp.com"
},
"ADMIN_EMAIL": {
"type": "text",
"value": "admin@preview-test.com"
},
"ADMIN_PASSWORD": {
"type": "password",
"value": "PreviewAdmin123!"
}
}
)
```
In a CI/CD pipeline, this pattern allows you to create a new environment record for each pull request, point your test plan at that environment and run it with `execute_test_plan(test_plan_id=...)`, and delete the environment record when the PR is merged.
***
## Viewing the Environments Page

The Environments page lists all environments in the workspace. Each row shows the environment name, base URL, and the number of parameters defined. Click on an environment name to open the parameter editor.
***
## Tips & Best Practices
* **Create at least two environments from the start: Staging and Production.** Even if you only run tests against Staging initially, having the Production environment configured makes it trivial to run a quick verification against production after a deployment.
* **Never store production credentials in a Staging environment.** Keep environment parameter sets fully separate. Staging environments should use dedicated test accounts, not production user credentials.
* **Use descriptive parameter keys.** `BASE_URL` is clearer than `URL`. `ADMIN_PASSWORD` is clearer than `PWD`. Future team members reading test steps should be able to understand what each `${ENV.KEY}` reference is without consulting the environment configuration.
* **Document unstable or environment-specific behaviors in the description.** If the staging environment is often slow, has a different authentication flow, or shows a maintenance page on weekends, note this in the environment description. This helps diagnose false failures quickly.
* **Rotate password parameters when credentials change.** When test accounts are rotated or API keys are regenerated, update the corresponding password parameters in the environment configuration. Tests will immediately use the new credentials without any test case changes.
## Troubleshooting
**Steps are failing with "variable not found" for an ENV parameter** Check that:
1. The parameter key in the environment exactly matches the `${ENV.KEY}` reference in the step, including case.
2. The correct environment is selected in the test plan or execution dialog.
3. The environment has been saved after the parameter was added.
**Password parameter values are appearing in execution logs** Password parameters are only redacted in ContextQA's own log outputs. If your application echoes back the value (for example, a REST API that returns the submitted password in an error response), it will appear in the network log body. This is an application security concern, not a ContextQA configuration issue.
**Switching environments caused a test to fail that previously passed** The most common cause is a missing parameter in the new environment. Compare the parameters defined in both environments — the failing environment may be missing a key that the working environment has. Open the failing execution's network log or console log for a "variable not resolved" error that identifies the missing key.
**I created a new environment but it does not appear in the execution environment dropdown** Refresh the browser. Environment lists in dropdowns are loaded from the API and may be cached for a few seconds after creation.
## Related Pages
* [Test Data Management](/web-testing/test-data-management)
* [Running Tests](/execution/running-tests)
* [Scheduling Tests](/execution/scheduling)
* [Core Concepts](/getting-started/core-concepts)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full test suite in parallel CI/CD execution.
{% endhint %}
# Scheduling
How to create, configure, and manage recurring test schedules in ContextQA using frequency options, and how scheduled results surface through email and Slack notifications.
## Quick answer
How to create, configure, and manage recurring test schedules in ContextQA using frequency options, and how scheduled results surface through email and Slack notifications. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA managers, and engineering managers who want to run test plans automatically on a recurring schedule — nightly regression, hourly smoke tests, or pre-release verification.
{% endhint %}
ContextQA runs test plans automatically on a recurring schedule without manual intervention. You configure scheduled runs at the test plan level by choosing a start date and time and a repeat frequency. Scheduled results surface through email and Slack notifications so failures reach the right people immediately.
## Prerequisites
* You have a test plan created and configured with at least one test suite and an environment.
* You have confirmed the test plan executes successfully when run manually at least once.
* For notification setup: you have connected a Slack workspace or have recipient email addresses ready.
***
## Creating a schedule
1. Navigate to **Test Development → Test Plans**.
2. Click the test plan you want to schedule.
3. Inside the test plan, click the **Schedules** tab.
4. Click **New Schedule** (or the **Add Schedule** button below the schedule list).
5. The schedule dialog opens. Fill in the following fields:
### Schedule fields
**Name** (required) A descriptive label for this schedule. Use names that describe the timing and purpose, for example "Nightly Regression — Staging", "Hourly Smoke — Production", or "Pre-Release Full Suite".
**Date** The start date for the schedule.
**Time** The start time for the schedule.
**Repeat** Select how often the schedule runs:
| Repeat | Behavior |
| ------------ | --------------------------------------------------------------------------------------------------- |
| Don't Repeat | Runs once at the specified date and time |
| Hourly | Repeats every hour |
| Daily | Repeats every day at the specified time |
| Weekly | Repeats every week on the same day (the chip shows the day, for example "Weekly on Friday") |
| Monthly | Repeats every month on the same date (the chip shows the day, for example "Monthly on the 8th day") |
6. Click **Save**.
The schedule appears in the Schedules tab with its next scheduled run time displayed.
{% hint style="info" %}
Schedules run in your browser's local timezone, derived from your system settings. There is no separate timezone field to set.
{% endhint %}
***
## Viewing scheduled runs
**Schedule list:** Navigate to **Test Plans → your plan → Schedules tab**. The Schedules tab uses a split view: the schedule list on the left and a calendar on the right.
Each schedule card shows:
* An active/paused toggle
* Schedule name
* Recurrence label (Once / Hourly / Daily / Weekly / Monthly)
* Next run time
* **Run now**, **Edit**, and **Delete** actions
**Calendar:** The calendar plots scheduled events on their target dates. Use the previous and next arrows to change months, or click **Today** to return to the current date. You can collapse or expand the schedule list to give the calendar more room.
**Across all plans:** Navigate to **Test Plans → Schedules** (the workspace-level Schedules tab) to see schedules across all test plans. This provides a consolidated view for scheduling hygiene — identifying overlapping schedules, dormant schedules that should be deactivated, or gaps in coverage.
***
## Pausing, resuming, and deleting schedules
**To pause a schedule:**
1. Navigate to the plan's Schedules tab.
2. Toggle the schedule **off** using the switch on its card.
The schedule keeps all its settings. It doesn't run while paused.
**To resume a schedule:** Toggle the switch back **on**. The next run time is recalculated from the current time.
**To run a schedule immediately:** Click **Run now** on the schedule card to trigger an execution outside the normal cadence.
**To edit a schedule:** Click the **Edit** icon on the schedule card to change its name, date, time, or repeat frequency.
**To delete a schedule:** Click the **Delete** icon on the schedule card. Deleting a schedule removes it permanently. The execution history from past scheduled runs is not affected.
***
## Notifications for scheduled runs
Scheduled runs that execute overnight or on weekends must surface failures without anyone manually checking the portal. ContextQA delivers scheduled-run results through email and Slack.
### Email
On the plan's **Settings** tab, enable **Send Notification** and add recipient email addresses. Each run then sends an email with the result.
### Slack
When you connect a Slack workspace for your workspace and enable **Send Notification** on the plan, each run also posts its result to your connected Slack channel. To connect Slack, see the [Slack integration](/integrations/integrations) guide.
The notification includes the test plan name, the run ID, the overall pass/fail status, pass/fail counts, and a link to the run report in the portal.
***
## Scheduled run best practices
### Smoke tests — run frequently
Schedule a lightweight smoke test plan to run **Hourly** against your staging environment. Smoke tests should cover the 5–10 most critical user flows and complete in under 5 minutes. Hourly smoke tests catch deployment issues or environment outages within 60 minutes.
```
Smoke Plan — Staging
Repeat: Hourly
```
### Full regression — run nightly
Schedule the full regression test plan to run overnight before your team starts work. Set the **Time** to an off-hours slot (for example, 1:00 AM) and **Repeat** to **Daily**. Every morning then begins with a clear picture of the application's health.
```
Regression Plan — Staging
Time: 01:00
Repeat: Daily
```
### Pre-release verification — run against production
Schedule a production verification run to execute after each deployment window. Set **Repeat** to **Daily** at a time shortly after your deployment slot, and pause it during freeze periods. This confirms the deployment did not break critical paths in the live environment.
### Freeze periods
Before a planned maintenance window or during a code freeze:
1. Navigate to each active schedule.
2. Toggle the schedule **off**.
3. Document the pause in your team's change log.
4. Toggle schedules back **on** after the maintenance window closes.
***
## Tips & best practices
* **Schedule against stable environments.** Avoid scheduling test plans against environments that have deployments running at the same time the tests execute. A test failure caused by a mid-deployment restart is a false negative that erodes confidence in the test suite.
* **Use different schedules for different environments.** Run smoke tests hourly on staging and a full regression daily on staging; reserve production runs for pre-release verification.
* **Stagger schedules to avoid concurrency conflicts.** If several plans run at the same time, offset their start times so they execute sequentially instead of competing for the same execution slots.
* **Review the workspace Schedules tab every sprint.** Schedules accumulate over time. Regularly review the workspace-level Schedules view to deactivate schedules for deprecated features, superseded test plans, or environments that no longer exist.
* **Test your notification setup before relying on it.** Trigger a deliberate failure (temporarily modify a test case to assert something false) on a scheduled run to confirm that email and Slack notifications work as expected.
## Troubleshooting
**A scheduled run did not execute at its configured time** Confirm the schedule is active — the toggle on the schedule card must be on. Paused schedules stay saved but don't run. Also confirm the date and time are correct; schedules run in your browser's local timezone.
**Scheduled runs are queuing instead of executing** Your workspace's concurrent execution limit was reached at the scheduled time. This happens when multiple schedules fire simultaneously or when a previous scheduled run is still in progress when the next one triggers. Stagger your schedules and review whether any executions are taking unusually long to complete.
**Slack notifications are not being received** Verify that the Slack integration is connected for your workspace and that **Send Notification** is enabled on the plan. If the connection was recently revoked (for example, a Slack workspace admin removed the ContextQA app), re-authorize the integration. Confirm the configured Slack channel still exists and that the ContextQA Slack app can post to it.
**I need a schedule that runs at different times on different days** Add multiple schedules to the same test plan. You can create any number of schedules on a plan — for example, one for weekday timing and a separate one for weekend timing. Both appear in the Schedules tab and can be managed independently.
## Related Pages
* [Test Plans](/web-testing/test-plans)
* [Running Tests](/execution/running-tests)
* [Configuring Environments](/execution/environments)
* [Managing Test Suites](/web-testing/managing-test-suites)
* [Integrations](/integrations/integrations)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full test suite in parallel CI/CD execution.
{% endhint %}
# Tutorial: Build and Schedule a Regression Suite
Group ContextQA tests into a regression suite, build and validate a test plan, then configure repeatable execution and failure notifications.
## Quick answer
Group ContextQA tests into a regression suite, build and validate a test plan, then configure repeatable execution and failure notifications. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who have created a few test cases and want to run them together, on a schedule, as a continuous regression check. You connect the building blocks — test cases, a suite, a test plan, and a schedule — into one automated workflow.
{% endhint %}
Individual test cases tell you whether one flow works right now. A regression suite tells you whether your whole application still works after every change — automatically, overnight, without anyone clicking **Run**. This tutorial takes you from a set of existing test cases to a nightly regression run that posts results to Slack.
In this tutorial you will:
1. Group related test cases into a test suite
2. Build a test plan that targets a browser and an environment
3. Run the plan manually to confirm it works
4. Schedule the plan to run automatically every night
5. Review continuous results and route failures to Slack
**End result:** A regression test plan that runs your suite every night against your staging environment and alerts your team in Slack when something breaks.
## Prerequisites
* A ContextQA account with a workspace ([sign up](https://accounts.contextqa.com/onboard))
* At least three test cases that pass when run individually (see the [Quick Start guide](/getting-started/quickstart) to create them)
* An [environment](/execution/environments) configured with the base URL of the application you want to test
* Optional: a connected Slack workspace for failure notifications (see the [Slack integration](/integrations/slack))
{% hint style="info" %}
Run each test case once on its own before adding it to a regression suite. A suite built from already-passing tests gives you a clean baseline, so the first failure you see is a real regression rather than a setup problem.
{% endhint %}
***
## Step 1: Group your test cases into a suite
A test suite is a named group of test cases that run together as a unit. It's the layer between individual test cases and the test plan that executes them.
1. In the left sidebar, click the **Test Development** icon.
2. Open the **Test Suites** tab.
3. Click **+ Create Test Suite**.
4. Fill in the suite form:
* **Suite Name** — use a pattern that signals scope and type, such as `Regression_Checkout`. A consistent name keeps the suite readable in test plan dropdowns and report headers.
* **Description** — note the feature area covered and the environment this suite targets.
* **Parent Suite** — leave empty for your first suite.
5. Click **Create Suite**.
Now add your test cases:
1. Open the new suite by clicking its name.
2. Click **Add Test Cases**.
3. Search for each test case by name, or filter by tag. Select the test cases you want to include.
4. Click **Add Selected**.
**Verify:** The suite now lists every test case you added. The order shown is the order in which the tests run when the suite executes sequentially — drag the handle (⋮⋮) on any row to reorder.
{% hint style="info" %}
Keep a regression suite focused on one feature area and under 50 test cases for fast, debuggable runs. For larger libraries, nest sub-suites under a parent suite. See [Managing Test Suites](/web-testing/managing-test-suites) for nesting and naming conventions.
{% endhint %}
***
## Step 2: Build a test plan
A test plan is the execution configuration: it specifies which suites to run, which browser or device to target, which environment to use, and how the run behaves on failure. ContextQA creates a test plan through a three-step wizard.
1. Open the **Test Plans** tab in Test Development.
2. Click **Create Test Plan**.
The wizard opens on the first step.
### Create Test Plan
Configure the plan basics:
* **Test Plan Name** — name it for its purpose and target, such as `Regression — Checkout — Staging`.
* **Environment** — select the environment whose base URL the tests run against. Choose your staging environment.
* **Test plan type** — select **Cross Browser Testing** for a web suite. (Choose **Cross Device Testing** only for mobile suites.)
Click **Next**.
### Test Machines & Suites Selection
On the second step, choose what runs and where:
1. Under **Select Browser**, pick a browser (for example, Chrome), then set the **Browser Version** and **Resolution**.
2. Under **Selected Test Suites**, add the regression suite you created in Step 1.
3. Set the suite execution behavior:
* **Run Test Suites in Parallel** — enable this to run independent suites at the same time for speed. Leave it off if suites must run in order.
* **Reset Session for Every Test Case** — enable this so each test case starts from a clean browser session, which prevents one test's state from leaking into the next.
Click **Next**.
### Test Plan Settings
On the final step, configure how the run handles failures:
* Under **Recovery Actions**, set **Rerun on failure** if you want ContextQA to automatically retry a failed test case once before reporting it as failed. This filters out transient flakiness in scheduled runs.
* Review the remaining recovery options for prerequisite and aborted-test handling, then adjust them to match your team's tolerance for partial runs.
Click **Save** (or **Create Test Plan**) to finish.
**Verify:** The new plan appears in the **Test Plans** list with the name you gave it.
***
## Step 3: Run the plan manually
Always confirm a plan runs cleanly by hand before you schedule it. A scheduled plan that has never passed only automates uncertainty.
1. In the **Test Plans** list, open your regression plan.
2. Click **Run** to trigger the execution.
ContextQA queues the run and executes each test case in the suite on the browser and environment you configured. As the run progresses, you see per-test pass/fail status in real time.
**Verify:** When the run completes, every test case shows a green pass indicator. Open the execution report to confirm the screenshots, video, and per-step results match your expectations.
{% hint style="warning" %}
If a test fails here, fix it before scheduling. A failing test in a manual run fails on every scheduled run too, producing alert noise that trains your team to ignore notifications. See [How to Debug a Failing Test](/reporting/debugging-failing-tests).
{% endhint %}
***
## Step 4: Schedule the plan
With a passing manual run as your baseline, set the plan to run automatically.
1. Open your regression plan and click the **Schedules** tab.
2. Click **+ Add Schedule**.
3. Configure the schedule:
* **Schedule Name** — describe the timing and purpose, such as `Nightly Regression — Staging`.
* **Frequency Type** — select **Preset** and choose **Daily**, or select **Cron Expression** for precise control.
* **Cron Expression** (if selected) — enter `0 1 * * *` to run at 1:00 AM every night.
* **Timezone** — set this to your team's local timezone so the run lands when you expect it. A cron of `0 1 * * *` in UTC isn't 1:00 AM where your team works.
* **Active** — leave this toggled on.
4. Click **Save Schedule**.
**Verify:** The schedule appears in the **Schedules** tab with its next scheduled run time displayed.
{% hint style="info" %}
Run a full regression suite nightly so every morning starts with a clear picture of application health. Pair it with a lighter smoke suite scheduled hourly (`0 * * * *`) to catch deployment breakages within the hour. See [Scheduling Tests](/execution/scheduling) for cron examples and scheduling hygiene.
{% endhint %}
***
## Step 5: Route failures to Slack
Overnight runs only help if a failure reaches the right people before work starts.
1. Open your regression plan and click the **Settings** tab.
2. Under **Notifications**, enable **Slack**.
3. Select the Slack channel to notify, such as `#qa-daily-report`.
4. Set the notification trigger:
* **On failure only** — recommended for most teams. ContextQA sends a Slack message only when a scheduled run has at least one failed test case.
* **Always** — sends a message for every run, pass or fail.
5. Save the plan settings.
**Verify your notification setup:** Temporarily edit one test case to assert something false, let the next scheduled run execute (or trigger a manual run), and confirm the Slack message arrives with the plan name, pass/fail counts, and a link to the report. Revert the test case afterward.
***
## Summary
You have turned a set of standalone test cases into a continuous regression check. You:
* Grouped related test cases into a named test suite
* Built a test plan targeting a browser and a staging environment
* Confirmed the plan passes with a manual run
* Scheduled the plan to run automatically every night
* Routed failures to Slack so your team learns about regressions immediately
Your application is now monitored on a recurring schedule, and the self-healing AI handles most minor UI changes automatically — so the failures that reach Slack are the ones worth investigating.
## Next steps
* [Parallel Execution](/execution/parallel-execution) — run large suites faster by executing test cases simultaneously
* [Configuring Environments](/execution/environments) — add staging and production environments so one plan can target each
* [Flaky Test Detection](/reporting/flaky-test-detection) — identify tests that fail intermittently and erode trust in your suite
* [Analytics Dashboard](/reporting/analytics-dashboard) — track pass rates and trends across scheduled runs
* [GitHub Actions Integration](/integrations/github-actions) — trigger the same plan from your CI/CD pipeline on every pull request
## Troubleshooting
**A test case I added to the suite isn't appearing** Refresh the page — the suite test case list updates asynchronously. Confirm no active filter in the test case picker excluded it.
**The plan ran but skipped a suite** Open the plan's **Test Machines & Suites Selection** step and confirm the suite is listed under **Selected Test Suites** and assigned to a browser.
**The scheduled run didn't execute at the configured time** Check the schedule's **Timezone**. A cron of `0 1 * * *` set to UTC runs at 1:00 AM UTC, not 1:00 AM local. Also confirm the schedule's **Active** toggle is on.
**Slack notifications aren't arriving** Confirm the Slack integration is connected from **Integrations & Plugins → Slack → View Details → Config** and that the ContextQA app still has permission to post to the selected channel.
## Related pages
* [Managing Test Suites](/web-testing/managing-test-suites)
* [Scheduling Tests](/execution/scheduling)
* [Running Tests](/execution/running-tests)
* [Configuring Environments](/execution/environments)
* [Quick Start guide](/getting-started/quickstart)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full regression suite on a schedule.
{% endhint %}
# Video & Screenshots
Test execution video recording and screenshots in ContextQA — every run produces a complete evidence package including WebM video, HAR, and Playwright trace.
## Quick answer
Test execution video recording and screenshots in ContextQA — every run produces a complete evidence package including WebM video, HAR, and Playwright trace. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, QA managers, and engineering managers who need to understand, access, and share the full evidence package captured during every test execution.
{% endhint %}
> **Execution evidence package:** The complete set of artifacts ContextQA captures for every test run — per-step screenshots, a session-level WebM video, an HAR network log, a browser console log, and a Playwright trace ZIP — stored per execution and accessible from the portal and via MCP tools.
When a test fails at 2 AM in a CI pipeline, the person investigating needs more than a pass/fail status. ContextQA captures a full evidence package for every execution so that failures are reproducible without re-running the test. This page describes every artifact type, how to locate and download each one from the portal, how S3 URL expiry works, and how MCP tools expose artifacts programmatically.

Treat the run page as the evidence record: begin with the failed step and its screenshot, then use video for sequence, console and network logs for application or service errors, and the trace for detailed browser timing and interaction. Classify the failure before filing a product defect. See [Regression risk and execution evidence](/business-use-cases/regression-risk-and-evidence) for the complete triage pattern.
## What artifacts does ContextQA produce?
ContextQA produces the following artifacts for each test execution:
| Artifact | Format | Scope | Description |
| ------------------- | ---------- | ------------- | ------------------------------------------------------------------------------------------------ |
| Step screenshots | JPG | Per step | One screenshot captured at the conclusion of each test step |
| Session video | WebM | Per test case | Full-session screen recording from browser launch to close |
| Network HAR | HAR (JSON) | Per test case | All HTTP/HTTPS requests and responses, including timing and headers |
| Browser console log | Text | Per test case | All `console.log`, `console.warn`, and `console.error` output from the page |
| Playwright trace | ZIP | Per test case | Playwright's built-in trace format, viewable at trace.playwright.dev |
| AI reasoning log | JSON | Per test case | ContextQA's internal AI decision log — step interpretations, selector choices, healing decisions |
All artifacts are stored in S3-backed object storage. URLs returned by the portal and by MCP tools are pre-signed and expire after **1 hour**. Always fetch a fresh URL from the portal or via the MCP tools before attempting to download — do not cache artifact URLs between sessions.
## Screenshot capture modes
Screenshot behavior is configurable per test plan. The three modes are:
| Mode | Behavior | Use case |
| -------------- | --------------------------------------------------------------------------------- | --------------------------------------------------------------------------------- |
| `ALL_TYPES` | Screenshot captured at every step regardless of pass/fail | Full audit trails, compliance testing, debugging step sequences |
| `FAILED_STEPS` | Screenshot captured only at the failing step (and the step immediately before it) | Faster runs, reduced storage consumption for large suites |
| `NONE` | No screenshots captured | Maximum speed; use only for performance benchmarking or ephemeral validation runs |
To set the screenshot mode:
1. Open **Test Plans** in the left navigation.
2. Select the test plan and click **Edit**.
3. In the plan settings step, locate the **Capture Screenshots** dropdown.
4. Select `ALL_TYPES`, `FAILED_STEPS`, or `NONE`.
5. Click **Save**.
The video recording is not affected by the screenshot mode setting — video is always captured when the plan is configured to record. Video can be disabled separately if storage cost is a concern.
## On-demand video capture during debug sessions
In addition to the automatic session recording, the interactive debugger supports on-demand video capture. While execution is paused at a step, you can click the **Capture Video** button in the simulator header to record a video clip of a specific interaction. Captured clips are available in the **Captured** view of the simulator during the live session.
After the debug execution completes, mid-session clips are replaced by the canonical full-session recording. For the complete workflow, see [Capturing video during a debug session](/execution/debugging-tests#capturing-video-during-a-debug-session).
## Locating artifacts in the execution report UI
After an execution completes:
1. Navigate to **Run Results** in the left navigation under **Test Plan & Results**.
2. Click the specific execution run to open the **Execution Report**.
3. Select a test case row to expand the step-level detail panel.
4. Each step row shows a thumbnail screenshot. Click the thumbnail to open the full-size JPG.
5. At the top of the case detail panel, the **Run Details** section displays the video, network HAR, console log, and Playwright trace artifacts inline.
The **Video** tab embeds the WebM player directly in the portal. Browsers that do not support WebM natively may require downloading the file and playing it locally with VLC or a compatible player.
## Downloading artifacts
**From the portal:**
* Click the download icon adjacent to each artifact tab to trigger a direct download.
* The downloaded file is the raw artifact: a `.webm` video, a `.har` JSON file, a `.zip` Playwright trace, or a `.txt` console log.
**Via MCP tools:**
ContextQA exposes six MCP tools for artifact retrieval:
| MCP Tool | Returns |
| ---------------------------- | --------------------------------------------------------------- |
| `get_execution_step_details` | Step-level data including screenshot URLs for each step |
| `get_network_logs` | The HAR content for a given execution |
| `get_console_logs` | The browser console log text for a given execution |
| `get_trace_url` | A pre-signed S3 URL for the Playwright trace ZIP |
| `get_ai_reasoning` | The AI reasoning log for a given execution |
| `get_test_step_results` | Pass/fail and metadata for each step, including screenshot URLs |
All URL-returning tools produce pre-signed S3 URLs. These URLs expire after **1 hour**. If you are building an automation that downloads artifacts after execution polling completes, call the relevant tool immediately after the execution status transitions to `PASSED` or `FAILED` — do not store the URL and use it later.
## Using the Playwright trace viewer
The Playwright trace is the most detailed artifact ContextQA produces. It contains:
* A DOM snapshot at every action
* Network request waterfall
* Console output timeline
* Screenshots interleaved with actions
* Test step durations
To view a trace:
1. Download the `.zip` trace file from the **Trace** artifact tab in the execution report, or retrieve the URL via the `get_trace_url` MCP tool.
2. Open [trace.playwright.dev](https://trace.playwright.dev) in any modern browser.
3. Drag and drop the `.zip` file onto the page, or click **Upload** and select the file.
4. The trace viewer opens with a full interactive timeline.
The Playwright trace viewer is a static web application — it requires no account, no login, and no ContextQA access. This makes it a portable audit artifact that can be attached to Jira tickets, shared in Slack, or archived independently of the ContextQA portal.
## S3 URL expiry and access patterns
Pre-signed S3 URLs are scoped to a single artifact and expire after **1 hour** from the time they are generated. This is a security constraint, not a content retention limit — the underlying artifact in storage persists for the duration defined by your organization's retention policy.
**Correct pattern:** Fetch the URL → download the artifact immediately.
**Incorrect pattern:** Fetch the URL → store the URL → download the artifact hours later. This will result in a 403 Forbidden response from S3.
If you are archiving artifacts to an external system (for example, an S3 bucket you control, or an evidence management tool), download the artifact immediately after receiving the URL and upload it to your target system in the same pipeline step.
## On-demand video capture in debug mode
In addition to the automatic full-session video recording, debug mode supports on-demand video capture. You can record a video clip of a specific execution segment while the debugger is paused at a breakpoint.
### Capturing a video clip
1. Start a debug session and pause execution at a breakpoint or step.
2. Click the **Capture Video** button in the live view panel header. The button is visible when execution is paused during an active debug session.
3. A progress dialog appears with the capture status:
* **Starting** — the capture request has been sent.
* **Capturing** — the video segment is being recorded.
* **Ready** — the clip is available for playback.
4. Click **Watch Now** to switch to the **Captured** view, or click **Close** to dismiss.
### Live and Captured views
The live view panel header includes a **Live / Captured** toggle during debug sessions. Switch between:
* **Live** — the real-time VNC browser stream.
* **Captured** — previously captured video clips from the current session.
Clips are accumulated during the session. Automatic iteration-end clips are also appended silently when available.
### What happens when the debug session ends
When the debug execution completes, the full session video (from `screen_recordings`) replaces any mid-session clips. The full video appears in the standard execution report, accessible from the **Video** tab in the test results.
***
## Frequently Asked Questions
### Why does the video show a black screen for some steps?
This typically occurs when the test case navigates to a page that triggers a browser prompt (alert, confirm, or file chooser) before the video frame is captured. The browser renders these prompts outside the normal page compositing layer, so they appear black in WebM recordings. Screenshots at the step level are captured differently and usually show the prompt correctly.
### Can I configure ContextQA to keep artifacts for longer than the default retention period?
Artifact retention is governed by your organization's subscription tier and the storage policy configured in **Settings → Organization Settings**. Contact ContextQA support to discuss extended retention. Artifact S3 URL expiry (1 hour) is separate from artifact retention and cannot be extended — it is a security property of the pre-signed URL system.
### Does `FAILED_STEPS` screenshot mode affect the video?
No. Video recording captures the full session regardless of screenshot mode. `FAILED_STEPS` only controls which steps receive a screenshot capture event. The WebM video remains a continuous recording from session start to end.
### How large are typical evidence packages?
A 30-step test case in `ALL_TYPES` mode produces approximately 30 JPG screenshots (typically 50–200 KB each), a 5–15 MB WebM video, a 1–5 MB HAR file, and a 2–10 MB Playwright trace ZIP. For suites with hundreds of test cases, storage consumption can reach several gigabytes per execution run.
## Related
* [Running tests and test plans](/execution/running-tests)
* [Parallel test execution](/execution/parallel-execution)
* [Failure analysis and root cause](/reporting/failure-analysis)
* [Exporting reports](/reporting/exporting-reports)
* [MCP server tool reference](/mcp-server/overview)
{% hint style="info" %}
**10× faster with parallel execution across browsers and devices.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See ContextQA run your full test suite in parallel CI/CD execution.
{% endhint %}
# Interactive Demo
Explore a live test execution run — step-by-step results, per-step screenshots, console logs, network traces, and AI root cause analysis, all captured automatically.
## Quick answer
Explore a live test execution run — step-by-step results, per-step screenshots, console logs, network traces, and AI root cause analysis, all captured automatically. Use this page to preview the workflow and its visible results before following the linked written instructions.
## What this page covers
Every ContextQA test run captures a complete evidence package automatically: per-step screenshots, session video, browser console logs, HAR network trace, and an AI root cause analysis for any failure. This demo walks through a 12-test execution run and shows how to investigate a failure using the captured artifacts.
{% tabs %}
{% tab title="Execution Overview" %}
{% stepper %}
{% step %}
### Execution Summary
A test plan with 12 test cases completed in 2 minutes and 34 seconds across 5 parallel workers.
| Metric | Value |
| ---------------- | ------ |
| Total Tests | 12 |
| Passed | 10 |
| Failed | 1 |
| Self-Healed | 1 |
| Duration | 2m 34s |
| Parallel Workers | 5 |
{% hint style="info" %}
**AI Agent:** Parallel execution distributes tests across multiple browser workers simultaneously, reducing total run time significantly compared to sequential execution.
{% endhint %}
{% endstep %}
{% step %}
### Test Case List
Click any test in the list to view its step-by-step results.
**12 test cases in this run:**
| # | Test Name | Status | Duration |
| -- | ------------------------- | ---------- | -------- |
| 1 | Login — valid credentials | Passed | 12s |
| 2 | Login — invalid password | Passed | 9s |
| 3 | Login — MFA flow | **Failed** | 18s |
| 4 | Add item to cart | Passed | 14s |
| 5 | Apply discount code | Passed | 11s |
| 6 | Checkout — credit card | **Healed** | 22s |
| 7 | Order confirmation email | Passed | 8s |
| 8 | Profile — update email | Passed | 10s |
| 9 | Forgot password flow | Passed | 13s |
| 10 | Search — product name | Passed | 7s |
| 11 | Filter by category | Passed | 9s |
| 12 | Mobile — responsive nav | Passed | 11s |
{% hint style="info" %}
**AI Agent:** Failed and healed tests are highlighted in the list. Selecting a test shows its individual step results and links to all captured evidence artifacts.
{% endhint %}
{% endstep %}
{% step %}
### Step-by-Step Results ✓
Selecting test #3 ("Login — MFA flow") shows the individual step results.
**Steps for "Login — MFA flow":**
1. ✓ Navigate to `/login` — 245ms
2. ✓ Enter email in Email field — 120ms
3. ✓ Enter password in Password field — 98ms
4. ✗ Click the Sign In button — POST /api/auth/login → 401 Unauthorized
{% hint style="success" %}
**AI Agent:** Each step shows the action performed, the element targeted, the timing, and — for failures — the error response. A screenshot thumbnail is available for every step.
Actions available from the results view:
* Re-run All
* Export Report
* Share the result URL with recipients who have access to the ContextQA organization
{% endhint %}
{% endstep %}
{% endstepper %}
{% endtab %}
{% tab title="Failure Investigation" %}
{% stepper %}
{% step %}
### Screenshots
The Screenshots tab shows a thumbnail for each step. Failed steps are highlighted in red, making it easy to see exactly what the browser displayed at the moment of failure.
**Step screenshots for "Login — MFA flow":**
* Step 1: Navigate — Pass
* Step 2: Enter Email — Pass
* Step 3: Click Login — **Fail**
{% hint style="info" %}
**AI Agent:** Screenshots are captured automatically after every step — no configuration required. They are stored and accessible indefinitely from the execution results.
{% endhint %}
{% endstep %}
{% step %}
### Console Log
The Console Log tab shows all browser console output captured during the test, including errors, warnings, and info messages with timestamps.
```
[12:34:01] INFO Page loaded — https://demo.contextqa.com/login
[12:34:02] INFO DOMContentLoaded
[12:34:04] ERROR Cannot read property 'submit' of null
[12:34:04] WARN Login button selector mismatch — retrying
[12:34:05] INFO Self-healing activated
```
{% hint style="info" %}
**AI Agent:** Console logs are captured at the browser level for every test run. The full log is indexed and searchable across executions — useful for diagnosing intermittent JavaScript errors.
{% endhint %}
{% endstep %}
{% step %}
### Network (HAR) Trace
The Network tab shows every HTTP request made during the test, including the status code, response time, and content type — in HAR format.
```
GET 200 /login 45ms text/html
POST 200 /api/analytics 12ms application/json
POST 401 /api/auth/login 38ms application/json ← FAILED
GET 200 /assets/main.js 890ms application/javascript
```
{% hint style="info" %}
**AI Agent:** The HAR trace captures every network request, making it straightforward to identify failed API calls, slow responses, or unexpected redirects that caused a test to fail.
{% endhint %}
{% endstep %}
{% step %}
### AI Root Cause Analysis ✓
The Root Cause AI tab provides an automated analysis of the failure, synthesizing the screenshot, console log, and network trace into a human-readable explanation with a suggested fix.
```
AI Root Cause Analysis
━━━━━━━━━━━━━━━━━━━━━━
Failure Summary:
The login request returned HTTP 401 Unauthorized.
The API rejected the credentials in step 3.
Classification: APPLICATION_BUG
Affected Step: 3 (POST /api/auth/login)
Evidence Used:
• Screenshot step 3 — login form submitted
• HAR log — 401 response from /api/auth/login
• Console log — error: "Authentication failed"
Suggested Fix:
Verify the test credentials are valid in the staging
environment. The user account may have been deactivated
or the password may have changed. Update the Test Data
Profile with valid credentials.
```
{% hint style="success" %}
**AI Agent:** Root cause analysis is generated automatically for every failed test — no manual investigation needed to understand why a test failed. The AI classifies the failure type (Application Bug, Flaky, Test Bug, or Environment Issue) to help teams prioritize their response.
{% endhint %}
| Evidence Artifact | Format | Captured Automatically |
| ----------------- | ------ | ---------------------- |
| Step Screenshots | JPG | Yes — every step |
| Session Video | WebM | Yes — full run |
| Console Log | Text | Yes — full browser log |
| Network Trace | HAR | Yes — all requests |
| AI Root Cause | Text | Yes — on failure |
| Playwright Trace | ZIP | Yes — DOM + timing |
| {% endstep %} | | |
| {% endstepper %} | | |
| {% endtab %} | | |
| {% endtabs %} | | |
***
{% hint style="success" %}
**See ContextQA with your own workflow** — [Book a Demo →](https://contextqa.com/book-a-demo/)
{% endhint %}
## Related documentation
[Run tests](/execution/running-tests) · [Review execution video and screenshots](/execution/video-and-screenshots)
# Reporting Overview
An overview of the dashboards, reports, and analytics that ContextQA provides to help QA teams, developers, and engineering managers understand test health at every level.
{% hint style="info" %}
**Who is this for?** QA managers, engineering managers, and VPs who need clear visibility into test health, pass rates, flakiness trends, and release readiness — without manual spreadsheet tracking.
{% endhint %}
ContextQA centralizes all test quality data into a set of dashboards and reports so every stakeholder has the right view of what is happening across the test suite. From a real-time execution feed to AI-generated quality observations, the reporting layer surfaces the information you need without requiring manual spreadsheet tracking or log diving.
## Quick answer
ContextQA reporting combines workspace activity, execution health, test results, coverage signals, failure analysis, and risk views. Testers use the result evidence to debug a run; QA managers use trends and consistently failing tests to manage suite health; engineering leaders use scoped readiness and risk signals to support release decisions. A dashboard is decision support, not a replacement for reviewing the underlying failed executions.

***
## Who uses reporting in ContextQA?
| Role | Primary concern | Recommended starting point |
| ----------------------------------- | -------------------------------------------------------------------------------------- | ---------------------------------------------- |
| **QA engineer** | Did my last run pass? What failed and why? | Execution Dashboard → test run detail |
| **QA manager** | What is our overall pass rate, flakiness, and coverage trend? | Dashboard → Execution Dashboard → Coverage tab |
| **Developer** | Which specific step failed, what did the UI look like, and what is the fix suggestion? | Test result detail page → Failure Analysis |
| **Engineering manager / executive** | Are we shipping with confidence? How is quality trending across sprints? | Dashboard → Insight tab → RBT tab |
***
## What is available
### Main Dashboard
The **Dashboard** (accessible from the left sidebar) is your command center. It shows:
* Total test case volume split by web, mobile, and API
* Daily activity trend comparing AI-driven actions (auto-heal, root cause analysis) versus human interventions
* A daily bar chart breaking down cases created, reviewed, executed, root-cause-identified, and auto-healed
Use the date range picker to scope all widgets to a sprint or release window. Toggle between line and bar chart modes on the activity trend widget.
### Execution Dashboard
The **Execution Dashboard** gives a live and historical view of every test run. Key panels include:
* Run-level summary: total executed, passed, failed, aborted, and success rate versus previous period
* Execution trend graph: daily pass/fail/aborted counts over time
* Test distribution widget: environment breakdown (web, mobile, API)
* Consistently failing test cases: a ranked list with root cause and failure count per case
### Coverage Dashboard
The **Coverage** tab inside the Execution Dashboard shows which application modules have test coverage and which do not. Each module card lists positive, negative, and ad-hoc scenarios and flags unresolved issues with a red badge.
### Insight and Risk-Based Testing
The **Insight** tab surfaces test health and readiness blockers — missing test data, broken prerequisites — with priority, source, and status for each blocker. The **RBT (Risk-Based Testing)** tab provides a heatmap matrix mapping test cases and defects against business priority and usage frequency so you can direct effort toward the highest-risk areas.
### Test Result Detail Pages
Each individual test execution has a detail page showing step-by-step pass/fail results, screenshots, video replay, and downloadable Playwright trace files. See [Test Results](/reporting/test-results) for a full walkthrough.
### Failure Analysis
The failure analysis view provides AI-generated root cause explanations, fix suggestions, and flaky test detection. Failures can be pushed directly to Jira or Azure DevOps. See [Failure Analysis](/reporting/failure-analysis).
***
## Navigating to reports
All reporting surfaces are reachable from the **left sidebar**:
* **Dashboard** — top-level platform summary
* **Execution Dashboard** — run history and per-run detail
* **Reports** — detailed pass/fail reports with screenshots, video, and step logs
***
## In this section
* [Test Results](/reporting/test-results) — understanding execution result pages
* [Analytics Dashboard](/reporting/analytics-dashboard) — dashboards, trends, and AI insights
* [Failure Analysis](/reporting/failure-analysis) — root cause analysis, flakiness, and bug tracker integration
***
## Execution Evidence
The following recording is from a live ContextQA execution of the analytics dashboard:
***
## FAQs
How do I scope dashboard data to a specific sprint or date range?
Use the date range picker at the top-right of the Dashboard page to filter all widgets to a specific window. You can select a preset (last 7 days, last 30 days) or define a custom range.
Can I export test results for stakeholder reporting?
ContextQA does not currently offer a general PDF or CSV export for a complete execution result. Share the authenticated execution URL, download the available evidence artifacts, or retrieve structured result JSON through MCP. The separate **Execution history** matrix can export its active view to CSV. See [Exporting Reports](/reporting/exporting-reports) for the exact boundaries.
Where do I see which tests are consistently flaky?
The Execution Dashboard's **Consistently failing test cases** panel ranks tests by failure count. The [Failure Analysis](/reporting/failure-analysis) view provides AI-generated root cause explanations and flaky test detection across your suite.
{% hint style="info" %}
**Get release readiness reports your stakeholders understand** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Test Results
Monitor a ContextQA test, inspect results and evidence, identify the mobile app build used by a run, and download a retained build for reproduction.
## Quick answer
Use the execution screen for live step progress and the completed run result for durable evidence. The result contains status, configuration, steps, screenshots, video, console, network, trace, and recent-run context when those artifacts are enabled. For a mobile run, the header shows the saved app-build name and provides **Download build** while the artifact remains available.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers, developers, technical writers, and release owners who need to monitor a run or investigate its evidence.
{% endhint %}
ContextQA separates a test run into two views:
* The **execution screen** shows live progress while the browser is running.
* The **run result screen** preserves the outcome, configuration, logs, and visual evidence after the run finishes.
This guide follows one standalone web test from execution to its passed result. Controls and artifacts can vary by test type, permissions, workspace configuration, and whether recording was enabled.
## Interactive demo: execution to evidence
Use this four-screen tour to follow a test from launch through live progress, completion, and retained visual evidence. The walkthrough is designed for a quick release-readiness review rather than a full product tour.
{% embed url="" %}
### What to notice
* Run configuration establishes what was tested before execution starts.
* Live progress identifies the active step and current application state.
* The completed result and visual artifacts help another authorized reviewer understand the outcome without recreating the run.
***
## Open the execution screen
1. Select **Test Cases** in the left sidebar.
2. Open the test case you want to run.
3. Select **Run**.
4. Choose the required browser, environment, and execution settings.
5. Start the run.
ContextQA opens the execution screen and updates it as each prerequisite and test step runs.

## Monitor a live execution
### Run header
Use the header to confirm that you are watching the intended run:
| Item | What it tells you |
| -------------------- | --------------------------------------------------------------------------------------------------- |
| Status | Whether the run is running, passed, failed, or stopped |
| Duration | Elapsed run time, anchored to the server-recorded execution start |
| Executed count | Completed steps compared with total steps |
| Platform and browser | For example, **Web** and **Chrome** |
| Run type | For example, **Manual** |
| Version | The workspace or test version used for the run |
| Bug | Creates a defect from available run evidence; availability can depend on run state and integrations |
| Stop | Stops an active run |
### Steps tab
The **Steps** tab is the primary execution timeline. It can show:
* prerequisites separately from the test's own steps;
* the active, passed, or failed state of each step;
* the time spent on each step;
* locator search and element-found events;
* click or input actions;
* auto-heal activity; and
* AI verification output.
Expand a step when you need its detailed event sequence. A prerequisite contributes to the total executed-step count, even though the result page can summarize the test's own steps separately.
#### API Data for REST API steps
When the selected step is a REST API call, open its **API Data** view to inspect the captured response status, body, and headers available for that run. In the JSON response viewer, select a property or value to copy or choose its generated JSON path when the control is available. Use that path in a payload validation or to capture a value for a later request.
For example, selecting `userId` in the first object of an array can produce a path such as `$[0].userId`. Review the generated path against the actual response shape; for dynamic arrays or unsupported structures, enter and test the path manually in the API step's validation settings. Do not infer a path from a screenshot when the retained response body is unavailable.
### Console tab
Select **Console** to inspect browser messages captured during execution. Early in a run, this tab can report that execution is still in progress and no logs are available yet.
Console errors do not automatically mean the test failed. A test can pass its configured assertions while the application logs unrelated `403`, `500`, warning, or diagnostic messages. Review console evidence independently when it matters to release quality.
### Network tab
Select **Network** to inspect requests captured during execution. The live view includes a search field for URL, method, or status. It can be empty until the browser has made and uploaded requests.
### Live browser area
The browser area identifies the platform, browser, and viewport, and displays the live session stream. Use it to confirm that the automation is on the expected page and is not blocked by a dialog, loading state, or authentication screen.
{% hint style="warning" %}
Do not treat the live stream as the durable evidence record. Open the completed result and review the generated artifacts before sharing or publishing them.
{% endhint %}
***
## Actions available after completion
When execution finishes, the screen displays the final status and exposes the next actions.

| Action | Use it to |
| ----------------------- | ---------------------------------------------------------------------------------------------------------------- |
| **View Run Results** | Open the persistent result and all captured evidence |
| **Re Run** | Execute the same test again |
| **Bug** | Open the destination chooser and create a Jira or Azure DevOps defect when an integration is available |
| **Debug log** | Download the retained engine log when the run was produced by an on-premises deployment and the log is available |
| **Screenshots / Video** | Preview captured visual evidence |
| **Copy run link** | Copy a link for another authorized ContextQA user |
| **Back To Test Case** | Return to the test editor |
| **Close** | Leave the completed execution view |
Use **View Run Results** for the complete investigation workflow.
***
## Read the run result screen

### Result header and metadata
The result header identifies the test name, final status, run ID, execution time, and duration. It can also break duration into application, tool, and AI time.
Metadata badges describe the execution context, including platform, browser, run type, environment, standalone or plan execution, viewport, and labels. Use these values before comparing two runs; unlike configurations can produce misleading comparisons.
For a mobile run, the header identifies the application build captured when that run was dispatched—not whichever build the device or test case uses today. If that retained artifact is still available, select the adjacent **Download build** action to retrieve the same package for reproduction. Older results created before build snapshots were recorded can fall back to the current device or test configuration. Treat the package as an internal artifact and distribute it only through an approved channel.
When **Bug** is available, select it to choose the configured defect tracker. ContextQA can send the failure to Jira or Azure DevOps and returns the destination reference so the team knows where the defect was created.
On an on-premises deployment, **Debug log** appears only when the result has a retained engine log. Download it for an authorized support investigation, then review the file for credentials, tokens, personal data, and internal URLs before sharing. The action is not expected on ContextQA Cloud results.
### Analysis
The **Analysis** view summarizes status and counts such as total, passed, failed, and self-healed steps.
{% hint style="warning" %}
Treat percentages as telemetry that still needs a reasonableness check. During the documented pilot, a passed two-step run displayed a self-healed value of **150%**. Values outside the expected range should be reported to the workspace administrator or ContextQA support and should not be copied into release metrics without validation.
{% endhint %}
### Configuration
Open **Configuration** to reconstruct how the run was executed. Depending on the test, this view can include:
* environment, platform, browser, and viewport;
* AI metadata, smartness, and default AI action;
* wait and test-case timeouts;
* auto-wait, auto-heal, and recording flags; and
* API mocking state.
Record configuration with the outcome when diagnosing a failure or documenting a reproducible example.
### Recent Runs
Open **Recent Runs** to review earlier executions of the same test. Each row can show run ID, outcome, execution type, timestamp, duration, platform, and standalone or plan context.
Select **Compare Runs** to choose a base run and a comparison run. The dialog includes passed, failed, and aborted status indicators and reports how many steps are being compared. Compare runs with similar configuration for the most useful result.
***
## Inspect step and diagnostic evidence
### Steps
The result separates prerequisites from the test's own steps. Open a step to review its description, status, duration, locator or action events, and AI verification response.
For a failed run, begin with the first failed step rather than the last recorded event. Then correlate that step with its screenshot, console messages, network calls, video time, and trace.
### Console
The completed **Console** tab contains captured browser output such as errors, warnings, autocomplete messages, and application logs. Use it to answer questions such as:
* Did the page log a JavaScript or resource-loading error?
* Did an authorization request return `403`?
* Did an application service return `500` even though the assertion passed?
The test result reflects configured test assertions; the console reflects application behavior. Review both.
Use the download action in the **Console** section to save the captured output as a text file for offline investigation or an approved defect report. Review the file for credentials, tokens, personal data, and customer information before sharing it outside the workspace.
### Network
The completed **Network** tab provides search, filters, and a request table. Available controls can include:
* search by URL, method, or status;
* evidence-source filters such as mocked, recorded, live, fetch, or XHR;
* method filters such as `GET`, `POST`, `PUT`, and `DELETE`;
* method, URL, status, duration, and size columns; and
* pagination for longer request lists.
Use network evidence to confirm that an expected request occurred, inspect failing status codes, and identify slow calls. A successful UI assertion does not guarantee that every background request succeeded.
***
## Review screenshots, video, and trace
### Screenshots
Open **Screenshots** to view images generated during the run. Select a screenshot to inspect the captured page state at full size.

Before publishing a screenshot:
1. Confirm it belongs to the correct run and step.
2. Check that the expected UI state is visible.
3. Crop only when the surrounding interface adds no useful context.
4. Redact credentials, tokens, personal data, internal URLs, customer data, and unrelated test names.
5. Add descriptive alternative text and a caption that explains what the reader should notice.
### Video
Open **Video** to play the recorded browser session. The observed player provided a video count, step markers, playback speed, duration, and an expanded-player control.
Use video when motion or timing is important—for example, a loading transition, menu expansion, hover interaction, or failure that is unclear from a still image. Link readers to the authenticated run result instead of embedding a temporary signed media URL.
### Trace
Open **Trace** for the interactive execution trace when it is available. Trace evidence is useful when screenshots and video do not explain a locator, timing, DOM, or request problem.
{% hint style="info" %}
Artifact availability depends on the run configuration and retention policy for your workspace. Verify access before relying on a run link as long-term documentation evidence.
{% endhint %}
***
## Documentation evidence workflow
Use a disposable, documentation-specific test so evidence collection does not change a valuable regression test.
1. Create or duplicate a suitable test and give it a clear `DOC-` prefix.
2. Remove destructive actions and use fictional, non-sensitive data.
3. Keep verifications within the visible viewport when the evidence needs to show several controls at once.
4. Run the test and wait for a final status.
5. Review **Steps**, **Console**, and **Network**, even when the run passes.
6. Open **View Run Results** and review **Analysis**, **Configuration**, and **Recent Runs**.
7. Review **Screenshots**, **Video**, and **Trace**.
8. Download only approved evidence, redact it if necessary, and add meaningful alt text.
9. Record the test ID and run ID in the documentation work item for auditability.
10. Delete the disposable test from the active list after the documentation is published. Use permanent deletion only when your retention policy requires it.
## Troubleshooting
The run passed, but Console contains errors
A passing status means the configured test assertions passed. It does not certify that every browser resource or background request succeeded. Review whether the errors affect the user journey, then create a defect or a separate assertion when appropriate.
No network requests appear during execution
Wait for the browser to navigate and for evidence to upload. If the completed result remains empty, confirm that recording was enabled and rerun with the required execution configuration.
The screenshot or video control is missing
Confirm that recording was enabled for the run and that the artifact is still retained and accessible in your workspace. Permissions and test type can also affect availability.
Why is Debug log missing?
The action is limited to on-premises results that contain a retained engine log. It is not shown for ContextQA Cloud runs or when the log URL is absent.
A shared run link does not open for another person
Run results can require an authenticated ContextQA session and access to the same workspace. Share exported, reviewed evidence through your approved documentation channel when the reader should not have platform access.
## Related pages
* [Create test cases](/web-testing/creating-test-cases)
* [Running tests](/execution/running-tests)
* [Video and screenshots](/execution/video-and-screenshots)
* [Failure analysis](/reporting/failure-analysis)
* [Flaky test detection](/reporting/flaky-test-detection)
# Execution History
Compare a test plan's recent runs side by side with ContextQA's execution history — a per-run matrix, plan summary, pass-rate trends, and CSV export.
## Quick answer
Compare a test plan's recent runs side by side with ContextQA's execution history — a per-run matrix, plan summary, pass-rate trends, and CSV export. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers, SDETs, and testers who want to see how a test plan has performed across its recent runs — which test cases keep failing, how the pass rate is trending, and where stability is improving or regressing.
{% endhint %}
A single run tells you whether a plan passed or failed today. **Execution history** tells you the story across many runs: it lines up a test plan's most recent executions side by side so you can spot recurring failures, flaky test cases, and pass-rate trends over time.
***
## Opening execution history
You can open execution history from two places.
### From a test plan
1. Navigate to **Test Development** → **Test Plans** in the left sidebar.
2. Click a plan to open its detail page.
3. Click the **Execution History** tab.
The tab loads the history for that plan only.
### From the dashboard
1. Open the execution dashboard for a plan run.
2. Use the **Analytics** / **Execution History** toggle at the top of the view to switch to **Execution History**.
3. Select a plan from the plan dropdown to load its runs.
***
## Reading the report
The execution history view has three parts: a control bar, a row of summary cards, and a report table.
### Summary cards
A row of summary cards sits above the table and aggregates the executions currently in view:
* **Passed** — number of test case results that passed.
* **Failed** — number that failed.
* **Aborted** — number that aborted mid-run.
* **Skipped** — number skipped due to unmet prerequisites or configuration.
* **Total** — total test case results across the runs shown.
* **Pass rate** — passed results as a percentage of the total.
Below the cards, a row of meta chips shows the number of test cases, how many executions appear, the date range covered, and the plan ID.
### Test case matrix
The **Test case matrix** view answers "which test cases keep failing?" Each row is a test case and each column is one plan run, ordered with the most recent run first. Every cell shows a status badge for that test case in that run:
| Badge | Meaning |
| ----------- | -------------------------------------------------- |
| **Passed** | The test case passed in that run. |
| **Failed** | The test case failed in that run. |
| **Aborted** | The run was aborted before the test case finished. |
| **Skipped** | The test case did not run in that execution. |
Each row also shows the test case's pass rate across the runs in view, so a test case that fails intermittently stands out from one that fails every time.
### Plan summary
The **Plan summary** view answers "how did each run do overall?" Each column is a run and each row is a status category (Passed, Failed, Aborted, Skipped, and Total), with the count of test cases in that category for the run. Use this view to see pass and fail counts trend from one run to the next.
Switch between the two views with the report toggle in the control bar.
***
## Controls
The control bar at the top of the view provides:
| Control | What it does |
| ------------------- | ----------------------------------------------------------------------------------------------------------------- |
| **Report toggle** | Switches between the **Test case matrix** and **Plan summary** views. |
| **Plan dropdown** | Selects which plan to show. Hidden when you open the tab from a specific plan, which locks the view to that plan. |
| **Execution limit** | Sets how many recent runs to include: **Last 10**, **Last 30**, or **Last 50 executions**. |
| **Export CSV** | Downloads the data in the active view as a CSV file. |
***
## Exporting to CSV
Click **Export CSV** to download the report. The export matches the view you are looking at:
* From the **Test case matrix** view, the CSV has one row per test case and one column per run.
* From the **Plan summary** view, the CSV has one row per status category and one column per run.
Use the export to share results with stakeholders or to track pass-rate trends in your own spreadsheets.
***
## Empty state
If the selected plan has no recorded executions, the view shows an empty state instead of a table. Run the plan at least once — see [Running tests](/execution/running-tests) — and the run appears in execution history once it completes.
***
## Related pages
* [Test plans](/web-testing/test-plans)
* [Test results and reports](/reporting/test-results)
* [Analytics dashboard](/reporting/analytics-dashboard)
* [Flaky test detection](/reporting/flaky-test-detection)
* [Running tests](/execution/running-tests)
# Analytics Dashboard
A guide to the dashboards and analytics surfaces in ContextQA, including execution trends, coverage, AI insights, and risk-based testing.
## Quick answer
A guide to the dashboards and analytics surfaces in ContextQA, including execution trends, coverage, AI insights, and risk-based testing. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers, engineering managers, and VPs who need trend data, coverage visibility, and risk-based testing insights to make informed release decisions.
{% endhint %}
ContextQA provides several analytics dashboards that together give a complete picture of your QA program's health. All dashboards are accessible from the left sidebar and update as executions complete.
[Watch the dashboard overview](https://drive.google.com/file/d/12ulnwgfotrp_vy0SSlmVs9DUVeX5McY_/preview).
***
## Main Dashboard
Navigate to **Dashboard** in the left sidebar to see the top-level platform summary.
### Test case volume summary
At the top of the Dashboard, a compact summary shows the total number of active test cases split by type:
* Web test cases
* Mobile test cases
* API test cases
This gives QA managers and engineering leads an instant read on the breadth of automated coverage.
### AI vs. human activity trends
The activity trend widget compares two lines over a configurable date range:
* **AI Actions (green)** — steps executed, healed, or root-cause-analyzed automatically by the ContextQA AI engine with no human input
* **Human Interventions (purple)** — manual reviews, step edits, or manually triggered executions performed by team members
A healthy test suite shows a high AI-to-human ratio. Spikes in human activity often indicate a debugging session following a failed release or a batch of new test authoring work.
Toggle between line and bar chart modes and adjust the date range picker to scope the chart to a specific sprint or release window.
### Daily test case activity bar chart
To the right of the trend widget, a bar chart breaks each day into color-coded segments:
| Segment | Meaning |
| --------------------- | ----------------------------------------------------- |
| Created | New test cases authored that day |
| Reviewed | Cases reviewed by a team member |
| Executed | Cases run (manually or automatically) |
| Root cause identified | Cases where AI produced a root cause explanation |
| Auto healed | Cases where the AI self-healing engine updated a step |
Use this chart to identify whether a day with many failures was also a day with a high auto-heal rate — a sign the application UI changed but the tests adapted automatically.
***
## Execution Dashboard
Navigate to **Execution Dashboard** in the left sidebar for run-level analytics.
### Run history and execution trend graph
The top of the Execution Dashboard shows:
* Total executed tests for the selected period
* Count of passed, failed, and aborted tests
* Success rate versus the previous period
Below this summary, the **Execution Trend Graph** plots daily passed, failed, and aborted counts. Use it to spot failure spikes that correlate with deployments or to confirm that a fix reduced the failure rate.
### Test distribution widget
The distribution widget shows which environments and platforms your tests cover: web, mobile, and API. Use it to identify platform gaps — for example, if mobile coverage is low relative to web coverage in a period when a mobile feature shipped.
### Consistently failing tests
A ranked list shows the test cases that have failed most frequently in the selected period. Each card shows:
* Test case ID and name
* Root cause (if AI analysis is available)
* Failure count
Click any card to navigate directly to the failure analysis detail for that test case.
***
## Coverage Dashboard
Select the **Coverage** tab inside the Execution Dashboard.
Each application module appears as a card summarizing:
* Positive, negative, and ad-hoc scenarios covered
* Whether coverage was authored by AI or manually
* A **red badge** on modules with unresolved issues, enabling priority-based triage
The Coverage Dashboard helps QA managers answer "which features are we not testing?" before a release rather than after.
***
## Insight Tab and AI observations
Select the **Insight** tab inside the Execution Dashboard.
### Test health and readiness
This panel surfaces critical blockers preventing tests from running successfully — for example, missing test data or broken prerequisite steps. Each blocker is listed with:
* What is missing or broken
* Priority level
* Source (AI-detected or manually flagged)
* Current status
Resolve the listed blockers before re-running the affected tests to avoid misleading failure data.
### Source distribution
The **Source** tab shows how test cases were created: through interactive AI-assisted recording or bulk AI uploads. Visualizations help you understand team adoption of AI-assisted authoring over time.
***
## Risk-Based Testing (RBT) heatmap
Select the **RBT** tab inside the Execution Dashboard.

The heatmap matrix maps test cases and defects by two dimensions:
* **Business priority** (columns): Critical, High, Medium, Minor
* **Usage frequency** (rows): how often each feature area is exercised by end users
Each cell shows how many test cases and defects fall in that priority-frequency zone. Use the heatmap to direct testing effort toward high-priority, high-frequency areas first, and to identify areas that have many defects but low test coverage.
The horizontal axis is labeled **Business Priority** in the current UI. “Business priority,” “priority,” and the Critical/High/Medium/Minor column values refer to this same axis; they are not separate scoring systems.
Combine the heatmap with changed requirements, code impact, defect history, compliance obligations, and integration criticality. A low-frequency workflow may still be release-blocking when its failure has a high financial, legal, or operational impact. See [Regression risk and execution evidence](/business-use-cases/regression-risk-and-evidence) for a portfolio and release-decision pattern.
### Do not confuse the heatmap surfaces
| Surface | What it shows | Prerequisite |
| -------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- |
| **RBT heatmap** | Test cases and defects arranged by usage frequency and business priority. | RBT access and classified test data. |
| **Element Usage Heatmap (Beta)** | Captured interaction activity over a page. It helps identify frequently used controls and areas that may deserve coverage. | The heatmap capability, a supported page URL, and captured data from the ContextQA Chrome extension. |
| **AI Insights activity pages** | URLs and user journeys observed in analyzed sessions; a page can offer **Open heatmap (Beta)** when heatmap data is eligible. | Captured AI Insights sessions and the browser extension. |
These surfaces are not a general-purpose real-user monitoring dashboard. ContextQA does not currently expose a separate public **RUM** page with standard production-monitoring metrics such as Core Web Vitals, page-load percentiles, or uptime. Availability of Beta heatmaps depends on workspace entitlement and captured data; when a page has no eligible data, the UI reports that no heatmap is available.
***
## Activity Log
Select the **Activity Log** tab inside the Execution Dashboard to browse a timestamped audit trail of all system and user actions. Each entry shows:
* Action performed
* Who performed it (user or AI)
* Affected test case or item
* Exact timestamp
Filter by action type, user, or date range to zero in on relevant changes. The activity log is useful for compliance audits and for understanding what changed between a passing run and a failing run.
***
## Filtering dashboards
All dashboard panels respect a common set of filters available in the toolbar:
* **Date range** — scope all widgets to a sprint, release window, or custom range using the date range picker
* **Test plan** — filter execution data to a specific test plan
* **Environment** — isolate results from staging, production, or a custom environment profile
* **Labels** — filter by the labels applied to test cases (e.g., by JIRA ticket number or feature area)
Applying these filters simultaneously is the fastest way to answer "how did the checkout feature perform in staging during the last sprint?" without leaving the dashboard.
{% hint style="info" %}
**Get release readiness reports your stakeholders understand.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the analytics dashboard, failure analysis, and flaky test detection for your test suite.
{% endhint %}
# Failure Analysis
How to use ContextQA's failure analysis, root cause, flaky test detection, and bug tracker integration features to diagnose and resolve test failures quickly.
## Quick answer
How to use ContextQA's failure analysis, root cause, flaky test detection, and bug tracker integration features to diagnose and resolve test failures quickly. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers and engineering managers who need to quickly diagnose test failures, distinguish real bugs from flaky tests, and push defects directly to Jira or Azure DevOps.
{% endhint %}
When a test fails, the goal is to determine as fast as possible whether the failure represents a real bug in the application, a flaky environmental issue, or a test that needs updating. ContextQA provides several tools to answer that question without manual log analysis.
## Interactive course: analyze root cause and impact
Use these two course segments to move from a failed execution and its captured evidence to an AI-assisted root-cause and impact assessment.
### Part 1 — Inspect the failed execution
{% embed url="" %}
### Part 2 — Review AI root cause and impact
{% embed url="" %}
### What to notice
* The investigation starts with the first meaningful failure and the evidence actually captured by that run.
* AI analysis distinguishes likely product, script, data, environment, and integration causes without presenting an unsupported conclusion as fact.
* Impact context helps a reviewer decide whether to update a test, rerun it, investigate the application, or create a defect.
***
## Accessing failure analysis from the results page
After a test execution completes:
1. Open the execution result page (via **View Detailed Report** in the post-run pop-up, or via **Execution Dashboard** → run history).
2. Click the failed step or the failing test case card.
3. The failure detail panel expands showing the error message, screenshot, and network log entries captured at the moment of failure.
From this panel you can access the full **Root Cause Analysis** view by clicking the root cause indicator or navigating to the failure analysis section.
***
## Root cause analysis
ContextQA's AI engine analyzes failed steps and produces a structured root cause report. The report contains:
* **Failure category** — a classification of the failure type (e.g., element not found, assertion mismatch, network error, timeout)
* **AI explanation** — a plain-English description of what went wrong and why, generated from the screenshot, DOM state, and error message captured at the point of failure
* **Fix suggestion** — a recommended action to resolve the failure, such as updating a locator, adding a wait step, or investigating a specific API endpoint
The AI explanation and fix suggestion are displayed directly in the result page so a developer or QA engineer can act on them without needing to reproduce the failure locally first.
### Evidence used by root cause analysis
The analysis can correlate several evidence layers, but only evidence captured by that run is available:
| Evidence layer | When it is available |
| ----------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| Failed step and runtime error | For a recorded failed step. |
| Screenshot and DOM/page state | For supported browser runs when visual and page-state capture completed. |
| Console and network data | When the browser run captured those logs; API-only and interrupted runs can have different evidence. |
| Test data and configuration context | When the run used attached data or environment configuration. Secret values remain masked and should not be copied into a defect. |
| Historical pattern | When earlier comparable executions exist. A single run cannot establish a repeatable trend by itself. |
| Repository file or line | Only when a compatible code/repository integration supplies source context. It is not guaranteed for every failure. |
The output is best-effort decision support. Depending on the available evidence, it can include a category, explanation, affected step, related failure pattern, suggested fix, and—when source correlation is available—a candidate file or line. Review the evidence before changing a test or filing a product defect.
When you create a Jira or Azure DevOps defect, ContextQA pre-populates the fields supported by the connected tracker from the evidence it has, such as the test name, failing step, error, root-cause summary, screenshot or evidence link, and result URL. Review the draft and remove sensitive data before submitting it; missing evidence is not fabricated.
### Root cause categories
The AI classifies each failure into one of the following categories. The category tells you where the problem lies and who should act on it:
| Category | What it means |
| -------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Script Failure** | The automation script failed to execute as written — a locator, wait, or step in the test broke. Fix the step and re-run. |
| **Functional / Product Bug** | The application under test behaved incorrectly. A genuine product defect — report it to the development team. |
| **Test Data Issue** | Invalid, missing, or stale test data caused the failure. Update the test data and re-run. |
| **Environment / Infrastructure** | A network, server, or deployment problem caused the failure. Check the environment and retry. |
| **ContextQA Platform** | The failure originated in the ContextQA platform itself. Contact ContextQA support if it persists. |
| **Flaky / Intermittent** | A potentially unstable, non-deterministic failure. Confirm the pattern across comparable runs, then fix its cause rather than hiding it with unconditional retries. |
| **Configuration / Setup** | A misconfiguration or incomplete setup caused the failure. Review the test or application configuration and prerequisites. |
| **Dependency / Integration** | A failure in an external dependency or integration. Verify the dependent API or third-party service. |
| **Unclassified / Needs Review** | The failure couldn't be automatically categorized and requires manual review. |
### Debug mode for interactive diagnosis
ContextQA includes a **Debug** mode that lets you diagnose failures interactively as a test runs. When a step fails during a debug session, you are presented with options to handle it without stopping the run:
* **Enter more detail** — provide a plain-English instruction to clarify the step (e.g., "click on admin")
* **Update and Rerun** — modify the failing step and retry from that point
* **Add a New Step and Rerun** — insert a new step at the failure point and resume
* **Skip Step** — bypass the failed step and continue with the remaining steps
* **Delete Step** — remove the step from the test case entirely
This workflow is useful during test authoring and maintenance when you want to iterate on a test case in real time rather than running it repeatedly from scratch.
***
## Suggested fixes
{% hint style="info" %}
**Availability:** Suggested fixes require the **auto-fix** capability on your plan. When it's not enabled, the root cause report still shows the failure category and AI explanation, but the apply-fix actions described below don't appear. Contact your account team to enable it.
{% endhint %}
When the auto-fix capability is enabled, ContextQA does more than explain a failure — it proposes concrete changes to the test and lets you apply them without opening the step editor. This turns root cause analysis into a review-and-apply repair workflow for script-level failures.
Unlike [AI self-healing](#ai-self-healing-and-auto-healed-steps), which repairs locator drift automatically while a test runs, suggested fixes are proposed after a run fails and applied by you after review. A suggested fix can update a step, add a step, or remove a step — not only change a locator — and always requires a re-run to confirm the fix works.
### Opening the suggested fixes panel
On the execution result page for a failed run:
1. Select the **Failure analysis & suggested fixes** button at the top of the report. After a fix has been applied, this button is replaced by a green **Fix applied · See fix** button (or **Auto-fixed · See fix** when the fix was applied automatically) that reopens the same panel.
2. The **AI Debug** tab opens and scrolls to the **Root Cause Analysis** panel, which shows the failure category, the AI explanation, and the proposed fix for each affected step.
### Types of proposed change
Each proposed fix targets one step and falls into one of three change types:
| Change type | Panel label | What it does |
| ------------- | ------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Update a step | **Proposed change** | Modifies an existing step — for example, replaces a broken locator with a **Proposed locator** plus one or more **Fallback** locators, or updates a data value. |
| Add a step | **New step** | Inserts a new step at the failure point. |
| Remove a step | **Step removal** | Deletes a step that is no longer valid. |
Some proposed changes require a concrete value from you, such as the destination URL for a newly added navigation step. Enter the requested value in the fix panel before applying it. ContextQA writes that value into the action field the step uses instead of saving a placeholder; review the resulting step and re-run it as you would any other applied fix.
### Applying a fix
* **Apply fix** — applies the proposed change for a single step. Use this to review and apply changes one at a time.
* **Apply all fixes** — applies every not-yet-applied step in one operation. Steps that are already applied are skipped.
After a fix is applied, ContextQA confirms with **Step updated. Re-run the test to verify.** (or **Steps updated. Re-run the test to verify.** for multiple steps). The applied steps are marked as fixed and their **Apply fix** control is hidden. When every proposed step has been applied, the run is marked as fixed and the top-of-report button switches to **Fix applied · See fix**.
{% hint style="warning" %}
Applying a fix changes your test case immediately. Re-run the test afterward to confirm the change resolves the failure — applying a fix doesn't re-execute the test for you.
{% endhint %}
### Other actions in the panel
Beyond applying fixes, the panel lets you:
* **Jump to failed step** — scrolls to and highlights the failing step in the step list.
* **Re-run** — re-executes the test case to verify a fix.
* **Edit manually** — opens the test case in the [Test Steps Editor](/web-testing/test-steps-editor) so you can make the change yourself instead of applying the proposal.
* **Mark as bug** — creates a Jira bug from the failure when the root cause is a genuine product defect rather than a test issue. This requires a connected Jira integration; if none is configured, ContextQA prompts you to connect Jira from **Integrations & Plugins**. See [Jira Integration](/integrations/jira).
***
## AI self-healing and auto-healed steps
When the application UI changes in a way that breaks a locator, ContextQA's AI self-healing engine attempts to automatically identify the correct new element and update the step. If the accuracy score is above 90% and there is no functional change to the flow, the step is healed automatically.
Healed steps are marked with an **auto-healed** indicator in the execution report. This means the test passed using an updated locator — not the original one — so you should review the healed step and confirm the update is correct before relying on it long-term.
To approve or review auto-healing suggestions, use the `approve_auto_healing` MCP tool or navigate to the auto-healing review queue in the platform.
***
## Flaky test detection
A test is considered flaky when it produces inconsistent results across runs on the same code and the same environment. ContextQA tracks pass/fail history per test case and surfaces tests that show non-deterministic behavior.
Flaky tests appear in the **Consistently Failing** list on the Execution Dashboard, often alongside a root cause note indicating intermittent failures. Use the failure trend data — available on the test case detail view — to see how often a given test has failed over recent runs and whether the failures cluster around specific times, environments, or deployments.
Common flaky failure categories surfaced by ContextQA:
* **Timing issues** — a step executing before a page element has fully loaded
* **Network variability** — a step depending on an API response that is occasionally slow
* **Data state issues** — test data that is not reset between runs
***
## Failure trends
The **Consistently Failing** panel in the Execution Dashboard lists test cases ranked by failure frequency. Each card shows the test case name, the failure count, and the AI-identified root cause when available.
Use this list to prioritize maintenance work. Test cases that appear repeatedly with the same root cause are strong candidates for a locator update or a stability fix. Test cases with varied root causes may indicate genuine application instability rather than test fragility.
***
## Integrating failures with bug trackers
Once you identify a genuine application bug from a failing test, you can push it directly to your bug tracker without leaving ContextQA.
### Reporting to Jira
From the test result detail page:
1. Click the **JIRA** option in the failure reporting toolbar.
2. Select your Jira project and set the issue type to **Bug**.
3. Click **Save** — a Jira ticket is created and linked to the ContextQA result.
The Jira issue is pre-populated with the test description, reproduction steps, and the result page link. See [Jira Integration](/integrations/jira) for setup instructions.
You can also create defect tickets programmatically using the `create_defect_ticket` MCP tool:
```
create_defect_ticket(
execution_id="",
project_id=""
)
```
### Reporting to Azure DevOps
From the test result detail page:
1. Click **Report Bug** in the failure reporting toolbar.
2. Select **Azure Board** as the destination.
3. Choose the issue type (e.g., Bug, Test Case) and enter a title.
4. Click **Save** — ContextQA automatically adds the test description and reproduction steps to the work item.
A direct link to the Azure Boards ticket appears immediately after creation. See [Azure DevOps Integration](/integrations/azure-devops) for setup instructions.
{% hint style="info" %}
**Get release readiness reports your stakeholders understand.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the analytics dashboard, failure analysis, and flaky test detection for your test suite.
{% endhint %}
# How to Debug a Failing Test
A step-by-step workflow for diagnosing why a test failed using ContextQA's execution evidence — AI root cause analysis, screenshots, video, network logs, console logs, and Playwright traces.
## Quick answer
A step-by-step workflow for diagnosing why a test failed using ContextQA's execution evidence — AI root cause analysis, screenshots, video, network logs, console logs, and Playwright traces. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and developers who need to determine why a test failed and decide whether to fix the test, file a bug, or address a flaky environment issue.
{% endhint %}
When a test fails, the goal is to answer three questions as fast as possible:
1. **What** failed? — Which step, what error message?
2. **Why** did it fail? — Application bug, test bug, flaky timing, or environment issue?
3. **What do I do next?** — Fix the test, file a bug, or stabilize the environment?
ContextQA captures a full evidence package for every execution — AI root cause analysis, per-step screenshots, session video, network logs, console logs, and a Playwright trace. This guide walks you through a systematic workflow that uses each artifact to reach a diagnosis quickly.
## Prerequisites
* A ContextQA account with access to at least one workspace
* A failed test execution to investigate (any test case or test plan run with a **FAILED** status)
* Familiarity with [test results and reports](/reporting/test-results) — specifically how to navigate to the detailed report view
***
## Step 1: Open the failed execution report
1. Navigate to **Test Cases** in the left sidebar and click the failed test case, or navigate to **Plans → Test Plans** and click the failed plan run.
2. Click **View Detailed Report** in the execution summary banner.
3. The detailed report opens showing every step in sequence with pass/fail indicators.
Locate the first step with a red **X** indicator. This is the step where the failure occurred. All subsequent steps may also show failures, but the root cause is almost always in the first failing step.
***
## Step 2: Read the AI root cause analysis
Before inspecting any artifact manually, check what the AI has already determined.
1. Click the **AI Insights** button (or **Root Cause Analysis** button) at the top of the report.
2. Read the structured output:
| Field | What it tells you |
| -------------------- | ---------------------------------------------------------------------- |
| **Summary** | A plain-English explanation of what failed and why |
| **Failure category** | `Application Bug`, `Test Bug`, `Flaky Failure`, or `Environment Issue` |
| **Affected step** | The step number and action where the failure occurred |
| **Suggested fix** | A specific, actionable recommendation |
**If the AI classification is clear and the suggested fix is actionable**, you may have your answer. Proceed to [Step 7: Decide your next action](#step-7-decide-your-next-action).
**If you need more context** — the classification is `Flaky Failure` without a clear cause, or the summary is ambiguous — continue to Step 3 to inspect the evidence yourself.
***
## Step 3: Inspect the failing step screenshot
Click the failing step row to expand it. Click the screenshot thumbnail to open the full-size image.
**What to look for:**
* **Is the expected element visible on the page?** If the step tried to click a button that is not on the screen, the page may not have loaded fully or navigated to the wrong URL.
* **Is a dialog, overlay, or banner blocking the element?** Cookie consent banners, modal dialogs, and notification popups are common causes of "element not interactable" failures.
* **Does the page show an error state?** A 500 error page, a "session expired" message, or a form validation error visible in the screenshot tells you immediately whether this is an application issue.
* **Does the UI match what the test expects?** If the test expects a "Submit Order" button but the screenshot shows "Place Order", the UI label has changed and the test step needs updating.
> **Tip:** Compare the failing step screenshot with the screenshot from the previous step. The previous step shows the page state just before the failure, which is often more revealing than the failure screenshot itself.
***
## Step 4: Watch the video recording
If the screenshot does not make the cause obvious, watch the session video.
1. Click the **Video** tab at the top of the report.
2. Click the failing step in the step list — the video jumps to the moment that step began.
3. Watch the 10–15 seconds leading up to the failure.
**What to look for:**
* **Timing issues:** The page is still loading or an animation is still playing when the step executes. This points to a timing-related flaky failure.
* **Unexpected navigation:** The application redirected to a different page (login page, error page) before the step could execute.
* **Element movement:** A page element shifts position after rendering — the AI clicked where the button was, but it moved before the click landed.
* **Multi-step context:** Sometimes the failure at step 8 was actually caused by step 5 entering the wrong value. The video reveals this because you can see the full flow in sequence.
***
## Step 5: Check the network and console logs
If the visual evidence (screenshot and video) does not explain the failure, the cause may be in the application's back end or JavaScript layer.
### Network log
1. Click the **Network** tab in the report.
2. Filter by status code to show only **4xx** and **5xx** responses.
| What you find | What it means |
| ------------------------------------------------- | ------------------------------------------------------------------------------------------------------ |
| A `500 Internal Server Error` on an API call | The application server crashed — this is an application bug |
| A `401 Unauthorized` or `403 Forbidden` | The test session lost authentication — check if credentials expired or a token timed out |
| A `422 Unprocessable Entity` on a form submission | Server-side validation rejected the input — the test data may be invalid |
| A request that took more than 5 seconds | A slow API response may have caused a timeout in the UI step |
| A missing request (expected API call never made) | The UI interaction did not trigger the back-end call — the click or form fill may have failed silently |
### Console log
1. Click the **Console** tab in the report.
2. Look for red entries (errors).
| What you find | What it means |
| -------------------------------------------------- | ------------------------------------------------------------------------------------------------ |
| `Uncaught TypeError` or `Uncaught ReferenceError` | A JavaScript error broke the page logic — this is an application bug |
| `Failed to fetch` or `net::ERR_CONNECTION_REFUSED` | The application could not reach a dependency (API, CDN, database) — this is an environment issue |
| `[Violation] 'click' handler took 3,412ms` | A slow event handler may be causing the UI to appear unresponsive, leading to timeout failures |
***
## Step 6: Use the Playwright trace for deep inspection
When screenshots, video, and logs are not enough — typically for "element not found" failures where the element appears to be on the page — the Playwright trace provides the definitive answer.
1. Click **View Playwright Trace** in the report. The trace viewer opens at `trace.playwright.dev` in a new tab.
2. In the timeline panel (top), navigate to the failing action.
3. In the action detail panel (left), read the exact locator that was attempted and the error.
4. In the DOM panel (right), inspect the actual HTML structure at the moment the locator was tried.
**What to look for:**
* **The element exists but has a different attribute.** The locator targets `[data-testid="submit-btn"]` but the element now has `[data-testid="submit-button"]`. This is a test bug — update the locator or re-record the step.
* **The element exists but is hidden.** The DOM shows the element with `display: none` or `visibility: hidden`. The element has not rendered yet (timing issue) or is conditionally hidden (application behavior change).
* **The element is inside an iframe.** The locator searches the main document but the target element is in an embedded iframe. Add a step to switch to the iframe context.
* **Multiple elements match the locator.** The trace shows that the locator matched three elements, and the one ContextQA interacted with was not the intended target. Make the locator more specific.
> **Note:** ContextQA retains Playwright traces for 30 days after execution and screenshots and logs for 90 days. If you are investigating an older failure, the trace may no longer be available.
***
## Step 7: Decide your next action
Based on your investigation, take the appropriate action:
### Application bug
The test is correct, but the application behaved incorrectly.
1. Click the **Report Bug** button in the failure reporting toolbar.
2. Select your bug tracker project and issue type.
3. ContextQA pre-populates the ticket with the failure description, screenshot, and a link to the full report.
4. Click **Create Issue**.
5. The test case remains as-is — it will pass once the application bug is fixed.
### Test bug
The test steps need updating because the application changed intentionally.
1. Open the test case in the **Test Steps Editor**.
2. Update the failing step — change the locator, update expected text, or add a missing step.
3. Re-run the test case to verify the fix.
4. If the test uses a step group, update the step group instead so the fix propagates to all test cases that use it. See [Step groups tutorial](/web-testing/step-groups-tutorial).
> **Tip:** If your plan includes the auto-fix capability, ContextQA can propose the step change for you and apply it with one click. Select **Failure analysis & suggested fixes** on the report to review and apply the proposed fix, then re-run. See [Suggested fixes](/reporting/failure-analysis#suggested-fixes).
### Flaky failure
The test fails intermittently due to timing or environment variability.
1. **Add an explicit wait step** before the failing step. In the step editor, add a **Wait** action that waits for the target element to be visible or for a network request to complete.
2. **Re-run the test three to five times** to confirm the fix eliminates the intermittent failure.
3. If the failure persists, consider whether the application under test has a genuine performance issue that needs addressing.
### Environment issue
The test environment is misconfigured or unavailable.
1. Verify the environment is running and accessible at the configured base URL. Open the URL in a browser to confirm.
2. Check **Environment & Data → Environments** in the left sidebar to confirm the environment configuration is correct.
3. If the issue is intermittent network connectivity, re-run the test. If it persists, check firewall rules, VPN configuration, or IP allowlisting.
***
## Using debug mode for interactive diagnosis
For failures that are difficult to diagnose from the execution report alone, re-run the test in **Debug** mode to interact with it in real time.
1. Open the test case.
2. Click **Debug** (instead of **Run**).
3. Watch the test execute step by step. When a step fails, ContextQA pauses and presents options:
| Option | When to use it |
| ---------------------------- | ------------------------------------------------------------------------------------------------------------------ |
| **Enter more detail** | The step description is ambiguous — provide a clarification (e.g., "click the admin dropdown, not the admin link") |
| **Update and Rerun** | You know the fix — edit the step and retry from that point |
| **Add a New Step and Rerun** | A missing step caused the failure — insert a wait, a click, or a navigation step |
| **Skip Step** | The step is not critical and you want to test the remaining flow |
| **Delete Step** | The step is obsolete and should be removed from the test case |
Debug mode is the fastest way to iterate on a failing test without re-running the entire sequence from scratch.
***
## Quick reference: debugging decision tree
```
Test failed
│
├── Read AI root cause analysis (Step 2)
│ ├── Classification is clear → Act on it (Step 7)
│ └── Need more context → Continue
│
├── Check the failing step screenshot (Step 3)
│ ├── Element missing or blocked → Likely test bug or timing issue
│ ├── Error page visible → Likely application bug
│ └── Page looks correct → Continue
│
├── Watch the video (Step 4)
│ ├── Timing/animation issue visible → Add wait step (flaky fix)
│ ├── Unexpected redirect → Check auth or navigation logic
│ └── Nothing obvious → Continue
│
├── Check network and console logs (Step 5)
│ ├── 5xx error → Application bug
│ ├── 4xx error → Auth or data issue
│ ├── JavaScript error → Application bug
│ └── No errors → Continue
│
└── Inspect the Playwright trace (Step 6)
├── Locator mismatch → Update the test step
├── Element hidden → Timing issue or conditional logic
└── Element in iframe → Add iframe context step
```
***
## Related pages
* [Test results and reports](/reporting/test-results) — reference for the detailed report view and all evidence artifacts
* [Failure analysis](/reporting/failure-analysis) — reference for AI root cause analysis, self-healing, and bug tracker integration
* [Flaky test detection](/reporting/flaky-test-detection) — reference for failure classification and flaky test management
* [Video and screenshots](/execution/video-and-screenshots) — reference for evidence capture configuration and retention
* [Test steps editor](/web-testing/test-steps-editor) — reference for editing test steps
* [AI self-healing](/web-testing/self-healing) — reference for auto-healed steps and locator updates
{% hint style="info" %}
**Diagnose failures in seconds, not hours.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI root cause analysis and the full evidence package with your application.
{% endhint %}
# Flaky Test Detection
Flaky test detection in ContextQA — AI-powered failure classification identifies intermittent failures and separates them from real application bugs.
## Quick answer
Flaky test detection in ContextQA — AI-powered failure classification identifies intermittent failures and separates them from real application bugs. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers and engineering managers who need to separate intermittent test noise from real regressions — so failures that matter get attention and flaky tests don't block deployments.
{% endhint %}
> **Flaky test:** A test case that produces inconsistent results — passing on some executions and failing on others — without any change to the application code or test definition, typically caused by timing issues, environment variability, or non-deterministic UI behavior.
Flaky tests are the primary reason development teams lose confidence in automated test suites. When every pipeline failure requires human triage to determine whether it is a real regression or noise, velocity drops and eventually the suite is ignored. ContextQA addresses this by classifying every failure with an AI-derived root cause category, making flakiness visible as a distinct failure type rather than an undifferentiated red status.
## What is a flaky test?
A flaky test passes on some runs and fails on others under conditions that have not changed — same code, same environment, same test definition. Common causes include:
* **Timing dependencies:** The test clicks a button before an async operation completes.
* **Order dependence:** The test relies on state left by a previous test case that sometimes runs in a different order.
* **Environment variability:** Network latency spikes, DNS resolution delays, or shared database contention.
* **Non-deterministic UI:** Animations, lazy-loaded components, or third-party widgets that render at unpredictable times.
ContextQA surfaces flakiness as a failure category distinct from an application bug. Treat a single-run AI classification as a triage hypothesis: confirm it with comparable execution history and the captured evidence. A real regression can also be intermittent, and a test problem can fail consistently.
## How ContextQA classifies failures
ContextQA uses AI root cause analysis on every failed test case. The analysis pipeline examines:
* The failing step and the error message
* The browser console log for JavaScript errors
* The HAR network log for failed or slow requests
* The DOM state at the time of failure (from the Playwright trace)
* Historical execution data for the same test case
From this data, ContextQA assigns one of four failure categories:
| Category | Meaning |
| --------------------- | ---------------------------------------------------------------------------------------------- |
| **Application Bug** | The application behaved incorrectly; the test is functioning as designed |
| **Test Bug** | The test definition has an error — incorrect selector, wrong expected value, missing wait |
| **Flaky Failure** | The failure is intermittent; root cause is timing, environment variability, or non-determinism |
| **Environment Issue** | Infrastructure-level failure — network timeout, missing credential, environment not responding |
The AI explanation accompanying each classification states specifically what evidence led to the classification. For a flaky failure, the explanation typically notes that the test has both passed and failed on identical code, and identifies the specific step and condition that is non-deterministic.
## Accessing flaky test data in the Analytics Dashboard
1. Open **Analytics** in the left navigation.
2. Click the **Execution Dashboard** tab.
3. Locate the **Consistently Failing Tests** widget. This widget lists test cases with repeated failures across recent runs, ranked by failure frequency.
4. Click any test case in the widget to open the failure detail panel.
5. The detail panel shows the failure category distribution (how many runs were classified as flaky vs. application bug vs. other) and the AI explanation for each failure type.
The **Consistently Failing Tests** widget surfaces test cases that failed in multiple consecutive runs. ContextQA distinguishes between cases that always fail (likely an application bug or test bug) and cases that alternate between passing and failing (likely flaky). The visual indicator for flakiness is a mixed pass/fail run history in the sparkline column.
For a broader view, the **Failure Analysis** report (accessed from **Analytics → Failure Analysis**) shows aggregate failure categories across an entire test suite or date range, allowing you to measure what percentage of your failures are flaky versus genuine regressions.
## Using the get\_root\_cause MCP tool
The `get_root_cause` MCP tool returns the AI failure classification for a specific execution programmatically. The response includes:
* `errorType`: one of `APPLICATION_BUG`, `TEST_BUG`, `FLAKY_FAILURE`, `ENVIRONMENT_ISSUE`
* `rootCause`: the AI's natural-language explanation of the root cause
* `fixSuggestion`: a concrete suggestion for resolving the failure
* `affectedStep`: the step number and action that failed
When building CI integrations that need to distinguish "block the release" from "likely noise," use the `errorType` field from `get_root_cause` to gate your pipeline logic. A pipeline that fails the build on `APPLICATION_BUG` but creates a Jira ticket and continues on `FLAKY_FAILURE` is a common pattern for teams managing large suites.
Example MCP invocation pattern:
```
get_root_cause(execution_id="")
→ { errorType: "FLAKY_FAILURE", rootCause: "...", fixSuggestion: "Add an explicit wait for the modal animation to complete before asserting." }
```
## What to do when a test is classified as flaky
ContextQA classifies the failure; resolving it requires one of three approaches depending on the root cause:
**1. Fix timing issues.** If the AI reasoning log identifies a race condition (for example, clicking an element before it is interactable), add an explicit wait step in the test case. In ContextQA's step editor, add a **Wait** action before the problematic step. The appropriate wait target is either a specific element becoming visible or a network request completing.
**2. Preserve the full plan result.** ContextQA test plans support a recovery action for failed test cases. In **Test Plans → \[Plan] → Settings**, `Run_Next_Testcase` records the failed case and continues with the remaining cases instead of halting the plan. This is continuation behavior, not a retry of the failed case. Use the completed plan result to compare failures without changing their evidence.
**3. Isolate environment dependencies.** If ContextQA consistently classifies failures as `ENVIRONMENT_ISSUE` for a specific test case, the test may be hitting a dependency that is unreliable in your staging environment. Use a dedicated test environment or mock the external dependency.
## Retry configuration and the recovery action
The **Recovery Action** in test plan settings controls what ContextQA does when a test case fails mid-plan:
| Recovery Action | Behavior |
| ------------------- | ----------------------------------------------------------- |
| `Stop` | Halt plan execution immediately on first failure |
| `Run_Next_Testcase` | Mark the failed case and continue executing remaining cases |
`Run_Next_Testcase` lets a plan complete so you can review every case outcome. It does not rerun, convert, or suppress a failure. After the run, compare the failure category and evidence with prior executions before deciding whether to rerun anything.
## Frequently Asked Questions
### How many runs does ContextQA need before it can identify a flaky test?
Root-cause analysis can return a provisional `FLAKY_FAILURE` classification from one run when the available evidence suggests timing or environment variability. Confirm flakiness across comparable runs before changing release policy or suppressing an alert. Historical widgets require repeat executions to show a pattern.
### Does ContextQA automatically retry flaky tests?
ContextQA does not automatically retry an individual failed case within the same execution. `Run_Next_Testcase` continues the plan; it does not retry. If your team chooses to rerun a case or plan, preserve the original failure, define a small retry limit, and report both attempts so a passing retry cannot hide the first failure.
### Can I mark a test case as "known flaky" to suppress notifications?
There is no explicit "known flaky" flag on test cases in the current UI. The recommended approach is to use the failure category data from `get_root_cause` in your CI integration to suppress notifications for `FLAKY_FAILURE` classifications while still alerting on `APPLICATION_BUG`.
## Related
* [Failure analysis report](/reporting/failure-analysis)
* [Analytics dashboard](/reporting/analytics-dashboard)
* [Test results](/reporting/test-results)
* [Video recording and screenshots](/execution/video-and-screenshots)
* [Exporting reports](/reporting/exporting-reports)
{% hint style="info" %}
**Get release readiness reports your stakeholders understand.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the analytics dashboard, failure analysis, and flaky test detection for your test suite.
{% endhint %}
# Exporting Reports
Test report export from ContextQA — share execution URLs, download evidence packages, export Playwright code, and embed results in Jira and Slack notifications.
## Quick answer
Test report export from ContextQA — share execution URLs, download evidence packages, export Playwright code, and embed results in Jira and Slack notifications. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers, engineering managers, and VPs who need to share test results with stakeholders, create defect tickets with embedded evidence, or archive execution records for compliance.
{% endhint %}
> **Test report export:** The set of mechanisms ContextQA provides to share, download, and embed test execution results outside the portal — including shareable URLs, downloadable artifact packages, Playwright TypeScript code generation, and defect ticket creation with embedded evidence.
Test results only create value when the right people can see them. A QA lead needs to share a failure with a developer, a release manager needs to verify a suite passed before deploying, and a compliance auditor needs a portable record of what was tested. ContextQA provides several export paths for each of these use cases. This page covers all of them.
## Sharing execution reports via URL
Every execution report in ContextQA has a permanent URL that can be shared with any user who has portal access. To obtain the link:
1. Navigate to **Test Plans** → select the plan → **Executions** tab.
2. Click the execution run you want to share.
3. Copy the URL from your browser's address bar. The URL includes the execution ID and resolves directly to the execution report.
Paste this URL into a Slack message, a Jira comment, a pull request description, or an email. The recipient clicks the link and lands on the full execution report, including all test case results, failure categories, and artifact tabs. You don't need to generate a separate shareable link — the execution report URL is the shareable link.
Recipients who are not signed in must authenticate using a login method enabled for the target ContextQA organization before reaching the report. Plan accordingly when sharing links with stakeholders who do not have portal access.
## Downloading the evidence package
Each test case execution produces a complete evidence package: per-step screenshots (JPG), session video (WebM), network HAR, browser console log, and Playwright trace (ZIP). To download any of these:
1. Open the execution report for the target run.
2. Select a test case row to expand the step-level detail panel.
3. Use the artifact tabs — **Video**, **Network**, **Console**, **Trace**, **AI Reasoning** — at the top of the detail panel.
4. Click the download icon on any tab to download the artifact directly.
Downloaded artifacts are raw files: `.webm` for video, `.har` for network data, `.zip` for the Playwright trace, `.txt` for console logs. These files can be archived, attached to tickets, or loaded into external analysis tools.
**S3 URL expiry:** Artifact download URLs are pre-signed S3 URLs that expire after 1 hour. If you open an artifact tab and do not click download immediately, the URL may expire before the download starts. Navigate away and back to the execution report to generate a fresh URL.
## Using the Playwright trace as a portable audit artifact
The Playwright trace ZIP is the most complete portable artifact ContextQA produces. It contains DOM snapshots, network waterfall, console timeline, and interleaved screenshots for every step. Critically, it requires no ContextQA account to view.
To use it as a portable audit artifact:
1. Download the trace ZIP from the **Trace** artifact tab.
2. Open [trace.playwright.dev](https://trace.playwright.dev) in any browser.
3. Upload the ZIP file using the drag-and-drop interface or the **Upload** button.
The viewer is a static web application — it works entirely in the browser with no server communication. This makes the trace ZIP a self-contained compliance record. You can attach it to a Jira epic as an audit trail, store it in a compliance evidence repository, or share it with a client who has no access to your ContextQA instance.
## Exporting test case definitions as Playwright code
ContextQA test cases can be exported as executable Playwright TypeScript code. This enables two workflows: migrating test cases to a code-based repository, and running ContextQA-authored tests in a self-hosted Playwright runner outside ContextQA infrastructure.
**Via MCP tools:**
The `export_test_case_as_code` tool exports a single test case:
```
export_test_case_as_code(
test_case_id=55,
framework_type="playwright",
language="typescript",
destination_path="./tests/generated"
)
→ Returns: TypeScript Playwright test file content
```
The `export_to_playwright` tool exports test cases as a structured Playwright project:
```
export_to_playwright(output_dir="./tests", project_name="my-tests", test_case_ids=[10, 11, 12])
→ Returns: A complete Playwright TypeScript project with page objects and test files
```
Both tools produce standard Playwright TypeScript that can be added to a `tests/` directory and executed with `npx playwright test`. The exported code uses the same selectors ContextQA uses internally, including any AI-optimized selectors generated during execution.
## Embedding result links in Jira and Slack
ContextQA's Jira and Slack integrations automatically post execution result links as part of their notification payloads. The result URL embedded in these notifications points directly to the execution report.
**Jira:** When you configure the Jira integration, a test plan completion can automatically create or update a Jira issue with the execution result. The issue body includes a direct link to the execution report.
**Slack:** The Slack integration posts a result message to the configured channel. The message includes the plan name, pass/fail counts, and a link to the execution report. Users can click the link directly from Slack without navigating through the ContextQA portal.
If you want to manually embed a result link — for example, in a pull request comment — use the execution report URL from the portal (see the sharing section above) and paste it directly.
## Creating defect tickets with embedded evidence
When a test case fails, ContextQA can create a defect ticket directly in Jira (or other connected issue trackers) via the `create_defect_ticket` MCP tool. The created ticket automatically includes:
* The test case name and the failing step number
* The error message from the failing step
* A screenshot of the failing step (as an attachment or inline image, depending on Jira configuration)
* A direct link to the full execution report in the ContextQA portal
* The AI-generated root cause classification and fix suggestion
To create a defect ticket manually from the portal:
1. Open the execution report and navigate to the failing test case.
2. Click the **Create Defect** button on the failing step row.
3. ContextQA opens a pre-populated ticket creation dialog with the evidence fields already filled in.
4. Review the fields, select the target Jira project, and click **Create**.
The defect ticket provides enough context for a developer to investigate the failure without needing portal access — the screenshot and error message are attached, and the execution report link provides the full trace for deeper analysis.
## Frequently asked questions
### Can I export a full test plan result as a PDF or CSV?
ContextQA does not currently produce a PDF or CSV export of a complete execution result from the portal UI. The recommended approach for compliance or management reporting is to share the authenticated execution report URL or download the available artifacts. If you need structured data, the `get_test_case_results` and `get_test_step_results` MCP tools return JSON that can be transformed into an organization-approved format.
This is different from **Execution history → Export CSV**. That control exports the active test-case matrix or plan-summary view for the selected plan and recent-run limit; it does not export the complete run report, screenshots, video, logs, or traces. See [Execution history](/reporting/execution-history#exporting-to-csv).
### Are exported Playwright test files immediately runnable?
Yes, with the caveat that they require a valid `playwright.config.ts` and the `@playwright/test` package installed. The `export_to_playwright` tool produces a complete project structure including a basic config. You may need to configure `baseURL` and authentication setup in the config to match your target environment.
### How long does ContextQA store execution reports?
ContextQA retains execution reports and their associated artifacts according to your organization's storage policy, which you can configure in **Settings → Organization Settings**. The reports themselves (metadata, pass/fail results, step data) persist independently of artifact storage and may be available for longer periods than the raw artifact files.
### Can I share an execution report with someone outside my organization?
Currently, execution report URLs require portal authentication. To share results with external stakeholders, download the relevant artifacts (trace ZIP, screenshots) and share the files directly, or export the test case as a Playwright code file and share that.
## Related
* [Video recording and screenshots](/execution/video-and-screenshots)
* [Failure analysis report](/reporting/failure-analysis)
* [Flaky test detection](/reporting/flaky-test-detection)
* [Jira integration](/integrations/jira)
* [Slack integration](/integrations/slack)
* [MCP server tool reference](/mcp-server/overview)
{% hint style="info" %}
**Get release readiness reports your stakeholders understand.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the analytics dashboard, failure analysis, and flaky test detection for your test suite.
{% endhint %}
# Interactive Demo
Explore the ContextQA Reporting & Analytics dashboard — track pass rates, detect flaky tests, classify failures by root cause, and share results with stakeholders.
## Quick answer
Explore the ContextQA Reporting & Analytics dashboard — track pass rates, detect flaky tests, classify failures by root cause, and share results with stakeholders. Use this page to preview the workflow and its visible results before following the linked written instructions.
## What this page covers
The ContextQA analytics dashboard gives teams a real-time view of test health across every execution. This demo walks through the key panels: KPI summary, daily pass rate trends, AI failure classification, and flaky test detection.
{% tabs %}
{% tab title="Last 7 Days" %}
{% stepper %}
{% step %}
### KPI Summary
The top row shows the four most important health metrics for the selected time period at a glance.
| Metric | Value | Trend |
| ---------------- | --------- | ------------------------- |
| Pass Rate | **94.2%** | ↑ 2.1% vs last week |
| Total Executions | **847** | ↑ 18% vs last week |
| Failures | **49** | ↓ 12 fewer than last week |
| Flaky Tests | **7** | ↑ 2 new this week |
{% hint style="info" %}
**AI Agent:** KPIs update in real time after every execution. Pass rate, failure count, and flaky test count are all computed automatically — no manual tagging required.
{% endhint %}
{% endstep %}
{% step %}
### Daily Pass Rate Chart
The bar chart shows passed, failed, and self-healed test counts for each day in the period.
**7-day breakdown (passed / failed / healed):**
* Monday: 98 / 5 / 2
* Tuesday: 112 / 8 / 3
* Wednesday: 89 / 12 / 1
* Thursday: 134 / 6 / 4
* Friday: 156 / 9 / 2
* Saturday: 78 / 3 / 1
* Sunday: 180 / 6 / 2
{% hint style="info" %}
**AI Agent:** "Healed" counts are tests that failed on first attempt but passed after self-healing — these are tracked separately from clean passes so teams can monitor UI churn over time.
{% endhint %}
{% endstep %}
{% step %}
### AI Failure Classification
Every failure is automatically classified by the AI into one of four categories — no engineer investigation needed to triage.
| Classification | Count | Share |
| ----------------- | ----- | ----- |
| Application Bug | 25 | 51% |
| Flaky Failure | 14 | 29% |
| Test Bug | 7 | 14% |
| Environment Issue | 3 | 6% |
{% hint style="info" %}
**AI Agent:** AI classifies failures from the evidence available to the run. Treat the category as a triage recommendation and confirm it against the failed step, logs, and comparable run history before assigning ownership.
{% endhint %}
{% endstep %}
{% step %}
### Flaky Test Detection ✓
ContextQA identifies tests that pass inconsistently across runs and surfaces them in a dedicated list with their flakiness rate and likely cause.
**Top flaky tests this week:**
| Test | Flakiness | Likely Cause |
| ------------------------------ | --------- | -------------- |
| Checkout — credit card payment | 30% | Timing issue |
| Search — autocomplete results | 20% | Race condition |
| Upload — large file (>10MB) | 10% | Timeout |
| Email notification delivery | 10% | Async timing |
{% hint style="success" %}
**AI Agent:** Flaky tests are flagged automatically based on pass/fail variance across recent runs. Teams can prioritize stabilization work based on flakiness rate without manually comparing run histories.
**Filter options available:** Last 7 days · Last 30 days · Last 90 days · Current Sprint
{% endhint %}
| Capability | Detail |
| ---------------------- | -------------------------------------------------------------------------------------------------------- |
| Failure Classification | Automatic — no manual tagging |
| Flaky Test Detection | Based on run variance across history |
| Shareable Reports | Authenticated execution URL or downloadable evidence artifacts |
| Stakeholder View | Portal access is required for an execution URL; a downloaded Playwright trace can be reviewed separately |
| {% endstep %} | |
| {% endstepper %} | |
| {% endtab %} | |
{% tab title="30 Days" %}
{% stepper %}
{% step %}
### Extended Trend View
Switch to the 30-day view for a broader picture of test health trends, regressions introduced by specific releases, and flaky test evolution over time.
{% hint style="info" %}
**AI Agent:** The 30-day view aggregates the same metrics but highlights week-over-week patterns — useful for identifying which sprint introduced a regression or which area of the application has the most test churn.
{% endhint %}
{% endstep %}
{% step %}
### Suite-Level Breakdown
Drill into pass rates by test suite to identify which feature areas are most stable and which need attention.
{% hint style="info" %}
**AI Agent:** Suite-level filtering is available for all chart views — select a suite from the filter row to scope all KPIs and charts to that subset of tests.
{% endhint %}
{% endstep %}
{% step %}
### Export & Share ✓
Share the execution URL with stakeholders who have access to the organization, or download the evidence artifacts that are available for the run. ContextQA does not currently generate a general PDF export or an unauthenticated public execution link.
{% hint style="success" %}
**AI Agent:** For a portable technical record, download the Playwright trace and open it in the Playwright trace viewer. For a spreadsheet summary, use **Execution history → Export CSV**; that CSV covers the active history view rather than the complete run report.
{% endhint %}
{% endstep %}
{% endstepper %}
{% endtab %}
{% endtabs %}
***
{% hint style="success" %}
**See ContextQA with your own workflow** — [Book a Demo →](https://contextqa.com/book-a-demo/)
{% endhint %}
## Related documentation
[Reporting overview](/reporting/reporting) · [Review execution and test results](/reporting/test-results)
# AI Features Overview
Overview of ContextQA AI for test generation, PR impact analysis, autonomous execution, self-healing, knowledge, custom agents, and context graphs.
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who want to leverage AI to generate tests faster, execute them autonomously, and reduce maintenance through self-healing and intelligent context awareness.
{% endhint %}
ContextQA embeds AI across the entire testing lifecycle — from generating test cases out of requirements to executing them autonomously in real browsers to healing them when the UI changes. Rather than bolting AI onto an existing tool, ContextQA treats the AI agent as the primary test executor: it reads your instructions, navigates your application, captures evidence, and reports results.
## Quick answer
ContextQA applies AI to test generation, execution, application context, user-activity analysis, failure diagnosis, and routine web element repair. A tester provides intent or a supported source, reviews the generated coverage, and retains control over what becomes a shared test or release gate. AI accelerates the workflow; it does not remove the need to validate requirements, sensitive inputs, and unexpected product failures.
***
## What AI brings to your testing workflow
**Faster test creation.** Generate complete test cases from Jira tickets, URLs, Figma designs, OpenAPI specs, video recordings, plain text descriptions, code changes, and more — over ten supported sources. Instead of manually scripting every step, describe what you want to test and let the AI produce the steps.
**Autonomous execution.** The AI agent runs a nine-stage pipeline for every test: planning the approach, navigating the application, interacting with elements, capturing evidence, and self-healing when something changes. Each stage operates independently so failures are isolated and recoverable.
**Application awareness.** The Knowledge Base and Context Graph give the AI agent deep understanding of your application — login flows, navigation patterns, MFA handling, and inter-page relationships. This context reduces false failures and makes the agent behave more like an experienced team member who already knows the product.
**Domain specialization.** Custom Agents let you encode domain-specific testing logic — Salesforce validation rules, healthcare compliance checks, financial calculation verification — into reusable AI instructions that apply across test cases.
**Change-aware regression scope.** PR Impact Analysis maps a GitHub pull request to affected tests and explains each recommendation with confidence and code-change evidence before a reviewer selects what to run.
***
## In this section
| Page | What it covers |
| ---------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [AI Assistant](/ai-features/ai-assistant) | Using the in-app AI Assistant to navigate the platform, generate test cases from natural language, and get contextual help during execution |
| [AI Test Generation](/ai-features/ai-test-generation) | Generating test cases from 10+ sources: Jira tickets, URLs, Figma designs, OpenAPI specs, video recordings, plain text, code changes |
| [AI Insights](/ai-features/ai-insights) | Analyzing real user sessions to discover the activities users take, surface console errors, track coverage across runs, and generate tests for uncovered activities |
| [Generate Requirements from a Crawl](/ai-features/crawl-requirements) | Having an AI agent crawl your live application to build test cases — from an AI Insights activity or from a new requirement — and reading the crawl requirement it produces |
| [PR Impact Analysis](/ai-features/pr-impact-analysis) | Mapping GitHub pull-request changes to affected tests with confidence, provenance, and reviewable evidence |
| [Tutorial: Generate Tests from Requirements](/ai-features/generate-tests-from-requirements-tutorial) | A hands-on walkthrough: turn a requirements document into a reviewed, runnable test suite with traceability back to each requirement |
| [Autonomous Agent Pipeline](/ai-features/autonomous-agent-pipeline) | The nine-stage AI pipeline that plans, navigates, interacts, captures evidence, and self-heals during execution |
| [Knowledge Base](/ai-features/knowledge-base) | Uploading application context (login flows, navigation patterns, MFA handling) that the AI agent uses during test runs |
| [Custom Agents](/ai-features/custom-agents) | Creating specialized AI agents with domain-specific instructions for complex testing scenarios |
| [AI Context Graph](/ai-features/context-graph) | The AI-powered context graph that maps relationships across your application for smarter test planning |
| [Interactive Demo](/ai-features/demo) | Hands-on demo of ContextQA's AI capabilities |
***
## How AI fits into the platform
1. **Generate** — Create test cases from requirements, designs, or existing application pages using [AI Test Generation](/ai-features/ai-test-generation).
2. **Enrich** — Add application context through the [Knowledge Base](/ai-features/knowledge-base) and [Context Graph](/ai-features/context-graph) so the AI agent understands your product.
3. **Specialize** — Build [Custom Agents](/ai-features/custom-agents) for domain-specific testing logic that applies across your suite.
4. **Execute** — The [Autonomous Agent Pipeline](/ai-features/autonomous-agent-pipeline) runs your tests with planning, navigation, interaction, evidence capture, and self-healing built in.
5. **Heal** — When UI elements change between releases, [AI Self-Healing](/web-testing/self-healing) finds the equivalent new element and continues the test without manual intervention.
6. **Prioritize** — Use [PR Impact Analysis](/ai-features/pr-impact-analysis) to focus regression review on tests related to the current code change.
***
## Related pages
* [Core Concepts](/getting-started/core-concepts) — foundational platform concepts including how ContextQA's AI engine works
* [AI Self-Healing](/web-testing/self-healing) — detailed guide to self-healing behavior during web test execution
* [MCP Server](/mcp-server/overview) — programmatic access to AI features through the Model Context Protocol server
{% hint style="info" %}
**Generate tests from Jira tickets, Figma, and more — in minutes** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# AI Assistant
Use the AI Assistant to navigate the ContextQA platform, generate test cases from natural language descriptions, and get contextual help during test execution.
## Quick answer
Use the AI Assistant to navigate the ContextQA platform, generate test cases from natural language descriptions, and get contextual help during test execution. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — testers, SDETs, developers, and QA managers — who want a guided way to navigate the platform, generate test cases with AI, and get contextual help while working.
{% endhint %}
The AI Assistant is an in-app guide that helps you work faster in ContextQA. It has two capabilities:
* **Navigate** — a guided, menu-driven conversation that walks you through test creation, execution, and results analysis step by step.
* **Test Case Generation** — a chat interface where you describe a feature in plain English and the AI produces a complete, ready-to-execute test case.
You can open the AI Assistant from any page in the platform.
***
## How to open the AI Assistant
You can access the AI Assistant in two ways:
1. **Floating button** — Click the ContextQA logo button at the bottom-right corner of any page. The assistant opens as a side panel on the right.
2. **Full-screen mode** — Navigate to the **AI Assistant** page from the left sidebar. This opens the assistant in a dedicated full-screen view.
The assistant remembers your conversation as you move between pages. Click the **Restart** button (refresh icon) in the header to start a new conversation.
***
## Navigate tab
The **Navigate** tab provides a three-step guided workflow that walks you through the core testing lifecycle.
### Step 1: Test creation and organization
Select **Step 1: Test Creation & Organization** to access options for building and organizing your test suite:
| Option | What it does |
| --------------------------- | ----------------------------------------------------------------------------------- |
| **Create a Test Case** | Choose between three creation methods: AI-generated, recorded, or manual steps |
| **Arrange Your Test Suite** | Opens the **Test Suites** page where you can group and organize test cases |
| **Integrations** | Opens the **Plugins** settings page to connect external tools (Jira, Slack, GitHub) |
When you select **Create a Test Case**, the assistant asks you to choose a method:
* **AI-Generated Test** — Opens the AI test creation dialog where you describe what to test and the AI generates all the steps. See [AI Test Generation](/ai-features/ai-test-generation) for details on AI Smartness modes and advanced settings.
* **Record a Test** — Opens the test creation dialog in recording mode so you can capture browser interactions.
* **Manual Test Steps** — Opens the test case editor where you define each step yourself.
### Step 2: Test execution and optimization
Select **Step 2: Test Execution & Optimization** to run tests and apply best practices. All three options in this step ask you to search for and select a test case first:
1. Type a test case name in the search field.
2. Select the test case from the autocomplete results.
3. The assistant navigates to that test case and presents follow-up options.
**Execute Tests** options:
| Option | What it does |
| ------------------------------------------------------ | -------------------------------------------------- |
| **Single Run (Default Chrome browser)** | Opens documentation for running a single test case |
| **Parallel Execution (Faster run time)** | Opens documentation for parallel test execution |
| **Cross-Browser Execution (Run on multiple browsers)** | Opens documentation for cross-browser testing |
**Apply Best Practices** options:
| Option | What it does |
| -------------------------------------------------- | ----------------------------------------------------- |
| **Step Groups (Organize test steps)** | Opens documentation for creating reusable step groups |
| **Data-Driven Testing (Run with multiple inputs)** | Opens documentation for parameterized test runs |
| **Parameterization (Use dynamic variables)** | Opens documentation for using variables in test steps |
**Advanced Testing Options:**
| Option | What it does |
| ------------------------- | --------------------------------------------- |
| **Performance Testing** | Opens documentation for performance testing |
| **Accessibility Testing** | Opens documentation for accessibility testing |
### Step 3: Results and analysis
Select **Step 3: Results & Analysis** to review outcomes and get help:
| Option | What it does |
| -------------------------- | ----------------------------------------------------------- |
| **View & Analyze Results** | View reports, re-run tests, or optimize with best practices |
| **Insights & Reports** | View test insights or filter to failed test cases |
| **AI Assistance & Help** | Access interactive tutorials and step-by-step documentation |
### Navigation controls
* Click **Go Back** (arrow icon) at any point to return to the previous menu.
* Click the **Restart** button in the header to return to the main menu and start a new conversation.
***
## Test Case Generation tab
The **Test Case Generation** tab lets you describe a feature in plain English and receive a complete test case with steps, actions, and assertions.
{% hint style="info" %}
This feature requires an active license with AI Test Case Assistant enabled. If you see a locked icon on this tab, contact your administrator or [book a demo](https://contextqa.com/book-a-demo/) to enable it.
{% endhint %}
### Generate a test case from a description
1. Click the **Test Case Generation** tab (flask icon) at the top of the assistant.
2. Type a feature description in the text area. Describe the user journey you want to test.
3. Click **Generate Test Cases** (or press **Enter**).
4. Wait for the AI to process your request — a thinking animation appears while it works.
5. Review the generated test case. The assistant displays the test case name and a numbered list of steps.
6. Click **Create Test Case** to save it to your test library. The new test case opens in a new browser tab, ready for execution.
### Writing effective descriptions
The AI works best when you provide a clear, specific user journey. Include:
* The **starting page** or URL
* The **actions** a user takes (click, type, navigate, select)
* The **expected outcome** or verification point
**Practical examples:**
```
Log in to the dashboard as admin@example.com, navigate to the
Settings page, change the notification preference to "Email only",
save the changes, and verify the success message appears.
```
```
Open the product catalog, filter by category "Electronics",
sort by price low to high, add the first item to the cart,
and verify the cart badge shows 1 item.
```
### Edit generated steps
After the AI generates a test case, you can edit individual step names by clicking the pencil icon next to any step. This lets you refine the test case before saving it.
***
## Contextual actions during execution
When you are on a test case steps page, the assistant automatically offers contextual actions:
| Context | Actions available |
| --------------------------- | ------------------------------------------------------------------------------------- |
| Viewing a test case | **Show Me Previous Run History**, **Apply Testing Best Practices** |
| After starting an execution | **Close This And Take Me To The Dashboard**, **Show Me Result**, **Help Me To Debug** |
| Viewing run results | **Show Me Report** |
These actions appear automatically based on where you are in the platform — you do not need to navigate the menu to find them.
***
## Summary
The AI Assistant provides two ways to work faster in ContextQA:
* Use the **Navigate** tab for guided, step-by-step access to test creation, execution, and results analysis.
* Use the **Test Case Generation** tab to describe features in plain English and produce complete test cases instantly.
* Take advantage of **contextual actions** that appear automatically based on your current workflow.
***
## Related pages
* [AI Test Generation](/ai-features/ai-test-generation) — generate test cases from 10+ source types including natural language, Jira tickets, Figma designs, and more
* [Creating Test Cases](/web-testing/creating-test-cases) — all four methods for creating test cases in the UI
* [Running Tests](/execution/running-tests) — execute individual cases or run suite coverage through a test plan
* [Knowledge Base](/ai-features/knowledge-base) — provide application context so the AI agent understands your product during test runs
{% hint style="info" %}
**Get AI-powered test generation — start your free trial today** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see the AI Assistant with your workflow.
{% endhint %}
# AI Test Generation
Generate test cases automatically from Jira tickets, Figma designs, Swagger specs, videos, or natural language using ContextQA's AI-powered test generation.
## Quick answer
Generate test cases automatically from Jira tickets, Figma designs, Swagger specs, videos, or natural language using ContextQA's AI-powered test generation. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — developers, QA engineers, and managers — who want to generate test cases automatically from Jira tickets, Figma designs, Swagger specs, videos, or plain English descriptions.
{% endhint %}
ContextQA can generate complete test cases from 10 different source types. You do not need to write steps manually — supply a source artifact (a ticket, a design file, a video, a git diff) and the AI produces a ready-to-execute test case with all steps, assertions, and expected results filled in.
This page covers each generation method, when to use it, and how to invoke it — both from the ContextQA UI and from the MCP tool interface.
## Current requirements workflow
For document- and ticket-driven generation, use the **Requirements Library** as the traceability layer:
1. Open **Requirements** and create a requirement from uploaded files or a connected Jira source.
2. Select **Web**, **Mobile**, or **API** as the target platform.
3. Choose **Required Approval** when generated cases must be reviewed before publication, or **Auto Publish** for a trusted low-risk workflow.
4. Select the required scenario types: positive, negative, edge, field validation, boundary, functional, and end-to-end.
5. Add visual context such as an image, wireframe, or video when the written requirement does not fully describe the interaction.
6. Answer clarification questions, review generated cases, and confirm that the requirement shows the expected linked-test coverage.
The business objective should guide the source choice. A formal requirements document is best for auditability, a Jira story for sprint traceability, a spreadsheet for migration, a video for an expert-demonstrated workflow, and natural language for rapid authoring. See [Requirements to release](/business-use-cases/requirements-to-release) for the complete review pattern and success measures.
***
## 1. From natural language (most common)
The simplest and most flexible generation path. Describe what the test should do in plain English and ContextQA generates all the steps.
### In the UI
1. Navigate to **Test Cases** in the left sidebar
2. Click the **+** button to open the test case creation dialog
3. Select **Start with AI Assistance** from the method selection screen
4. *(Optional)* Select **Prerequisites** — existing test cases to run before this test
5. Enter the **URL** of the application page you want to test
6. Type your test scenario in the **Description** field — describe the user journey in plain English
7. Select the **Target Platform** — **Web Application** or **Mobile**
8. *(Optional)* Expand **Advanced Settings** to configure AI behavior:
* **Enable AI Smartness** — Choose `Expert` (thorough analysis), `Fast` (quick generation), `Strict` (follows description exactly), or `Organization Default`
* **AI Action** — Choose `Create Steps`, `Dynamic Steps`, `Action`, or `Organization Default`
* **Knowledge Base** — Select a knowledge base to provide application context
* **Environments** — Select a target environment
9. Click **Generate & Execute Test Case** — ContextQA creates and runs the test case with all steps filled in
10. Review the generated test cases on the verification screen, then click **Save** or **Save All Test Cases**
{% hint style="info" %}
If the **Generate From Crawl** feature is enabled on your plan, you can click **Generate From Crawl** instead of **Generate & Execute Test Case**. This option crawls the target URL and generates test cases based on the discovered pages and interactions.
{% endhint %}
**Example task descriptions:**
```
Log in as admin@test.com with password Test123!, navigate to the
Products page, search for "wireless headphones", and verify that
at least one product appears in the search results.
```
```
Open the checkout page with one item in the cart, fill in the
shipping address form with valid UK address data, proceed to
payment, and verify the order summary shows the correct total.
```
### AI Smartness modes
| Mode | Behavior |
| ------------------------ | --------------------------------------------------------------------------------------------------------------------- |
| **Expert** | The AI takes more time to analyze the application and produces thorough, detailed steps with comprehensive assertions |
| **Fast** | The AI prioritizes speed, generating steps quickly with less in-depth analysis |
| **Strict** | The AI follows your description exactly with minimal interpretation or additional steps |
| **Organization Default** | Uses the AI Smartness setting configured by your organization administrator |
### Via MCP
```python
create_test_case(
url="https://myapp.com/login",
task_description="Log in as admin@test.com with password Test123!, navigate to the Products page, search for 'wireless headphones', and verify at least one product appears in the results.",
name="Products - Search Smoke Test"
)
```
**Best for:**
* Creating new tests quickly when you know the user journey
* Exploratory testing where you are discovering application behavior
* One-off tests for specific regression scenarios
* Any scenario where you can describe the workflow in 1–3 sentences
**Tips for better results:**
* Include the starting URL in the task description or `url` parameter
* Mention specific field names, button labels, and page section names as they appear in the UI
* Include any setup state the test needs (e.g., "already logged in", "with an empty cart")
* For assertions, be specific: "verify the success message says 'Order placed'" is better than "verify success"
* Use **Expert** AI Smartness for complex flows where thoroughness matters more than speed
* Attach a **Knowledge Base** when the AI needs context about your application's domain or terminology
***
## 2. From Jira / Azure DevOps tickets
Generate tests directly from user stories and bug tickets. The AI reads the ticket description and acceptance criteria to create comprehensive test scenarios.
### Prerequisites
Connect Jira or Azure DevOps under **Integrations & Plugins**. Use a dedicated integration identity and the narrowest permissions needed to read the selected tickets or work items.
### In the UI
1. Navigate to **Assets → Requirements** and select **New Requirement**.
2. Choose **Generate from Integrations**. During the staged rollout, some workspaces may still show **Generate from Jira** as the first entry.
3. Choose Jira or Azure DevOps from the connected integration cards.
4. Search and select the tickets or work items. Azure DevOps supports project and work-item-type filters.
5. Choose the target platform, environment, publish mode, test types, and any additional AI context.
6. Start analysis and answer clarification questions when prompted.
7. Review the generated cases in the resulting requirement before approval or publication.
ContextQA stores the source items, clarifications, AI analysis, generated cases, metadata, and gaps on the requirement record. This preserves stronger traceability than an isolated generated case.
### Via MCP
```python
generate_tests_from_jira_ticket(
ticket_id="MYAPP-567",
include_acceptance_criteria=True
)
```
**What the AI reads:**
* Ticket summary (title)
* Ticket description
* Acceptance criteria (if present)
* Labels and priority (used to suggest edge cases for high-priority or bug tickets)
**Best for:**
* Agile teams who want test cases that map directly to user stories
* Ensuring every acceptance criterion has a corresponding automated test
* Bug tickets — the AI generates a reproduction test case from the steps-to-reproduce section
* Teams that manage requirements in Jira and want to maintain traceability
**Example output for a ticket like:**
> MYAPP-123: As a user, I want to reset my password so I can regain access if I forget it. AC1: User can request a reset link by entering their email AC2: Reset link expires after 24 hours AC3: New password must be at least 8 characters
ContextQA generates three test cases:
* "Password Reset - Request Link Flow" (main scenario)
* "Password Reset - Link Expiry After 24 Hours" (AC2)
* "Password Reset - Password Minimum Length Validation" (AC3)
***
## 3. From Figma designs
Generate tests from Figma design files before the application is even built. The AI analyzes design screens and creates tests matching the intended UX flows.
### Prerequisites
* A Figma URL with view access (the AI does not require edit access)
* For private files: a Figma personal access token configured from the Figma card under **Integrations & Plugins**
### Via MCP
```python
generate_tests_from_figma(
figma_url="https://www.figma.com/file/ABC123/My-App-Designs?node-id=1%3A2"
)
```
### How it works
The AI receives the Figma file and:
1. Identifies all screens and frames in the design
2. Analyzes the interactive elements (buttons, inputs, links, navigation)
3. Infers the intended user flows by connecting screens that share navigation patterns
4. Creates test cases for each distinct flow it identifies
For a three-screen checkout flow (cart → shipping → payment → confirmation), the AI creates a test case that navigates through each screen in sequence, fills the forms with realistic test data, and asserts the correct content on each screen.
**Best for:**
* Design-driven development — testing the intended UX before it is built
* Catching mismatches between design intent and implementation during QA
* Generating a test suite in parallel with development to reduce QA bottlenecks
* Design reviews — sharing generated test scenarios with stakeholders to validate flows
**Tips:**
* Use frames (not groups) for individual screens in Figma for best results
* Name your frames descriptively — "Step 1: Shipping Address" is more useful to the AI than "Frame 123"
* For complex flows, link the Figma file URL to the specific flow's starting screen using `node-id`
***
## 4. From Excel / CSV files
Migrate existing manual test case libraries into ContextQA. The AI parses your spreadsheet and maps columns to test steps, expected results, and metadata.
### Supported formats
* `.xlsx` (Excel 2007+)
* `.xls` (Excel 97-2003)
* `.csv` (comma-separated)
### Expected column structure
ContextQA recognizes common column names automatically:
| Detected Column | Mapped To |
| ------------------------------------------ | ------------------ |
| `Test Case Name`, `Name`, `Title` | Test case name |
| `Step`, `Step Description`, `Action` | Step description |
| `Expected Result`, `Expected`, `Assertion` | Expected result |
| `URL`, `Page`, `Base URL` | Test case URL |
| `Tags`, `Labels`, `Category` | Test case tags |
| `Priority`, `Severity` | Test case priority |
If your column names do not match these patterns, ContextQA presents a mapping UI where you can assign each column to the appropriate field before importing.
### Via MCP
```python
generate_tests_from_excel(
file_path="/path/to/test-cases.xlsx"
)
```
For remote files:
```python
generate_tests_from_excel(
file_path="https://example.com/shared/test-cases.xlsx"
)
```
**Best for:**
* Migrating from manual QA processes to automation
* Teams that maintain test cases in shared spreadsheets
* One-time import of a large legacy test library
* Taking over a QA process from another team that used Excel
***
## 5. From Swagger / OpenAPI specifications
Generate API contract tests for every endpoint in your OpenAPI specification. ContextQA creates test cases that verify each endpoint's request/response contract, status codes, and data shapes.
### Supported spec formats
* OpenAPI 3.0 (`.json` or `.yaml`)
* OpenAPI 3.1
* Swagger 2.0
### Via MCP
```python
generate_tests_from_swagger(
file_path_or_url="https://api.myapp.com/openapi.json"
)
```
Or from a local file:
```python
generate_tests_from_swagger(
file_path_or_url="/path/to/openapi.yaml"
)
```
### What gets generated
For each endpoint, ContextQA creates:
* **Happy path test**: valid request with all required parameters, asserts 2xx response
* **Validation test**: missing required fields, asserts 4xx response
* **Response schema test**: verifies the response body matches the declared schema
* **Auth test** (if security schemes are defined): verifies unauthorized requests get 401/403
**Best for:**
* API testing coverage — ensure every endpoint has at least one automated test
* Contract testing — catch breaking changes when the API changes
* Microservice teams where API test coverage is a release gate requirement
* Generating a baseline test suite immediately after a new service is deployed
***
## 6. From video screen recordings
Convert screen recordings of user journeys into automated tests. The AI watches the video and extracts each distinct user action as a test step.
### Supported video formats
* `.mp4` (H.264 codec recommended)
* `.mov` (QuickTime)
* `.webm`
### Via MCP
```python
generate_tests_from_video(
video_file_path="/path/to/user-journey-demo.mp4"
)
```
### How it works
The AI processes the video frame by frame to identify:
* Navigation events (URL changes, page loads)
* Click actions (identifies what was clicked based on visual context)
* Text input (captures what was typed, including field context)
* Assertions implied by visible state changes (a success banner appearing, a list populating)
Each identified action becomes a test step. The AI uses the visual context of each action (what is on screen, what the user interacted with) to write the step description in natural language.
**Best for:**
* Converting screen recordings from user research sessions into regression tests
* Capturing complex multi-page workflows that would take a long time to write manually
* Onboarding documentation — record a product demo once and generate tests from it
* Creating tests for legacy applications where no design files or specifications exist
**Tips for best video quality:**
* Record at normal speed — avoid fast-forwarding through steps
* Keep the cursor visible — use a cursor highlight tool if possible
* Pause briefly on each page before clicking to allow the AI to capture the page state
* Avoid recording over remote desktop connections (additional latency causes frame artifacts)
***
## 7. From requirements documents
Paste a requirements document in plain text format and ContextQA generates test scenarios covering all stated requirements.
### Via MCP
```python
generate_tests_from_requirements(
requirements_text="""
User Registration Requirements:
1. The registration form shall collect: first name, last name, email address, and password.
2. Email addresses must be unique across all user accounts.
3. Passwords must be at least 8 characters, contain at least one uppercase letter,
one lowercase letter, and one number.
4. A verification email shall be sent to the provided address upon successful registration.
5. The user shall be redirected to the dashboard after successful registration.
6. If registration fails (duplicate email, invalid password), an error message shall
be displayed inline next to the relevant field.
"""
)
```
### What gets generated
ContextQA generates test cases for:
* Each positive requirement (the happy path that must work)
* Validation rules (each constraint described in the requirements)
* Error states (each failure mode mentioned)
For the example above, it would generate tests for: successful registration, duplicate email error, password too short, password no uppercase, password no number, email verification sent, redirect after registration, and inline error message display.
**Best for:**
* Documentation-driven projects (government, regulated industries, large enterprises)
* Teams that maintain formal requirements specifications
* Converting BRDs (Business Requirements Documents) or FRDs into test suites
* Ensuring full traceability between requirements and tests
***
## 8. From code changes (PR-level testing)
Analyze a git diff and generate tests that specifically target the application flows affected by the changed code. This is the recommended approach for CI/CD integration.
### Via MCP
```python
generate_tests_from_code_change(
diff_text="""
diff --git a/src/checkout/payment.py b/src/checkout/payment.py
index 3f4a1b2..8c9d0e1 100644
--- a/src/checkout/payment.py
+++ b/src/checkout/payment.py
@@ -45,6 +45,12 @@ def process_payment(order_id, payment_method):
+ if payment_method.type == 'crypto':
+ raise PaymentMethodNotSupportedError('Crypto payments are not supported')
""",
app_url="https://staging.myapp.com"
)
```
### How it works
The AI analyzes the diff to understand:
* Which files changed and what those files are responsible for (route handlers, models, UI components)
* What the behavioral change is (new validation rule, new feature, bug fix, configuration change)
* Which user-facing flows are affected by the changed code paths
It then generates tests that specifically exercise those affected flows — in the example above, it generates a test that attempts to check out with a crypto payment method and asserts the application displays the appropriate error message.
**Best for:**
* CI/CD pipelines — run targeted tests on every pull request instead of the full suite
* Reducing test execution time in PRs while maintaining meaningful coverage
* Automated test generation as part of a code review process
* Ensuring every meaningful code change has a corresponding test
### GitHub Actions example
```yaml
- name: Generate tests from PR changes
env:
CONTEXTQA_USERNAME: ${{ secrets.CONTEXTQA_USERNAME }}
CONTEXTQA_PASSWORD: ${{ secrets.CONTEXTQA_PASSWORD }}
run: |
DIFF=$(git diff origin/main...HEAD)
python -c "
from app.contextqa_client import ContextQAClient
import os
client = ContextQAClient(os.environ['CONTEXTQA_USERNAME'], os.environ['CONTEXTQA_PASSWORD'])
result = client.generate_tests_from_code_change(
diff_text='''$DIFF''',
app_url='https://staging.myapp.com'
)
print(result)
"
```
***
## 9. From n8n workflows
Map n8n automation workflow nodes to ContextQA test steps. Each node type in the n8n workflow becomes a corresponding verification step in the test case.
### Via MCP
```python
generate_contextqa_tests_from_n8n(
file_path_or_url="/path/to/workflow.json"
)
```
Or from a published n8n workflow URL:
```python
generate_contextqa_tests_from_n8n(
file_path_or_url="https://n8n.io/workflows/1234-my-workflow"
)
```
### Node mapping
| n8n Node Type | Generated Test Step |
| ---------------- | ---------------------------------------------------------------------- |
| HTTP Request | API call assertion: verify endpoint returns expected status and body |
| Code | Logic verification: verify output data matches expected transformation |
| AI / LLM | AI response validation: verify response contains expected content |
| Webhook | Webhook trigger test: send test payload and verify processing |
| Database | Data assertion: verify database state after workflow execution |
| Email | Notification test: verify email delivery and content |
| Conditional (IF) | Branch coverage: generate separate test cases for each branch |
| Loop | Iteration test: verify correct behavior across N iterations |
**Best for:**
* Teams using n8n for business automation who want to test their workflows
* Ensuring n8n workflow changes do not break downstream processes
* Validating webhook integrations end to end
* CI/CD testing for n8n workflow deployments
***
## 10. Edge case generation
Generate boundary conditions, invalid input scenarios, and error state tests for any feature described in natural language.
### Via MCP
```python
generate_edge_cases(
context_query="user login with email address and password validation"
)
```
### Example output
For the login edge case query, ContextQA generates scenarios including:
* Empty email field submission
* Empty password field submission
* Email address without @ symbol
* Email address with consecutive dots
* Password exceeding maximum length (if any)
* Login with valid email but wrong password (N times, to trigger lockout if applicable)
* Login with correct credentials after account lockout
* Login with SQL injection attempt in the email field
* Login with XSS payload in the password field
* Login with Unicode characters in the password
* Login with leading/trailing whitespace in both fields
* Concurrent login from two different browsers
**Best for:**
* QA engineers who want comprehensive negative test coverage without writing each scenario manually
* Security-minded teams who need to cover injection attacks and boundary conditions
* Feature completeness reviews before release — run edge case generation on every new feature
* Augmenting a happy path test suite with systematic negative testing
***
## Comparing generation methods
| Method | Best Input Quality | Time to Generate | Test Quality |
| ---------------- | ------------------------------------- | ---------------- | ------------------------------------------------- |
| Natural language | Any — works with vague descriptions | Seconds | High for clear descriptions, lower for vague ones |
| Jira ticket | Well-written tickets with ACs | Seconds | Very high — traces directly to requirements |
| Figma design | Complete, screen-based designs | 15-30 seconds | High for UI flows |
| Excel/CSV | Structured, well-labeled spreadsheets | 30-60 seconds | Depends on existing test quality |
| Swagger/OpenAPI | Any valid spec | 30-60 seconds | Very high for API tests |
| Video | Clear, normal-speed recordings | 1-3 minutes | High — captures exact interactions |
| Requirements | Formal, numbered requirements | Seconds | Very high — systematic coverage |
| Code change | Git diff with clear intent | 15-30 seconds | High for targeted regression |
| n8n workflow | Valid n8n JSON export | 15-30 seconds | High for integration tests |
| Edge cases | Any feature description | Seconds | High breadth, AI-inferred scenarios |
***
## After generation
Regardless of which method you use, after generation you should:
1. **Review on the verification screen** — when generating from the UI (Natural Language or Import File methods), the creation dialog presents a verification screen showing each generated test case with its title, description, steps, and expected result. Review each case and click **Save** individually or **Save All Test Cases** to save them all. Any skipped test cases appear with a reason explaining why they were omitted.
2. **Execute the test** — run it once to verify it works against your current application state. Use `execute_test_case` via MCP or the **Run** button in the UI.
3. **Review the results** — if any step fails on the first run, use AI root cause analysis to understand whether the failure is a test issue (step was generated incorrectly) or an application issue (a real bug).
4. **Add to a suite** — once the test passes, add it to the appropriate test suite so it runs as part of your regular regression cycle.
## Related pages
* [Autonomous Agent Pipeline](/ai-features/autonomous-agent-pipeline) — how the AI executes your generated tests
* [Creating Test Cases](/web-testing/creating-test-cases) — all four test case creation methods in the unified creation dialog
* [Knowledge Base](/ai-features/knowledge-base) — provide application context to improve generation accuracy
* [Custom Agents](/ai-features/custom-agents) — create domain-specific agents for specialized test generation
* [Running Tests](/execution/running-tests) — execute your generated tests
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# AI Insights
Analyze real user sessions with ContextQA AI Insights, discover activities and console errors, measure activity coverage, and generate tests for uncovered journeys.
{% hint style="info" %}
**Who is this for?** QA engineers, SDETs, and QA managers who want to base their test suite on how customers actually use the application, and to find gaps between real user behavior and existing test coverage.
{% endhint %}
AI Insights analyzes real user sessions captured on a domain you choose, groups them into the distinct **activities** users perform, and reports what those activities reveal — console errors encountered along the way, how many activities you have already turned into tests, and which ones still need coverage. From any discovered activity, you can generate a test case, so your suite tracks real usage instead of assumptions.
## Quick answer
ContextQA AI Insights turns observed application usage into prioritized testing opportunities. It analyzes captured sessions, reconstructs distinct user activities, surfaces console errors and uncovered journeys, and lets a tester generate a requirement and test case from an activity. Scheduled runs help teams compare real usage with automated coverage over time.
## What this page covers
Each analysis is called an **AI Insight**, and it runs on a schedule you set. Every time it runs, it produces a **run** — a point-in-time snapshot of the activities found in that window. You can switch between runs, watch a run progress phase by phase, and compare how coverage changes over time.
Unlike [AI Test Generation](/ai-features/ai-test-generation), which creates tests from a source you provide (a ticket, a URL, a design), AI Insights works backward from observed behavior: it looks at what users did, then tells you what is worth testing.

***
## Key concepts
| Term | What it means |
| ------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **AI Insight** (session) | A single analysis configured against one domain, an optional session window, and a schedule. The **New Session** action creates one. |
| **Run** | One execution of an insight. Each run analyzes the sessions in its window and produces a report. Insights that run on a schedule accumulate many runs over time. |
| **Activity** | A distinct path a user took through your application, reconstructed from one or more sessions. In the report, an activity is also shown as a **journey**. Each has a priority, a narrative, and any console errors captured during it. |
| **Coverage** | How many activities you have converted into test cases, out of the total discovered. |
| **Console error** | A JavaScript or network error captured in the browser console during a session. AI Insights treats these as real, user-visible defects. |
| **Requirement** | The record a generated test case is created from. Activities you generate tests for produce a **crawl requirement** — see [Generate requirements from a crawl](/ai-features/crawl-requirements). |
***
## Opening AI Insights
1. Open your ContextQA workspace.
2. In the left navigation, go to **AI Insights** (route: `/td/:versionId/ai-insights`).
3. The page opens on two tabs:
* **Overview** — workspace-level metrics across every insight and run.
* **Sessions & Activities** — the list of insights you have configured.
The header carries a **New Session** action that creates a new insight from either tab.
### Overview tab
The **Overview** tab (`/td/:versionId/ai-insights/overview`) summarizes AI Insights activity for the whole workspace version. Use the date range picker at the top (which defaults to **All time**) to change the window.
A **Key metrics** row shows six tiles:
| Tile | What it shows |
| ---------------------------- | --------------------------------------------------------------------------------------------------------- |
| **Sessions captured** | How many user sessions were captured. |
| **Activities captured** | How many distinct activities were reconstructed from those sessions. |
| **Requirements generated** | AI-generated requirements attributed to an AI Insights activity. Manual and Jira uploads are not counted. |
| **Test cases created** | How many test cases were generated from those requirements. |
| **Mean time to requirement** | The mean latency from an activity being surfaced to its requirement being generated, in hours. |
| **Converted to suite** | The percentage of generated test cases that sit in a suite. |
The first four tiles show a **last-run delta** — a `+` count with an upward-trend icon — when the most recent run of each insight added something new.
The delta is the latest run's contribution inside the selected date window; it is not a percentage comparison with the preceding calendar period and it is not a website-traffic growth metric. To compare periods, set the date range for the first window, record the metrics, then repeat for the second window. Keep the same domain, URL-path scope, and schedule when you want a meaningful comparison.
Below the metrics, a **Trend** chart plots **Activities** against **Test cases** over the selected period. Switch the granularity between **Day**, **Week**, and **Month**.
If no data has been captured yet, the tab shows "No AI Insights data yet."
### Sessions & Activities tab
The **Sessions & Activities** tab (`/td/:versionId/ai-insights/sessions`) lists every insight configured for this workspace version. Search the list with the **Search AI Insights** box, and filter by date range, created date, status, or domain.
Each row shows:
| Column | What it shows |
| ----------------- | -------------------------------------------------------- |
| **ID** | The insight identifier. |
| **Name / Domain** | The insight name and the domain it analyzes. |
| **Activities** | How many activities the latest run found. |
| **Test cases** | How many test cases have been generated from it. |
| **Coverage** | How many activities have been converted into test cases. |
| **Status** | Where the insight is in its run (see below). |
| **Range** | The session window the run analyzed. |
| **Created At** | When the insight was created. |
The status column reflects where each insight is:
| Status | Meaning |
| --------------- | ------------------------------------------------------------------------- |
| **Scheduled** | The insight is waiting for its next scheduled run. |
| **In Progress** | A run is analyzing sessions. The status shows a percentage while it runs. |
| **Ready** | Activities are ready to review. Open the insight to view its report. |
| **Completed** | The run finished. |
| **Stopped** | The run was stopped before completion. |
| **Failed** | The run couldn't complete. Use **Re-Run** to start it again. |
Each row has an action menu with **Edit** and **Re-Run**. Click a row to open its report.
{% hint style="info" %}
**Prerequisite:** AI Insights needs captured session data for the domain you select. The **Domain Name** dropdown lists only domains that have recorded sessions, with the number of events available for each. If your domain does not appear, no session data has been captured for it yet.
{% endhint %}
***
## Creating an AI Insight

1. From either tab, click **New Session**.
2. Select the **Domain Name** — the site whose sessions you want to analyze. Each option shows the captured event count, for example `app.example.com (12,345 events)`.
3. Enter a **Name** — a descriptive label for this insight.
4. Choose a **Scheduler** value to control how often the analysis runs:
* **Once** — runs a single time (default).
* **Daily** — runs once every day.
* **Weekly** — runs once every week.
* **Biweekly** — runs once every two weeks.
5. Set the **Date** and **Time** for the first (or only) run. Both default to five minutes from now, and the scheduled time must be in the future.
6. To refine the analysis, expand **Advanced Options**:
* **URL Path** — narrow the analysis to a section of the domain, for example `/checkout`. This field searches the paths captured under the selected domain as you type, so pick a domain first.
* **Date Range** — limit analysis to sessions recorded between a start and end date.
* **Additional Context** — optional guidance for the AI, for example "focus on booking flows."
7. Click **Submit**.
ContextQA queues the insight and begins processing at the scheduled time.
{% hint style="info" %}
The **Date Range** in Advanced Options controls which sessions are analyzed. The **Date** and **Time** at the top of the form control when the analysis runs.
{% endhint %}
### Editing the schedule
Open an insight and use the **Edit** action to change its scope, context, or schedule. When you edit an existing insight, the schedule shows as a read-only summary until you click **Change schedule**; new insights open with the schedule editor already expanded.
* **Pause and resume** — a scheduled insight can be paused so no further runs fire. Activities already generated are kept, and you can still start a run by hand. Saving a schedule change to a paused insight resumes it.
* **In-progress lock** — while a run is in progress, its schedule can't be edited.
***
## Working with runs
Open an insight to see its report. Because a scheduled insight runs repeatedly, the report always shows one **run** at a time — by default, the latest.
### Run summary and run switcher
The header identifies the insight and the run you are viewing:
* The **title** shows the environment the insight ran against, with a link to the domain.
* A **run summary** describes the selected run, for example `Latest run · Today, Jul 7 · 12 journeys`.
* The **run switcher** (labeled **Switch run**) lists every run, newest first, with its date and outcome. Select a run to view it; the choice is pinned to the page URL so you can share a link to a specific run.
* **Re-Run** starts a fresh run immediately.
* **Context** opens the additional context you set, and a schedule button shows the cadence and whether the schedule is active or paused.
A run can end in several states, shown in the switcher and on the report:
| Run outcome | Meaning |
| --------------------------------------------- | ---------------------------------------------------------------------------------- |
| Journeys count (for example, **12 journeys**) | The run finished and produced activities. |
| **Analyzing…** | The run is still processing. It shows the current phase and a progress percentage. |
| **Queued** | The run is waiting to start. |
| **Superseded** | A newer run replaced this one. |
| **No journey** / **No activities** | The run finished but found nothing to report. |
| **Partial** / **Incomplete** | The run finished only some of its work. Use **Re-Run** to try again. |
| **Unreachable** | The site could not be reached. |
| **Rate limited** | The run was throttled. |
### Run-phase timeline
While a run analyzes sessions, it moves through five phases in order:
1. **Selecting sessions**
2. **Processing video**
3. **Identifying user activities**
4. **Generating journeys**
5. **Matching existing tests**
The report shows the active phase, a progress bar, and a stage checklist. Use **Refresh** to update a run that is still analyzing, or **Re-Run** to restart a run that stopped early.
***
## Reading the report
When a run is ready, the report opens in a two-pane layout with an overview strip above it.
### Overview strip
A collapsible **Overview** section summarizes the run in four cards:
| Card | What it shows |
| --------------------- | --------------------------------------------------------------- |
| **Activities found** | The total number of distinct activities discovered in this run. |
| **Console errors** | The number of console errors captured across all activities. |
| **P1 critical flows** | How many activities are high priority. |
| **Already processed** | How many activities have already produced tests. |
### Activity list
The left pane lists every activity. Each row shows:
* A **priority badge** (`P0` for the highest priority, then `P1`, `P2`, and lower).
* A **console error** badge (or **0 errors** when there are none).
* A **steps** count.
* When the activity was **captured**.
Search the list with the box at the top, and select the checkbox on one or more rows to generate tests in bulk. When rows are selected, an action bar appears with **Generate test cases (N)** and **Clear**.
### Activity details
Select an activity to open its detail panel. The header shows the priority, the title, and one primary action:
* **Open Requirement** — opens the requirement linked to this activity, when one exists.
* **Generate Test Case** — generates a test for this activity when it has no linked requirement.
The panel has three sub-tabs:
* **Insight** — explains the activity. It includes a **Why this matters** callout with the AI's reasoning, a **User journey** narrative describing the steps the user took, and a collapsible **Discarded activities** list of steps the AI analyzed but left out of this activity.
* **Console Errors** — lists the console errors captured during the session.
* **Replay** — plays an embedded session replay, when a recording is available.
***
## Generating test cases from activities
When an activity has no test coverage, turn it into one or more test cases directly from the report. ContextQA generates each test case by crawling your live application, so every generation produces a **crawl requirement**.
1. Select one or more uncovered activities using their row checkboxes, or open a single activity and click **Generate Test Case**.
2. In the action bar, click **Generate test cases (N)**. The **Generate test cases** drawer opens.
3. The drawer analyzes the selected activities first (the **Analysis** step), then walks you through **Clarifications**, **Inputs**, and **Crawl**.
{% hint style="info" %}
If every activity you selected has already produced a requirement, the drawer shows an **Already generated** state with a link to each existing requirement. Pick at least one activity that hasn't been generated yet.
{% endhint %}
For the full walkthrough of the drawer — answering clarifications, configuring inputs, and reading the crawl requirement it produces — see [Generate requirements from a crawl](/ai-features/crawl-requirements).
***
## Summary
AI Insights closes the loop between how users behave and what your tests cover:
1. **Create** a session against a domain, an optional session window, and a schedule.
2. **Review** each run's activities, their priorities, and their console errors.
3. **Track** how many activities you have already converted into tests, run over run.
4. **Generate** test cases for the activities that matter most.
Because you can schedule an insight to run daily, weekly, or biweekly, your test suite keeps pace with how customers actually use your application.
***
## Related pages
* [Generate requirements from a crawl](/ai-features/crawl-requirements) — the crawl workflow that turns activities into test cases, and how to read a crawl requirement
* [AI Test Generation](/ai-features/ai-test-generation) — generate test cases from tickets, URLs, designs, and other sources
* [Requirements Coverage Gaps](/ai-features/requirements-coverage-gaps) — find requirements that lack test coverage
* [AI Assistant](/ai-features/ai-assistant) — the in-app AI assistant for navigation and test creation
* [Test Results](/reporting/test-results) — understanding execution result pages
## Frequently asked questions
What is ContextQA AI Insights?
AI Insights is the user-behavior analysis area in ContextQA. It analyzes captured sessions for a configured domain, groups behavior into activities or journeys, reports associated console errors and coverage, and provides a path to generate tests for uncovered activity.
How is AI Insights different from AI Test Generation?
AI Test Generation starts from a source you deliberately provide, such as requirements, a ticket, URL, design, or API definition. AI Insights starts from observed user sessions and identifies the activities that users actually performed before recommending coverage.
Does AI Insights automatically turn every activity into a test?
No. Review the activity, its priority, narrative, errors, and existing coverage first. You choose an uncovered activity and start test generation, including any required clarification and input review.
What does AI Insights coverage measure?
Coverage compares activities discovered by the insight with activities that have been converted into generated requirements and tests. It is activity coverage within AI Insights, not a universal guarantee of complete product or requirements coverage.
Why would a run show partial, unreachable, or rate-limited?
Those states mean the run could not complete its normal analysis window. Review the status and phase, verify that the configured site is reachable and eligible for capture, and use **Re-Run** after correcting the condition.
## See AI Insights on a real application
Choose a customer journey whose real usage is difficult to translate into regression coverage. In a guided demo, the ContextQA team can show how captured activity becomes an insight, a coverage decision, and a reviewable test.
[**Book a Demo →**](https://contextqa.com/book-a-demo/)
# Generate Requirements from a Crawl
How to generate test cases in ContextQA by having an AI agent crawl your live application — from an AI Insights activity or from a new requirement — and how to read the crawl requirement it produces.
## Quick answer
Start **Assets → Requirements → New Requirement → Generate from Crawl**, give the AI agent a target URL and a concrete user goal, then choose the scenario types and approval mode. ContextQA keeps the live crawl, clarifications, source context, AI analysis, and generated tests together in one requirement so an AI agent or reviewer can trace each test back to what the crawl observed.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who want an AI agent to walk their live application and build test cases from what it finds, either starting from a discovered user activity or from scratch.
{% endhint %}
A **crawl** hands a task to an AI agent that navigates your live application in a browser, then generates test cases from what it finds. Every crawl produces a **crawl requirement** — the record the generated test cases are created from, which preserves the context the crawl started from.
You can start a crawl two ways:
* **From an AI Insights activity** — turn a discovered user activity into test cases. See [AI Insights](/ai-features/ai-insights).
* **From a new requirement** — describe a flow yourself and let the agent explore it.
Both paths produce the same kind of crawl requirement, which you read the same way.
***
## Starting a crawl from AI Insights activities
When you generate test cases from one or more activities in an AI Insights report, the **Generate test cases** drawer opens. Its subtitle explains the model: **Each selected activity produces its own requirement.** Nothing is merged across activities.
The drawer is a four-step flow.
### 1. Analysis
Analysis starts as soon as the drawer opens, so you review what the AI actually found before configuring anything. For each activity it works out the prerequisite steps and the clarifications worth asking, and summarizes them in a **What the AI found** card.
Activities that have already produced a requirement are skipped. If every activity you selected has already been generated, the drawer shows an **Already generated** state instead — close it and pick at least one activity that hasn't been generated yet.
When the analysis finishes, click **Continue to clarifications**.
### 2. Clarifications
Each activity that needs a decision shows one or more questions. The AI's recommended answer is preselected, so change only what you disagree with — or choose **Other** to enter your own answer. A progress indicator tracks how many questions you have answered, and **Use recommended** resets every answer to the AI's suggestion.
You can also attach a prerequisite step the generated tests should reuse. When nothing needs deciding, the step shows **Nothing needs deciding** and you can carry on.
Click **Continue to inputs**.
### 3. Inputs
Review the selected activities and edit the **start URL** for each one. Expand **Show Configuration Options** to set how the tests are generated (see [Crawl configuration options](#crawl-configuration-options) below), and optionally add extra context.
Click **Start crawls**.
### 4. Crawl
ContextQA creates one crawl requirement and one live crawl session per activity. Each row shows its status and links to the requirement it produced:
| Status | Meaning |
| --------------------- | ---------------------------------------------------------- |
| **Crawling** | The crawl is running. |
| **Already generated** | The activity already had a requirement, so it was skipped. |
| **Failed** | The crawl couldn't start. |
You can close the drawer once crawls start — each requirement fills in as its own crawl completes. Use **View live crawl** to watch a running crawl, or **View requirement** to open the result.
***
## Starting a crawl from a new requirement
You can also start a crawl without an AI Insight.
1. Open the **New Requirement** dialog from the requirements library.
2. On the **Choose how you'd like to generate your test cases** screen, select **Generate from Crawl** and click **Get started**.
3. Complete the **Inputs** step, then start the crawl.
The Crawl flow has two steps: **Inputs** and **Crawl**.
### Inputs
Fill in the crawl inputs:
* **Target URL** — where the crawl starts. It becomes the first step of the crawl, so it is always required, for example `https://app.example.com/login`.
* **What should the crawl explore?** — the task handed to the AI agent, for example "Sign in, add a product to the bag, apply a coupon and complete checkout." Use the **Example Prompts** below the field for inspiration.
* **Name this requirement** *(optional)* — leave blank to name it after the date and time the crawl started.
* **Additional context** *(optional)* — anything the AI should know that isn't in the instructions above.
Expand **Show Configuration Options** to set the generation options described below.
Click **Start Crawl**. ContextQA creates the requirement and a live browser session, then shows the result card with a link to the requirement (`REQ-`) and a **View live crawl** button while the crawl runs. You can close the dialog — the crawl continues in the background and the requirement fills in as it completes.
{% hint style="info" %}
On the Free plan, crawls are limited to the demo URLs ContextQA provides. Any other URL is rejected with a "URL Not Allowed" message.
{% endhint %}
### Crawl configuration options
Both crawl paths share the same configuration options:
| Option | What it controls |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Select Target Platform** | The platform the generated tests target. A live crawl always runs in a browser, so **Web Application** is the only available platform; **Mobile** and **API** are disabled. |
| **Publish Mode** | **Require approval** keeps generated tests in a draft state until you review them. **Auto publish** publishes them automatically after analysis. |
| **Test case types** | The types of test cases the AI generates — **All Types**, or any of **Positive / Happy Path**, **Negative**, **Edge Cases**, **Field Level Validation**, **Boundary Value**, **Functional**, and **End to End**. If you select none, the AI decides for you. |
| **Prerequisites** *(optional)* | Test cases that must run before every test case this crawl generates, for example "User is logged in." They do not replace the target URL, which the crawl always starts from. |
| **Create Test Suite** | Add the generated tests to a new suite, named in **Test Suite Name**. |
| **Create Test Plan** | Add the generated tests to a new plan, named in **Test Plan Name**, with an option to **Execute Test Plan**. |
{% hint style="info" %}
Tests awaiting approval cannot be added to a suite or plan. To use **Create Test Suite** or **Create Test Plan**, set **Publish Mode** to **Auto publish**.
{% endhint %}
### Write an AI-ready crawl goal
Describe the business outcome, important checkpoints, and stopping condition instead of listing brittle selectors. For example:
```
Sign in with the approved test account, find an unpaid invoice, apply a valid
payment method, and stop after the confirmation page. Verify the invoice ID,
amount, currency, and final status. Do not submit a second payment.
```
After generation, confirm that the scenario types shown on the generated rows match the types you selected. Review prerequisites separately from the newly generated positive, negative, edge, or validation cases; referenced prerequisites do not count as newly generated scenarios.
### Crawl boundaries and authenticated applications
A crawl explores from the target URL in pursuit of the goal you provide. It does not guarantee discovery of every route, role, hidden state, or edge case, and it does not prove complete application coverage.
* Keep the goal narrow enough to review and include a clear stopping condition.
* Use a non-production environment and a dedicated test identity for authenticated flows.
* Put passwords, tokens, and OTP seeds in Environment Password/Vault values or an approved runtime integration—never in the crawl goal, requirement text, or knowledge base.
* Attach a validated login prerequisite when the crawl must begin in an authenticated state. A prerequisite does not bypass CAPTCHA, multi-factor authentication, or an external identity provider.
* Confirm that redirects, popups, and any required external domain are reachable in the managed browser session.
* Prefer **Require approval** for state-changing flows and review generated steps before publishing or executing them.
The generated cases are reviewable drafts of what the agent observed. Add scenarios for roles, data states, or routes the crawl could not reach, and verify that the tests do not create duplicate payments, messages, or production records.
***
## Reading a crawl requirement
Open a crawl requirement to review what the crawl captured and generated. A crawl requirement is marked with an **AI Insights** badge and adds crawl-specific content to two tabs.
### Metadata tab
The **Metadata** tab shows two sections for a crawl requirement:
* **Generation Information** — the activity title and platform, plus capture stats drawn from the source activity: **Console Errors**, **Steps Executed**, **Pages Visited**, **Test Cases**, and **Version**.
* **Configurations** — **Publish Mode**, **Environment**, **Test Case Types**, **Test Suite**, and **Test Plan**.
### Requirement Data tab
The **Requirement Data** tab has two sub-tabs:
* **Sources & Context** — traces the requirement back to the AI Insight and the activity it came from. A capture card shows the source **Insight** (as a link), when it was **Generated**, and the platform. A **Captured activity** entry lists when it was captured, its step count, its console error count, and its priority, with a **What I considered** note from the AI. If no source context exists, the tab shows "No source context."
* **AI Analysis** — summarizes the generation pass, including **AI Understanding**, **Assumptions Made**, **Coverage Notes**, **Warnings & Gaps**, and a **Confidence Score**.
***
## Summary
Crawling turns a live walkthrough of your application into test cases:
1. **Start** a crawl from an AI Insights activity or from a new requirement.
2. **Configure** the target, the task, the platform, and how the results are published.
3. **Run** the crawl in the background while the requirement fills in.
4. **Review** the crawl requirement's metadata, sources, and AI analysis.
***
## Related pages
* [AI Insights](/ai-features/ai-insights) — discover the activities users take and generate tests for the gaps
* [AI Test Generation](/ai-features/ai-test-generation) — generate test cases from tickets, URLs, designs, and other sources
* [Requirements Coverage Gaps](/ai-features/requirements-coverage-gaps) — find requirements that lack test coverage
* [Requirements management](/web-testing/requirements-management) — review generated cases, variables, and approvals
# Tutorial: Generate Tests from Requirements
Upload requirements, answer AI clarifications, review traceable generated test cases, and run the accepted ContextQA coverage without writing test steps.
## Quick answer
Upload requirements, answer AI clarifications, review traceable generated test cases, and run the accepted ContextQA coverage without writing test steps. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA managers, SDETs, and agile teams who maintain requirements in documents or tickets and want a complete test suite generated from them — with each test traceable back to the requirement it covers.
{% endhint %}
ContextQA reads a requirements artifact — a specification document, a user story, or a set of acceptance criteria — and generates a complete set of test cases from it. Instead of translating each requirement into steps by hand, you upload the source, answer a few clarifying questions, and review the test cases the AI produces. Every generated case maps back to a requirement, so you can show coverage at a glance.
In this tutorial you:
1. Start an import from a requirements document
2. Configure the target platform, publish mode, and suite creation
3. Let ContextQA analyze the requirements and answer its clarifying questions
4. Review the generated test cases and approve the ones you want
5. Run a generated test and confirm it works
**End result:** A reviewed test suite generated from a requirements document, with each test case traceable to the requirement that produced it — ready to run as part of your regression cycle.
[Watch the requirements-to-tests walkthrough](https://drive.google.com/file/d/1JtdXOKBYGoQiGa4woSapLiVOge0vrlyS/preview).
{% hint style="info" %}
**Business use case:** Import a release specification once, generate positive and negative coverage together, and keep approval with the QA owner before the cases enter a shared regression plan.
{% endhint %}
## Prerequisites
* A ContextQA account with at least one workspace ([sign up](https://accounts.contextqa.com/onboard))
* A requirements document to import — a `.pdf`, `.docx`, `.xlsx`, `.csv`, or `.txt` file describing the behavior you want to test
* The URL of the web application the requirements describe
* Familiarity with [core concepts](/getting-started/core-concepts) — specifically test cases, suites, and test plans
If you don't have a requirements document handy, create a plain text file named `registration-requirements.txt` with the following content and use it throughout this tutorial:
```
User Registration Requirements
1. The registration form collects first name, last name, email address, and password.
2. Email addresses must be unique across all accounts.
3. Passwords must be at least 8 characters and contain one uppercase letter,
one lowercase letter, and one number.
4. On successful registration, the user is redirected to the dashboard.
5. If the email is already in use, an inline error appears next to the email field.
6. If the password does not meet the rules, an inline error appears next to the
password field.
```
***
## Step 1: Start a requirements import
Begin by opening the test case creation panel and choosing the import path.
1. In the left sidebar, select **Test Cases**.
2. Click the **+** icon to open the creation panel. A full-height panel slides in from the right.
3. On the method selection screen, click **Import File**.
4. The panel asks *What type of file would you like to import?* Select the **Import Requirements** card.
**Verify it worked:** The panel switches to a stepper with three steps — **Inputs**, **Analysis**, and **Clarifications** — with **Inputs** active.
{% hint style="info" %}
**Tip:** **Import Requirements** generates test cases from a specification. The other card, **Import Test Cases**, is for a different task — migrating an existing test library from an Excel spreadsheet where the steps are already written.
{% endhint %}
***
## Step 2: Configure the import
On the **Inputs** step, set how ContextQA generates and publishes the test cases before you upload the file.
1. Click **Show Configuration Options** to expand the settings.
2. Under **Select Target Platform**, choose **Web Application**.
3. Under **Publish Mode**, choose **Require Approval**. Generated test cases stay in a draft state until you review them, which is the right choice while you learn the workflow.
4. *(Optional)* Add context that helps the AI generate more accurate cases:

| Field | Example value |
| -------------------------- | ------------------------------------------------------------------------------------------- |
| **Name** | `User registration requirements` |
| **Additional information** | `Web app at https://yourapp.com/register. Email and password are the only required fields.` |
{% hint style="info" %}
**Tip:** Attach UI mockups or screenshots alongside the document. Visual context helps the AI generate more relevant and complete test cases.
{% endhint %}
5. Upload your requirements file. You can add up to 10 files per import — documents (`.pdf`, `.docx`, `.xlsx`, `.csv`, `.txt`), images, or video recordings.
6. Continue to the next step.
**Verify it worked:** The stepper advances to **Analysis** and ContextQA begins reading the document.
{% hint style="info" %}
**Note:** **Require Approval** keeps the generated test cases as drafts until you approve them. **Auto Publish** publishes them immediately and lets you also create a test suite, create a test plan, and run the plan as part of the same import. Use **Auto Publish** once you trust the generation quality for a given source.
{% endhint %}
***
## Step 3: Review the analysis and answer clarifications
ContextQA reads the document, extracts the testable requirements, and then asks about anything ambiguous.
1. On the **Analysis** step, ContextQA lists the requirements it identified from your document. Confirm the list reflects the behavior you want covered.
2. The flow advances to the **Clarifications** step. The AI presents follow-up questions about details the document left open — for example, *What's the exact wording of the duplicate-email error?* or *What URL should the registration test start from?*
3. Answer each question in its field. Specific answers produce more accurate tests. If a question doesn't apply, leave it blank.
4. Submit your answers to start generation. If you have no answers to add, skip the questions instead — generation still runs.
**Verify it worked:** ContextQA generates a set of test cases covering the requirements and their failure modes. For the registration example, it produces cases for successful registration, the duplicate-email error, and each password validation rule.
{% hint style="info" %}
**Why clarifications matter:** Generation quality tracks input quality. A requirement that says "passwords must be strong" produces a vague test; answering the clarification with "at least 8 characters, one uppercase, one lowercase, one number" produces a precise one. The more explicitly you describe expected behavior, the better the generated tests.
{% endhint %}
***
## Step 4: Review and approve the generated test cases
Generated cases from a requirements import appear under the uploaded file so you can review coverage in one place.
1. In the left sidebar, go to **Assets → Requirements**. Your imported file appears in the list with a **Status** of **Completed** and a count of generated test cases.
2. Click the file row to open its detail view. The **Test Cases** tab lists every generated case.
3. Review the table. Each row shows:
| Column | What it tells you |
| --------------------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Test Case** | The under-review ID, name, and description. An existing-case icon and linked `TC-` identify a match already in the repository. |
| **Type** | The test type — `Positive`, `Functional`, `Negative`, `Edge`, `Field Validation`, `End to End`, or `Boundary Value` |
| **Priority / Prerequisite** | Triage metadata and any reusable setup case |
| **Variables** | Test-data, environment, or global references detected in the generated steps |
| **Decision** | **Pending**, **Approved**, or **Rejected** |
4. Click any test case to open the detail drawer and inspect its steps, expected results, and variables.
5. For each case you want to keep, click **Approve**. To discard one, click **Reject**. To send an approved or rejected case back for another look, use **Revert to Review**.
{% hint style="info" %}
When the existing-case icon appears, open its linked `TC-` and compare the match reason and steps before approving anything new. This preserves traceability without silently duplicating repository coverage.
{% endhint %}
**Verify it worked:** The test cases you approved move to an **Approved** decision and are published to your test case list. Because you chose **Require Approval** in Step 2, only the cases you approved are published.
{% hint style="info" %}
**Tip:** Open the **Gaps** tab in the file detail view to see requirements the generated suite doesn't yet cover. Address gaps by adding context and regenerating. See [Requirements coverage gaps](/ai-features/requirements-coverage-gaps).
{% endhint %}
***
## Step 5: Run a generated test
Confirm a generated test works against your live application.
1. Open one of the approved test cases — for example, *Registration — successful sign-up*.
2. Review the steps. The AI fills in the starting URL, the form interactions, and the assertions from your requirement and clarification answers. Edit any step whose wording doesn't match your application's exact labels.
3. Click **Run** in the top toolbar.
4. Select an execution environment and start the run.
**Verify it worked:** The execution viewer shows each step with a real-time pass/fail indicator. When the run finishes, click **View Detailed Report** to see the step-by-step breakdown, screenshots, and video.
{% hint style="warning" %}
**Common mistake:** If a step fails because a button or field label doesn't match, the requirement described the behavior in different words than your application uses. Edit the step to use the exact label, or add a [Knowledge Base](/ai-features/knowledge-base) entry so future generations use your application's real terminology.
{% endhint %}
***
## Summary
You generated a test suite from a requirements document in five steps:
1. **Started a requirements import** from the test case creation panel
2. **Configured** the target platform, publish mode, and context for generation
3. **Reviewed the AI analysis** and answered clarifying questions to sharpen the output
4. **Approved** the generated test cases, each traceable to the requirement that produced it
5. **Ran** a generated test and reviewed the evidence
A specification that existed only as a document is now a reviewed, runnable test suite.
## Next steps
* **Generate from a Jira ticket:** If you manage requirements in Jira, the same flow can pull test cases from ticket descriptions and acceptance criteria. See [Jira integration](/integrations/jira) and [AI test generation](/ai-features/ai-test-generation#2-from-jira--azure-devops-tickets).
* **Close coverage gaps:** Use the **Gaps** tab to find requirements without a test, then add context and regenerate. See [Requirements coverage gaps](/ai-features/requirements-coverage-gaps).
* **Improve accuracy with application context:** Add a [Knowledge Base](/ai-features/knowledge-base) so the AI knows your login flow, navigation, and terminology before it generates.
* **Organize and schedule:** Add the approved cases to a suite and schedule them. See [Managing test suites](/web-testing/managing-test-suites) and [Tutorial: Build and schedule a regression suite](/execution/regression-suite-tutorial).
* **Run on every change:** Trigger the suite from your pipeline. See [GitHub Actions](/integrations/github-actions) or [Tutorial: CI/CD with GitHub Actions](/getting-started/ci-cd-tutorial).
## Related pages
* [AI test generation](/ai-features/ai-test-generation) — every generation source, including requirements, Jira, Figma, OpenAPI, and video
* [Creating test cases](/web-testing/creating-test-cases) — all four creation methods in the unified panel
* [Uploaded test files](/web-testing/uploaded-test-files) — manage imported files and their generated test cases
* [Requirements coverage gaps](/ai-features/requirements-coverage-gaps) — find and close gaps in generated coverage
* [Knowledge Base](/ai-features/knowledge-base) — give the AI application context for more accurate generation
{% hint style="info" %}
**Turn your requirements into tests — no code required.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see ContextQA generate a suite from your specifications.
{% endhint %}
# Requirements Coverage Gaps
How to review AI-identified coverage gaps in your uploaded requirements, inspect gap details with similarity scores, and accept or dismiss AI-suggested test cases.
## Quick answer
How to review AI-identified coverage gaps in your uploaded requirements, inspect gap details with similarity scores, and accept or dismiss AI-suggested test cases. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers, testers, and QA managers who upload requirement documents and want to identify which requirements lack adequate test coverage.
{% endhint %}
When you upload a requirements document, ContextQA's AI engine analyzes it against your existing test cases and identifies coverage gaps — requirements that are not yet tested or only partially covered. The **Gaps** tab shows these gaps with similarity scores, and you can accept AI-suggested test cases to close them.
***
## Prerequisites
* A ContextQA workspace with AI features enabled.
* At least one requirement document uploaded through the **Import Requirement** option (see [Creating Test Cases](/web-testing/creating-test-cases)).
* The uploaded file must have finished processing (status: **Completed** or **Pending Action**).
***
## Opening the requirements library
1. In the left navigation, go to **Assets → Requirements**.
2. The Requirements list displays all uploaded requirement documents with their status, test case count, and creation details.
3. Click a file name to open the file details view.
{% hint style="info" %}
**Filtering by test plan:** Use the test plan filter dropdown above the list to narrow results. Type to search across your test plans — the filter supports server-side search with pagination.
{% endhint %}
***
## Understanding file statuses
| Status | Meaning |
| ------------------ | -------------------------------------------------------------------------------------------------------------- |
| **Completed** | Processing finished. Test cases and gap analysis are available. |
| **Pending Action** | The AI needs clarification before generating test cases. Answer the questions or skip to generate immediately. |
| **Processing** | The file is still being analyzed. Refresh the page to check progress. |
| **Failed** | An error occurred during processing. Check the error details and re-upload if needed. |
***
## Answering AI clarification questions
When a file has **Pending Action** status, ContextQA's AI has questions about your requirements to improve test generation accuracy.
1. Click the file name. The **Help AI Understand Your Requirements** dialog opens.
2. Review each question. The AI provides context explaining why it needs this information.
3. Enter your answers in the text fields.
4. Click **Submit** to send your answers and start test generation.
To skip the questions, click **Skip & Generate Test Cases**. The AI generates test cases using its best interpretation of the requirements.
{% hint style="warning" %}
**Answering questions improves accuracy.** Providing answers helps the AI generate more relevant test cases and more accurate gap analysis. Skip only if the requirements are straightforward.
{% endhint %}
***
## Reviewing the gaps tab
Once a file finishes processing, the file details view shows multiple tabs. Select the **Gaps** tab to see AI-identified coverage gaps.
Each gap card displays:
* **Requirement identifier** — the requirement ID (e.g., REQ-001) and type tag.
* **Priority** — the assessed priority level of the gap.
* **Similarity score** — a percentage indicating how closely the requirement matches existing test cases. A lower score means less coverage.
* **Summary** — a brief description of what the gap covers and why it was flagged.
* **Missing prerequisites** — any prerequisites identified as missing from current test coverage.
### What the similarity score means
| Score range | Coverage level | Action needed |
| ----------- | ----------------- | --------------------------------------------- |
| 80–100% | Well covered | Review for edge cases only |
| 50–79% | Partially covered | Review suggested test cases |
| 0–49% | Poorly covered | Strongly consider adding suggested test cases |
{% hint style="info" %}
**No gaps found?** If the Gaps tab shows "No gaps found — All requirements are well covered," your existing test cases already provide adequate coverage for this requirements document.
{% endhint %}
***
## Inspecting gap details
1. On a gap card, click **View details**.
2. The gap detail drawer slides open from the right side of the screen.
The drawer displays:
* **Similarity score ring** — a visual indicator showing the coverage percentage with color coding (green for high, amber for medium, red for low).
* **Summary** — a detailed explanation of the coverage gap.
* **What's missing** — a list of specific items not covered by existing test cases.
* **AI-suggested test cases** — test cases the AI recommends creating to close the gap. Each suggestion includes a confidence badge indicating how well it addresses the gap.
Press **Esc** or click outside the drawer to close it.
***
## Accepting AI-suggested test cases
### Accept a single suggestion
1. Open the gap detail drawer for a gap.
2. Review the suggested test case details (title, steps, expected results).
3. Click **Add to Test Cases** on the suggestion you want to accept.
4. The test case is created and added to your test suite.
### Accept all suggestions for a gap
1. In the gap detail drawer, click **Add All** to accept every pending suggestion at once.
2. All suggested test cases are created and added to your test suite.
### Accept all suggestions from the gaps tab
1. On the Gaps tab, click **Add All Test Cases** to bulk-accept all AI suggestions across every gap.
2. All pending suggestions for the entire requirements document are created as test cases.
{% hint style="warning" %}
**Review before bulk accepting.** While the AI generates relevant suggestions, review the gap details and similarity scores before accepting all suggestions. Some may need manual refinement after creation.
{% endhint %}
### Dismissing a gap
If a gap is not relevant, click **Dismiss** in the gap detail drawer. The gap is removed from the active list.
***
## Viewing generated test cases
After accepting suggestions or once processing is complete, view the generated test cases:
1. In the file details view, select the **Test Cases** tab.
2. Test cases are grouped into two sections:
* **Newly Created Test Cases** — labeled "New," these are test cases generated from your requirements.
* **Existing Test Cases** — labeled "Duplicate," these match tests already in your repository.
3. Click a test case ID to open it in the test steps editor.
***
## Tips and best practices
* **Upload focused requirements documents.** Smaller, well-scoped documents produce more accurate gap analysis than large, broad documents.
* **Answer clarification questions.** Providing context improves both test generation and gap detection accuracy.
* **Review low-similarity gaps first.** Gaps with scores below 50% represent the largest coverage risks and should be addressed first.
* **Refine accepted test cases.** AI-generated test cases are a starting point. After accepting, review and adjust steps, test data, and assertions as needed.
* **Re-upload after major changes.** If your requirements change significantly, upload the updated document to get fresh gap analysis.
***
## Related pages
* [AI Test Generation](/ai-features/ai-test-generation)
* [Creating Test Cases](/web-testing/creating-test-cases)
* [Knowledge Base](/ai-features/knowledge-base)
* [Analytics Dashboard](/reporting/analytics-dashboard)
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# PR Impact Analysis
Use ContextQA PR Impact Analysis to map a GitHub pull request to affected, reusable, or missing tests with confidence and code-change evidence.
## Quick answer
ContextQA PR Impact Analysis reads a GitHub pull request, maps its code changes to the test repository, and produces a reviewable report grouped by recommended action. Start in **Settings → PR Impact Analysis**, define the base branch and path scope, then open a **PR Impact** row in **Assets → Requirements**. The initial production experience is an advisory, read-only report: it explains what is affected and why, but it does not change test cases or block the GitHub build.
## What this page covers
{% hint style="info" %}
**Who is this for?** QA engineers, SDETs, developers, and release owners who want change-based regression selection without relying on test names or tribal knowledge.
{% endhint %}
{% hint style="warning" %}
PR Impact Analysis is a limited-rollout capability. The settings route or PR Impact requirement type may be unavailable until ContextQA enables it for your workspace and connects an eligible GitHub repository.
{% endhint %}
## What PR Impact Analysis answers
For each pull request, the report answers three citation-friendly questions:
1. **Which tests are related to this change?** The report groups impacted tests by its recommended verdict.
2. **Why is each test included?** Expand a row to inspect code-change evidence, confidence, and the generated MCP prompt.
3. **How trustworthy is the recommendation?** The report identifies confidence and whether the match came from structural application mapping or semantic test knowledge.
This makes the analysis useful as both a release-review surface and an evidence trail for an AI agent preparing a regression run.
## Configure the analysis boundary
Open **Settings → PR Impact Analysis**.

The current settings page includes:
| Setting | What it controls |
| -------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Autonomy tier** | The operating mode. **Read** produces an advisory report and makes no test changes. Other tiers may be visible but are not part of the initial read-only rollout. |
| **Confidence threshold** | Recommendations below the threshold are held rather than treated as high-confidence guidance. |
| **Base branch filter** | Limits analysis to pull requests targeting the named branch, such as `main`. |
| **Max files per analysis** | Caps the files evaluated in one run. Reports beyond the limit are marked partial. |
| **Path scope** | One glob per line for the repository or monorepo subtree to include. |
| **Post PR comment** | Posts or updates the ContextQA summary on the pull request when enabled. |
| **Post GitHub check** | Adds an advisory GitHub check. The check does not fail the build. |
| **Suppress paths** | Excludes generated, vendor, or other noisy paths from analysis. |
{% hint style="info" %}
The settings snapshot is stored with an analysis so a reviewer can understand the boundary used at that time, even after an administrator changes the live configuration.
{% endhint %}
## How a pull request becomes a coverage report
```mermaid
flowchart LR
A[GitHub pull request updated] --> B{Matches base branch
and path scope?}
B -- No --> C[No analysis created]
B -- Yes --> D[ContextQA maps changed code
to test knowledge]
D --> E[PR Impact requirement]
E --> F[Overview: actions and confidence]
F --> G[Verdict tabs: impacted tests]
G --> H[Evidence, confidence, and MCP prompt]
H --> I[Reviewer selects the regression scope]
```
The GitHub comment is updated in place as the pull request changes, so reviewers do not need to follow a chain of obsolete comments. A newer commit can supersede an earlier analysis; ContextQA preserves the earlier report as history and links to the newer run.
## Review a PR Impact report
1. Open **Assets → Requirements**.
2. Find the row whose type is **PR Impact** and open its `REQ-` link.
3. Confirm the pull-request repository, target branch, commit range, author, and changed-file count in the header.
4. Read the **AI summary** and check for a **Partial** or **Superseded** notice.
5. Use **Overview** to review the recommended-action totals and average confidence.
6. Open each verdict tab to inspect the affected test cases.
7. Expand **Evidence, confidence & prompt** on a row.
8. Use the report to select or update the regression scope through your normal reviewed workflow.
The expanded row can show:
* the linked test-case ID and title;
* priority and confidence;
* the reason the test was associated with the change;
* relevant code-change evidence;
* whether the signal is structural or semantic; and
* a generated MCP prompt that an authorized AI agent can use as a starting point.
{% hint style="warning" %}
The initial production report is read-only. It does not approve, dismiss, edit, create, retire, or run a test by itself. Apply any change through the normal test-case approval and execution controls available in your workspace.
{% endhint %}
## Read the result safely
* Treat **high confidence** as stronger evidence, not as proof that the test will pass.
* A **semantic** match means the diff aligns with test knowledge; a **structural** match means the changed file maps to an exercised route or component.
* A **partial** report did not analyze every changed file. Review the unprocessed scope before using it as a release gate.
* **No behavioural change detected** is a valid result. Confirm the repository and path settings before assuming no regression is possible.
* A failed analysis offers retry and full-suite fallback actions; it should not produce a false empty report.
## FAQ
Does PR Impact Analysis change my test cases automatically?
Not in the initial read-only rollout. It produces recommendations, evidence, and an MCP prompt while leaving the test repository unchanged.
Does the GitHub check block a merge?
No. The current GitHub check is advisory and does not fail the build.
Why is a report marked partial?
The pull request exceeded the configured file limit or another analysis boundary. Review the report notice and expand the regression scope when needed.
## Related documentation
* [Requirements management](/web-testing/requirements-management)
* [Requirements coverage gaps](/ai-features/requirements-coverage-gaps)
* [GitHub Actions](/integrations/github-actions)
* [Running tests](/execution/running-tests)
* [MCP agent integration](/mcp-server/agent-integration-guide)
{% hint style="info" %}
**See AI change-impact analysis on your repository.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — Review how ContextQA turns a pull request into an evidence-backed regression scope.
{% endhint %}
# Autonomous Agent Pipeline
How ContextQA's autonomous AI agent pipeline executes tests across nine stages — navigate, discover, plan, execute, capture, assert, heal, report, and archive.
## Quick answer
How ContextQA's autonomous AI agent pipeline executes tests across nine stages — navigate, discover, plan, execute, capture, assert, heal, report, and archive. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — particularly engineers and QA leads who want to understand how ContextQA's AI pipeline executes tests, captures evidence, and self-heals broken steps.
{% endhint %}
When you run a ContextQA test case, an autonomous AI pipeline takes over. You do not run a script — you have a natural language description of what should happen, and ContextQA's AI pipeline figures out how to make it happen in a real browser.
This page explains each stage of that pipeline, what it does, and how it produces the evidence artifacts you see in test reports.

***
## Overview
Every test execution goes through the same pipeline in sequence:
```
URL + NLP Steps
↓
Stage 1: Navigation Agent
↓
Stage 2: Element Discovery Agent
↓
Stage 3: Intent Parser
↓
Stage 4: Action Executor
↓
Stage 5: Screenshot Agent
↓
Stage 6: Network Monitor ← runs continuously throughout execution
↓
Stage 7: Console Monitor ← runs continuously throughout execution
↓
Stage 8: Verification Agent ← activated for assertion steps
↓
Stage 9: Self-Healing Agent ← activated when element not found
↓
Evidence Package
(screenshots, video, HAR, console log, Playwright trace, AI reasoning)
```
Stages 6 and 7 run in parallel with the main pipeline throughout the entire execution. Stages 8 and 9 are conditional — they activate only when needed.
***
## Stage 1: Navigation Agent
The pipeline begins with the Navigation Agent, which opens a clean browser session and navigates to the test case URL.
**What it does:**
* Launches a headless Chromium (or specified browser) instance in a clean profile — no cookies, no cached state from previous runs
* Navigates to the test case URL
* Handles HTTP redirects automatically (301, 302, 307, 308)
* Waits for the page to reach a stable loaded state — specifically, waits for the `load` event and for network activity to go idle (no pending requests for 500ms)
* Captures the initial screenshot after the page is fully loaded
* Records the actual final URL (post-redirect) as the starting point
**Why this matters:** A clean browser session ensures test isolation. Each execution starts from the same known state regardless of what ran before it. If your application requires a logged-in starting state, the test steps themselves must include the login flow, or you can use a pre-requisite test case that establishes the session.
***
## Stage 2: Element Discovery Agent
Before executing any steps, the pipeline builds a comprehensive map of every interactive element on the current page.
**What it does:**
* Performs a full DOM traversal to identify all interactive elements: `button`, `input`, `select`, `textarea`, `a`, and elements with click handlers
* Applies visual AI to the screenshot to identify elements that may not be semantically marked up correctly (e.g., a `div` styled as a button)
* Analyzes the page to identify all interactive elements and prepares the AI agent for the next action.
* Stores the element map in memory for use by the Action Executor in Stage 4
The element map is refreshed automatically after any action that triggers a navigation or significant DOM change (detected by watching MutationObserver events).
***
## Stage 3: Intent Parser
The Intent Parser processes each natural language step and converts it into a structured action specification.
**What it does:**
* Reads the NLP step description (e.g., `"Click the Submit button"`)
* Classifies the action type: `navigate`, `click`, `type`, `select`, `scroll`, `hover`, `assert`, `wait`, `api_call`
* Identifies the target element reference from the step (e.g., `"Submit button"`)
* Extracts any data values embedded in the step (e.g., `"type 'admin@test.com' into the Email field"`)
* Resolves variable references if test data profiles are in use (e.g., `"{{username}}"` → the actual value from the data row)
* Produces a structured action object:
```json
{
"type": "click",
"target": "Submit button",
"target_confidence": 0.97,
"data_value": null,
"wait_before_ms": 0,
"wait_after_ms": 500
}
```
**Action types recognized:**
* `click` — single click on an element
* `double_click` — double click
* `right_click` — right-click (context menu)
* `type` — type text into a focused input
* `clear_and_type` — clear existing value and type new text
* `select` — choose an option from a dropdown
* `check` / `uncheck` — checkbox state
* `upload` — file upload input
* `scroll` — scroll the page or an element
* `hover` — hover over an element (for tooltips, dropdowns)
* `navigate` — navigate to a URL
* `assert` — verify a condition without performing an action
* `wait` — explicit wait for a condition or time
* `api_call` — make an HTTP request and assert the response
**Why this matters:** Separating intent parsing from action execution allows the pipeline to validate the full step sequence before beginning execution, flag any steps that are ambiguous or unrecognizable, and optimize the execution order where steps can be parallelized.
***
## Stage 4: Action Executor
The Action Executor performs the actual browser action using Playwright's automation API, guided by the structured action from Stage 3 and the element map from Stage 2.
**What it does:**
1. Receives the structured action from the Intent Parser
2. Looks up the target element in the pre-built element map from Stage 2
3. Attempts to locate the element in the live DOM using the highest-confidence locator strategy
4. If found: performs the action (click, type, select, etc.)
5. If not found on first attempt: tries alternative locators from the element map
6. If all locators fail: activates the Self-Healing Agent (Stage 9)
7. Waits for the post-action state to stabilize before returning control
**Locator fallback sequence:**
1. `data-testid` attribute match
2. ARIA label match
3. Exact visible text match
4. Partial visible text match
5. CSS selector from the element map
6. Visual match (screenshot-based element identification)
7. → Self-Healing Agent if all above fail
**Smart waiting:** Rather than using fixed `sleep()` calls, the Action Executor waits for meaningful signals: network idle (for actions that trigger API calls), DOM stability (for actions that modify the page structure), or specific element visibility (for assertions). This makes tests faster and more reliable than fixed-delay approaches.
***
## Stage 5: Screenshot Agent
A screenshot is captured automatically after every action in the pipeline.
**What it does:**
* Takes a full-page screenshot immediately after each action completes and the page stabilizes
* Generates a unique filename with the step number, action type, and timestamp
* Uploads the screenshot to S3 storage and returns a publicly accessible URL
* Also captures a screenshot on failure — specifically, captures the DOM state at the exact moment of failure, not just before the failing action
**Screenshot types captured:**
* **Pre-action**: the page state before an action (for complex assertion steps)
* **Post-action**: the page state after each action (stored as evidence for every step)
* **Failure screenshot**: captured immediately when an error occurs
* **Assertion screenshot**: for assertion steps, captures the specific region being verified when possible
**Why this matters:** Every test report in ContextQA shows a screenshot for each step. This means test failures are always visually evident — you can see exactly what the browser looked like when a step failed, which is far more useful than a stack trace or error message alone.
***
## Stage 6: Network Monitor
The Network Monitor runs as a parallel process throughout the entire execution, not just during specific steps.
**What it does:**
* Intercepts all outgoing HTTP/HTTPS requests made by the browser
* Captures request details: method, URL, headers, request body
* Captures response details: status code, headers, response body (up to 1MB)
* Flags requests that return 4xx or 5xx status codes
* Tracks API response times
* Writes the complete log to HAR (HTTP Archive) format
**Data captured per request:**
```json
{
"url": "https://api.myapp.com/orders",
"method": "POST",
"status": 200,
"duration_ms": 234,
"request_headers": {"Content-Type": "application/json", "Authorization": "Bearer "},
"request_body": {"item_id": "123", "quantity": 2},
"response_headers": {"Content-Type": "application/json"},
"response_body": {"order_id": "ORD-456", "status": "created"},
"timestamp": "2026-03-15T14:23:45.123Z"
}
```
**Why this matters:** Many test failures are caused by API errors, not UI problems. If a form submission fails silently (the page does not show an error but the data was not saved), the network log shows the failed API call immediately. This makes the HAR log one of the most valuable debugging artifacts for modern single-page applications.
The network log is accessible via the `get_network_logs` MCP tool after execution.
***
## Stage 7: Console Monitor
The Console Monitor also runs in parallel throughout the entire execution, capturing all browser console output.
**What it does:**
* Intercepts all console events: `console.log`, `console.warn`, `console.error`, `console.info`, `console.debug`
* Captures unhandled JavaScript exceptions and promise rejections
* Records the console message text, the originating file, and the line number
* Timestamps each entry to correlate with the execution timeline
**Error types captured:**
* JavaScript runtime errors (`TypeError`, `ReferenceError`, etc.)
* Unhandled promise rejections
* Application-level error logs
* Warning messages from frameworks (React, Angular, Vue deprecation warnings)
* Custom application logging
**Why this matters:** Frontend applications often log errors to the console when something goes wrong — errors that are invisible to the end user and do not cause obvious UI failures. A test that "passes" but generates multiple console errors may indicate latent bugs. The console log gives QA engineers visibility into JavaScript health that screenshot-based testing cannot provide.
The console log is accessible via the `get_console_logs` MCP tool after execution.
***
## Stage 8: Verification Agent
The Verification Agent is activated specifically for assertion steps — steps that check that something is (or is not) present, visible, or in a particular state.
**What it does:**
1. Receives the assertion description from the Intent Parser (e.g., `"verify the success message is visible"`)
2. Takes a screenshot of the current page state
3. Analyzes the screenshot + DOM state against the natural language assertion condition
4. Returns a pass/fail determination with a reasoning explanation
**Assertion types handled:**
| Assertion Pattern | Example |
| ------------------------ | ---------------------------------------------------- |
| Element visibility | "verify the Submit button is visible" |
| Element absence | "verify the error message is not displayed" |
| Text content | "verify the page title says 'Dashboard'" |
| Text contains | "verify the success banner contains 'Order placed'" |
| URL verification | "verify the URL contains '/dashboard'" |
| Count assertion | "verify at least 3 items appear in the list" |
| Input value | "verify the email field contains ''" |
| Checkbox state | "verify the Terms checkbox is checked" |
| Element enabled/disabled | "verify the Submit button is enabled" |
| Visual state | "verify the status indicator is green" |
**AI-powered assertions:** For assertions that are difficult to express as DOM queries (e.g., "verify the chart shows an upward trend"), the Verification Agent uses visual AI to analyze the screenshot directly. It returns a confidence score alongside the pass/fail result. Assertions below 0.70 confidence are flagged in the report for human review.
**Why this matters:** Natural language assertions are far more maintainable than XPath assertions like `//div[@class='alert alert-success']/span[contains(text(), 'Order')]`. When the implementation changes (different CSS class, different DOM structure), the natural language assertion still works as long as the visible state is correct.
***
## Stage 9: Self-Healing Agent
When the Action Executor cannot find the target element using any of its locator strategies, it activates the Self-Healing Agent.
**What it does:**
1. Receives the step description and the failed locator information
2. Takes a fresh screenshot of the current page state
3. Searches the current DOM and screenshot for elements that are visually or semantically similar to the target
4. Evaluates candidate elements to find the best match for the original test step.
5. Selects the best candidate if it meets the confidence threshold
**Healing outcomes:**
| Confidence Level | Action Taken |
| ---------------- | --------------------------------------------------------------------------------------- |
| High | Heal and continue: performs the action using the new locator, marks step as auto-healed |
| Medium | Heal with warning: performs the action but flags the step for review in the report |
| Low | Fail: marks the step as FAILED, shows the best candidate as a suggested fix |
**What counts as a healing:**
* Button text changed (e.g., "Save" → "Save Changes") — the text similarity matcher finds it
* Element moved to a different position on the page — the visual AI locates it in the new position
* CSS class renamed — the visual match finds the same visual element with the new class
* Element wrapped in an additional container — the DOM traversal finds it at a deeper path
**What cannot be healed:**
* Element genuinely removed from the page (intentionally deleted from the UI)
* Functionality moved to a completely different page
* Element hidden behind authentication or permissions that the test user lacks
* Complete page redesign where no equivalent element exists
**Reviewing healed steps:** In the test report, auto-healed steps are marked with a healing indicator. Click the step to see the original locator, the new locator, and the confidence level. You can accept the healing (which updates the test case definition permanently) or reject it (which reverts the step and marks it for manual review).
Healings can also be reviewed and applied via the MCP tools `get_auto_healing_suggestions` and `approve_auto_healing`.
***
## Evidence Package
Every execution produces a complete set of artifacts regardless of whether the test passed or failed:
### Per-Step Screenshots
`.jpg` images captured after every action. Stored in S3 with public URLs, retained for 90 days. Viewable in the test report step-by-step view or accessible via `get_execution_step_details`.
### Full Session Video
A `.webm` video recording of the entire browser session from first navigation to last action. The video is synchronized with the step timeline in the report — click any step to jump to that moment in the video. Retained for 30 days.
### Playwright Trace File
A `.zip` binary file in Playwright's trace format. Contains:
* Complete DOM snapshots before and after every action
* All network requests with full request/response data
* Console output synchronized with the action timeline
* Screenshots at every step
Viewable by uploading to [trace.playwright.dev](https://trace.playwright.dev) — no installation required. This is the deepest debugging artifact available. Access the URL via `get_trace_url`.
### HAR Network Log
A JSON file in HAR (HTTP Archive) format containing every network request and response made during the session. Import into Chrome DevTools, Fiddler, or any HAR viewer for network analysis. Access via `get_network_logs`.
### Browser Console Log
A JSON array of all console events: errors, warnings, info messages, and JavaScript exceptions. Access via `get_console_logs`.
### AI Reasoning Log
A JSON structure containing the AI's decision-making trace for every step: which element was targeted and what actions were taken. Access via `get_ai_reasoning`. Useful for diagnosing flaky tests where the AI sometimes makes different decisions.
***
## Execution Infrastructure
Tests run on managed cloud infrastructure:
* **Browser**: Chromium (default), Firefox, or WebKit (Safari)
* **OS**: Linux (Ubuntu 22.04) for browser tests; iOS/Android device farm for mobile
* **Isolation**: Each execution gets a clean container with a fresh browser profile
* **Concurrency**: Multiple tests can run in parallel (subject to your plan's concurrency limits)
* **Timeouts**: Default step timeout is 30 seconds; default total execution timeout is 30 minutes. Both are configurable per test case.
* **Geolocation**: Tests can be run from specific geographic regions if latency or geo-based routing is relevant to your tests
***
## How to Interpret a Failure
When a test fails, use the evidence package to diagnose it:
1. **Start with the failure screenshot** — it shows the browser state at the exact moment of failure. Often the cause is visually obvious: a modal blocking the target element, a validation error preventing form submission, or a loading spinner that never resolved.
2. **Check the network log** — if the screenshot looks correct but the test still failed, check whether an API call returned an error. A 500 on a form submission is often the real root cause.
3. **Check the console log** — if both the screenshot and network log look clean, a JavaScript exception may have broken client-side logic without any visible UI error.
4. **Use AI root cause analysis** — call `get_root_cause` via MCP or click the AI Insights button in the UI. The AI correlates all evidence sources and provides a plain-English explanation.
5. **Open the Playwright trace** — for complex failures where you need DOM-level detail, the trace file shows the exact DOM state before and after every action. Use it to verify that an element was in the expected state when an action was attempted.
## Related Pages
* [AI Test Generation](/ai-features/ai-test-generation) — generate test cases from 10+ sources
* [AI Self-Healing](/web-testing/self-healing) — how self-healing works in practice
* [Core Concepts](/getting-started/core-concepts) — platform building blocks
* [Custom Agents](/ai-features/custom-agents) — extend the pipeline with domain-specific agents
* [Test Results](/reporting/test-results) — interpret the evidence the pipeline produces
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# Knowledge Base
How to create and use Knowledge Base entries to teach ContextQA's AI agent how to handle application-specific UI patterns, consent banners, popups, and test-specific instructions.
## Quick answer
How to create and use Knowledge Base entries to teach ContextQA's AI agent how to handle application-specific UI patterns, consent banners, popups, and test-specific instructions. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — especially QA engineers who want to teach ContextQA's AI how to handle application-specific UI patterns, consent banners, popups, and test conventions.
{% endhint %}
A Knowledge Base is a set of plain-English instructions stored at the workspace level that the ContextQA AI agent reads before and during every test execution. It is the mechanism for encoding persistent, application-specific knowledge into the test engine — so you write the instruction once and every test in the workspace benefits automatically.
## Interactive demo: give the AI agent application context
See how a team records application-specific guidance once and makes it available to the ContextQA execution agent without embedding that guidance in every test case.
{% embed url="" %}
### What to notice
* Each entry describes one recurring application behavior in direct, actionable language.
* Workspace or run scoping controls where the context applies.
* Knowledge Base instructions explain how to use named data or secrets; they do not store the secret values themselves.
{% hint style="danger" %}
**A Knowledge Base is not a secret store.** Never paste a production password, API token, session cookie, private key, OTP seed, or recovery code into an entry. Knowledge Base text becomes AI context and is visible to users who can view or edit the entry. Put the value in an approved **Password** or **Vault** environment variable (or another organization-approved secret manager), and let the Knowledge Base describe *when and how to use the named secret* without containing the secret itself.
{% endhint %}
***
## Why You Need a Knowledge Base
The ContextQA AI agent is trained to test general web and mobile applications. But every production application has quirks: a GDPR consent modal that appears on first load, a live chat widget that opens over content, a feature tour that appears on every login, a staging-only banner that covers part of the UI.
Without guidance, the AI agent either attempts to interact with these overlays (causing false failures) or gets confused by them. With a knowledge base entry like *"If a cookie consent modal appears, click 'Accept All Cookies' before any other interaction"*, the AI handles it correctly on every run.
***
## Accessing the Knowledge Base
1. Open your ContextQA workspace.
2. In the left navigation, go to **Knowledge Base** (route: `/td/:versionId/Knowledge_Base`).
3. The Knowledge Base list shows all entries for this workspace.
> **Access note:** Knowledge Base requires a plan that includes AI features. If the Knowledge Base menu item is grayed out or missing, contact your workspace administrator.
***
## Creating a Knowledge Base Entry
1. From the Knowledge Base list, click **+ New Knowledge Base**.
2. Enter a **Title** — a short label describing what this entry handles (e.g., "Cookie consent banner", "Chat widget dismissal", "Payment test card").
3. Enter the **Prompt** — the plain-English instruction the AI will follow. See the [Writing Effective Prompts](#writing-effective-prompts) section below.
4. Click **Save**.
The entry is immediately active for all test executions in this workspace.
***
## Writing Effective Prompts
The AI interprets prompts as instructions to follow whenever the described condition is encountered. Write prompts as imperative sentences.
### ✅ Good prompt patterns
| Situation | Prompt |
| ---------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Cookie consent modal | `If a cookie consent banner, GDPR notice, or privacy consent dialog is visible, click the button labelled "Accept All Cookies" or "Accept" immediately before any other action.` |
| Live chat widget | `If a live chat widget, help bubble, or Intercom button opens in the bottom corner of the screen, close it by clicking the X or minimize button before interacting with other page elements.` |
| Feature tour / product walkthrough | `If a product tour, onboarding guide, or "Get started" wizard appears as an overlay or modal, click "Skip", "Dismiss", or "Close" to exit it before proceeding.` |
| Test payment data | `On a payment form in the sandbox environment, use the approved payment-test values selected from the environment data picker. Never submit a live card or bank account.` |
| Two-factor authentication | `If the staging sign-in flow requests a one-time code, retrieve it through the approved test-mailbox or TOTP workflow. Do not ask a person to paste a reusable seed into the test.` |
| Loading indicators | `If a loading spinner, skeleton screen, or "Please wait" overlay is present, wait for it to disappear before interacting with the page.` |
### ❌ Avoid these patterns
| Anti-pattern | Why it fails |
| --------------------------------- | ------------------------------------------------------------------------ |
| `Handle cookie popups` | Too vague — the AI doesn't know what "handle" means |
| `The app sometimes shows a popup` | Not an instruction; no action specified |
| `Be careful on the payment page` | Ambiguous — no concrete behavior described |
| `Click X to close the chat` | Too specific — the selector may change; describe the widget type instead |
### Prompt length and scope
* Keep each knowledge base entry focused on **one specific situation**.
* For complex applications, create multiple entries (one per pattern) rather than one long combined entry.
* The AI reads all entries before each run, so there's no performance cost to having many entries.
### Referencing credentials safely
Use this division of responsibility:
| Store here | Example |
| --------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Knowledge Base** | `For the staging admin flow, use the credential fields named stageAdminUser and stageAdminPassword from the selected environment.` |
| **Environment & Data → environment variable** | The actual username as a String and password as a **Password** or **Vault** value. |
| **Test step** | Insert the approved value with the environment-data picker; do not type the literal credential into the action text. |
Secret values are masked where the selected secret type supports masking, but names, descriptions, Knowledge Base text, and literal step text are not automatically redacted. Before sharing screenshots, videos, logs, traces, exported data, or AI output, verify that no secret is visible. Access to an entry follows workspace permissions; keep entries scoped to the smallest appropriate workspace and remove obsolete instructions.
If a test needs an OTP, magic link, or temporary token, retrieve it at runtime from an approved test-only source. Store only the resulting short-lived value in a runtime variable, and never preserve the reusable seed or long-lived token in the Knowledge Base.
***
## Scoping Knowledge Bases to Specific Runs
When a knowledge base is workspace-scoped, it applies to every test execution. To apply a knowledge base only to specific runs:
1. When executing a test case, click the **Settings** icon next to Run.
2. Under **Knowledge Base**, select the specific entry to apply.
3. Click Run.
Via the MCP server:
```python
execute_test_case(
test_case_id=18688,
knowledge_id="kb_abc123" # ID from list_knowledge_bases()
)
```
Use `list_knowledge_bases()` to retrieve the ID for a specific entry.
***
## Managing Knowledge Base Entries
| Action | How |
| ------------------------ | ---------------------------------------------------------------- |
| Edit an entry | Click the entry name → Edit |
| Delete an unused entry | Click the three-dot menu → Delete, then confirm the warning |
| Disable without deleting | Not directly supported — delete and recreate when needed |
| Duplicate | Not directly supported — create a new entry with similar content |
ContextQA blocks deletion when a knowledge base is still referenced by a test case, test plan, or organization default. Remove or replace those references first, then retry the deletion. If an older result or record points to a knowledge base that no longer exists, the UI displays **None** rather than a stale identifier.
{% hint style="warning" %}
Deleting a knowledge base is permanent. Before deletion, search shared test cases and plans for references and confirm that **Settings → Organization Setting → AI Configuration → Default Knowledge Base** does not select it.
{% endhint %}
***
## MCP Tools for Knowledge Bases
| Tool | Use |
| ------------------------------------- | ------------------------------------------------ |
| `list_knowledge_bases` | Get all knowledge bases and their IDs |
| `create_knowledge_base` | Create a new knowledge base programmatically |
| `execute_test_case(knowledge_id=...)` | Attach a knowledge base to a single test run |
| `execute_test_plan(knowledge_id=...)` | Attach a knowledge base to a full plan execution |
### Create via MCP
```json
{
"title": "Cookie consent banner",
"prompt": "If a cookie consent banner, GDPR notice, or privacy consent dialog is visible, click the button labelled Accept All Cookies or Accept immediately before any other action."
}
```
***
## Common Use Cases
### E-commerce applications
```
If a promotional popup or discount offer modal appears, close it by clicking the X button or "No thanks" link before interacting with the main content.
```
### SaaS applications with onboarding
```
If a feature announcement modal, "What's new" dialog, or onboarding checklist panel is visible when you arrive on a page, click Dismiss, Close, or X to close it before proceeding with the test.
```
### Multi-tenant applications
```
When the application asks to select a tenant or organization, always select "Test Organization" from the dropdown.
```
### Staging environments
```
If a staging environment banner or "Test mode" notice appears at the top of the screen, ignore it and proceed with the test. Do not click on it.
```
***
## Related Pages
* [Custom Agents](/ai-features/custom-agents)
* [AI Test Generation](/ai-features/ai-test-generation)
* [Running Tests](/execution/running-tests)
* [Test Plans](/web-testing/test-plans)
* [System Configuration](/administration/system-configuration)
* [MCP: list\_knowledge\_bases](/mcp-server/tool-reference/telemetry-and-agents)
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# Tutorial: Configure a Knowledge Base
Create ContextQA Knowledge Base entries for application-specific behavior, then verify that the AI follows the instructions during test execution.
## Quick answer
Create ContextQA Knowledge Base entries for application-specific behavior, then verify that the AI follows the instructions during test execution. Follow the documented prerequisites and steps, then verify the expected result before using the workflow in a shared or production process.
## What this page covers
{% hint style="info" %}
**Who is this for?** Testers, SDETs, and QA managers who want to reduce false test failures caused by cookie banners, chat widgets, onboarding tours, and other application-specific UI patterns.
{% endhint %}
Every web application has patterns that trip up automated testing — a GDPR consent banner that covers the page on first load, a live chat widget that floats over buttons, a product tour that hijacks clicks. Without guidance, the ContextQA AI agent either interacts with these overlays by mistake or gets blocked by them, causing false failures.
In this tutorial, you create two Knowledge Base entries that teach the AI to handle these patterns automatically. By the end, every test in your workspace benefits from these instructions without any changes to individual test cases.
**What you will accomplish:**
1. Create a Knowledge Base entry for handling cookie consent banners
2. Create a second entry for dismissing live chat widgets
3. Set one entry as the workspace default
4. Run a test case with the knowledge base attached and verify the AI follows your instructions
**Time:** 10 minutes
***
## Prerequisites
* A ContextQA account with a plan that includes AI features (the **Knowledge Base** menu item is visible in your left sidebar)
* At least one existing test case in your workspace — if you have not created one yet, complete the [Quickstart Guide](/getting-started/quickstart) first
* A test case that targets an application with a cookie consent banner or chat widget (to see the knowledge base in action)
***
## Step 1: Navigate to the knowledge base
1. Sign in to ContextQA and open your workspace.
2. In the left sidebar, click **Knowledge Base** (under the Test Plan & Results section).
The Knowledge Base list page opens. If this is your first time here, the page displays an empty state with the message "No data available."
{% hint style="info" %}
If **Knowledge Base** is grayed out or missing from the sidebar, your current plan does not include AI features. Contact your workspace administrator to upgrade.
{% endhint %}
***
## Step 2: Create your first entry — cookie consent banner
This entry teaches the AI to dismiss cookie consent banners before interacting with the page.
1. Click the **+ Add** button in the top-right corner of the page.
2. The **Create Knowledge Base** dialog opens with two required fields.
3. In the **Name** field, enter:
```
Cookie consent banner
```
4. In the **Description** field, enter:
```
If a cookie consent banner, GDPR notice, or privacy consent dialog
is visible on the page, click the button labelled "Accept All Cookies"
or "Accept" immediately before any other interaction. If no accept
button is visible, click "Close" or the X button to dismiss the banner.
```
5. Click **Save**.
A success notification confirms "Prompt was successfully created." The entry now appears in the Knowledge Base list.
**Verification:** The list shows one row with the name "Cookie consent banner" in the **Name** column.
***
## Step 3: Create a second entry — live chat widget
Repeat the process to handle live chat widgets that float over page content.
1. Click the **+ Add** button again.
2. In the **Name** field, enter:
```
Live chat widget dismissal
```
3. In the **Description** field, enter:
```
If a live chat widget, help bubble, or Intercom-style messenger button
opens or expands in the bottom corner of the screen, close it by clicking
the X or minimize button before interacting with other page elements.
Do not type into the chat input field.
```
4. Click **Save**.
**Verification:** The list now shows two entries. Both have a toggle in the **Status** column, but neither is marked as the default yet.
***
## Step 4: Set a default entry
The default Knowledge Base entry applies automatically to test executions. Only one entry can be the default at a time.
1. In the Knowledge Base list, find the **Cookie consent banner** row.
2. Click the toggle switch in that row.
A success notification confirms "Prompt was successfully set as default." The **Status** column now displays a **Default Prompt** badge next to the cookie consent entry.
**Verification:** The "Cookie consent banner" row shows a blue **Default Prompt** badge. The "Live chat widget dismissal" row has no badge — it is available for manual selection but does not apply automatically.
{% hint style="info" %}
To remove the default, click the toggle again. The tooltip changes from **Deactivate** (when on) to **Set as Default** (when off).
{% endhint %}
***
## Step 5: Run a test with your knowledge base
Now verify that the AI follows your instructions during execution. You can attach a knowledge base entry in two ways: through the default (which already applies) or by selecting a specific entry at execution time.
### Option A: Run with the default (automatic)
Since you set "Cookie consent banner" as the default in step 4, it applies to every execution in this workspace automatically.
1. Navigate to **Test Development** in the left sidebar.
2. Select an existing test case that targets an application with a cookie banner.
3. Click the **Run** button to execute the test.
The AI reads the default Knowledge Base entry before the run begins and follows the instruction when it encounters a cookie consent banner.
### Option B: Select a specific entry at execution time
To use a different entry (for example, the chat widget entry) for a single run:
1. In the test case details view, click the **Settings** icon next to the **Run** button.
2. In the execution settings, find the **Knowledge Base** dropdown.
3. Select **Live chat widget dismissal** from the list.
4. Click **Run**.
This overrides the default for this specific execution only. Future runs still use the workspace default.
***
## Step 6: Verify the AI followed your instructions
After the execution completes:
1. Open the execution results (click **View Report** or navigate to the result from the **Results** list).
2. Review the step-by-step screenshots. Look for the moment where the cookie banner or chat widget appeared.
3. Confirm the AI dismissed the overlay before continuing with the test steps.
**Signs it worked:**
* The cookie consent banner appears in an early screenshot and is gone in the next one — the AI clicks "Accept" without being told to in the test steps
* The test did not fail on a step that an overlay blocked
* No step interacted with the chat widget or cookie banner by mistake
**Signs it did not work:**
* A step failed because the AI clicked the banner instead of the intended element — refine the prompt wording to be more specific about which button to click
* The banner is still visible in later screenshots — the AI did not detect it; try adding alternative button labels to the description (for example, "I agree", "Got it", "OK")
***
## Summary
You created two Knowledge Base entries that teach the ContextQA AI to handle common UI obstacles:
| Entry | What it handles | Scope |
| -------------------------- | ------------------------------------ | --------------------------------------- |
| Cookie consent banner | GDPR and cookie consent dialogs | Workspace default (applies to all runs) |
| Live chat widget dismissal | Chat widgets that float over content | Manual selection (apply per-run) |
These entries persist at the workspace level — every team member and every test benefits from them without modifying individual test cases.
***
## Next steps
* **Add more entries** for other patterns in your application — onboarding tours, promotional popups, staging banners, MFA codes for test environments
* **Use the knowledge base with AI test generation** — when creating a test case with AI assistance, expand **Advanced Settings** and select a Knowledge Base entry to give the AI context during generation
* **Attach a knowledge base to a test plan** — in test plan settings, select a Knowledge Base entry under the **Knowledge Base** dropdown so every execution in the plan uses it automatically
* **Manage entries programmatically** — use the MCP tools `list_knowledge_bases` and `create_knowledge_base` to manage entries from AI agents or CI scripts
***
## Writing effective knowledge base entries
As you add more entries, follow these guidelines:
| Do | Avoid |
| ------------------------------------------------------------------------ | ------------------------------------------------------------------ |
| Write imperative instructions: "Click the Accept button" | Vague descriptions: "Handle the popup" |
| Describe the visual pattern: "a banner at the top of the page" | Over-specific selectors: "Click the element with id='consent-btn'" |
| Specify the action and the target: "Close the chat widget by clicking X" | Ambiguous instructions: "Be careful on this page" |
| Keep each entry focused on one pattern | Combining multiple patterns in a single entry |
***
## Related pages
* [Knowledge Base](/ai-features/knowledge-base) — full reference for Knowledge Base features and MCP tools
* [Custom Agents](/ai-features/custom-agents) — create specialized AI agents with domain-specific testing instructions
* [AI Test Generation](/ai-features/ai-test-generation) — generate test cases from Jira tickets, Figma designs, and more
* [Running Tests](/execution/running-tests) — execution options and settings
* [Quickstart Guide](/getting-started/quickstart) — create and run your first test case
{% hint style="info" %}
**Reduce false failures with AI that understands your application.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) to see the Knowledge Base in action with your application.
{% endhint %}
# Custom Agents
How to create custom AI agent personas in ContextQA to calibrate test execution behavior for specialized application domains such as Salesforce, accessibility testing, or localization.
## Quick answer
How to create custom AI agent personas in ContextQA to calibrate test execution behavior for specialized application domains such as Salesforce, accessibility testing, or localization. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — particularly SDETs and QA engineers who need domain-specific AI behavior for Salesforce, accessibility testing, financial applications, or other specialized domains.
{% endhint %}
A Custom Agent is a named AI persona with a domain-specific system prompt that shapes how the AI agent behaves during test execution. While the default ContextQA AI agent is calibrated for general web and mobile testing, custom agents let you tune the behavior for specialized application types, testing methodologies, or organizational conventions.
***
## When to Use Custom Agents
Use a custom agent when the default AI agent's behavior is not optimal for your domain:
| Scenario | What custom agent solves |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------ |
| Salesforce Lightning UI | Teaches the agent to recognize Lightning component naming patterns, handle record pages, and navigate App Launcher |
| Accessibility testing | Instructs the agent to flag missing ARIA labels, poor color contrast, and keyboard navigation issues on every page |
| Localization / RTL apps | Calibrates the agent for right-to-left layouts and non-ASCII character handling |
| Financial applications | Encodes domain knowledge about currency formatting, decimal precision, and financial calculation validation |
| Healthcare / EHR systems | Trains the agent on clinical workflow patterns (patient records, order entry, clinical notes) |
| Internal tools with unusual UX | Encodes institutional knowledge about non-standard UI patterns specific to your internal applications |
Custom agents are applied per execution — you choose which agent to use when triggering a test case or test plan.
***
## Accessing Custom Agents
1. Open your ContextQA workspace.
2. In the left navigation, go to **Custom Agents** (route: `/td/:versionId/custom_agents`).
3. The Custom Agents list shows all personas for this workspace.
> **Access note:** Custom Agents requires a plan with advanced AI features. Contact your workspace administrator if this option is not visible.
***
## Creating a Custom Agent
1. From the Custom Agents list, click **+ New Agent**.
2. Enter a **Name** — a descriptive label (e.g., "Salesforce Lightning Agent", "Accessibility Auditor").
3. Enter the **Description / System Prompt** — plain-English behavioral instructions for this persona.
4. Click **Save**.
The agent is now available for selection when executing test cases and test plans.
***
## Writing Effective Agent Descriptions
The agent description (system prompt) tells the AI how to behave throughout the test execution. Think of it as a job description for a specialized QA engineer.
### ✅ Effective agent descriptions
**Salesforce Lightning Agent:**
```
You are a Salesforce QA engineer specialized in testing Lightning Experience.
- When navigating Salesforce, use the App Launcher (grid icon in the top-left) to open applications.
- Record pages use a two-column layout; the related lists are in the right column.
- Lightning component IDs include random strings — match components by their visible label text, not by ID.
- Use the Global Search bar at the top for navigating to records. Enter a search term, wait for autocomplete, then select the correct record type.
- When creating or editing records, look for the "Save" button in the top-right of the record form.
- If Salesforce shows a "Mixed Content Warning" or "Enhanced Security" prompt, click Allow.
```
**Accessibility Auditor:**
```
You are an accessibility testing specialist. In addition to executing test steps, perform these checks on every page:
- Check that all images have meaningful alt text (not empty or "image").
- Verify that all interactive elements (buttons, links, form fields) are reachable via Tab key navigation.
- Flag any text that appears to have insufficient contrast against its background.
- Confirm that form fields have visible labels or aria-label attributes.
- Report any ARIA roles or aria-* attributes that appear misapplied.
Add accessibility findings as additional observations in your step results.
```
**Financial Application Agent:**
```
You are a QA engineer testing a financial services application.
- All monetary values should be formatted with two decimal places and appropriate currency symbols.
- When comparing calculated totals, allow for rounding differences of ±$0.01.
- When entering test amounts, always use even dollar values (e.g., $100.00, $250.00) unless the test case specifically requires fractional cents.
- When the application shows an "Are you sure?" confirmation before submitting financial transactions, always confirm.
- The "pending" state in transaction lists is expected and should not be treated as an error.
```
### ❌ Anti-patterns
* **Too short:** `"Test the application carefully."` — provides no actionable guidance.
* **Contradictory:** Including both "click Accept on all dialogs" and "dismiss unexpected dialogs" creates conflicting behavior.
* **Overly rigid selectors:** `"The submit button has ID btn-submit-9xa3"` — these IDs change and will cause failures after the next deploy.
***
## Using a Custom Agent in Test Executions
### Via the portal
1. Open a test case and click **Run**.
2. In the execution settings panel, select a **Custom Agent** from the dropdown.
3. Click **Execute**.
### Via the MCP server
```python
# Get available agent IDs
agents = list_custom_agents() # returns [{id: "agent_abc123", name: "Salesforce Lightning Agent"}, ...]
# Execute with a specific agent
execute_test_case(
test_case_id=18688,
persona_id="agent_abc123"
)
# Execute a test plan with a custom agent
execute_test_plan(
test_plan_id=42,
persona_id="agent_abc123"
)
```
***
## Combining Custom Agents with Knowledge Bases
Custom agents and knowledge bases serve complementary purposes:
| Feature | Purpose | Scope |
| ------------------ | -------------------------------------------------------------------------------------- | -------------------------------------- |
| **Custom Agent** | *How* the AI behaves (domain expertise, testing methodology) | Applied per execution |
| **Knowledge Base** | *What* the AI should do when specific situations arise (close banners, use test cards) | Applied per workspace or per execution |
Best practice: Use the custom agent for domain-wide behavioral calibration, and knowledge base entries for specific recurring UI situations.
```python
execute_test_plan(
test_plan_id=42,
persona_id="agent_abc123", # Salesforce domain expertise
knowledge_id="kb_xyz789" # "Close session warning modals"
)
```
***
## MCP Tools for Custom Agents
| Tool | Purpose |
| ----------------------------------- | ----------------------------------- |
| `list_custom_agents` | List all agents and get their IDs |
| `create_custom_agent` | Create a new agent programmatically |
| `execute_test_case(persona_id=...)` | Apply an agent to a test case run |
| `execute_test_plan(persona_id=...)` | Apply an agent to a test plan run |
### Create via MCP
```json
{
"name": "E-Commerce Checkout Agent",
"description": "You are a QA engineer specialized in e-commerce checkout flows. When testing checkout: always use the test credit card 4111111111111111 with any future expiry date and CVV 123. When prompted about address verification, select the 'Use entered address' option. After submitting an order, wait up to 15 seconds for the order confirmation number to appear before considering the step failed."
}
```
***
## Managing Custom Agents
| Action | How |
| --------------- | ------------------------------------------------------------------------------------------------------------- |
| Edit an agent | Click the agent name → Edit description |
| Delete an agent | Click the three-dot menu → Delete |
| Test an agent | Run a representative test case with the agent selected; review the execution video for behavioral differences |
***
## Related Pages
* [Knowledge Base](/ai-features/knowledge-base)
* [AI Test Generation](/ai-features/ai-test-generation)
* [Running Tests](/execution/running-tests)
* [MCP: list\_custom\_agents](/mcp-server/tool-reference/telemetry-and-agents)
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# AI Context Graph
ContextQA AI context graph — how ContextQA builds and applies accumulated application knowledge through UI Elements, Knowledge Bases, Custom Agents, and AI Data Analyst.
## Quick answer
ContextQA AI context graph — how ContextQA builds and applies accumulated application knowledge through UI Elements, Knowledge Bases, Custom Agents, and AI Data Analyst. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** All roles — engineers, QA managers, and technical leads who want to understand how ContextQA builds and applies accumulated application knowledge to improve test accuracy over time.
{% endhint %}
> **AI context graph:** The conceptual model describing how ContextQA accumulates, organizes, and applies knowledge about an application under test — combining element repository data, explicitly authored knowledge bases, domain-specific custom agents, and natural-language query capabilities into a unified application intelligence layer.
AI-powered test automation is only as good as the AI's understanding of the application it is testing. A generic AI that knows nothing about your application's domain, terminology, or UI patterns will produce brittle tests and poor failure analysis. ContextQA addresses this through a layered knowledge model that grows over time. This page describes each layer of that model and how they work together.
## What is the AI context graph?
"Context graph" is a conceptual term for the sum of knowledge ContextQA holds about a specific application under test. The UI does not have a single screen labeled "Context Graph." Instead, the knowledge is distributed across four components that each contribute a different dimension of understanding:
1. **UI Elements repository** — machine-learned knowledge about the application's interface
2. **Knowledge Bases** — human-authored domain knowledge provided to the AI
3. **Custom Agents** — domain-specific AI personas with tailored reasoning behavior
4. **AI Data Analyst** — a natural-language interface for querying the accumulated test data
Together, these components give ContextQA an increasingly accurate model of what your application does, how it behaves, and what failures mean in context.
## UI Elements: machine-learned interface knowledge
Every time ContextQA executes a test case, it observes the application's DOM, records element attributes, and updates the element repository. The repository stores selectors, element types, labels, and contextual relationships between elements.
This accumulated element data is accessible at **Settings → UI Elements** (route: `/td/:versionId/elements`). The UI Elements view shows every element ContextQA has encountered during executions, along with its selector history and the test cases that interact with it.
This repository is the foundation of ContextQA's self-healing capability. When an element changes — its ID, class, or position shifts between deployments — ContextQA searches the element repository to find the best matching selector, rather than treating the change as a hard failure. The more executions ContextQA has run against an application, the richer the element repository becomes, and the more accurate self-healing is.
The element repository also informs test generation. When ContextQA generates test cases from requirements or Figma designs, it consults the element repository to use selectors that are already known to work, rather than generating selectors from scratch.
## Knowledge Bases: human-authored domain context
The UI Elements repository captures structural knowledge about the interface. Knowledge Bases capture semantic knowledge about the application's domain — business rules, terminology, test patterns, and application-specific conventions that the AI cannot infer from DOM observation alone.
A Knowledge Base is a structured document that you provide to ContextQA to inform its AI reasoning. Examples of what a Knowledge Base might contain:
* **Business rule documentation:** "A checkout is only valid if the user has confirmed their email address. Tests that check checkout behavior should always begin with a verified user account."
* **Terminology glossary:** "In this application, 'account' refers to a merchant account, not a customer account. Customer-facing concepts use 'profile' instead."
* **Known limitations:** "The date picker component on the scheduling page requires a two-step interaction: first click the field to open the calendar, then click the date. Clicking the date without opening the calendar first will not work."
* **Test data conventions:** "All test users use the email pattern `testuser+@example.com`. The password is always the same across test environments."
To create a Knowledge Base:
1. Use the `create_knowledge_base` MCP tool, providing the name and content.
2. Alternatively, navigate to the Knowledge Bases section in the portal and use the creation form.
Once created, a Knowledge Base is referenced by ContextQA's AI when generating tests, analyzing failures, and making self-healing decisions for the associated application version. The `list_knowledge_bases` MCP tool returns all configured knowledge bases for the current project.
Knowledge Bases are versioned alongside your application. As your application evolves, update the relevant knowledge bases to reflect changes in business rules or UI conventions. Stale knowledge bases can mislead the AI — treat them with the same discipline as code documentation.
## Custom Agents: domain-specific AI personas
Custom Agents extend the context graph with behavioral directives. Where a Knowledge Base provides facts, a Custom Agent provides a persona — a specific reasoning approach, tone, or domain focus that shapes how the AI operates when that agent is active.
A Custom Agent might specify:
* "When analyzing failures in the payment flow, prioritize checking network response codes before examining DOM state."
* "When generating tests for the admin panel, always include negative test cases for permission boundaries."
* "Use the language and terminology of an insurance underwriter when describing test scenarios in this project."
Create a Custom Agent with the `create_custom_agent` MCP tool. List existing agents with `list_custom_agents`. Custom Agents can be assigned to specific test suites or used as defaults for particular application areas.
The combination of a rich Knowledge Base and a well-defined Custom Agent gives ContextQA a domain-specific reasoning context that significantly improves the relevance of AI-generated test cases and failure analyses compared to using the generic AI without customization.
## AI Data Analyst: querying accumulated knowledge
The AI Data Analyst provides a natural-language interface for querying the test data and execution history that ContextQA has accumulated. Access it at:
**Route:** `/td/:versionId/AI_Data_Analyst`
Rather than navigating through report pages and filtering tables, you can ask questions directly:
* "Which test cases have failed more than three times in the last two weeks?"
* "What is the pass rate for the checkout flow test suite this month versus last month?"
* "Show me the test cases that are most often classified as flaky failures."
* "What is the average execution time for test plan 'Nightly Regression'?"
The AI Data Analyst formulates and executes the appropriate data queries based on your natural-language input and returns structured answers with supporting data. It also has access to the Knowledge Base content for your application, so it can interpret query results in the context of your domain.
The `query_contextqa` MCP tool provides programmatic access to the same querying capability — useful for building custom reporting integrations or populating dashboards with AI-interpreted test data.
## How the layers combine
The power of the context graph is in the combination of layers:
* **Execution data → UI Elements** — Each test run refines element knowledge, making future runs more resilient.
* **Knowledge Bases → AI reasoning** — Domain facts improve test generation accuracy and failure interpretation.
* **Custom Agents → behavior** — Persona directives shape how the AI applies its knowledge in specific contexts.
* **AI Data Analyst → insight** — Natural-language querying makes the accumulated data accessible without requiring BI tools or SQL knowledge.
A new ContextQA project starts with minimal context. After dozens of executions, a few well-authored Knowledge Bases, and a custom agent scoped to the application's domain, ContextQA's AI operates with a model of the application that is meaningfully differentiated from a generic AI assistant.
## Frequently Asked Questions
### Does the UI actually show something called a "context graph"?
No. "Context graph" is a conceptual label for the combined knowledge model. The individual components — UI Elements, Knowledge Bases, Custom Agents, and AI Data Analyst — each have their own portal locations. There is no single "context graph" screen.
### How often should I update my Knowledge Bases?
Update a Knowledge Base whenever a significant application change affects the facts it contains — for example, a renamed feature, a changed business rule, or a new UI convention. A practical cadence is to review Knowledge Bases at the end of each sprint and update anything that has changed during that sprint's development work.
### Can multiple Custom Agents be active at the same time?
A single Custom Agent is typically assigned per test suite or application area. Using multiple conflicting agents simultaneously can produce inconsistent AI behavior. Design agents to be complementary and assign each to a specific scope rather than stacking agents with overlapping directives.
### What data does the AI Data Analyst have access to?
The AI Data Analyst has access to execution history, test case pass/fail data, failure categories, execution timing, and Knowledge Base content for the current application version. It does not have access to the raw application data under test, only to ContextQA's own test execution records.
## Related
* [Knowledge base configuration](/ai-features/knowledge-base)
* [Custom agents](/ai-features/custom-agents)
* [AI test generation](/ai-features/ai-test-generation)
* [Autonomous agent pipeline](/ai-features/autonomous-agent-pipeline)
* [Failure analysis and root cause](/reporting/failure-analysis)
* [Flaky test detection](/reporting/flaky-test-detection)
{% hint style="info" %}
**70% less human effort with AI test generation and self-healing.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See AI generate, execute, and maintain tests for your application.
{% endhint %}
# Interactive Demo
See how ContextQA generates complete, executable test cases from a URL and plain-English description in under 30 seconds — no code required.
## Quick answer
See how ContextQA generates complete, executable test cases from a URL and plain-English description in under 30 seconds — no code required. Use this page to preview the workflow and its visible results before following the linked written instructions.
## What this page covers
Describe what you want to test in plain English, point ContextQA at your application URL, and the AI generates structured, ready-to-run test cases automatically. This demo walks through the full workflow from input to execution.
{% tabs %}
{% tab title="From URL" %}
{% stepper %}
{% step %}
### Describe Your Test
Provide the application URL and a plain-English description of what you want to test. Optionally give the test case a name.
**Example input:**
* **URL:** `https://demo.contextqa.com/login`
* **Description:** Verify that a user can log in with valid credentials and see the dashboard. Then navigate to the Reports section and verify at least one report is visible.
* **Test Case Name:** Login and access Reports
{% hint style="info" %}
**AI Agent:** Accepts free-form test descriptions — no structured syntax or scripting required. Also supports Jira ticket, Swagger spec, or Figma design as the source.
{% endhint %}
{% endstep %}
{% step %}
### AI Generates Steps
ContextQA navigates to the target URL, analyzes the page structure, parses your description, and generates individual test steps automatically.
**Generation log (live):**
```
→ Navigating to https://demo.contextqa.com/login
→ Analyzing page structure and UI elements…
✓ Found: Email field, Password field, Sign In button
→ Parsing test description…
→ Generating step 1/5: Navigate to login URL
→ Generating step 2/5: Enter email credentials
→ Generating step 3/5: Enter password
→ Generating step 4/5: Click Sign In button
→ Generating step 5/5: Verify dashboard text
✓ Test case #18750 created (5 steps)
→ Discovering Reports navigation flow…
✓ Test case #18751 created (3 steps)
✓ Generation complete — 2 test cases, 8 steps total
```
{% hint style="info" %}
**AI Agent:** Automatically discovers UI elements on the page and maps them to the natural language steps in your description.
{% endhint %}
{% endstep %}
{% step %}
### Review & Run
Two test cases are generated and ready to review, edit, or execute immediately.
**TC #18750 — Login with valid credentials** (5 steps)
1. Navigate to `https://demo.contextqa.com/login`
2. Enter email in the Email field
3. Enter password in the Password field
4. Click the "Sign In" button
5. Verify the text "Welcome back" appears on the page
**TC #18751 — Navigate to Reports and verify content** (3 steps)
1. Click "Reports" in the navigation menu
2. Verify the Reports page title is visible
3. Verify at least one report item is displayed in the list
{% hint style="info" %}
**AI Agent:** Generated test cases are fully editable. Steps can be modified, reordered, or deleted before running.
{% endhint %}
{% endstep %}
{% step %}
### Run Both Tests ✓
Click **Run Both Tests** to execute. ContextQA launches a real browser, executes each step, and captures screenshots at every stage.
{% hint style="success" %}
**AI Agent:** Executing in Chrome on cloud infrastructure — screenshots captured after every step, full session video recorded, results available immediately after completion.
**Available after run:**
* Per-step screenshots
* Session video recording
* AI root cause analysis (on failure)
* Export as Playwright option
{% endhint %}
| Artifact | Detail |
| -------------------- | ---------------- |
| Test Cases Generated | 2 |
| Total Steps | 8 |
| Generation Time | Under 30 seconds |
| Code Required | None |
| {% endstep %} | |
| {% endstepper %} | |
| {% endtab %} | |
{% tab title="From Jira Ticket" %}
{% stepper %}
{% step %}
### Connect Jira Integration
Select **From Jira Ticket** as the source and provide the Jira issue key. ContextQA reads the ticket title, description, and acceptance criteria automatically.
{% hint style="info" %}
**AI Agent:** Reads the Jira ticket content and extracts testable requirements from the acceptance criteria and description fields.
{% endhint %}
{% endstep %}
{% step %}
### Review Generated Tests
ContextQA maps each acceptance criterion to one or more test cases, complete with steps derived from the feature description.
{% hint style="info" %}
**AI Agent:** Each acceptance criterion in the Jira ticket typically maps to one test case. Edge cases and negative paths are also generated where relevant.
{% endhint %}
{% endstep %}
{% step %}
### Link Tests Back to Jira ✓
Generated test cases are linked to the originating Jira ticket. Execution results automatically update the ticket status.
{% hint style="success" %}
**AI Agent:** Two-way Jira sync — test results flow back to the ticket, and test cases reference the originating issue for full traceability.
{% endhint %}
{% endstep %}
{% endstepper %}
{% endtab %}
{% tab title="From Swagger" %}
{% stepper %}
{% step %}
### Provide Swagger / OpenAPI URL
Select **From Swagger** and paste the URL to your OpenAPI specification. ContextQA parses all endpoints, request schemas, and response codes.
{% hint style="info" %}
**AI Agent:** Reads the full OpenAPI spec — endpoints, parameters, request bodies, and expected response codes are all used to generate test cases.
{% endhint %}
{% endstep %}
{% step %}
### Generate API Test Cases
A test case is generated for each endpoint, covering the happy path, required field validation, and common error responses (400, 401, 404, 500).
{% hint style="info" %}
**AI Agent:** Automatically generates positive and negative test cases for each endpoint. Authentication flows are detected and included as prerequisites.
{% endhint %}
{% endstep %}
{% step %}
### Execute API Tests ✓
Run the generated API tests against your staging or production environment. Response validation, schema checks, and status code assertions are all included.
{% hint style="success" %}
**AI Agent:** API tests run without a browser — faster execution with full request/response logging captured as evidence.
{% endhint %}
{% endstep %}
{% endstepper %}
{% endtab %}
{% endtabs %}
***
{% hint style="success" %}
**See ContextQA with your own workflow** — [Book a Demo →](https://contextqa.com/book-a-demo/)
{% endhint %}
## Related documentation
[AI feature overview](/ai-features/ai-features) · [Generate tests with AI](/ai-features/ai-test-generation)
# Integrations Overview
A guide to all the systems ContextQA connects with, including bug trackers, CI/CD pipelines, project management tools, and notification systems.
{% hint style="info" %}
**Who is this for?** SDETs, developers, and engineering managers who need to connect ContextQA to their existing CI/CD pipelines, bug trackers, and notification systems.
{% endhint %}
ContextQA is designed to fit into existing engineering workflows rather than replace them. The integrations in this section let you connect your test results to the tools your team already uses for project tracking, deployment, and communication.
## Quick answer
ContextQA integrations connect requirements, test execution, notifications, and defect reporting to the delivery tools a team already uses. Portal plugins are configured from **Integrations & Plugins**; CI/CD guides explain how to prepare approved test-plan quality gates; authenticated MCP tools let compatible AI agents orchestrate supported workflows. These are related surfaces, but they do not imply one interchangeable authentication or API contract.
## What this page covers
Open **Integrations & Plugins** in the ContextQA sidebar to configure portal integrations. Find a card in **All Plugins** or its category, select **View Details**, and open **Config**. Categories include Bug Reporting, Product Management, Test Lab, and CI/CD.


***
## Bug trackers and issue managers
| Integration | Category | What it does |
| -------------------- | --------------------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Jira** | Bug Report | Generate test cases from Jira tickets; create Jira bug reports from failing tests; view execution status in the Jira sidebar panel |
| **Azure DevOps** | Requirements and Bug Report | Generate tests from Azure Boards work items and create defects from failed runs with reproduction evidence |
| **FreshRelease** | Bug Report | Push test failure details to FreshRelease issues |
| **Mantis** | Bug Report | Create Mantis Bug Tracker issues from failing test cases |
| **YouTrack** | Bug Report | Create YouTrack issues with execution evidence attached |
| **BackLog** | Bug Report | File Nulab BackLog issues from ContextQA test results |
| **BugZilla** | Bug Report | Create Bugzilla bug entries from ContextQA failures |
| **ContextQA Plugin** | Bug Report | Browser-based test recorder and issue capture plugin |
***
## Project management and ALM tools

| Integration | Category | What it does |
| ----------- | ------------------ | ------------------------------------------------------------------------------- |
| **Linear** | Product Management | Generate test cases from Linear issues; create Linear issues from test failures |
| **Trello** | Product Management | Create Trello cards from test failures; link test results to existing cards |
| **ClickUp** | Product Management | Push test failures to ClickUp tasks; generate tests from ClickUp tickets |
| **Zepel** | Product Management | Link test runs to Zepel sprints; create defect items from failures |
***
## CI/CD pipelines
Open a test plan and select **CI / CD** to review the integration targets exposed by the current production workspace. The page lists GitHub, GitLab, Bitbucket, Azure DevOps, CircleCI, Codeship, Bamboo, Jenkins, AWS, TravisCI, and Generic shell. It also describes **Start Test Plan** and **Check Status** REST operations.

{% hint style="warning" %}
The verified production page does not display public REST endpoint paths. These guides cover safe pipeline preparation and quality-gate design, but do not publish copy-and-paste calls based on private portal traffic. Use an endpoint contract only when it is displayed in your workspace or provided through an official ContextQA reference.
{% endhint %}
| Integration | What it does | Guide |
| ------------------- | ---------------------------------------------------------------------------------------------- | ---------------------------------------------- |
| **GitHub Actions** | Prepare repository secrets, variables, triggers, and branch protection for a plan quality gate | [GitHub Actions](/integrations/github-actions) |
| **Azure Pipelines** | Prepare secure variables and a deployment-stage quality gate | [Azure DevOps](/integrations/azure-devops) |
| **Jenkins** | Prepare Jenkins credentials and a test-plan gate | [Jenkins](/integrations/jenkins) |
| **GitLab CI** | Prepare protected variables and a merge-request gate | [GitLab CI](/integrations/gitlab-ci) |
| **CircleCI** | Prepare a Context, workflow trigger, and approval gate | [CircleCI](/integrations/circleci) |
Each guide separates verified portal behavior from external pipeline configuration that depends on a published API contract.
***
## Notification systems
| Integration | Category | What it does |
| ------------------- | ------------- | --------------------------------------------------------------------------------- |
| **Slack** | Notifications | Send test run summaries and critical failure alerts to Slack channels via webhook |
| **Microsoft Teams** | Notifications | Send test execution results and failure notifications to Teams channels |
| **Google Chat** | Notifications | Send test result notifications to Google Chat spaces via webhook |
***
## Security and test infrastructure
| Integration | Category | What it does |
| ------------------- | ------------------ | --------------------------------------------------------------------------------------------------------------------- |
| **Azure Key Vault** | Secrets Management | Retrieve test credentials and secrets from Azure Key Vault at execution time, avoiding hardcoded values in test steps |
| **Private Grid** | Test Lab | Execute tests on your own on-premises device grid rather than the ContextQA cloud infrastructure |
***
## Integration summary
ContextQA provides portal-managed plugin integrations plus CI/CD preparation guides for common external pipeline systems.
**Portal integrations** (**Integrations & Plugins**):
| Category | Count | Integrations |
| ------------------ | ----- | --------------------------------------------------------------------------------------- |
| Bug Report | 8 | Jira, Azure DevOps, FreshRelease, Mantis, YouTrack, BackLog, BugZilla, ContextQA Plugin |
| Product Management | 4 | Linear, Trello, ClickUp, Zepel |
| Notifications | 3 | Slack, Microsoft Teams, Google Chat |
| Secrets / Infra | 2 | Azure Key Vault, Private Grid |
**CI/CD preparation guides**:
| Category | Count | Integrations |
| -------- | ----- | ------------------------------------------------------------- |
| CI/CD | 5 | GitHub Actions, Azure Pipelines, Jenkins, GitLab CI, CircleCI |
Plugin categories in the UI:
* **Bug Report** — all defect tracker integrations
* **Test Lab** — Private Grid and device farm connectors
* **Product Management** — ALM and project tool integrations
***
## MCP server
The ContextQA MCP server exposes the platform's core capabilities as callable tools for authenticated MCP hosts. Relevant tools for integrations include:
* `execute_test_plan` — trigger a test plan by ID
* `execute_test_case` — run a single test case
* `get_execution_status` — poll an execution for its current state
* `create_defect_ticket` — create a bug report in Jira or Azure DevOps
* `generate_tests_from_jira_ticket` — generate test cases from a Jira or ADO ticket URL
* `generate_tests_from_linear_ticket` — generate test cases from a Linear issue
* `get_test_case_results` — retrieve results for a completed run
See the [MCP Server reference](/mcp-server/overview) for full tool documentation.
***
## In this section
* [Jira](/integrations/jira) — full Jira integration setup and usage
* [Azure DevOps](/integrations/azure-devops) — Azure Boards requirement generation, defect reporting, and Azure Pipelines integration
* [GitHub Actions](/integrations/github-actions) — running ContextQA tests in GitHub Actions workflows
* [Jenkins](/integrations/jenkins) — triggering test plans from a Jenkinsfile and failing builds on test failures
* [GitLab CI](/integrations/gitlab-ci) — triggering test plans from `.gitlab-ci.yml` and failing pipeline stages on test failures
* [CircleCI](/integrations/circleci) — triggering test plans from a CircleCI `config.yml` and failing workflows on test failures
* [Slack](/integrations/slack) — configuring Slack notifications for test events
* [Webhooks](/integrations/webhooks) — sending test results to any HTTP endpoint for custom integrations
***
## Execution Evidence
The following recording is from a live ContextQA execution demonstrating the integrations workflow:
***
## FAQs
Where do I find the integrations configuration in ContextQA?
Open **Integrations & Plugins** in the left sidebar. Find the integration in **All Plugins** or its category, select **View Details**, and open **Config**.
Can I connect multiple bug trackers at the same time?
Yes. You can configure multiple bug reporting integrations simultaneously (for example, both Jira and Azure DevOps). Each can be enabled or disabled independently.
Does the CI/CD integration require the MCP server?
No single transport is implied by the CI/CD tab. An authenticated MCP host can use `execute_test_plan`. A REST-based pipeline must use the current public endpoint contract provided for its workspace. Do not translate private portal calls into a public integration.
{% hint style="info" %}
**Connect ContextQA to your CI/CD pipeline in 15 minutes** [**Book a Demo →**](https://contextqa.com/book-a-demo/)
{% endhint %}
# Jira
Connect ContextQA to Jira to generate test cases from tickets, report defects with AI root cause analysis, and sync test execution status bidirectionally.
## Quick answer
Connect ContextQA to Jira to generate test cases from tickets, report defects with AI root cause analysis, and sync test execution status bidirectionally. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, developers, and engineering managers who want to generate tests from Jira tickets and report defects directly from ContextQA test failures.
{% endhint %}
The ContextQA Jira integration creates a two-way connection between your requirements and your test suite. You can generate test cases directly from a Jira user story, view live execution status inside Jira, and report defects as Jira issues without leaving the test result page.
[Watch the Jira-to-tests walkthrough](https://drive.google.com/file/d/1v3KHLYP17reGp1BZDSOOxGF5MAsLuTF_/preview).
{% hint style="info" %}
**Business use case:** Generate tests from the Jira stories selected for a release so QA can preserve source traceability, review the proposed coverage, and run accepted tests without copying ticket content into a separate document.
{% endhint %}
## Interactive demo: generate tests from Jira
Use this guided walkthrough to see how a Jira work item becomes traceable test coverage in ContextQA. Follow the pointer through the Jira selection and generation workflow, then use the instructions below when you configure your own connection.
{% embed url="" %}
### What to notice
* The Jira ticket remains the source context for the generated tests.
* Review gates let a tester refine proposed coverage before accepting it.
* Traceability connects delivery work, test execution, and failure follow-up.

***
## Set up the Jira integration
1. Open **Integrations & Plugins** in the left navigation.
2. Find Jira in **All Plugins** or **Bug Reporting** and select **View Details**.
3. Open **Config** when you need to create or change the connection.
4. Enter the Jira **Account URL**, such as `https://yourorg.atlassian.net`.
5. Enter the Jira account **User Name** (normally the email address used for Jira Cloud).
6. Create a Jira API token at [Atlassian account security](https://id.atlassian.com/manage-profile/security/api-tokens), then enter it as the **API Key**.
7. Save the integration and confirm that its Jira details are displayed.
{% hint style="warning" %}
Treat the Jira API token as a secret. Never include it in screenshots, examples, ticket descriptions, or test steps.
{% endhint %}
***
## Generating Tests from Jira Tickets
1. Open **Requirements**.
2. Select **Upload Jira Requirement**.
3. Continue to the Jira ticket picker.
4. Search by ticket key or text and select one or more tickets that belong to the same testing objective.
5. Continue and review the detected variables. Mark sensitive values as secrets where appropriate.
6. Answer any clarification questions required to remove ambiguity from the selected stories.
7. Start generation and leave the requirements page open or return later while ContextQA processes the selection.
8. Open the generated requirement record and review each proposed test. Edit it if needed, then accept or reject it.
9. Run an accepted test once and review its steps and evidence before promoting it to a shared suite or plan.
The selected Jira item remains the source requirement, which makes it easier to explain why the test exists and which delivery item it covers.
***
## Running Tests from Jira
With test cases linked to a Jira ticket, you can trigger execution from the ContextQA panel inside Jira:
1. Open the Jira ticket
2. In the ContextQA panel, find the linked test cases
3. Click **Execute** next to the test case you want to run, or **Execute All** to run all linked tests
4. The panel updates with a status indicator (Running → Passed / Failed) as the execution progresses
You can also run tests from ContextQA directly and the results will be visible in the Jira panel the next time you open the ticket.
***
## Auto-Creating Defects from Test Failures
When a test case fails and the failure indicates a genuine application bug, ContextQA can create a Jira issue automatically with all relevant evidence attached.
### Interactive demo: report a failure to Jira
Follow the failure-to-defect workflow to see how ContextQA carries test identity, root-cause context, reproduction information, and evidence into a Jira issue for review.
{% embed url="" %}
#### What to notice
* The failed execution remains the evidence source for the Jira issue.
* A reviewer can confirm the project, issue type, summary, and description before submission.
* The resulting issue link preserves traceability between triage, delivery work, and the ContextQA result.
### Via the UI
1. Open the failed test execution report in ContextQA
2. Click the **Create Bug** button (or **JIRA** button in the failure reporting toolbar)
3. Select the Jira project and issue type (Bug is the default)
4. Optionally customize the summary and description
5. Click **Create Issue**
ContextQA creates the Jira issue and populates it with:
* **Summary:** Derived from the test case name and the failing step
* **Description:** AI-generated root cause explanation, reproduction steps, and the exact step that failed
* **Attachment:** The failure screenshot
* **Links:** A direct URL to the ContextQA execution (for video, trace, and full step log access)
* **Labels:** The test case label (Jira ticket ID) for traceability
A link to the newly created issue appears immediately in the ContextQA execution report.
### Automatic bug creation and sync status
When automatic Jira bug creation is enabled, ContextQA creates a Jira issue automatically when a test run fails. The status of this auto-creation is visible directly on the execution screens:
**Auto-created bug badge:** When ContextQA successfully creates a Jira issue for a failed run, a clickable badge appears in the execution header displaying the Jira issue key (e.g., `MYAPP-1234`). Click the badge to open the issue directly in Jira.
**Sync status banner:** If the automatic bug creation fails (for example, due to invalid field values or permission issues), a warning banner appears at the bottom of the live execution screen and the run results screen. The banner displays the specific error reason (e.g., "labels: The label 'AI Upload' can't contain spaces.") and a **Retry** button. Click **Retry** to attempt the Jira issue creation again. The banner disappears when the sync succeeds or when the issue is created manually.
{% hint style="info" %}
The sync status banner only appears when the auto-creation pipeline fails. It does not appear for successful syncs, pending syncs, or legacy runs that predate this feature.
{% endhint %}
### Via MCP
```python
create_defect_ticket(
execution_id="27045",
project_id="MYAPP"
)
# Returns: {"ticket_id": "MYAPP-1234", "url": "https://yourorg.atlassian.net/browse/MYAPP-1234"}
```
This is the recommended approach for automated triage pipelines. Combine it with `get_execution_status` and `get_root_cause` to build a workflow that creates a Jira bug only when a failure persists across multiple runs:
```python
# Run the test
execution = execute_test_case(test_case_id="1234")
status = poll_until_complete(execution)
if status["result"] == "FAILED":
# Get AI root cause before creating the ticket
root_cause = get_root_cause(execution_id=status["execution_id"])
# Create the defect ticket
ticket = create_defect_ticket(
execution_id=status["execution_id"],
project_id="MYAPP"
)
print(f"Defect created: {ticket['url']}")
```
***
## Viewing Test Coverage in Jira
The ContextQA panel in Jira shows a summary of test coverage for each ticket:
* **Test Cases Linked:** How many test cases have been generated for or linked to this ticket
* **Last Execution Status:** The most recent execution result for each linked test case
* **Coverage Percentage:** What fraction of the acceptance criteria have corresponding test cases
This view gives product managers and developers visibility into test health without leaving their workflow in Jira.
***
## Bidirectional Status Sync
When you configure the integration with write access to Jira:
* When all test cases for a Jira ticket pass, ContextQA can automatically transition the ticket to a configured status (e.g., **Ready for Release** or **Done**)
* When a test case fails, ContextQA can reopen the linked ticket or add a comment with the failure details
* Configure these options from **Integrations & Plugins → Bug Reporting → Jira → View Details → Config** when they are enabled for your workspace.
***
## Filtering Tests by Jira Ticket
In the ContextQA **Test Cases** view, use the **Labels** filter to display only test cases linked to a specific Jira ticket. Labels are applied automatically during generation and follow the Jira ticket number format (e.g., `MYAPP-123`).
***
## Using the Azure DevOps Integration
If your team uses Azure DevOps (ADO) instead of Jira, the integration follows the same patterns. Navigate to **Integrations & Plugins → Bug Reporting → Azure DevOps → View Details → Config** and configure your ADO organization URL and personal access token. The `create_defect_ticket` MCP tool supports ADO by setting the `tracker` parameter accordingly.
See the [Azure DevOps Integration](/integrations/azure-devops) page for full ADO-specific configuration details.
***
## Troubleshooting
**"Cannot connect to Jira" error during setup:**
* Verify the base URL does not have a trailing slash
* For Jira Cloud, the URL format is `https://yourorg.atlassian.net` (not `.com`)
* Confirm the API token is for the same account as the email address entered
* If you are on Jira Server, ensure the ContextQA server can reach the Jira URL (firewall/VPN)
**An "invalid JSON" or unexpected login-response error appears:**
This usually means Jira returned an HTML sign-in page, redirect, proxy page, or gateway error where the integration expected JSON. Open **Integrations & Plugins → Bug Reporting → Jira → View Details → Config**, then reconnect and verify the account URL, account email, API token, network reachability, and Jira permissions. For Jira Cloud, use the tenant base URL without a trailing slash. Do not paste the token or full response body into a ticket or shared log; if the error continues, provide a redacted timestamp and ContextQA run or request reference to support.
**Test cases not appearing in the Jira panel:**
* Ensure the ticket ID format matches exactly (case-sensitive: `MYAPP-123` not `myapp-123`)
* Confirm the integration is configured from both sides (ContextQA settings and Jira panel installation)
**Defect tickets missing screenshots:**
* Screenshots are attached as links, not as uploaded files, due to Jira attachment size limits
* Click the ContextQA execution link in the Jira issue description to view full screenshots and video
{% hint style="info" %}
**Connect ContextQA to your CI/CD pipeline in 15 minutes.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the full integration walkthrough for your existing toolchain.
{% endhint %}
# Azure DevOps
Connect Azure DevOps to ContextQA, generate tests from Azure Boards work items, report failed runs as bugs, and link execution evidence.
## Quick answer
Connect Azure DevOps under **Integrations & Plugins**. You can then use **Assets → Requirements → New Requirement → Generate from Integrations** to select Azure Boards work items for AI test generation, or select **Bug** on a failed run and choose Azure DevOps as the defect destination. ContextQA keeps a link between the work item and the requirement or run evidence.
## What this page covers
{% hint style="info" %}
**Who is this for?** SDETs, developers, and engineering managers who use Azure Boards for issue tracking and want to push test failures directly as work items.
{% endhint %}
The ContextQA Azure DevOps integration supports two user-facing loops:
* **Requirement to coverage** — select Azure Boards work items and let ContextQA generate reviewable tests from their content.
* **Failure to defect** — create a work item from a failed run with reproduction context and a link back to the evidence.

***
## Setting up the Azure DevOps integration
### Step 1: Generate a Personal Access Token in Azure DevOps
1. Open your Azure DevOps dashboard.
2. Go to your profile menu, select the three-dot menu, and choose **User settings**.
3. Select **Profile**, then navigate to **Personal access tokens**.
4. Click **New token**.
5. Give the token a clear name and grant the narrowest Azure Boards work-item permissions the ContextQA workflow requires. Avoid **Full access** unless your administrator and ContextQA support confirm that it is necessary.
6. Click **Create** and copy the generated token immediately. You will not be able to view it again after closing the dialog.
### Step 2: Enable the Azure DevOps plugin in ContextQA
1. In ContextQA, click **Settings** in the left sidebar.
2. Open **Integrations & Plugins**.
3. Find **Azure DevOps Board** in the plugin list and enable it.
### Step 3: Enter your integration credentials
1. Paste the Personal Access Token copied in Step 1 into the access key field.
2. Enter your Azure DevOps organization URL (copy this from the address bar of your Azure DevOps portal, for example `https://dev.azure.com/your-org`).
3. Click **Create**.
ContextQA verifies the credentials and confirms a successful connection. The integration is now active for all projects in your ContextQA workspace.
***
## Generate tests from Azure Boards work items
1. Open **Assets → Requirements** and select **New Requirement**.
2. Choose **Generate from Integrations**. During a staged rollout, the first card may still read **Generate from Jira** before the integration chooser appears.
3. Choose **Azure DevOps**. If it is not connected, follow the link back to **Integrations & Plugins**.
4. Search by work-item ID or title. Narrow the list by **Project** and **Work Item Type** when needed.
5. Select the work items and click **Continue**.
6. Choose the platform, publish mode, environment, test-case types, and optional context.
7. Start analysis. Answer clarification questions when ContextQA needs more information.
8. Open the resulting requirement and review **Test Cases**, **Questionnaire**, **Requirement Data**, **Metadata**, and **Gaps** before approval.
The picker supports multiple selections and reports unreadable items before generation. Remove failed items rather than publishing a partial selection accidentally.
```mermaid
flowchart LR
A[Azure Boards work items] --> B[Integration picker]
B --> C[AI analysis and clarifications]
C --> D[Requirement record]
D --> E[Reviewable test cases]
E --> F[Test repository and execution]
```
***
## Creating work items from test failures
Once the integration is configured, you can report a bug to Azure Boards directly from any failing test result.
### Step 1: Identify a failed test case
Open the execution result page for a failed test run. The failed step is highlighted with a red status badge, a screenshot, and an error message.
### Step 2: Start reporting a bug
Click **Bug** in the test result toolbar.
### Step 3: Select Azure DevOps as the destination
When the destination chooser opens, select **Azure DevOps**. The same action can also offer Jira when both integrations are configured.
### Step 4: Fill in work item details
* **Issue type** — select the work item type appropriate for your Azure project (e.g., Bug, Test Case, Shared Step)
* **Title** — enter a clear title; ContextQA automatically pre-fills the test description and reproduction steps in the description field to save time
### Step 5: Save and sync
Click **Save**. The work item is created immediately in Azure Boards and a direct link appears in the ContextQA result page.
### Step 6: Verify in Azure Boards
Follow the generated link to open Azure Boards and confirm the ticket was created. The work item includes the full bug description, test step history, and all context provided by ContextQA.
***
## Managing the work item in Azure Boards
Once the ticket is in Azure Boards:
* Assign it to the responsible developer using the standard Azure Boards assignment workflow
* Use Azure Boards sprint and backlog management to prioritize the fix
* Update the ticket status as the fix progresses — the link in ContextQA continues pointing to the same ticket so QA engineers can monitor resolution
***
## Configuring project and area path
When creating work items, ContextQA uses the organization and credentials provided during setup. If your Azure DevOps organization contains multiple projects, select the appropriate project in the work item creation dialog each time you report a bug. Azure Boards manages area path and iteration configuration according to your existing project structure.
***
## Azure Pipelines CI/CD integration
Use an Azure Pipelines stage to coordinate a ContextQA test-plan run and require its result before deployment.
Before configuring the stage:
1. Create and manually validate the test plan.
2. Open its **CI / CD** tab and confirm Azure DevOps is listed.
3. Obtain the current public start and status contract supplied for your workspace.
4. Create a dedicated [API token](/administration/api-tokens) with the narrowest required scopes.
{% hint style="warning" %}
The verified production **CI / CD** tab describes start and status operations but does not display public endpoint paths. Do not use older account-password or `/testplans/{id}/execute` examples, and do not copy internal URLs from portal network traffic.
{% endhint %}
In **Pipelines → Library → Variable Groups**, add the API token as a secret variable named `CONTEXTQA_API_TOKEN`. Store the test plan ID and the public base URL, when supplied, as non-secret variables. Authorize the variable group only for the pipelines that need it.
When the public contract is available, the stage should:
1. Start the plan with the published method, path, and payload.
2. Capture the returned run ID.
3. Poll the published status operation with a bounded timeout.
4. Return a non-zero exit code for every documented non-success result.
5. Include the run ID in the job output so reviewers can find the run in ContextQA.
Place the stage after the target environment is ready and before the protected deployment stage. Use environment approvals and checks when production requires an additional human gate.
***
## Traceability
With both the Jira and Azure DevOps integrations in use, ContextQA can push bugs to whichever tracker your team uses. Each bug includes:
* A link to the ContextQA result page with screenshots, video, and step logs
* The reproduction steps generated by the AI
* The test case name and ID for lookup in ContextQA
* A direct execution or result link when the work item was created from an external Azure DevOps workflow
This gives developers enough context to begin triage from Azure Boards. Opening the linked screenshots, video, logs, or live result still requires authorized access to the corresponding ContextQA organization and workspace.
## Related documentation
* [Requirements management](/web-testing/requirements-management)
* [Execution and test results](/reporting/test-results)
* [PR Impact Analysis](/ai-features/pr-impact-analysis)
* [API tokens](/administration/api-tokens)
{% hint style="info" %}
**Connect ContextQA to your CI/CD pipeline in 15 minutes.** [**Book a Demo →**](https://contextqa.com/book-a-demo/) — See the full integration walkthrough for your existing toolchain.
{% endhint %}
# GitHub Actions
Prepare GitHub Actions secrets, variables, triggers, and branch protection for a ContextQA test-plan quality gate.
## Quick answer
Prepare GitHub Actions secrets, variables, triggers, and branch protection for a ContextQA test-plan quality gate. Use this page to understand when the capability applies, complete its user-facing workflow, and verify the expected result.
## What this page covers
Use GitHub Actions to place a ContextQA test-plan result in the pull-request or deployment path. ContextQA runs the browsers or devices; the GitHub runner coordinates the request and evaluates the result.
## Before you begin
* Create and manually validate the test plan you want to use as the gate.
* Open the plan's **CI / CD** tab and confirm GitHub is listed.
* Obtain the current public start and status contract supplied for your workspace.
* Create a dedicated [API token](/administration/api-tokens) with the narrowest required scopes.
{% hint style="warning" %}
The verified production **CI / CD** tab does not display public endpoint paths. Do not use older examples based on account-password login or `/testplans/{id}/execute`. Do not copy request URLs from portal network traffic.
{% endhint %}
## Store GitHub configuration
In the GitHub repository, open **Settings → Secrets and variables → Actions**.
Add:
| Type | Name | Value |
| -------- | ------------------------ | ------------------------------------------------------------- |
| Secret | `CONTEXTQA_API_TOKEN` | The one-time token value copied from ContextQA |
| Variable | `CONTEXTQA_TEST_PLAN_ID` | The plan ID shown on the ContextQA plan overview |
| Variable | `CONTEXTQA_API_BASE_URL` | The public base URL from the official contract, when supplied |
Use an environment-level secret when production deployments require stricter reviewers or a different token.
## Choose the workflow trigger
Select the event that matches the plan's purpose:
| Trigger | Good fit |
| --------------- | ---------------------------------------------------- |
| Pull request | Small smoke or risk-based plan before merge |
| Push to `main` | Post-merge verification |
| Deployment | Pre-production or post-deployment validation |
| Schedule | Broad regression outside the developer feedback loop |
| Manual dispatch | Troubleshooting and controlled reruns |
Avoid running the same expensive plan on overlapping events unless the duplicate coverage is intentional.
## Implement the quality gate
When the public contract is available, the workflow job should:
1. Read the token from `secrets.CONTEXTQA_API_TOKEN` and the plan ID from `vars.CONTEXTQA_TEST_PLAN_ID`.
2. Start the plan using the published request method, path, and payload.
3. Store the returned run ID as a step output.
4. Poll the published status operation with a bounded timeout.
5. Fail the job for every documented non-success terminal result.
6. Add the run ID to the job summary and direct reviewers to the ContextQA portal.
Do not construct a deep link unless the public response returns one.
## Protect the branch
After validating both pass and fail paths:
1. Open the repository ruleset or branch protection rule.
2. Require the ContextQA job's check name before merge.
3. Keep the workflow file and required-check name stable.
4. Require review for changes to the workflow when it protects production.
## Security guidance
* Use one token per repository or GitHub environment.
* Never use a user's ContextQA password in Actions.
* Mask response values that could contain sensitive test data.
* Rotate the token before expiry and immediately after suspected exposure.
* Add an IP allowlist only when the runner egress addresses are stable.
## Troubleshooting
**The workflow has no endpoint to call**
The current production CI/CD tab describes the operations but does not publish their paths. Obtain the public API contract for your workspace; do not infer it.
**The request returns unauthorized or forbidden**
Check the token's status, expiry, permission scopes, and IP allowlist. Confirm the workflow reads the intended GitHub secret.
**A passing plan does not unblock the pull request**
Verify that branch protection requires the exact current job name and that the workflow runs for the target pull-request event.
## Related pages
* [Prepare a CI/CD quality gate](/getting-started/ci-cd-tutorial)
* [Test Plans](/web-testing/test-plans)
* [API tokens](/administration/api-tokens)
* [Jenkins](/integrations/jenkins)
* [GitLab CI](/integrations/gitlab-ci)
* [CircleCI](/integrations/circleci)
---
[Next Page](/llms-full.txt/1)